magical experience with codex on iPad
COMPUTING
-
Is It Time to Worry About Compute Scarcity?
By
–
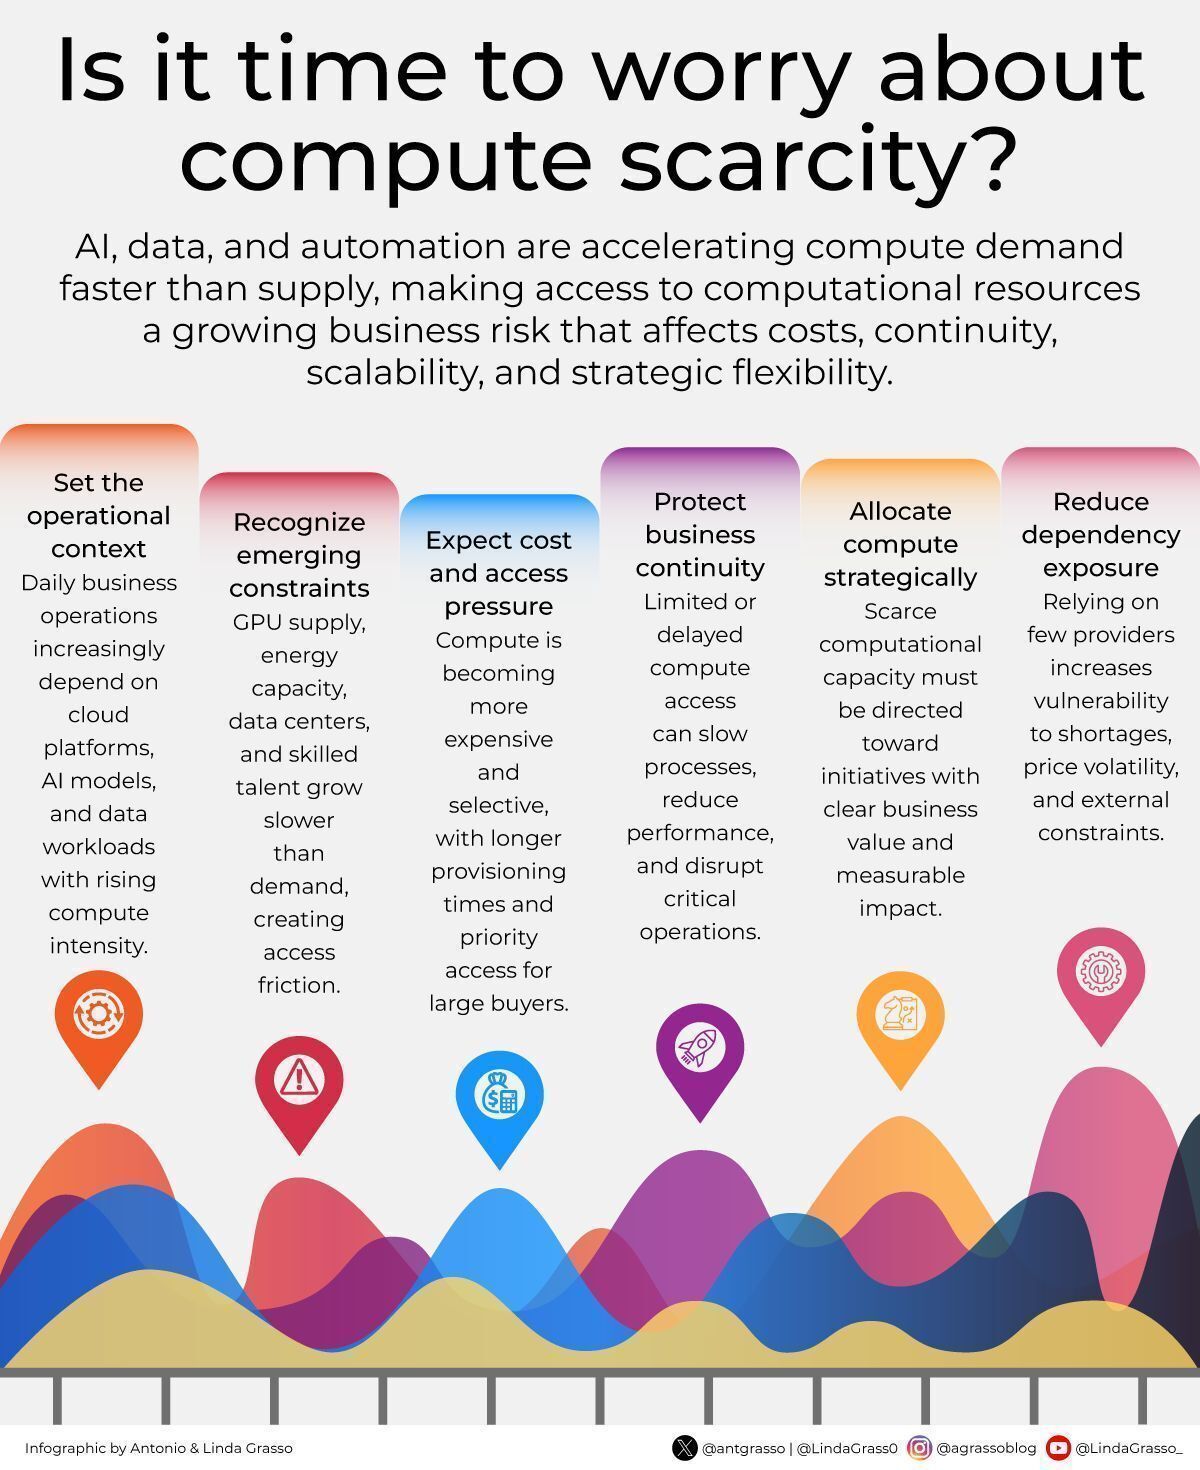
Is it time to worry about compute scarcity?
by @antgrasso #ArtificialIntelligence #IT #Tech #Technology -
MiniMax Teases Sparse Attention Architecture for M3 with Significant Speedup Benchmarks
By
–
MiniMax just teased their Sparse Attention architecture for M3. The benchmarks show 9.7x prefilling speedup and 15.6x decoding speedup at 1M tokens vs M2. MiniMax deliberately went back to full attention for M2 because efficient attention wasn't production-ready. Their pretrain
-
Huawei’s Tau Scaling Law Key to Post-Moore AI Efficiency
By
–
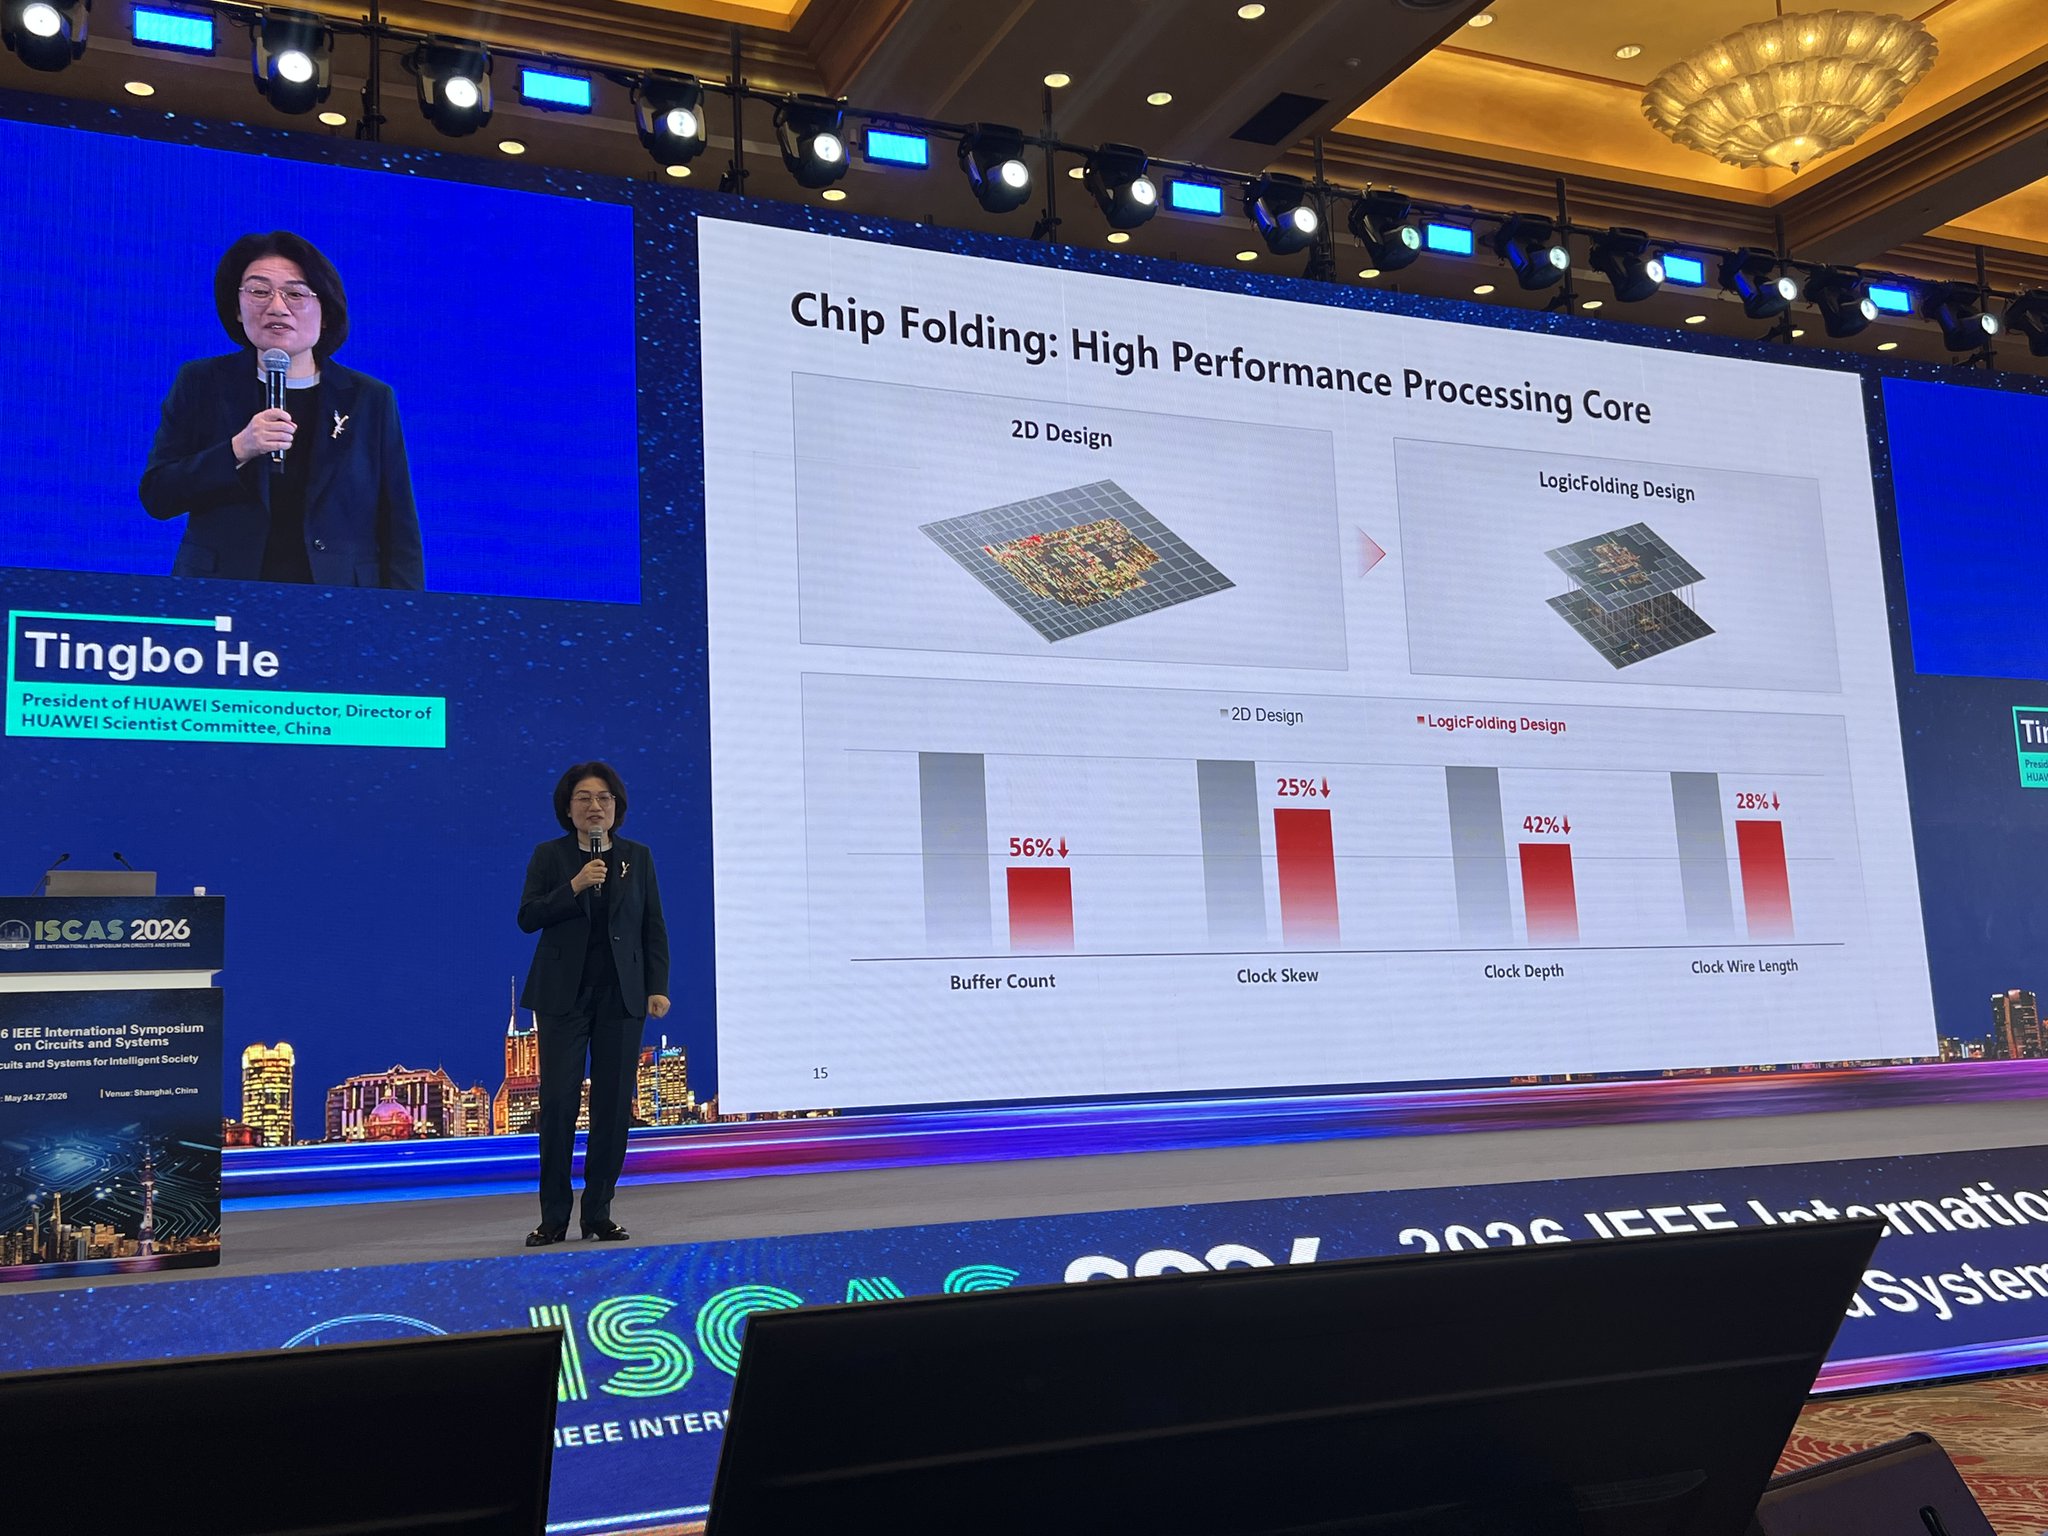
The future of AI will not only be shaped by better models. It will be shaped by faster, more efficient systems underneath them. That is why Huawei’s Tau Scaling Law (Her’s Law) matters for the post-Moore era. #HuaweiPartner @Huawei #AI #Semiconductors #ChipDesign #MooresLaw
-
AI inference efficiency depends on data movement through memory, chips, and interconnects.
By
–
This matters directly for AI inference. Every AI response depends on data moving through: memory,
chips,
interconnects,
and full systems. If that movement is slow, inference becomes slower, more energy-intensive, and more expensive to scale. -
Next AI Bottleneck May Be Data Movement, Not Compute
By
–
The next AI bottleneck may not only be compute power. It may be data movement. Huawei’s Tau Scaling Law (aka Her’s Law) brings this question into focus: How much time can we remove from the system? #HuaweiPartner @Huawei
-
Free ChatGPT Deep Dive Video & Article Breakdown
By
–
I still can’t believe @karpathy released this 3.5-hour deep dive on how ChatGPT actually works… for FREE. 🤯
— Charly Wargnier (@DataChaz) 26 mai 2026
Easily the best video I've watched on the topic.
Swap your next Netflix binge for this.
Then read the ace article below from Codez breaking it all down 👀↓ https://t.co/5RYVSFckqq pic.twitter.com/c8spocCq5rI still can’t believe @karpathy released this 3.5-hour deep dive on how ChatGPT actually works… for FREE. Easily the best video I've watched on the topic. Swap your next Netflix binge for this. Then read the ace article below from Codez breaking it all down ↓
-
Books That Teach the Math Behind Machine Learning
By
–
Books That Will Teach You the Math Behind Machine Learning. #BigData #Analytics #DataScience #IoT #IIoT #Python #RStats #TensorFlow #JavaScript #ReactJS #Serverless #DataScientist #Linux #Books #Mathematics #Programming #Coding #100DaysofCode https://
geni.us/Math–Books -
Fast and High-Resolution Latent Decoding with Pixel Diffusion
By
–
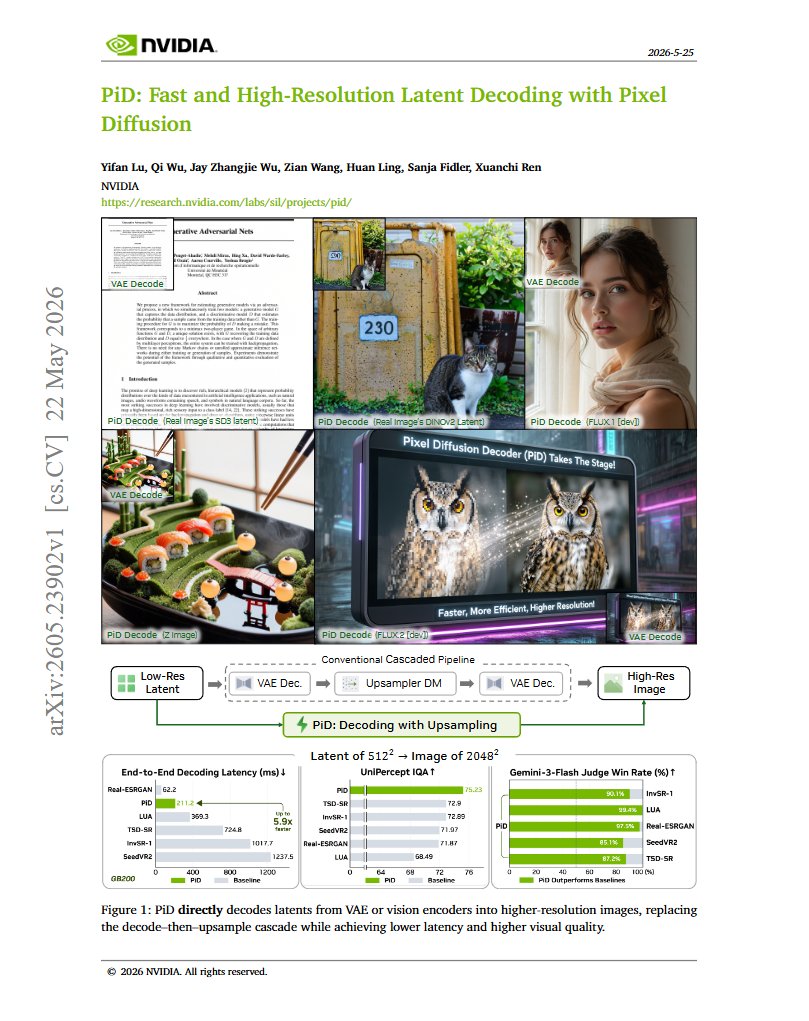
Image models usually VAE decode first, then super-res later, which is slow and mostly reconstructs rather than creates detail. This NVIDIA research makes the decoder itself a pixel diffusion model, so a 512^2
-
LLM agents with evolving episodic memory: CASCADE framework
By
–
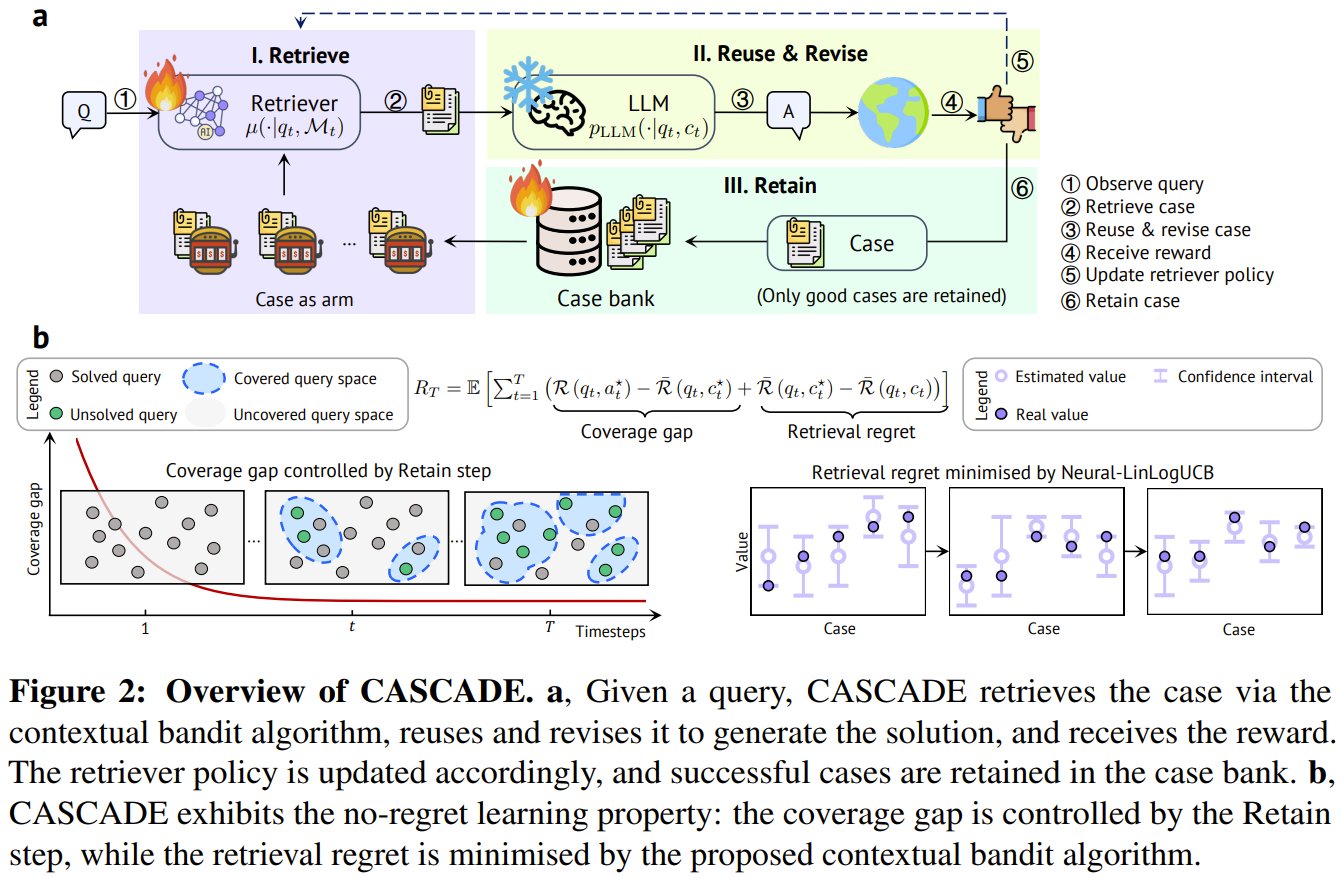
What if your LLM kept learning after deployment—even without changing its weights? Researchers from Jilin University, King's College London, and UCL introduce CASCADE, a framework that equips LLM agents with an evolving episodic memory. It treats experience reuse like a