The next era of enterprise is being built AI-native from day one. Join this CES panel to explore how organizations are designing end-to-end AI systems—from infrastructure to creative interfaces—to unlock real transformation at scale. CES Foundry Stage | Fontainebleau,
COMPUTING
-
PyTorch’s Signed 64-bit Index Standardization Decision
By
–
Pytorch made the right call standardizing on signed 64 bit indexes. I would probably still be rather pointlessly making case by case decisions to use int32 if it were an option. Some old habits linger.
-
Breaking Down Problems: Essential Skill in Computer Science
By
–
"Learning to break down problems into smaller pieces is one of the most important skills in computer science/life." — Addy Osmani (
@addyosmani
) -
The Efficiency Era of AI Models
By
–
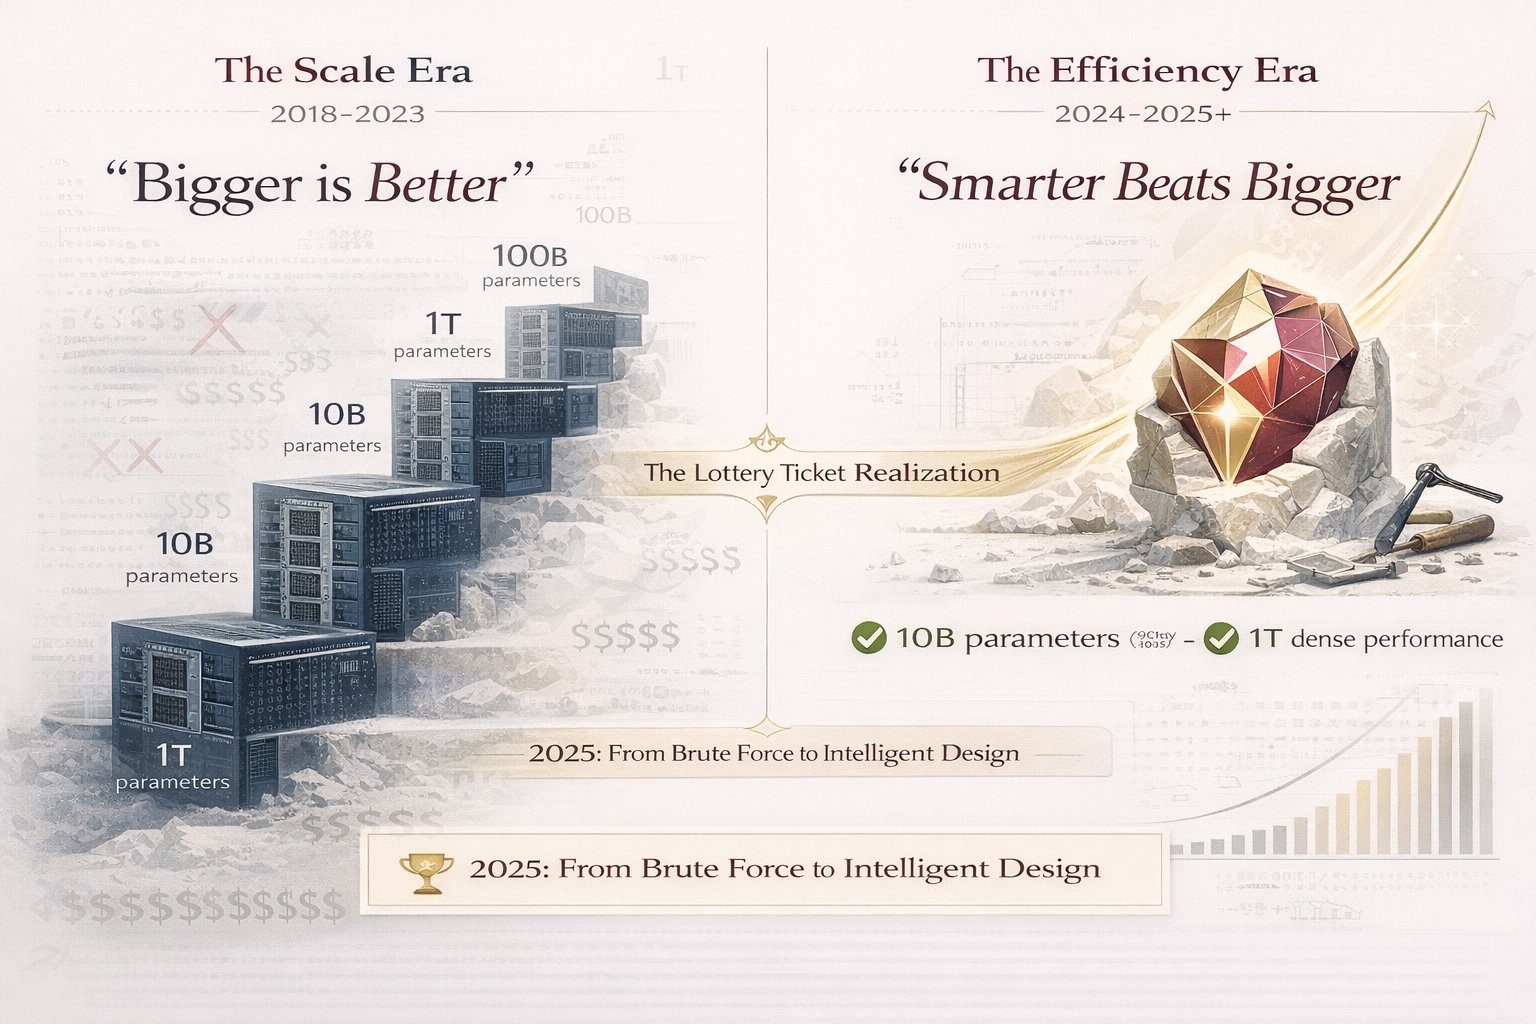
The lottery ticket hypothesis wasn't wrong. We just weren't ready for it. In 2025, sparse models are no longer academic curiosities. They're production infrastructure. The future isn't bigger models. It's smarter pruning. Welcome to the efficiency era. Read it here if you
-
2026 Breakthroughs Made AI Production-Ready
By
–
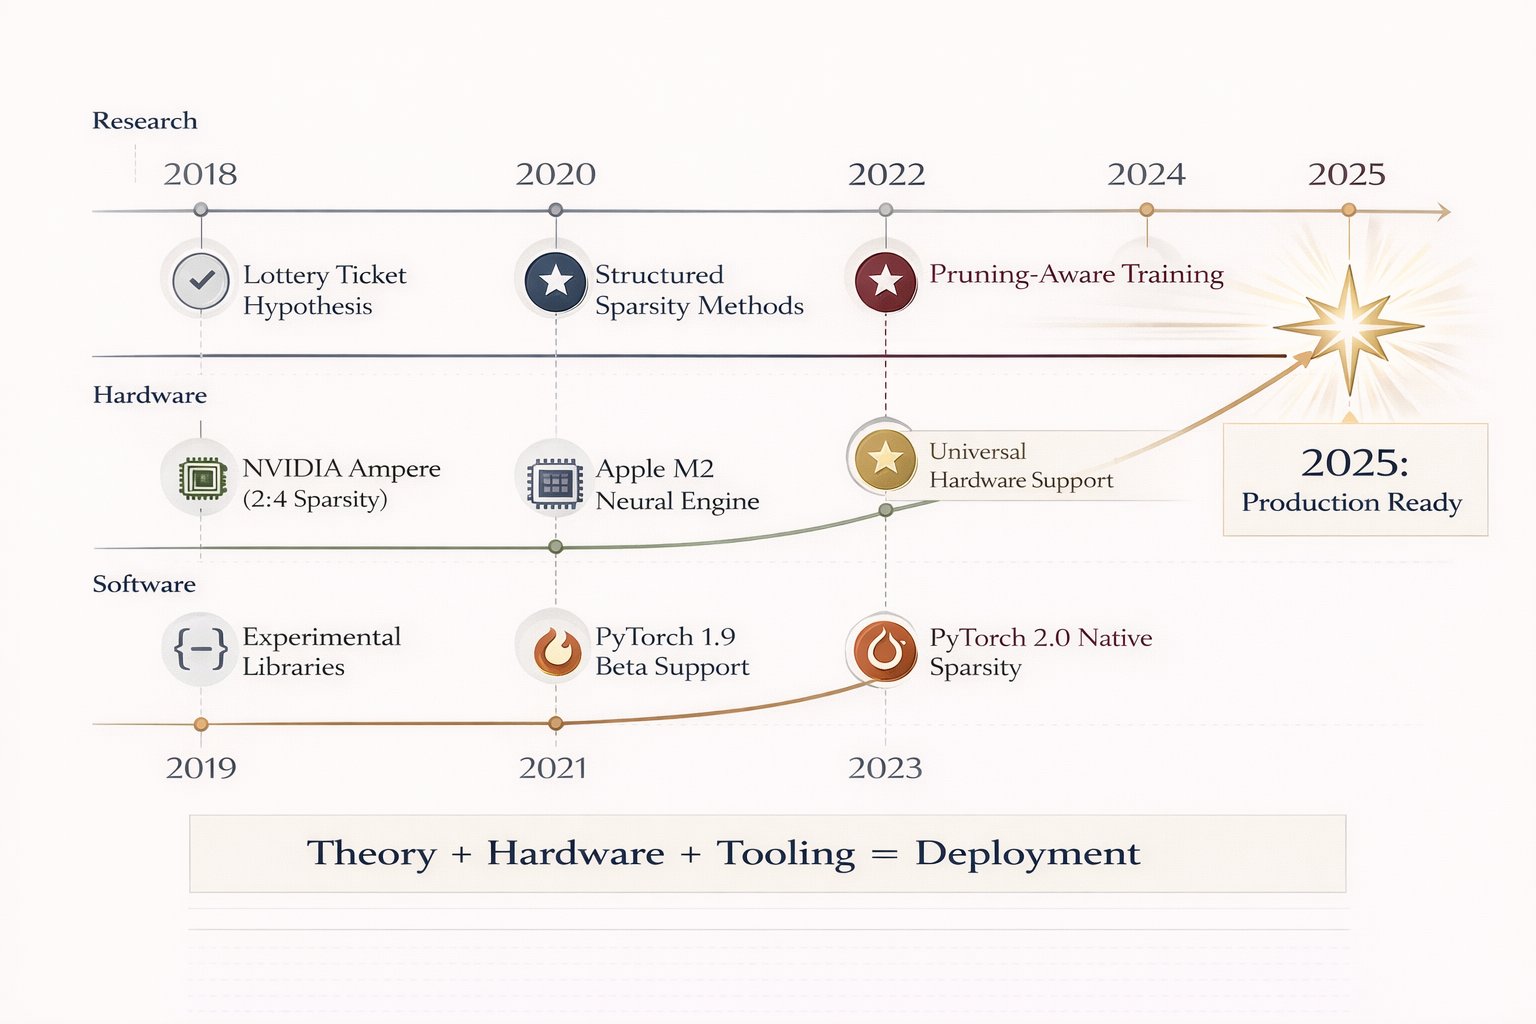
Three breakthroughs made this production-ready in 2026: 1. Pruning-aware training (train sparse from the start)
2. Hardware support (NVIDIA Ampere+, Apple Neural Engine)
3. Framework integration (PyTorch 2.0 native sparsity) The tooling finally caught up to the theory. -
Neural networks are 90% redundant by design
By
–
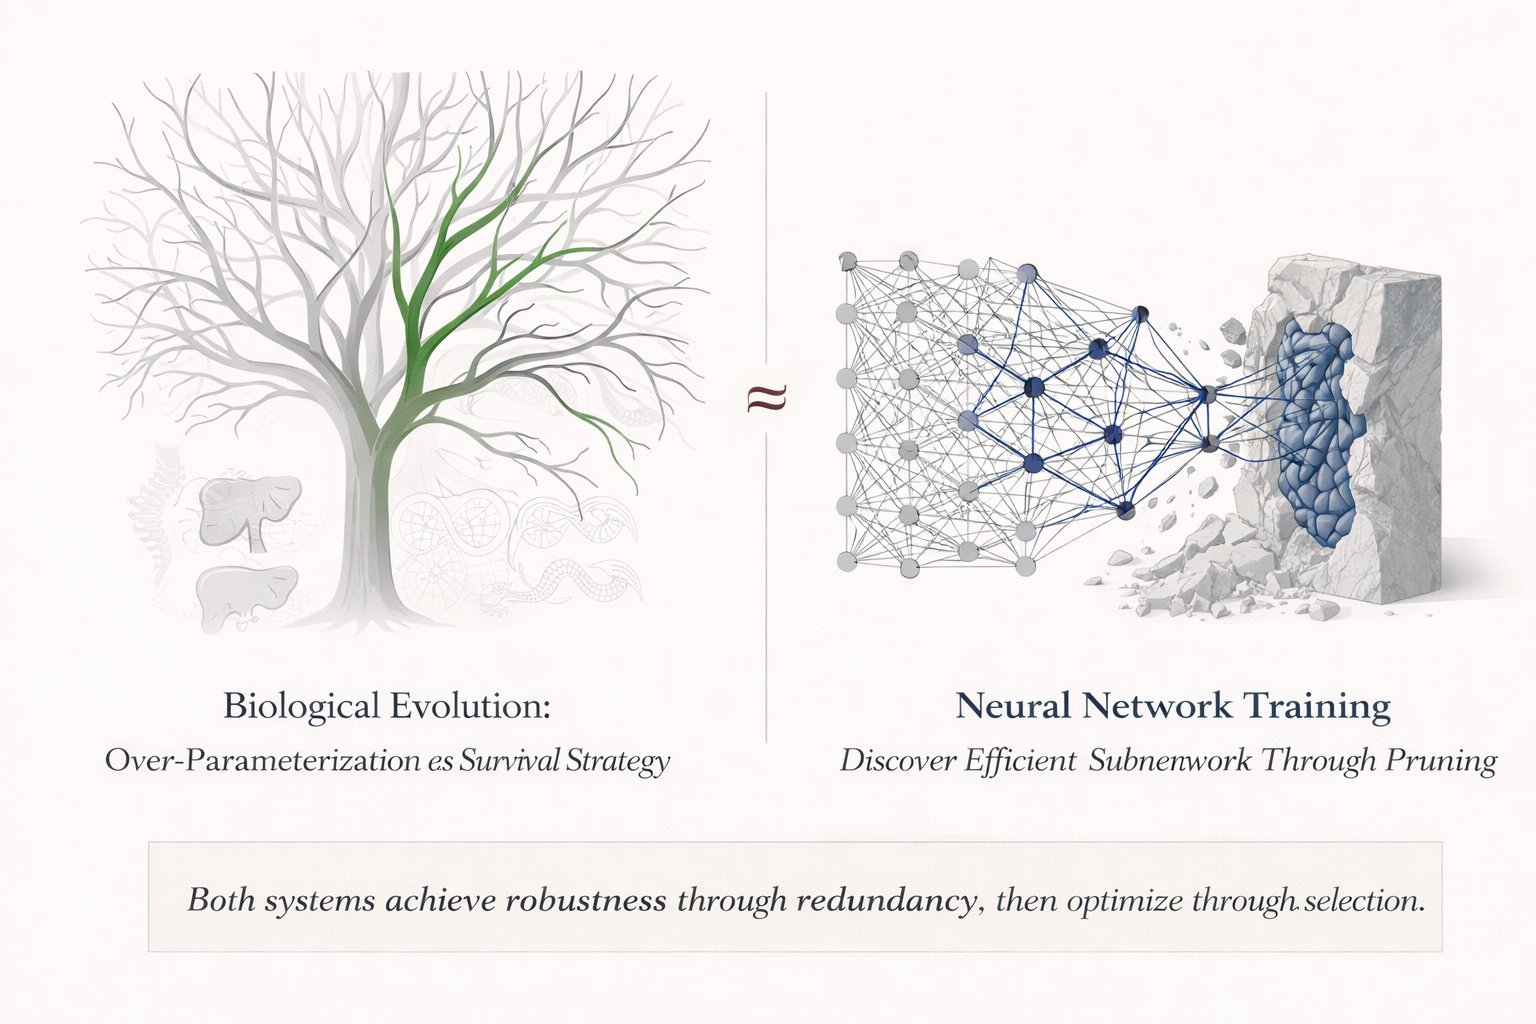
The academic papers missed the real story. It's not about finding "winning tickets" in random initialization. It's about discovering that neural networks are 90% redundant by design, and modern hardware finally lets us exploit that. Evolution over-parameterizes. We can prune.
-

Transformational AI Model Efficiency Gains
By
–
The deployment implications are massive: – GPT-3 scale models (175B params) → 17.5B params at same accuracy
– Monthly inference costs: $500K → $50K
– Latency: 2 seconds → 200ms
– Memory requirements: 350GB → 35GB This isn't incremental. It's transformational. -
GPU Tensor Cores Accelerate Sparse Networks
By
–
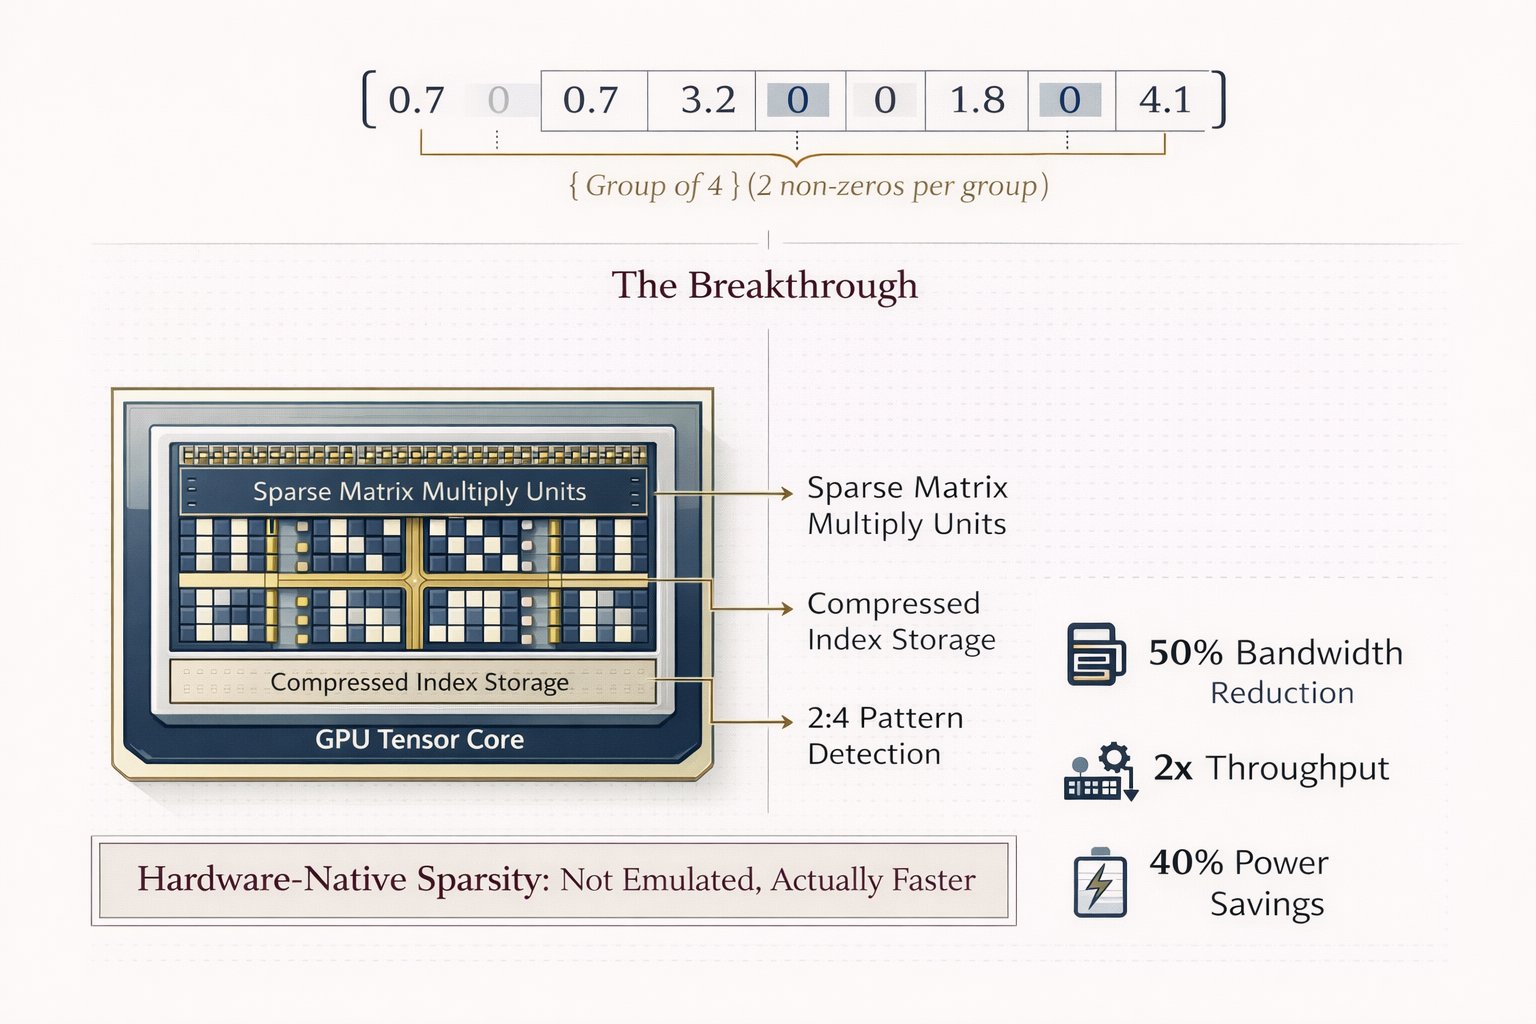
Here's the math that makes it work: Modern GPUs have specialized Tensor Cores optimized for 2:4 sparsity (2 non-zero values per 4 elements). This isn't emulated. It's silicon-level acceleration. 90% sparse network = 50% memory bandwidth + 2x compute throughput. Real speed,
-
NVIDIA’s Block Sparsity Breakthrough Speeds AI
By
–
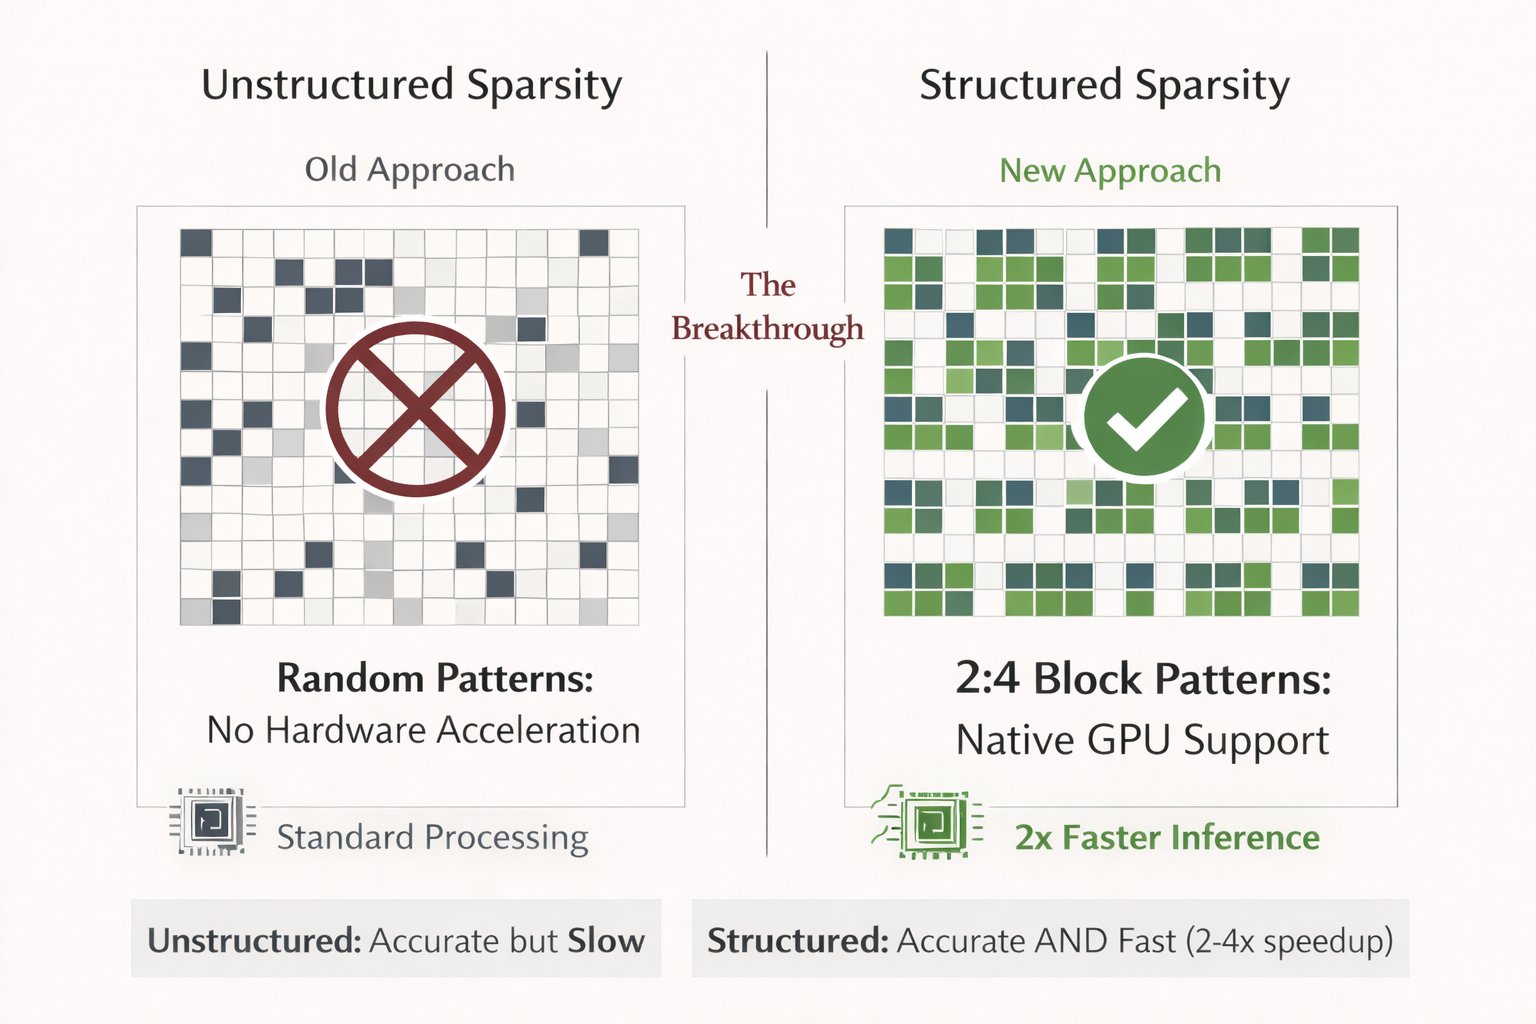
Then came the breakthrough nobody expected: Structured sparsity + modern hardware. NVIDIA proved you don't need random sparse patterns. Block sparsity (2:4, 4:8 patterns) runs NATIVELY on modern GPUs. Suddenly the lottery ticket isn't just accurate. It's actually faster.
-

MIT’s 90% Neural Network Deletion Breakthrough Ignored
By
–
MIT proved you can delete 90% of a neural network without losing accuracy. Five years later, nobody implements it. "The Lottery Ticket Hypothesis" just went from academic curiosity to production necessity, and it's about to 10x your inference costs. Here's what changed (and