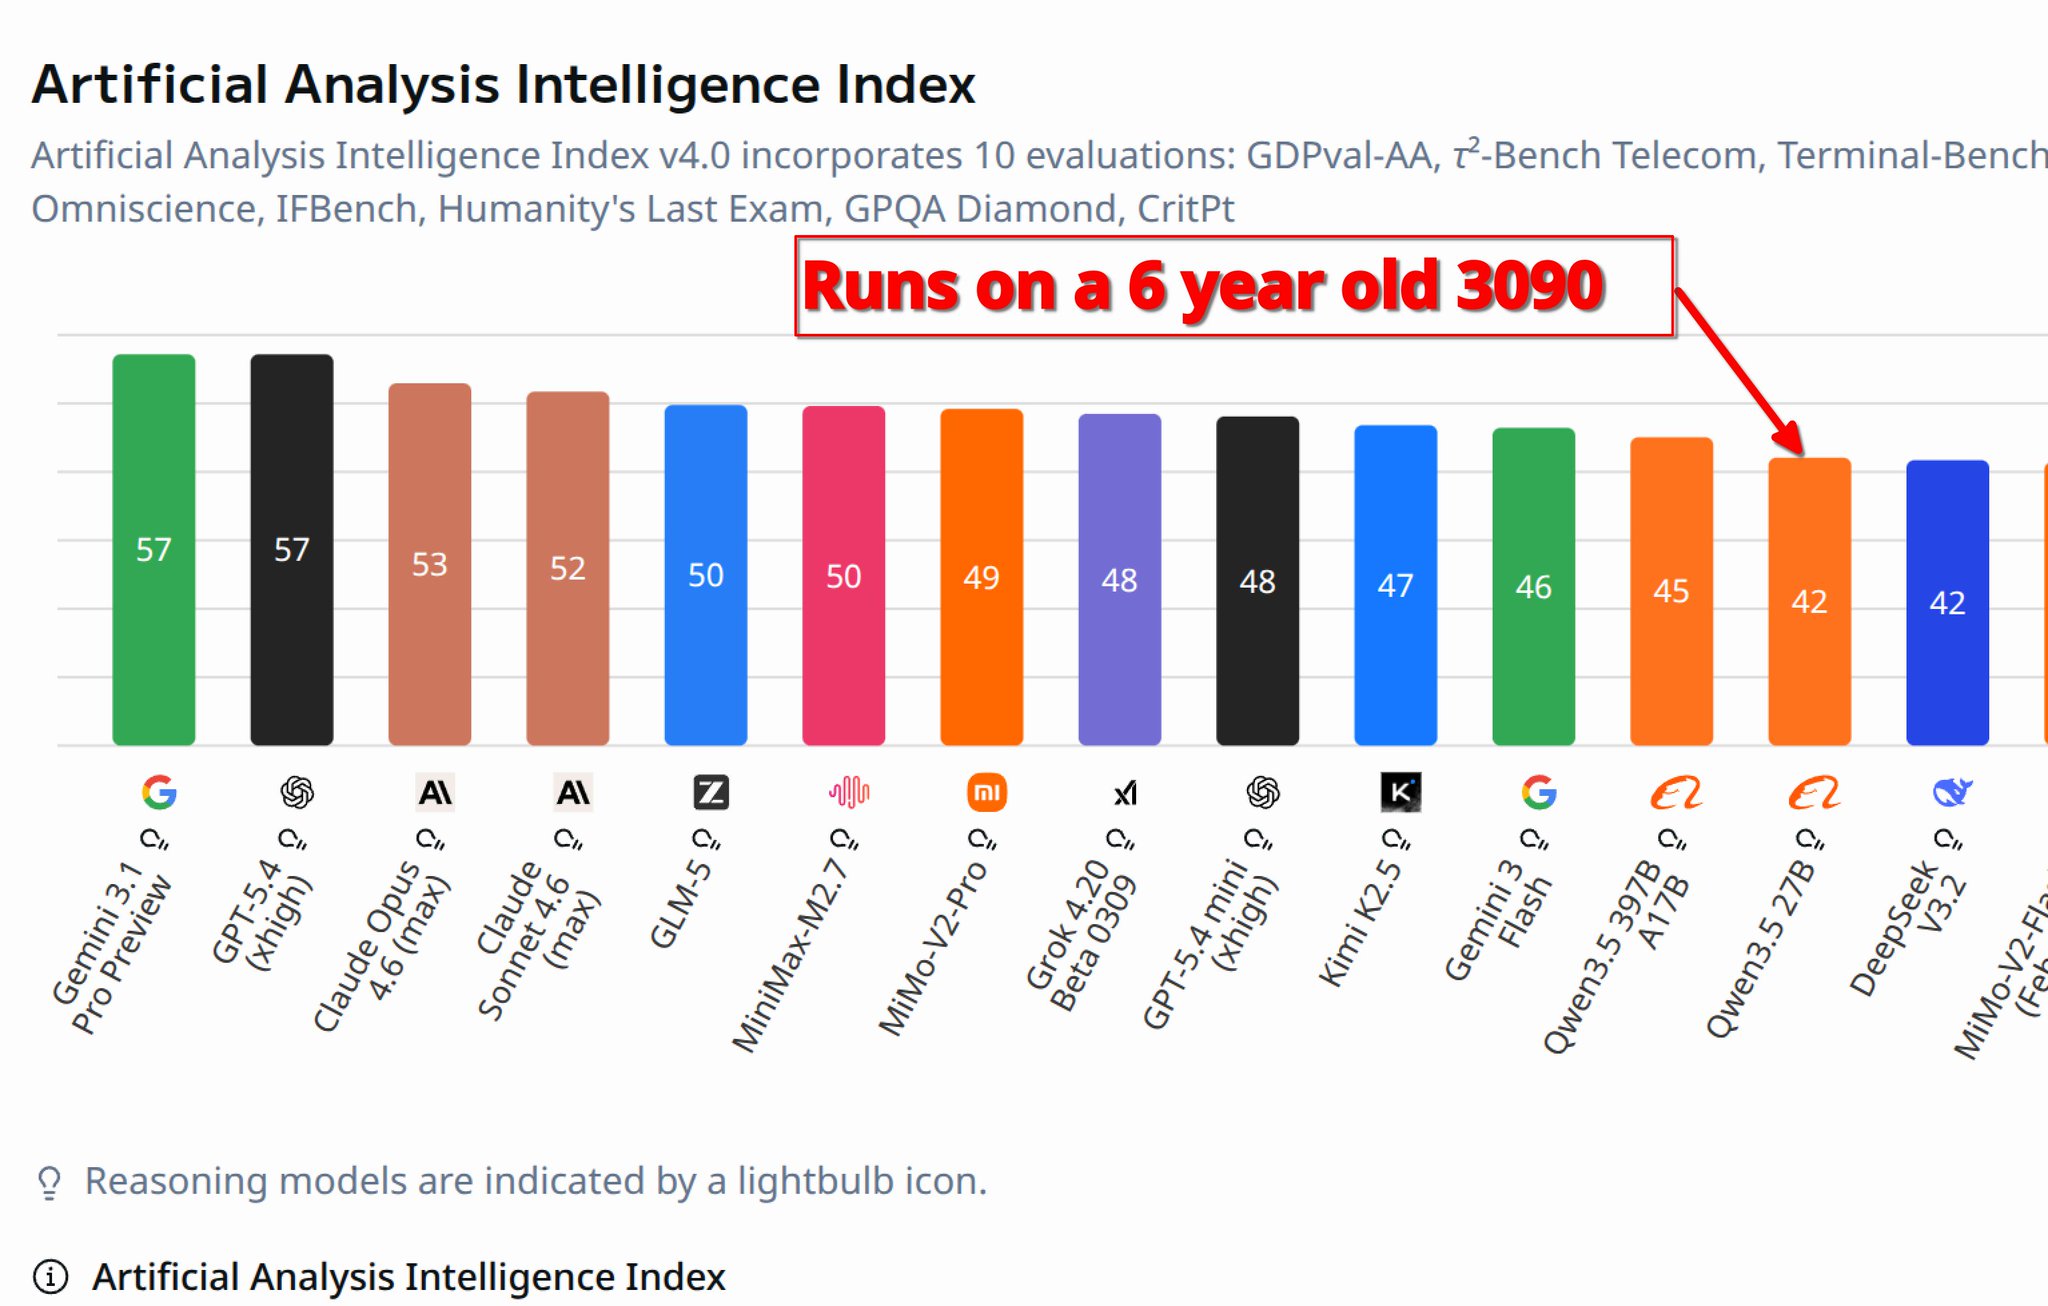
Mine are all running at gen4 x8 when I had only 8x RTX 3090s in this node they were all running at gen4 x16 Also, each pair in the 14 are NVLinked I am not your crypto cryptobro I do this shit for a living
COMPUTING
-
Unified Memory Hardware vs. GPUs for AI Agents
By
–
Unified Memory hardware like – DGX Sparks
– Mac Studios are great for background & periodic agents Any realtime agent (requiring low-latency) demands a GPU -
Notification Protocol Extension Introduced for Systems
By
–
There's a notification protocol extension
-
Software Stack Crucial for Hardware Adoption, GPU Support Lags
By
–
It’s wild to me that folks still don’t understand this A piece of hardware doesn’t matter if the software stack isn’t there Good luck waiting 5 years for that Intel GPU to be widely supported Even the Blackwell kernels aren’t mature yet and it’s already widely adopted lol x.com/AlexKi1993/sta…
-
Moondream 3 MPS Compatibility Tweaks for Apple Silicon
By
–
Moondream 3 doesn't work on Apple MPS out of the box but a a couple of tweaks can make it work.
— Satya Mallick (@LearnOpenCV) 28 mars 2026
1. use float16 on MPS
2. disable flex decoding on MPS (and CPU fallback)
You can also make it work on the CPU, but that option is really bad. It is about 20x slower than MPS. https://t.co/GbdBWMEnVXMoondream 3 doesn't work on Apple MPS out of the box but a a couple of tweaks can make it work. 1. use float16 on MPS
2. disable flex decoding on MPS (and CPU fallback) You can also make it work on the CPU, but that option is really bad. It is about 20x slower than MPS. -
Owning Hardware is a Must Due to Open Source Developments
By
–
Oh, they will. They’d have done by now if it wasn’t for opensource. Owning your compute / hardware is a must
-
User Upgrades Laptop with 128GB RAM for AI Workloads
By
–
My existing laptop was showing its age, and I think 128GB RAM will do me for quite a while
-
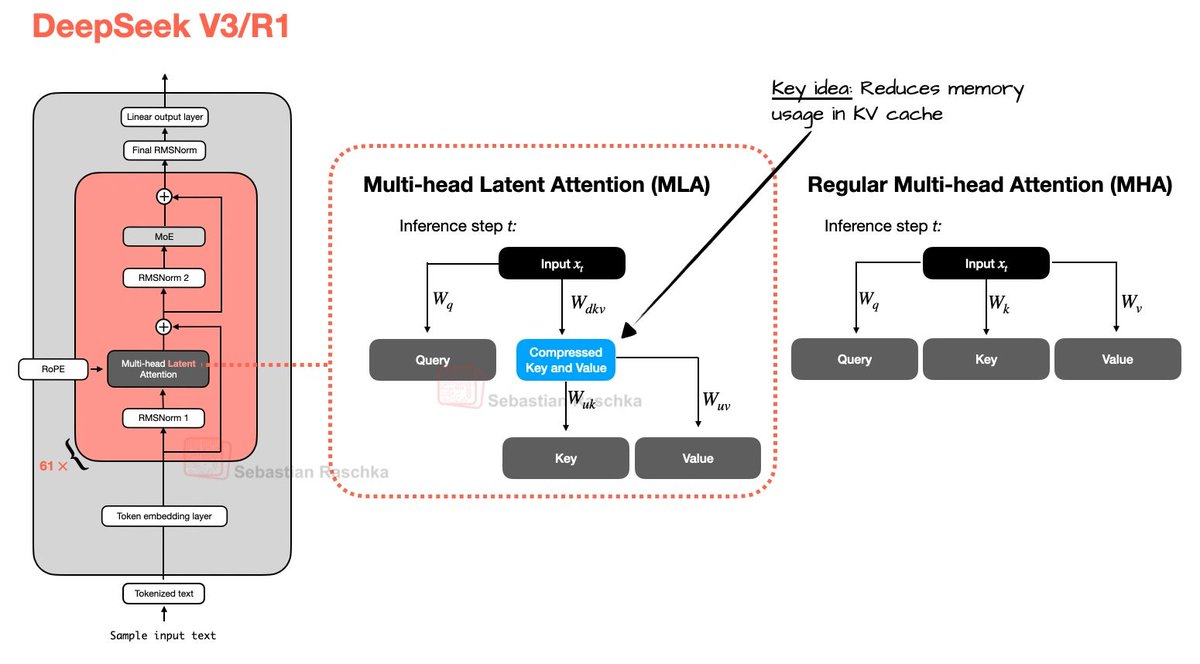
Day 83 GPU Programming: DeepSeek Multi-Head Latent Attention Optimization
By
–
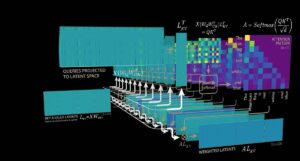
Day 83/365 of GPU Programming Looking at DeepSeek's Multi-Head Latent Attention today. The last part of the AMD challenge series is to optimize an MLA decode kernel for MI355X where the absorbed Q and compressed KV cache are given and your task is to do the attention computation. A resource that really helped internalize what MLA does was @rasbt's incredible visual guide to attention variants in LLMs (luckily he posted that last week!), which covers everything from MHA to GQA to MLA to SWA, et cetera. If there's one place to get a visual intuition for recent attention mechanisms, it's this blog post. @jbhuang0604's video on MQA, GQA,MLA and DSA was the best conceptual intro I found on the topic and progressively builds up the ideas from first principles. The Welch Labs analysis of MLA is a great watch as well. Beautiful visualization of the changes DeepSeek made for MLA. Tried out a few kernels once I had a basic understanding of MLA and I think I'm slowly getting more comfortable with at least analyzing kernels. levi (@levidiamode) Day 82/365 of GPU Programming Taking a closer look at Mixture of Experts today, so I can write better MoE kernels. Specifically, to optimize an MXFP4 MoE fused kernel for the GPU Mode challenge. I haven't had much prior exposure to MoEs, so lots of new concepts I learned today. Luckily I found the best intro to MoEs thanks to @MaartenGr visual overview of the topic. I then watched @tatsu_hashimoto's amazing Stanford CS336 lecture on MoEs, which added deeper context around why MoEs are gaining popularity, FLOPs, OLMoE, infra complexity, routing functions (mindblown this works so well…), expert sizes, training objectives, top k routing and DeepSeek variations. Once I had a basic understanding I started playing around with the some AITER kernels but progress there is tbd. Also had a nice chat with @juscallmevyom (who was kind enough to reach out!) about the AMD kernels and the challenge of materialization overhead. — https://nitter.net/levidiamode/status/2037297869518950430#m