SpaceX (xAI) becoming the next Oracle.
Reflection apparently has immediate access to Nvidia GB300 chips via SpaceX and will pay $150 million per month starting July 1, 2026.
If the deal continues until 2029, the total value would reach approximately $6.3 billion
COMPUTING
-

SpaceX/xAI gets Nvidia GB300 chips for $150M/month
By
–
-
Organize large codebases with path-scoped rules in .claude/rules/
By
–
6/ For a big or messy codebase, do not pile it all into one file. Use path-scoped rules in a .claude/rules/ folder. They load only when Claude touches the matching part of your code, so your context stays clean instead of carrying everything at once.
-
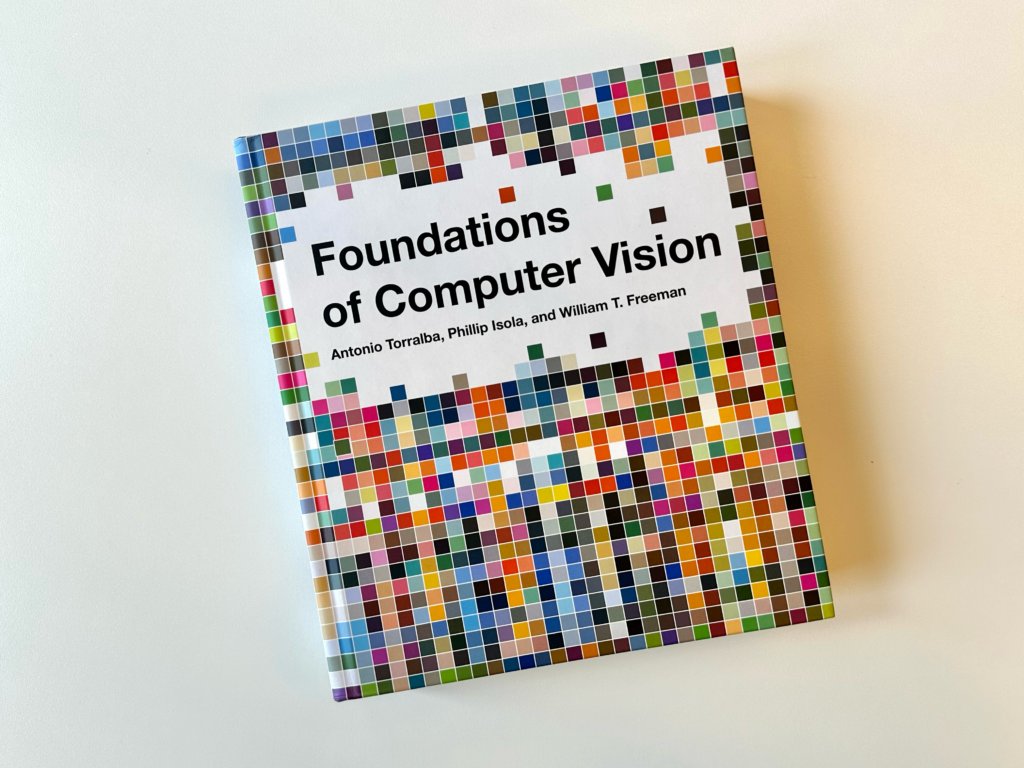
Free MIT guide to key concepts of computer vision
By
–
A free MIT guide to key concepts of computer vision: https://bit.ly/43Tn1vW
-
Autonomous ML Research: Fugu Ultra improves GPT model via AutoResearch
By
–
Use Case 1: Autonomous ML Research
— Sakana AI (@SakanaAILabs) 22 juin 2026
Can an AI autonomously improve another AI’s training recipe?
We tasked Fugu Ultra with improving a small GPT model using AutoResearch. Over 14 hours on a single H100 GPU, Fugu ran > 100 experiments. It iteratively edited the training code, ran… pic.twitter.com/Gp96FEQ797Use Case 1: Autonomous ML Research Can an AI autonomously improve another AI’s training recipe? We tasked Fugu Ultra with improving a small GPT model using AutoResearch. Over 14 hours on a single H100 GPU, Fugu ran > 100 experiments. It iteratively edited the training code, ran
-
SkyRL async RL training with autonomous research agent
By
–
1/4: A couple notes on the implementation. The async RL training itself is powered by SkyRL, with the research agent’s goal being resolving setup issues (in this case a libnuma dependency) and analyzing runs autonomously.
-
Sandboxes: serverless speed and persistent state
By
–
Sandboxes must achieve 2 things at the same time… The speed of a serverless function. You cannot make an agent wait 2 minutes for a VM to start. It must offer the persistent state of a complete machine. Agents are not
-
Real-time streaming inference model for interactive worlds
By
–
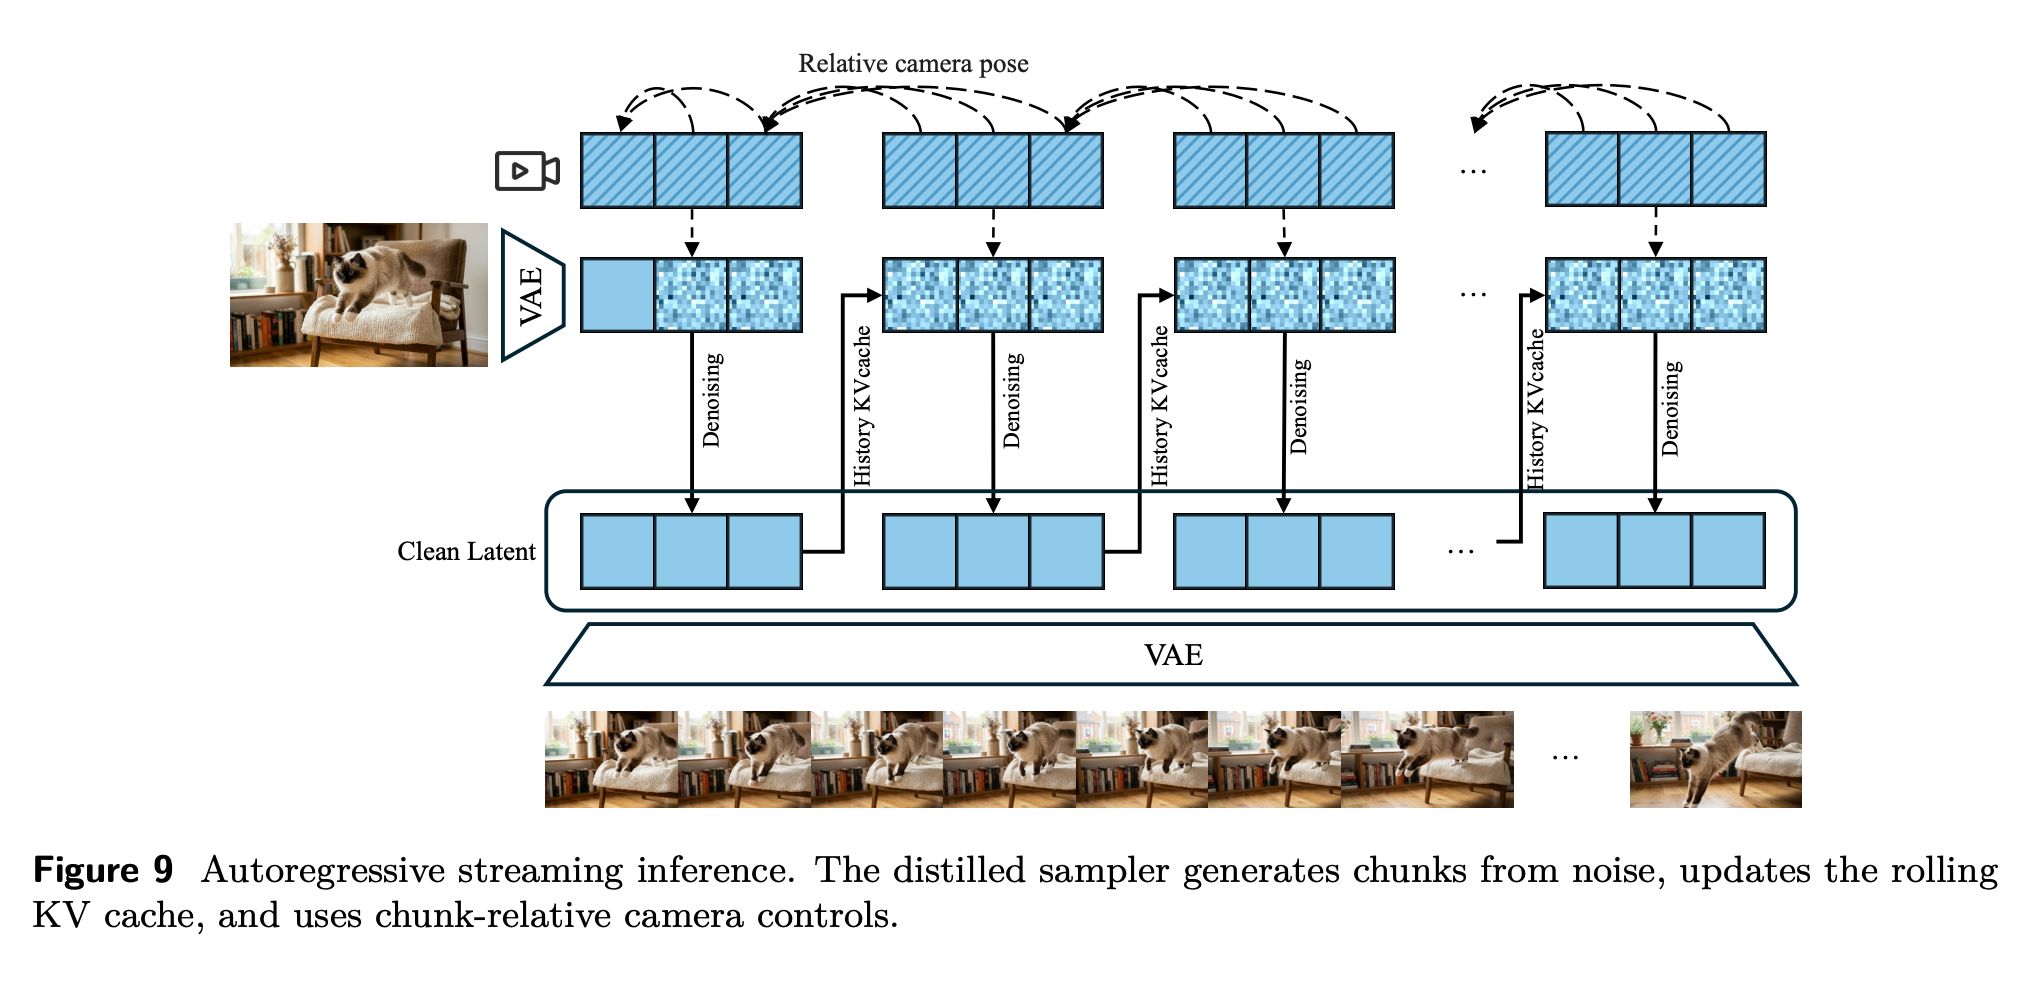
/5 An interactive world isn't truly interactive if it lags. This model is built specifically for real-time streaming inference. Using DMD-style distillation and an autoregressive rolling KV cache, it generates environments chunk-by-chunk from noise. When paired with asynchronous
-

Announcement of new GPT-5.6, Pro, and bidirectional voice models this Thursday
By
–
It looks like we are going to have a whole range of new GPT models this Thursday: GPT-5.6, 5.6 Pro, and a new bidirectional voice model. Initial tests of the voice model have been exceptional, this is exactly what I was hoping for two years ago!
-

Sonnet 5 tests ongoing, excellent release ahead
By
–
It seems that the first tests with Sonnet 5 are already in progress. If this is confirmed, we are in for an excellent release!
