Join the Engineering Development Group (EDG) at MathWorks
COMPUTING
-

Micron Launches Industry’s Fastest HBM for Generative AI
By
–
Micron Delivers Industry’s Fastest, Highest-Capacity HBM to Advance Generative AI Innovation https://
yhoo.it/43XtxhW
#AI #MachineLearning #DeepLearning #LLMs #DataScience -

Renxin Xia Presents speedAI240 2-Petaflop Inference Acceleration Device
By
–
Join Renxin Xia, #VP of #Hardware #Engineering at @UntetherAI
, for an industrial session at the 2023 @ieee_socc this morning. Renxin will present our #2ndGen architecture, "speedAI240: A 2-Petaflop, 30-Teraflops/W At-Memory Inference Acceleration Device." https://
edas.info/p30574#S156961
8625
… -
Jais: Open-Source Arabic NLP Model Performance Breakthrough
By
–
Cerebras welcomes a guest post from Inception CEO Andy Jackson about our recent work together on Jais, the world’s best-performing open-source Arabic model The post details the model architecture, data, hardware, and performance evaluations Read here: https://
cerebras.net/blog/jais-a-ne
w-pinnacle-in-open-arabic-nlp
… -
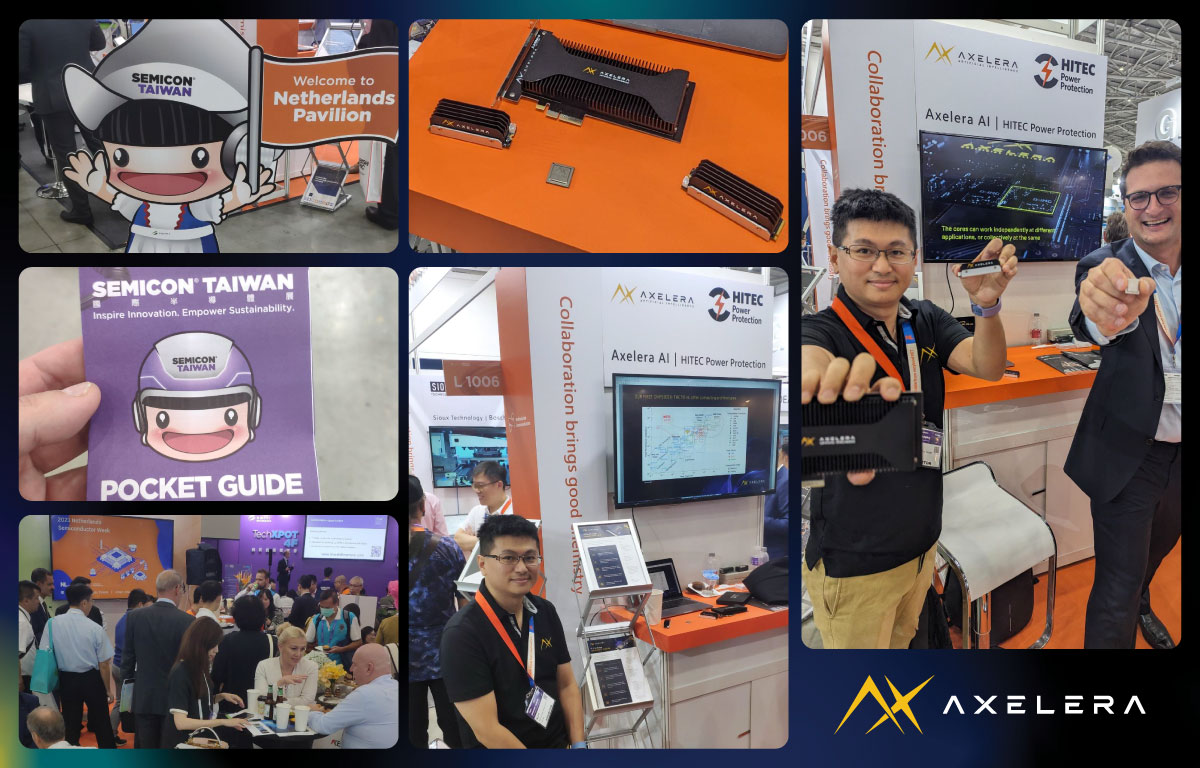
Computer Vision AI Solutions Showcase at Semicon Taiwan 2023
By
–
Today was the first day at #SemiconTaiwan 2023 in the NL Pavilion! We're here to connect and share insights about our computer vision solutions for AI at the edge. Join us if you're around. Date: Sept 6/7 Location: TaiNEX Hall 1, 4th Floor, Booth No. L1006
-
Building AI Products at Scale for Billions
By
–
It has been deeply gratifying to work on incredibly exciting computer science and AI problems with amazing colleagues, & to help build out a suite of 10+ products that each have more than 1B users all over the world.
-
Early Search Systems Engineering Evolution Through Generations
By
–
I gave a talk at WSDM 2009 that talks about some of the early search systems engineering that gives a bit of a flavor of some of the developments through multiple generations of the search system.
-
Search Infrastructure: MapReduce, BigTable, Spanner, Protocol Buffers
By
–
Much of the search system scaling work led to infrastructure creation of things like MapReduce, BigTable, Spanner, protocol buffers, and other things.
-
Unpublished Web Index Scaling Techniques and Data Storage Innovation
By
–
We never published most of the things we did in order to accomplish this scaling. Lots of cool things here like storing data on outside of disk platters for better read bandwidth, better index compression, to then storing the entire web index in RAM (in each serving cluster!)
-
Scaling Search Index from Millions to Billions of Pages
By
–
As our search traffic grew, we were desperately trying to avoid melting every Tuesday around noon (peak traffic for the week), while simultaneously improving the service. Making the index bigger (30M->70M->200M->500M->1B pages and beyond in a short span), …