BGP antics for a start. Then, who has kompromat on one of the DNS root signing key guys, or the NTP maintainers?
COMPUTING
-
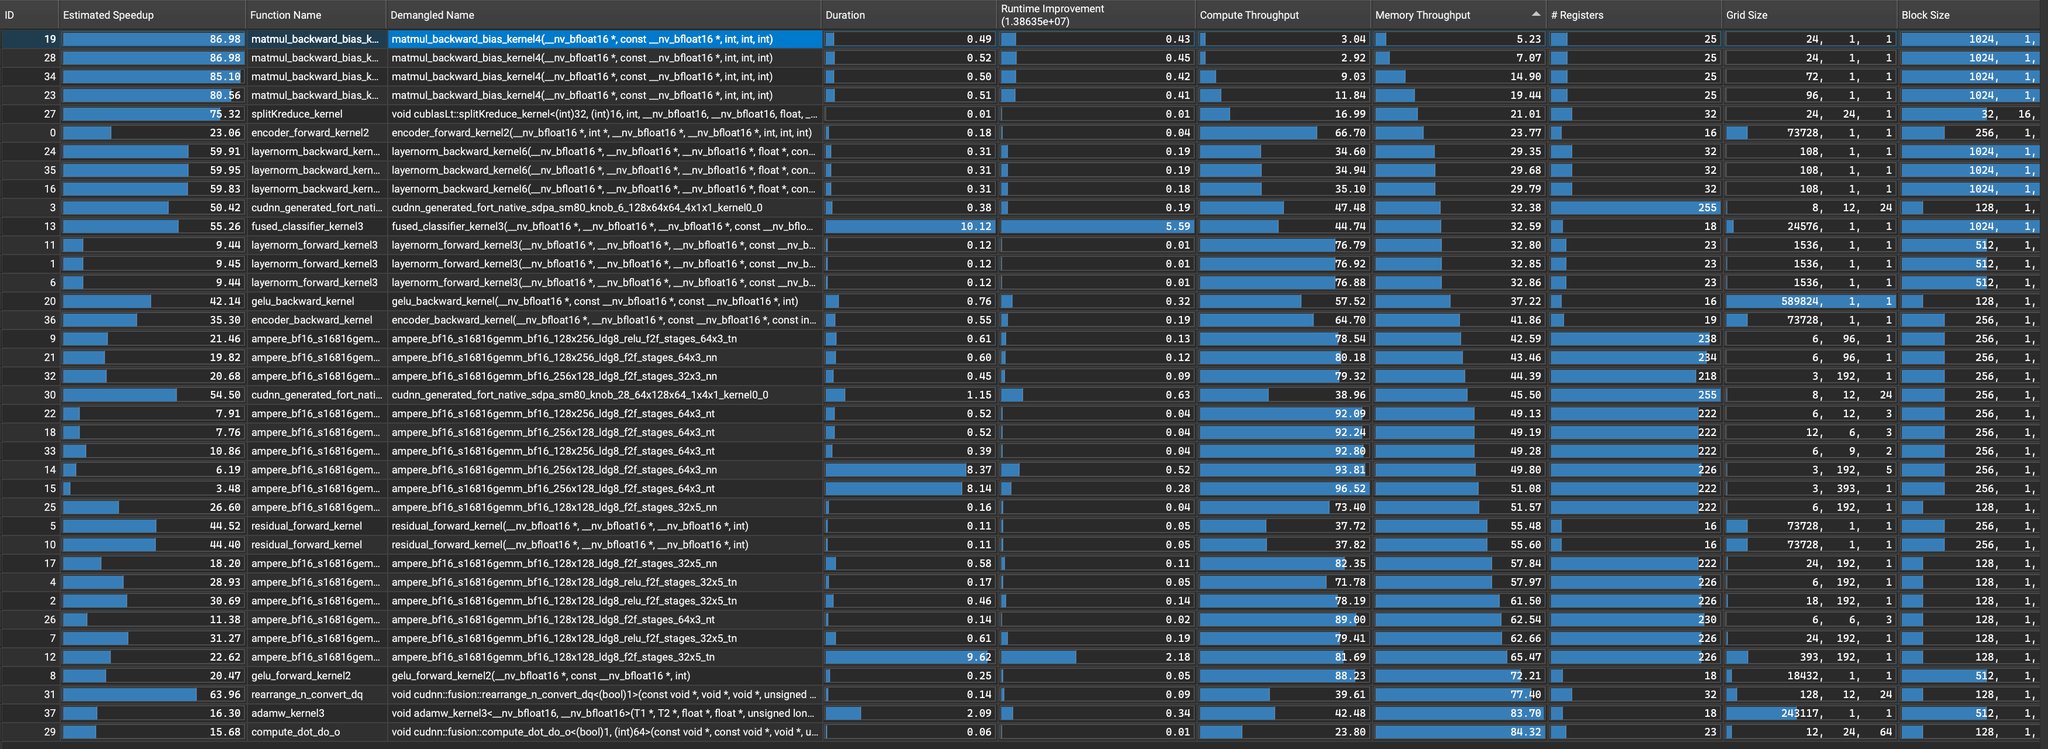
cuBLASLt and cuDNN Dependencies for Optimized Performance
By
–
Yes, cuBLASLt for gemms, cuDNN for flash attention
The fp32 version will become more educational and will delete these dependencies. The "mainline" version we just want to be really fast, so we're less discriminating. cuBLASLt I think is ~ok dep, but cuDNN turned out surprisingly -
Cerebras AI Innovation Solutions for Enterprise
By
–
Work with winners! Learn how Cerebras can bring AI innovation into your company. Contact us here: https://
cerebras.net/contact-us/ -
llm.c Day 24: Multi-GPU Training in C/CUDA Outperforms PyTorch
By
–
Day 24 of llm.c: we now do multi-GPU training, in bfloat16, with flash attention, directly in ~3000 lines of C/CUDA, and it is FAST! We're running ~7% faster than PyTorch nightly, with no asterisks, i.e. this baseline includes all modern & standard bells-and-whistles: mixed
-
MacBook Pro M2/M3 pricing impacts personal laptop ownership trends
By
–
A good M2/M3 MacBook Pro is $4,000+ I imagine a lot of people no longer have a personal laptop in the same class as their work laptop these days
-
MacBook M1 Pro achieves 20-25 tokens per second performance
By
–
Totally, depends on the usecase and the number of users you concurrently want to serve. I get 20-25 tokens/sec on my Macbook M1 pro 16 GB.
-
Run Llama-3 locally on your computer for free
By
–
Bonus: 3 ways to run Llama-3 locally on your computer (100% free and without internet)
-

Cerebras SDK 1.1.0 Unleashes WSE-3 High-Performance Computing
By
–
Unlock the full potential of high-performance computing with the latest Cerebras SDK! We recently released the Cerebras SDK 1.1.0, now offering initial support for the groundbreaking Cerebras WSE-3. Our SDK has already enabled researchers at TotalEnergies, KAUST, and
-

Energy-Efficient AI Inference Acceleration Workshop with Untether AI
By
–
Join Bill Jenkins, UAI's Sr. Director of Technical Marketing, at @CMCMicrosystems
' 5th Annual Accelerating AI Workshop on May 8th (2:40pm-3pm) as he presents "Energy-Efficient AI Inference Acceleration with Untether AI". Register now! https://
cmc.ca/accelerating-a
i-workshop-2024/
… -
Llama-3 Memory Requirements: 5GB to 40GB Across Model Sizes
By
–
Nope. From 5 GB for llama-3 8B to 40GB for llama-3 70B. Check it out here at @ollama
: