so much more fun to use a computer via codex
CODE
-
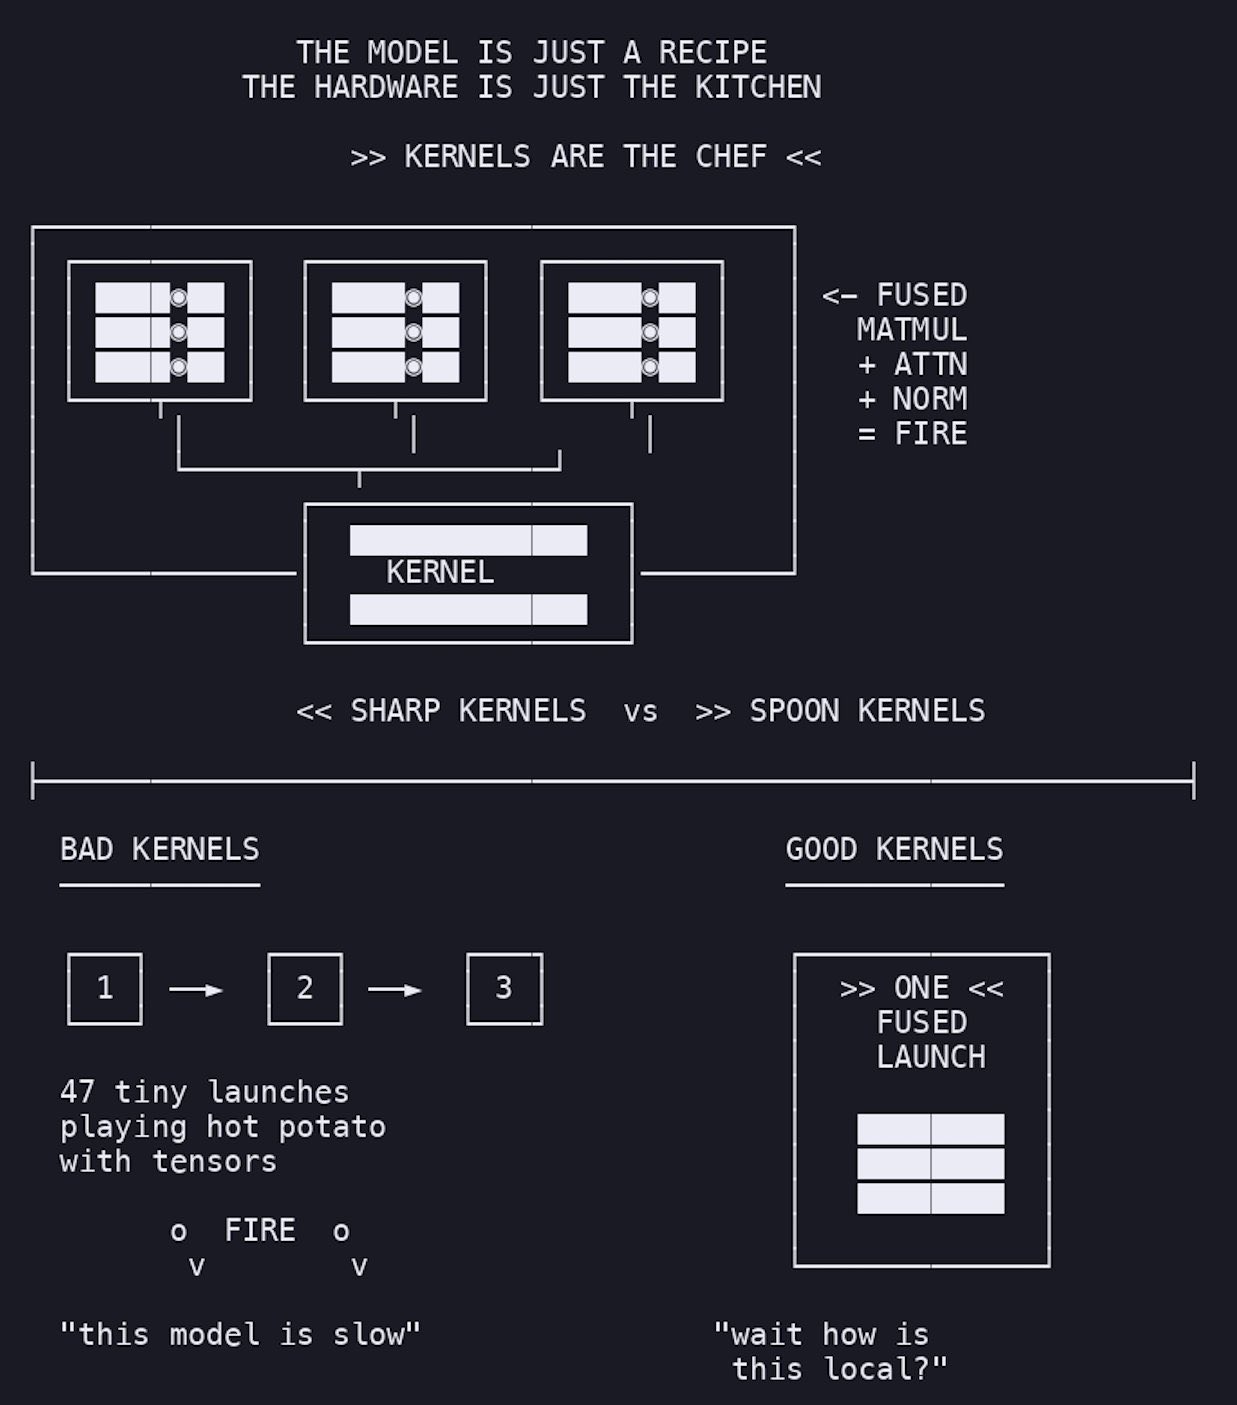
Kernels Are the Actual Work in Model Inference
By
–
You don’t “run a model”
You run Kernels The model is just a graph The Inference Engine is scheduler / optimizer / executor But the actual work? That happens in the Kernels – MatMul Kernels
– Attention Kernels
– RMSNorm Kernels
– KV cache Kernels
– Quantized linear Kernels
– -

Seeking Frontier Research Scientists and Core Engineers for Recursive Self-Improvement
By
–
We didn’t just start working on Recursive Self-Improvement yesterday. We have been methodically shipping the foundations for two years. To execute the next phase of this mission, we are seeking a select group of distinguished Frontier Research Scientists and Core Engineers. We
-

ActiveGraph coding agent always provides trace and graph
By
–
and here's what a coding agent on activegraph looks like basically you always get a trace and a graph automatically
-
Agent put on the case, fast AI debug
By
–
Thank you, I'm immediately putting an agent on it, it will be fixed in the next few minutes. The platform integrates an AI that debugs all this nonsense from the inside, it will be fast.
-

Real-world agentic leaderboard from Arena measures actual performance
By
–

Huge! Real-world agentic leaderboard from Arena. Instead of synthetic benchmarks, it measures how models actually perform when real users put them to work – writing code, debugging projects, researching the web, building apps, analyzing documents. The methodology is different
-
Claude’s new version design, Mythos Preview achieves 52x training speedup
By
–
🚨 Dario confirmed that Claude is currently designing the next version of itself.
— Charly Wargnier (@DataChaz) 5 juin 2026
To test this, the company asks its new models to optimize the training code for smaller AIs.
While Claude Opus 4 achieved a 3x speedup, Mythos Preview hit a staggering 52x 🤯
Recursive… pic.twitter.com/MONKQ9g1aZDario confirmed that Claude is currently designing the next version of itself. To test this, the company asks its new models to optimize the training code for smaller AIs. While Claude Opus 4 achieved a 3x speedup, Mythos Preview hit a staggering 52x Recursive
-
Deploy Google ADK agents to LangSmith with one function call
By
–
You can now deploy Google ADK agents to LangSmith! Wrap your ADK agent with one function call and deploy it to managed infra, with built in: Session persistence Streaming Tracing
-

Karpathy’s 2015 RNN coding experiments and 2017 gradient descent advances
By
–
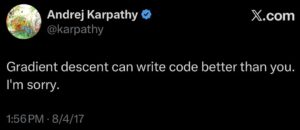
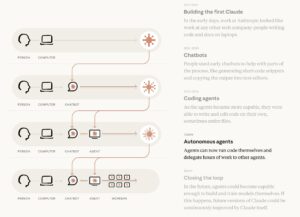
2015: Karpathy publishes one of the earliest experiments (if not the first public article/blog with practical artifacts) on language models for coding (The Unreasonable Effectiveness of Recurrent Neural Networks). 2017: @karpathy again: gradient descent can write code better
-
Luca centralizes 12 Google Drives into an AI hub with Replit
By
–
Luca (@agi2asi) built Grid to centralize 12 different Google Drives into one hub.
— Replit ⠕ (@Replit) 5 juin 2026
With Replit, he turned a prompt into an AI-powered employee hub in just 10 minutes. Now, team members can ask about anything from seating charts to expense policies.
Always Be Building. pic.twitter.com/F2qlIK85lHLuca (@agi2asi) created Grid to centralize 12 different Google Drives into a single hub. With Replit, he turned a prompt into an AI-powered employee hub in just 10 minutes. Now, team members can ask questions about anything, from plans