Snorkel contributed: • An agentic RL eval environment • FinQA-Reasoning dataset • Finance Reasoning benchmark Full technical breakdown from the rLLM team + our enterprise takeaways here:
CODE
-
Tool Discipline Improves AI Reasoning Better Than Scale
By
–
Key insight: tool discipline > scale. Instead of complex multi-table training, we reinforced reliable tool use on simple queries — and saw transfer to 12-step reasoning tasks (59.7% Pass@1).
-

Databricks AppKit and Replit Speed Enterprise App Development
By
–
Ship enterprise apps faster with Databricks AppKit and @Replit
. AppKit is a TypeScript framework with built-in observability and seamless integration with Databricks services. The new Replit integration lets you develop data-aware apps using natural language and deploy directly -
Agentic AI Tools in Software Engineering and Risk Monitoring
By
–
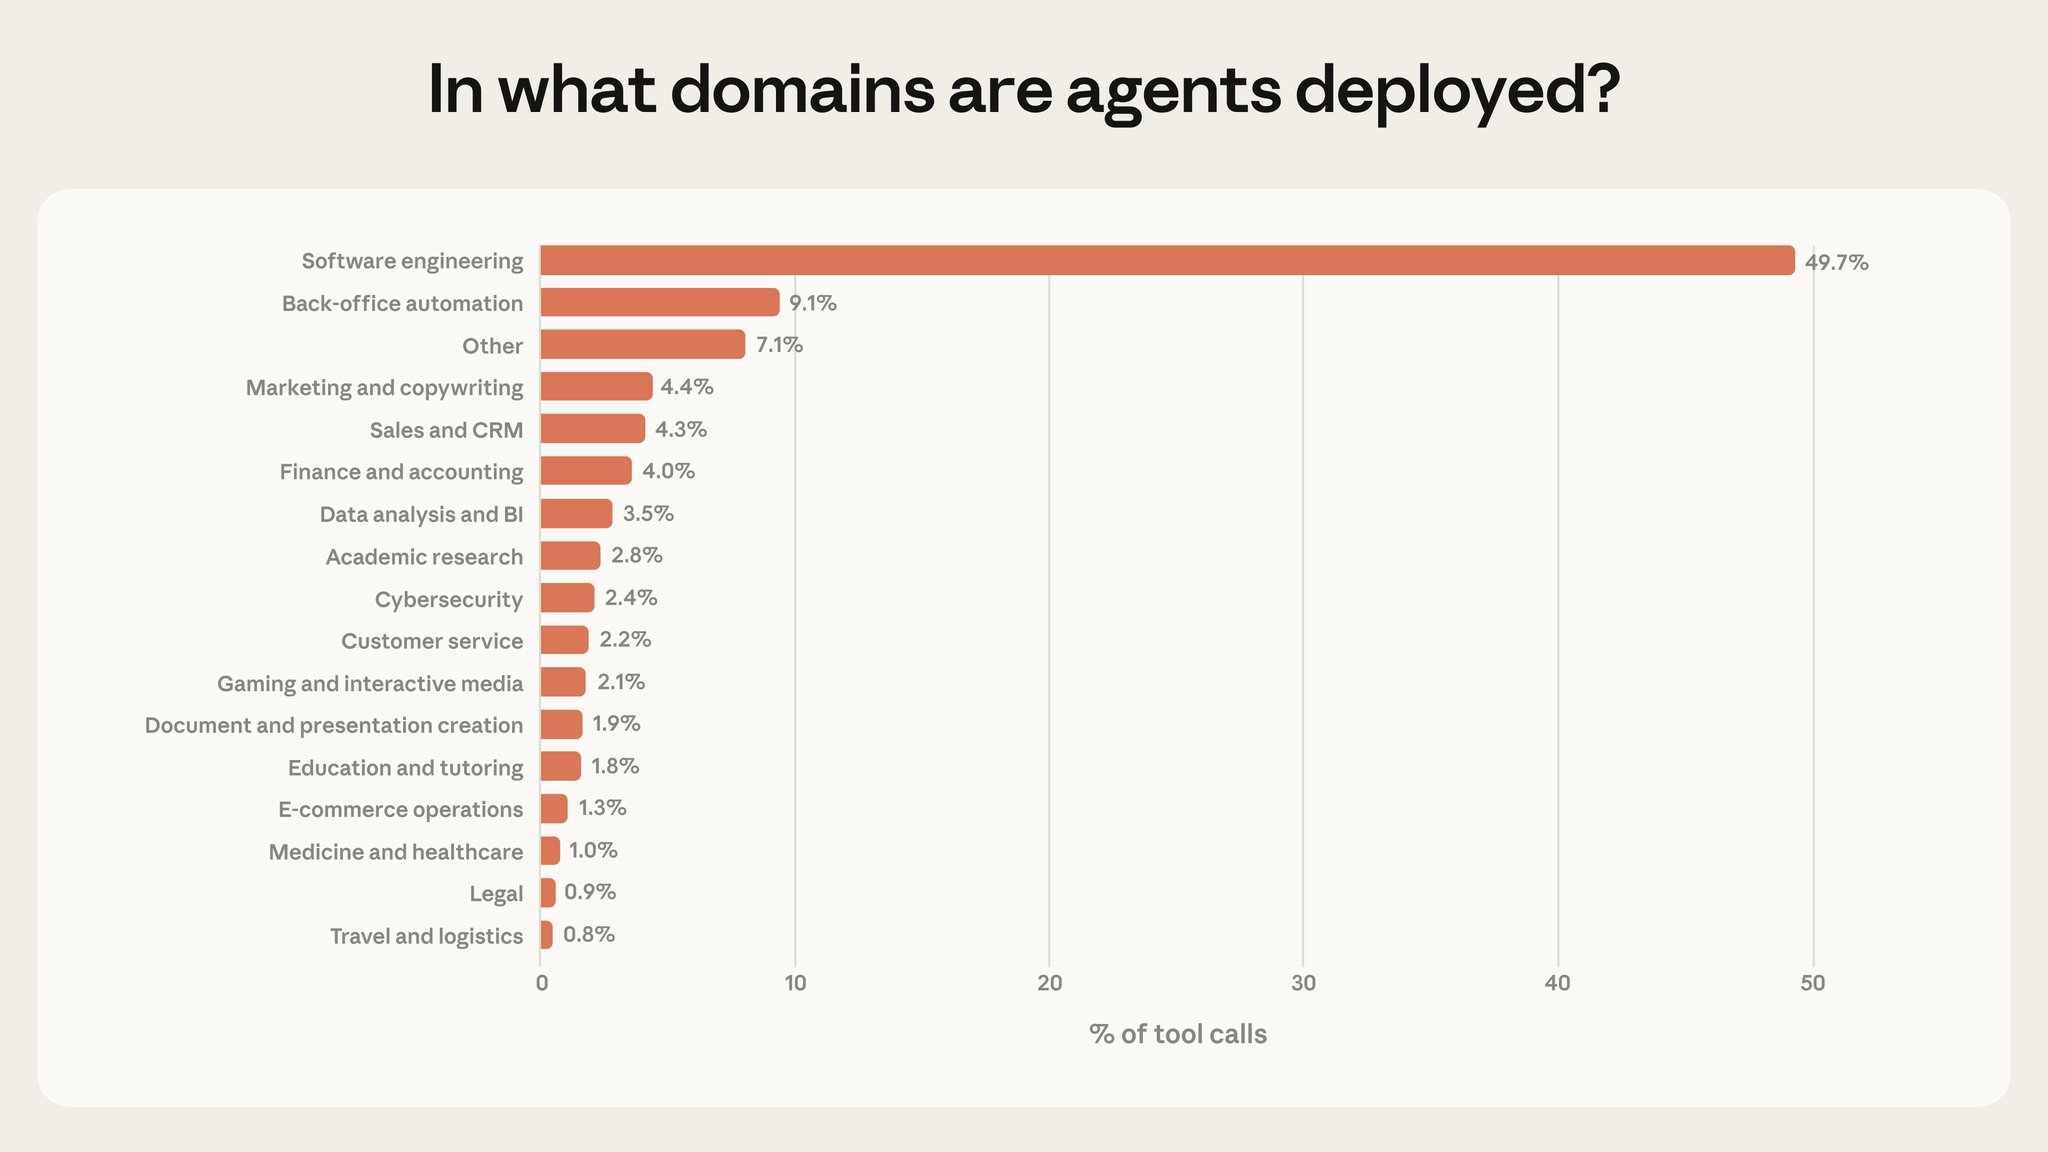
Software engineering makes up ~50% of agentic tool calls on our API, but we see emerging use in other industries. As the frontier of risk and autonomy expands, post-deployment monitoring becomes essential. We encourage other model developers to extend this research.
-

Claude Code Enhances AI Safety Through Uncertainty Recognition
By
–
Claude Code also encourages oversight by stopping to ask questions. On complex tasks, Claude Code pauses for clarification more than twice as often as humans interrupt it. Training models to recognize uncertainty is an important, under-appreciated safety property.
-

User Experience Shift: Interruptions Increase With Claude Code Experience
By
–
But interruptions also increase with experience. New users interrupt Claude Code in 5% of turns, compared to 9% for more experienced users. This suggests a shift from approving each action to delegating and interrupting when needed.
-

Claude Code Autonomy Growing: 99.9th Percentile Turns Double
By
–
Most Claude Code turns are short (median ~45 seconds). But the longest turns show where autonomy is heading. In three months, the 99.9th percentile turn duration nearly doubled, from under 25 minutes to over 45 minutes. This growth is smooth across model releases.
-

OpenAI and Paradigm launch an EVMbench to evaluate AI agents
By
–

OpenAI and @paradigm introduced a new EVMbench to measure how AI agents can detect, exploit and fix vulnerabilities in smart contracts.
-
EVMbench: AI Agents Detecting Smart Contract Vulnerabilities
By
–
Introducing EVMbench—a new benchmark that measures how well AI agents can detect, exploit, and patch high-severity smart contract vulnerabilities.
-
LangSmith Agent Builder Major Update: New Chat and File Features
By
–
🚀 We just shipped a major update to LangSmith Agent Builder:
— LangChain (@LangChain) 18 février 2026
• New agent chat: One always-available agent with access to all your workspace tools
• Chat → Agent: Turn any conversation into a specialized agent with one click
• File uploads: Attach files directly to Agent… pic.twitter.com/tNDIKLTcY4We just shipped a major update to LangSmith Agent Builder: • New agent chat: One always-available agent with access to all your workspace tools
• Chat → Agent: Turn any conversation into a specialized agent with one click
• File uploads: Attach files directly to Agent