not just plain MoE but LatentMoE 🙂
CODE
-
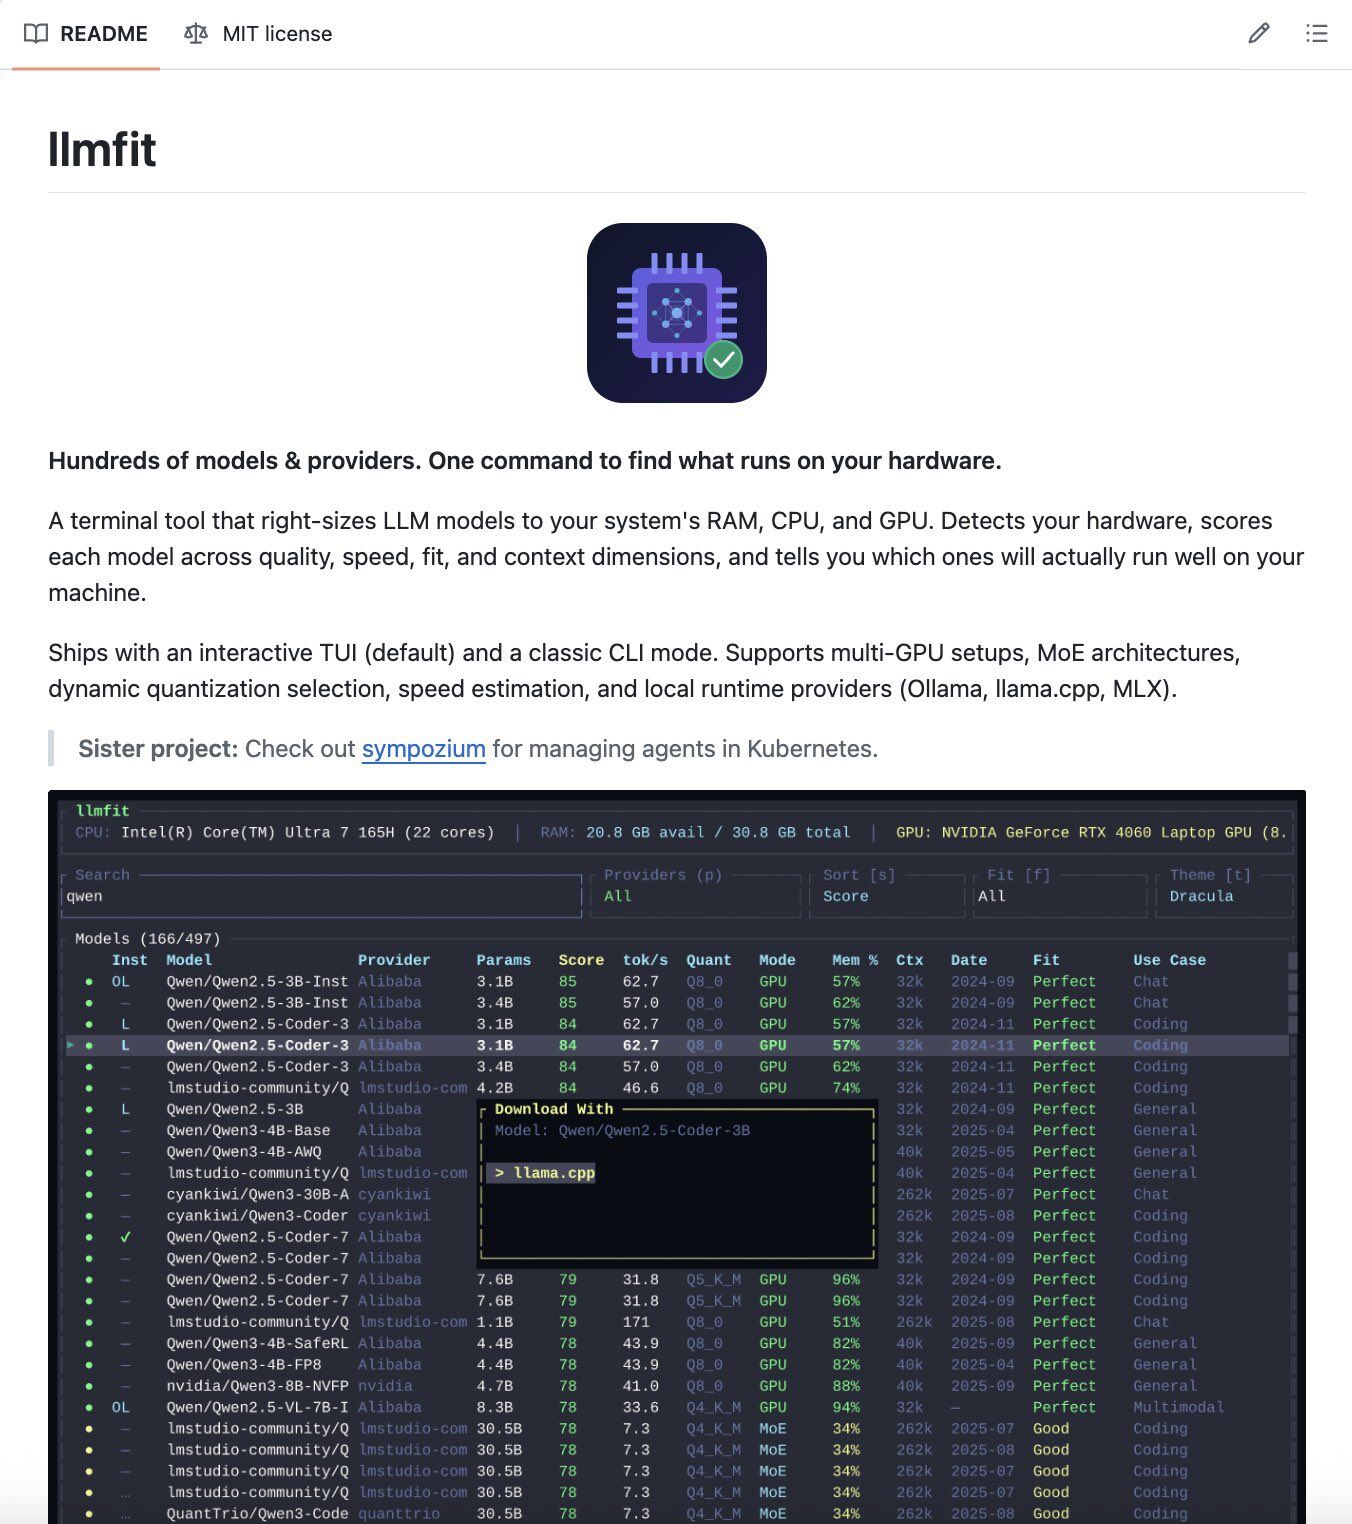
llmfit: Auto-detect hardware and rank 206 models by VRAM compatibility
By
–
Stop guessing which models fit in your VRAM! llmfit is a CLI tool that auto-detects your hardware and ranks 206 models by what actually runs on your system. You download a 70B model and hope it fits. Or you estimate memory requirements across quantization levels and still end
-
GitHub Repository for AI Engineering Hub with Secure Deployment Steps
By
–
Glad you liked it Avi! Here's I have put together all the steps in this Markdown file with all the commands: https://
github.com/patchy631/ai-e
ngineering-hub/tree/main/openclaw-secure-deployment
… -
Model optimization: context reduction saves download resources
By
–
Yeah and it tries half context if nothing fits at full. Saves you from downloading models that won't work
-
CLI vs MCP: Single-User Hackers Enterprise Teams
By
–
CLI: Good for single-user mode, hackers.
MCP: Good for multi-user mode, teams/enterprises. -
CLI vs MCP: Single-User Hackers versus Multi-User Teams
By
–
CLI: Good for single-user mode, hackers.
MCP: Good for multi-user mode, teams/enterprises. -
CLI vs MCP: Single-user versus Enterprise AI Interfaces
By
–
CLI: Good for single-user mode, hackers.
MCP: Good for multi-user mode, teams/enterprises. -
Practical Linear Algebra for Data Science with Python Applications
By
–
Practical Linear Algebra for #DataScience — From Core Concepts to Applications Using #Python — http://
amzn.to/3WWJKR4
————
#DataScientist #AI #ML #MachineLearning #Mathematics -
Naive Bayes Classification Explained with Python Code and Resources
By
–
Naive Bayes Classification, explained with Python code: https://
github.com/taspinar/siml/
blob/master/notebooks/Naive_Bayes.ipynb
…
++
Learn more in this book: http://
amzn.to/312hAHF
————
#DataScience #MachineLearning #AI #ML #Algorithms #Statistics #DataScientist #Mathematics -
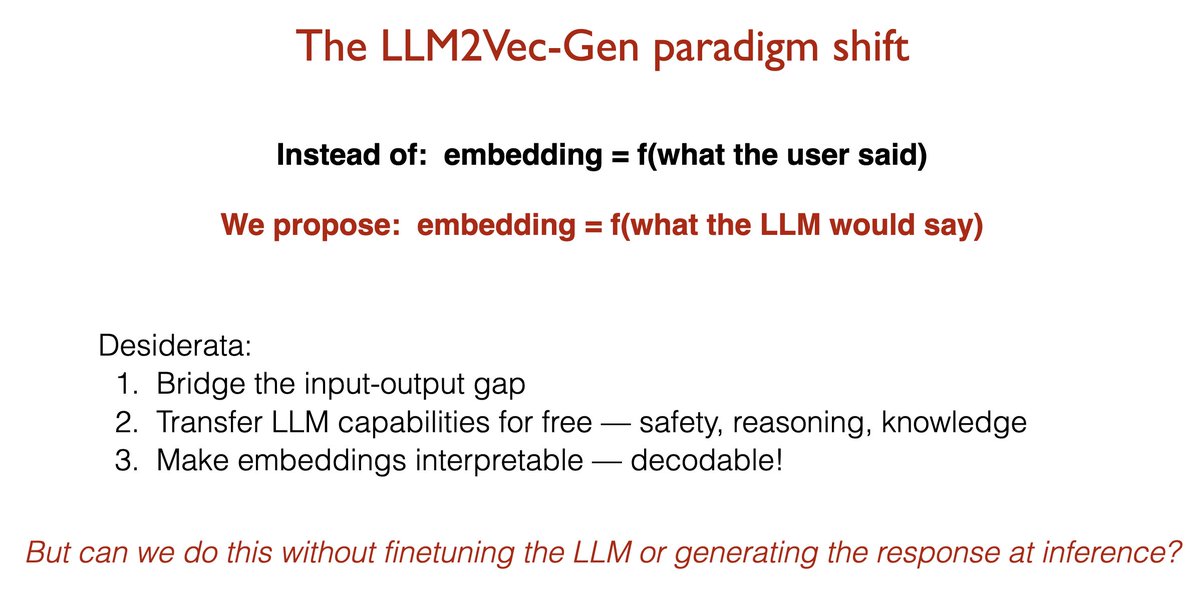
LLM2Vec-Gen: Frozen LLMs Generate Better Embeddings Through Reasoning
By
–
LLM2Vec-Gen represents a major paradigm shift for embeddings/retrieval. Why encode the query when the LLM already knows what to look for and can directly produce an embedding for it? Best part: it’s self-supervised, and it does all of this while the LLM remains completely frozen. Think about it: "solve x² + 3x − 4 = 0" has zero reasoning in it. But the LLM's response does. By encoding the response, the embedding captures the reasoning — and the better the LLM reasons, the better the embedding. This is why our results scale with model size. As LLMs get smarter, our embeddings automatically get better. LLM2Vec-Gen is also the first demonstration of the promise of @ylecun's JEPA for text embeddings. The alignment loss is JEPA — predict in representation space, not token space. The reconstruction loss goes beyond — it keeps embeddings decodable. This paradigm shift opens new frontiers: 🔬 Can we build a full JEPA for language where the teacher and student are the same LLM? ⚡ Can LLMs reason in compressed space without ever generating text? 🤖 Can agents reason in compression tokens and carry that directly into retrieval? 💬 Can agents talk to each other in compression tokens instead of text — dense, fast, and still human-readable? LLM2Vec-Gen is a first step toward all four. Vaibhav Adlakha (@vaibhav_adlakha) Your LLM already knows the answer. Why is your embedding model still encoding the question? 🚨Introducing LLM2Vec-Gen: your frozen LLM generates the answer's embedding in a single forward pass — without ever generating the answer. Not only that, the frozen LLM can decode the embedding back into text. 🏆 SOTA self-supervised embeddings 🛡️ Free transfer of instruction-following, safety, and reasoning — https://nitter.net/vaibhav_adlakha/status/2032065008603951187#m
→ View original post on X — @hugo_larochelle, 2026-03-12 12:37 UTC