Damn! Codex finished the task in 2 minutes. Claude Code took 30 minutes and failed.
→ View original post on X — @romainhuet, 2026-03-30 17:22 UTC
By
–
Damn! Codex finished the task in 2 minutes. Claude Code took 30 minutes and failed.
→ View original post on X — @romainhuet, 2026-03-30 17:22 UTC
By
–
Which models would you recommend for longer context tool calling? Are there any benchmarks for that which you find credible? I've not found a local model with tool calling good enough for me to trust with Claude Code or Codex, but I may not have been looking at the right options
By
–
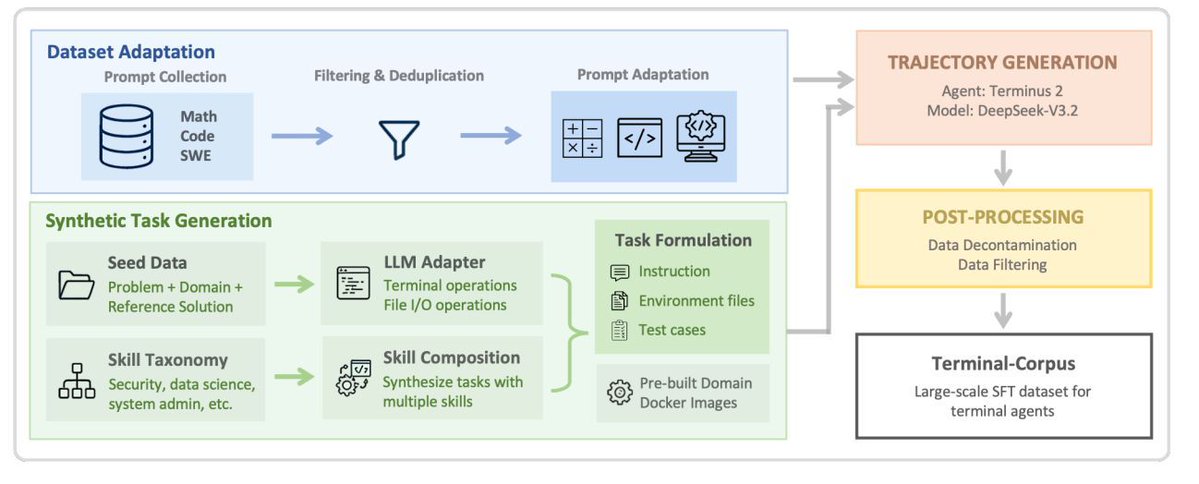
On Data Engineering for Scaling LLM Terminal Capabilities buff.ly/AKibXBi #AI #MachineLearning #DeepLearning #LLMs #DataScience
→ View original post on X — @miketamir, 2026-03-30 16:05 UTC
By
–
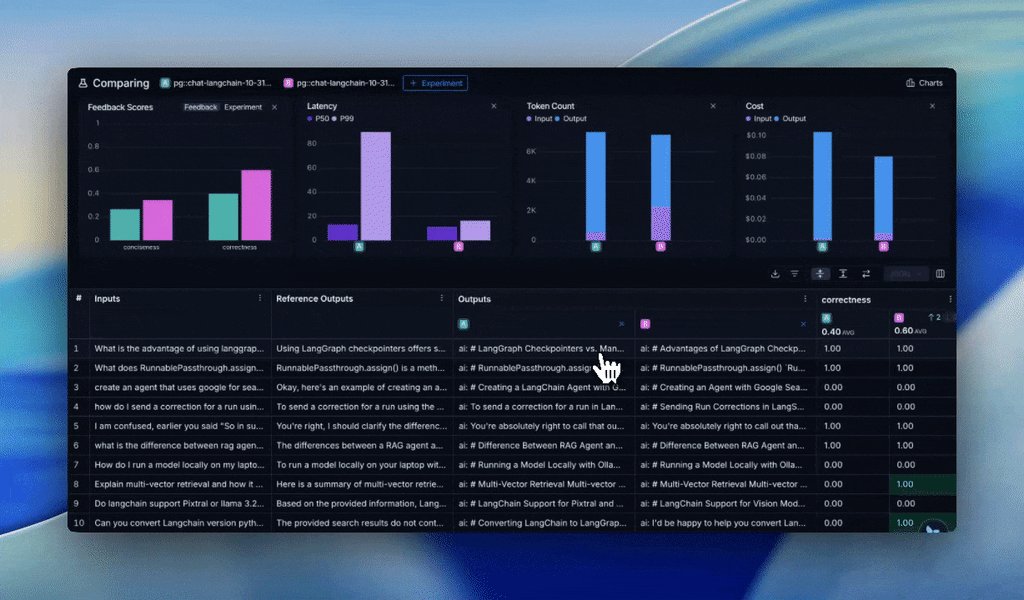
The hardest part of debugging an AI agent isn't knowing it failed–it's knowing why.
— LangChain (@LangChain) 30 mars 2026
We rebuilt the detail view in LangSmith Experiments from the ground up to answer that question faster.
Next time you click and inspect any experiment results, you will find:
* Less clutter
*… pic.twitter.com/x50OxCJxnW
The hardest part of debugging an AI agent isn't knowing it failed–it's knowing why. We rebuilt the detail view in LangSmith Experiments from the ground up to answer that question faster. Next time you click and inspect any experiment results, you will find:
* Less clutter
*
By
–
That would only be true if the losses didn’t share any computation. I would think the far more common case of multiple losses would be regularizations on a shared set of layers, in which case splitting the loss backwards would still give the same result, but be early twice as

By
–
// Coding Agents are Effective Long-Context Processors // We are just touching the surface of what's possible with coding agents. LLMs struggle with long contexts, even the ones that support massive context windows. It turns out coding agents already know how to solve this; you just need to reframe the problem. This work places massive text corpora into directory structures and lets off-the-shelf coding agents (Codex, Claude Code) navigate them with terminal commands and Python scripts. This is great, as you are not feeding massive text directly into a model’s context window or relying on semantic retrieval. Results: – On BrowseComp-Plus (750M tokens), this approach scores 88.5% vs 80% best published. – On Oolong-Real (385K tokens), 33.7% vs 24.1%, a 56% relative improvement. – GPT-5 full-context baseline only manages 20% on BrowseComp-Plus. Works up to 3 trillion tokens. Instead of scaling context windows or building retrieval pipelines, coding agents that already know how to navigate file systems can process virtually unlimited context. The agents autonomously develop task-specific strategies: writing scripts, iterative query refinement, and programmatic aggregation. Paper: arxiv.org/abs/2603.20432 Learn to build effective AI agents in our academy: academy.dair.ai/

By
–
Okay LLM + PyTorch people, trunc_normal_, what the fuck! Many LLM inits use it w/ default cutoffs. It's either not doing anything or it's quite broken due 2 issues. 1. The a/b cutoffs in PyTorch are not in std-devs, they are absolute. So w/ a std=0.02, and -2/2 (default arg) cutoffs that's 100σ!! That is a normal distribution, trun isn't doing anything. 2. There are numerical issues. Even in float32, the truncation produces a handful of -2 (lower cutoff) values, 100σ!! That's incomprehensibly improbable. I doubt a float32 or even float64 algo could even produce it, but clamping a bad float value does. Olmo (@allenai codebases) appear to be one of the few that uses trunc_normal_ and bothered to set the cutoffs properly. It'd be nice to see more train code opened up as a default. We so often only end up with a sanitized version of the inference/fine-tune friendly model these days and may lose details like original init. I've known about #1 for ages, I have an alternate trunc_normal_tf_ implementation in timm for that reason. But I saw those -2's last week when I was debugging something and was a little surprised.
→ View original post on X — @jeremyphoward, 2026-03-30 15:09 UTC
By
–

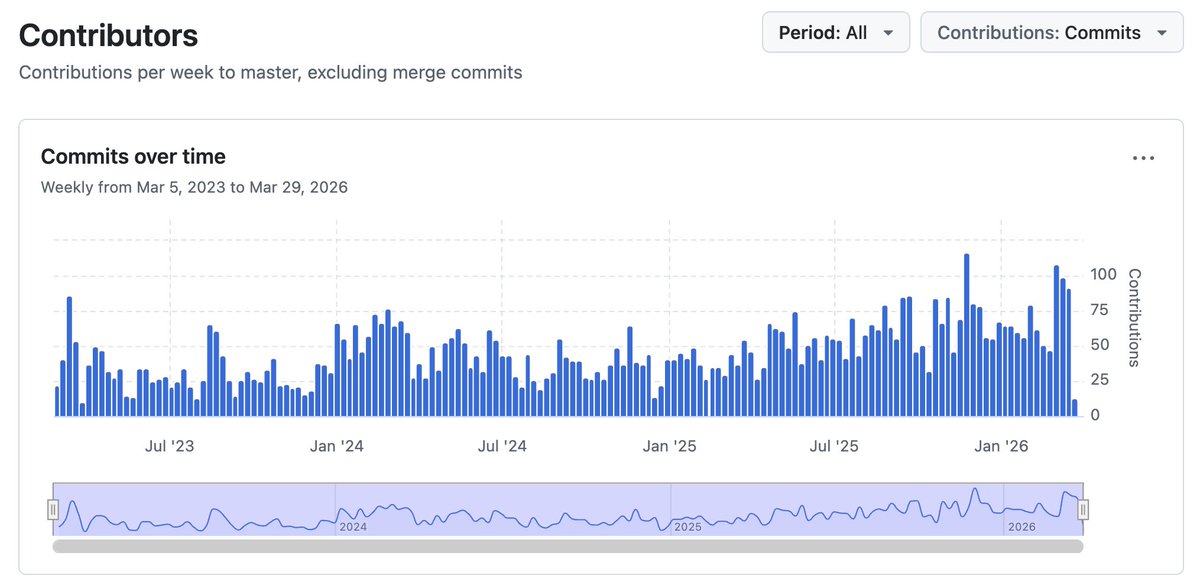
llama.cpp at 100k stars now that 90% of the code worldwide is being written by AI agents, I predict that within 3-6 months, 90% of all AI agents will be running locally with llama.cpp 😄 Jokes aside, I am going to use this small milestone as an opportunity to reflect a bit on the project and the state of AI from the perspective of local applications. There is a lot to say and discuss and yet it feels less and less important to try to make a point. Opinions about viability of local LLMs are strongly polarized, details are overlooked, the scientific approach is lacking. Arguments are predominantly based on vibes and hype waves. One thing is clear though – local LLMs are used more and more. I expect this trend to continue and likely 2026 will end up being one of the most important years for the local AI movement. I admit that I didn't expect the agentic era to come so quickly to the local LLM space. One year ago, the available models were too computationally expensive for doing long-context tasks. There wasn't an obvious path towards meaningful agentic applications. The memory and compute requirements were huge. Last summer, with the release of gpt-oss, things started to change. It was the first time we saw a glimpse of tool calling that actually works well within the resource constraints of our daily devices. Later in the year, even better models were released and by now, useful local agentic workflows are a reality. Comparing local vs hosted capabilities at a given moment of time is pointless. To try put things into perspective: – We don't need frontier intelligence to automate searches and sending emails – We don't need trillion parameter models to be able to summarize articles or technical documents – We don't need massive GPU data centers to control our home appliances or turn the lights off in the garage I believe that there is a certain level of intelligence we as humans can comprehend and meaningfully utilize to improve our working process. Beyond that level, access to more intelligence becomes unnecessary at best and counterproductive at worst. I also believe that that level of useful artificial intelligence is completely within reach locally and it has always been just a matter of implementing the right software stack to bring it to the end user. With llama.cpp, I am confident that we continue to be on the right track of building that software stack! The llama.cpp project is going stronger than ever. With more than 1500 contributors, the project keeps growing steadily. From technical point of view, I think that llama.cpp + ggml is the only solution that actually makes sense. That is, the software stack must run efficiently on every possible device, hardware and operating system. The technology is too important to be vendor-locked. It has to be developed in the open, by the community, together with the independent hardware vendors. This is the only right way to build something that will truly make a difference in the long run. I won't try to convince you about what is currently and will be possible with local AI. We will just continue to build as usual. I am confident that after the smoke clears and we look objectively at what we have built together, the benefits will be obvious to everyone. Big shoutout to all llama.cpp maintainers. I feel extremely lucky to be able to work together with so many talented contributors. Every day I learn something new and I feel there is so much more cool stuff that we are going to build. Also, I am really thankful that the project continues to have reliable partners to support it! Cheers!
By
–
If you have uv installed you can start a conversation (after a 2GB model download) directly like this: uvx –with llm-mrchatterbox llm chat -m mrchatterbox
By
–
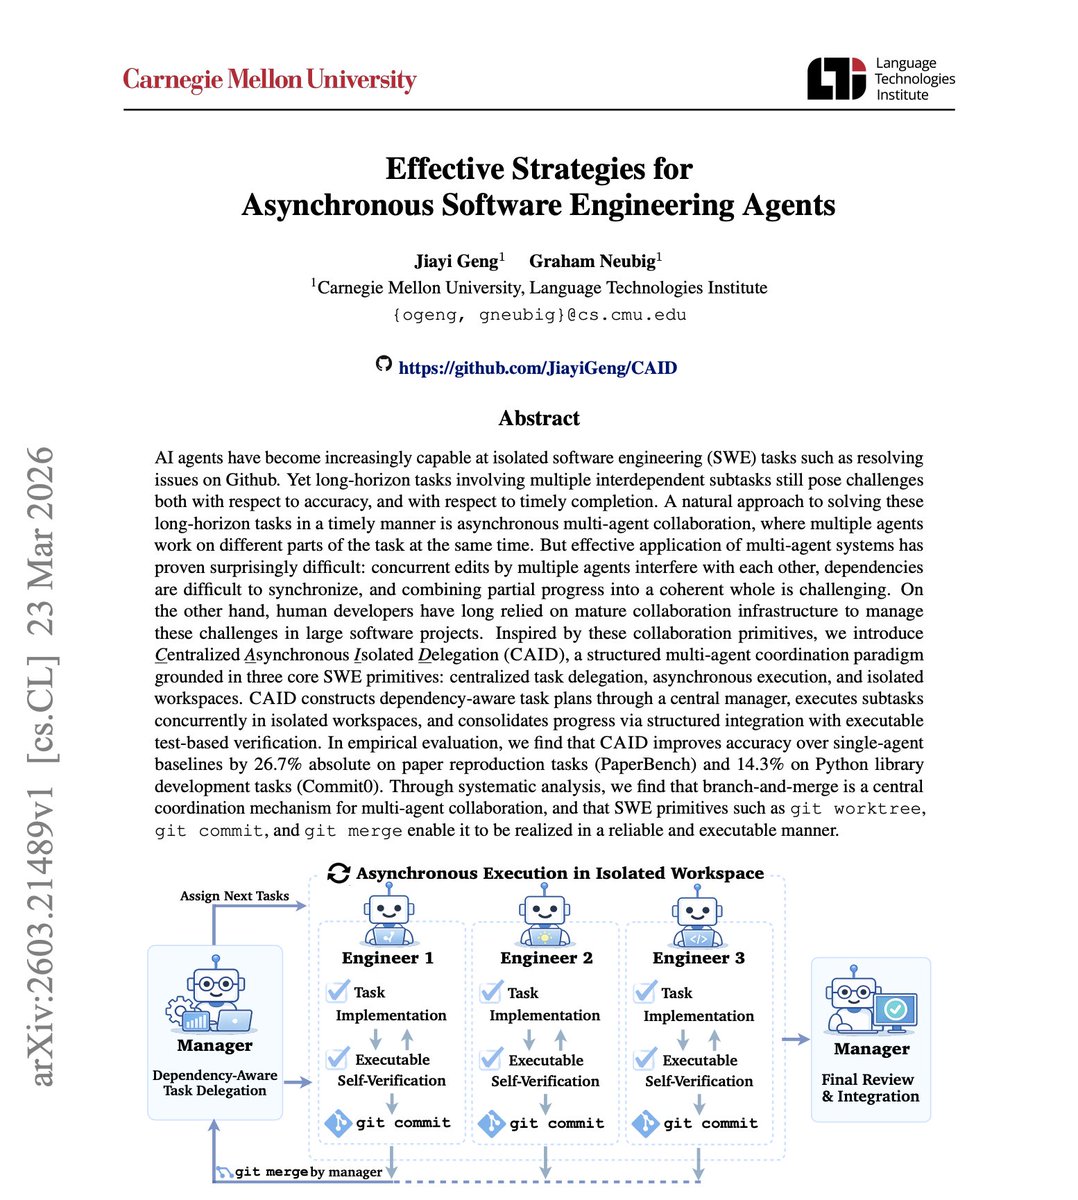
Effective strategies for asynchronous software engineering agents. elvis (@omarsar0) NEW research from CMU. (bookmark this one) The biggest unlock in coding agents is understanding strategies for how to run them asynchronously. Simply giving a single agent more iterations helps, but does not scale well. And multi-agent research shows that coordination > compute. A new paper from CMU proves this with a practical multi-agent system. CAID (Centralized Asynchronous Isolated Delegation) borrows proven human SWE practices: a manager builds a dependency graph, delegates tasks to engineer agents who work in isolated git worktrees, execute concurrently, self-verify with tests, and integrate via git merge. CAID improves accuracy over single-agent baselines by 26.7% absolute on paper reproduction tasks (PaperBench) and 14.3% on the Python library development tasks (Commit0). The key insight is that isolation plus explicit integration beats both single-agent scaling and naive multi-agent approaches. For long-horizon software engineering tasks, multi-agent coordination using git-native primitives should be the default strategy, not a fallback. Paper: arxiv.org/abs/2603.21489 Learn to build effective AI agents in our academy: academy.dair.ai/ — https://nitter.net/omarsar0/status/2038627572108743001#m