AI Agents is a waste of time. AI Agents = LLM + Data + Tools + Web Codex / Claude Code = the same thing (CLI Agents = good at reading files and coding). Just use that. Best agent = markdown file and scripts running through the file structure. That’s it.
CODE
-
LangChain adds specific reviewer assignment to annotation queues
By
–
we just added the ability to assign specific reviewers to an annotation queue. as building agents becomes more and more automated, human feedback being part of the loop will be as critical as ever. pic.twitter.com/UMYbJzKNan
— Sam Crowder (@samecrowder) 2 avril 2026we just added the ability to assign specific reviewers to an annotation queue. as building agents becomes more and more automated, human feedback being part of the loop will be as critical as ever.
→ View original post on X — @langchain, 2026-04-02 23:12 UTC
-
Knowledge Base System with Interactive Tools for Podcast Research
By
–
Same, I have a similar setup. A mix of Obsidian, Cursor (for md), and vibe-coded web terminals as front-end. Since I do a podcast, the number/diversity of research interests is very large. But the knowledge-base approach has been working great. For answers, I often have it generate dynamic html (with js) that allows me to sort/filter data and to tinker with visualizations interactively. Another useful thing is I have the system generate a temporary focused mini-knowledge-base for a particular topic that I then load into an LLM for voice-mode interaction on a long 7-10 mile run. So it becomes an interactive podcast while I run, where I ask it questions and listen to the answers to learn more. Anyway, heading out for a run now, thanks for the write-up 👊
→ View original post on X — @lexfridman, 2026-04-02 23:06 UTC
-
Codex pricing changes: free trial and usage-based options for teams
By
–
We've changed our pricing so it's now possible to try Codex at work without any up-front commitment. Codex (especially through the app!) has gotten *really* good. Happy building! Rohan Varma (@rohanvarma) We just made it frictionless for teams to try Codex! > New $0 Codex only seat for Codex access that is fully usage-based > Annual team seats are dropping from $25 to $20 per month For each Codex only seat you add to a new or existing workspace, we’ll credit your team $100, for your to $500! 💰 Free to get started and only pay for what you use 🤌🏾 openai.com/index/codex-flexi… — https://nitter.net/rohanvarma/status/2039818201060811126#m
-

Qwen3.6 Plus Vision-Language Model Now Available on Poe
By
–
Qwen3.6 Plus is now live on Poe. Delivers advanced vision‑language performance from Qwen, with clear gains in code‑heavy workflows like agentic and front‑end coding, plus stronger multimodal understanding including improved OCR and precise object localization. Designed for
-
Codex launches flexible pay-as-you-go pricing for teams
By
–
For business and enterprise, Codex now starts at $0 seats with pay-as-you-go. It's time to build. openai.com/index/codex-flexi…
→ View original post on X — @romainhuet, 2026-04-02 22:20 UTC
-
Chunking Strategy for Effective AI Document Processing
By
–
Use epub not PDF, convert epub to txt/md, summarize the wikipedia article into "book context", with it in context summarize one chapter at a time, etc. I mean basically imo for good results you have to "work it" in chunks and shouldn't expect that just attaching a pdf and asking
-

Gemma 4 MLX Support: 125 Quantized Models Released for Mac Developers
By
–
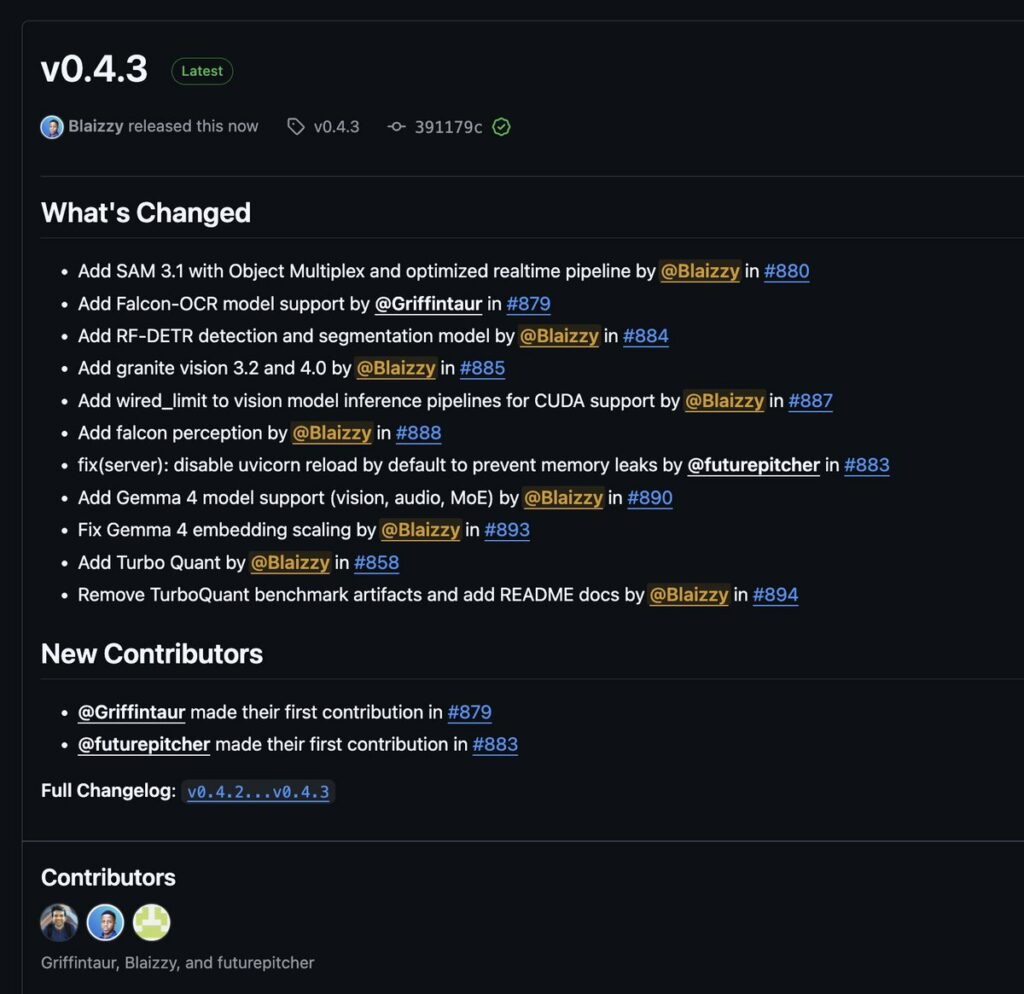
This guy is BEYOND CRACKED. Gemma 4 already on MLX, bro has uploaded all models with quantization. 125 models uploaded in last few hours 🤯 New mlx-vlm repo also supports turbo-quant, and rf-detr too (among other things) If you are a mac dev, you better be jumping at this. Bookmark him, turn his notifications on, sponsor his work. Prince Canuma (@Prince_Canuma) mlx-vlm v0.4.3 is here 🚀 Day-0 support: 🔥 Gemma 4 (vision, audio, MoE) by @GoogleDeepMind 🦅 Falcon-OCR + Falcon Perception by @TIIuae 🪨 Granite Vision 4.0 by @IBMResearch New models: 🎯 SAM 3.1 with Object Multiplex by @facebook 🔍 RF-DETR detection & segmentation by @roboflow Infra: ⚡ TurboQuant (KV cache compression) 🖥️ CUDA support for vision models (Sam and RF-DETR) Get started today: > uv pip install -U mlx-vlm Leave us a star ⭐️ github.com/Blaizzy/mlx-vlm — https://nitter.net/Prince_Canuma/status/2039815307821199709#m
→ View original post on X — @huggingface, 2026-04-02 21:44 UTC
-
MCP Server Development for AI Infrastructure
By
–
Yeah, @blevlabs already had it build one MCP server for it. Don't know when I'll be able to get to this. But it is an interesting idea! On the list.
-
AI Systems Speaking MCP Protocol With Easy Training
By
–
My AI speaks MCP. And is easily trained. Just a little talking it through what we want.