The best way to ensure good code is to have a good organization. This paper from Microsoft looking at 50M lines of code found that organizational factors were far more powerful in explaining the number of bugs than any technical aspect of the project. https://
microsoft.com/en-us/research
/wp-content/uploads/2016/02/tr-2008-11.pdf
…
CODE
-
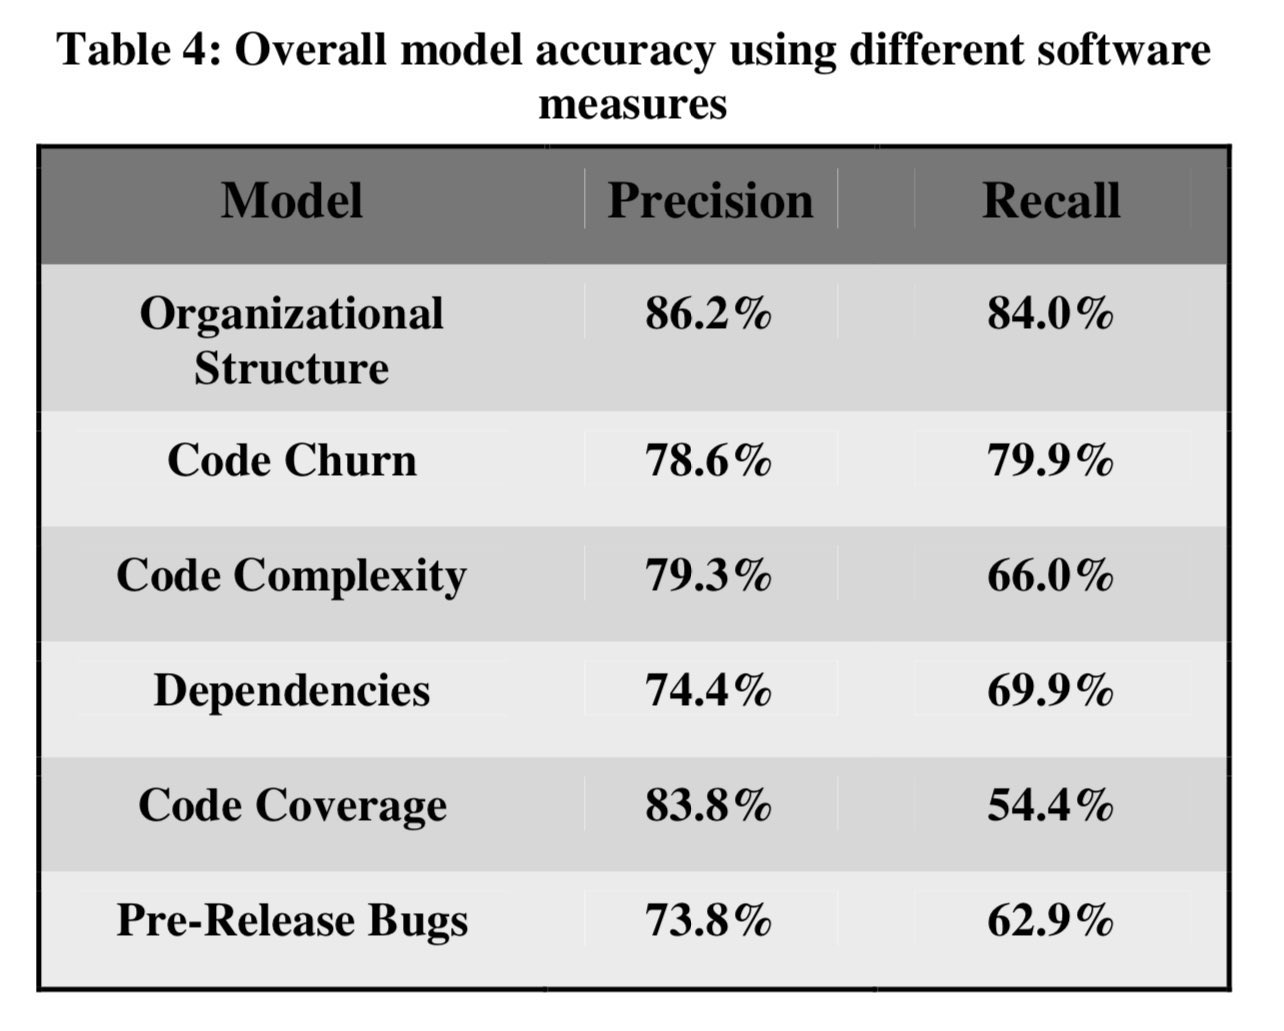
Organizational factors matter more than technical aspects for code quality
By
–
-
GitHub Data Backup: Protecting Your Code and Issues
By
–
In fact, increasingly I have data I care about stored on GitHub – in repos or in issue threads I keep meaning to setup backups for that, in case my GitHub account ever becomes unavailable for some reason
-
Keras Preprocessing Layers: Seeking Company Collaboration for Large-Scale adapt()
By
–
If you're a company that uses Keras and you face this use case (large scale adapt() of Keras preprocessing layers), would you consider working with us to implement it? We're a small team and we don't have the resources for this at this time…
-
Beam-style computation support designed but not yet implemented
By
–
Correct, the underlying API / infra is designed to potentially allow Beam-style computation. We have not implemented it and it's currently deprioritized (the current adapt() is serial and single-threaded). But we could if there's demand in the future — the design is there.
-
TensorFlow Graph Performance Eliminates Python Slowness Issues
By
–
The fact that we're able to do everything as part of the TF graph is really nice — Python slowness is never an issue. There's no need for us to rewrite anything in, like, Cython or Rust.
-
Keras Preprocessing Layers: High-Performance In-Graph Implementation
By
–
All the work is done in Keras preprocessing layers, which are implemented in TF ops (everything is 100% in-graph!) so it's highly performant. During training (presumably on GPU/TPU) you'd use async preprocessing in TF data to avoid CPU preprocessing being a bottleneck.
-

Learn the Architecture of a Data Pipeline
By
–
Learn the Architecture of a Data Pipeline: This article was published as a part of the Data Science Blogathon. Introduction Controlling the flow of information from a source to a destination system, such as a data warehouse, is an integral part of any… https://
analyticsvidhya.com/blog/2022/10/l
earn-the-architecture-of-a-data-pipeline/?utm_source=dlvr.it&utm_medium=twitter
… -

Building Machine Learning Systems: Complete Components Overview
By
–
Building machine learning systems is hard. Some of the components you need: 1. Data sources
2. Data pipelines
3. Feature stores
4. Model training
5. Model evaluation
6. Model deployment
7. Model monitoring
8. Predictions API At @abacusai we help you with this! -
LangChain 0.0.12 Release with AI21Labs and Manifest Integrations
By
–
LangChain version 0.0.12 Two super exciting integrations! @AI21Labs integration (from a friend of @YuvalinTheDeep
) Integration with @HazyResearch
's manifest library (with help from @laurel_orr1
) -
ML in Production: Beyond Notebooks to Deployment Challenges
By
–
Machine learning is hard, there's no doubt about that But Machine learning in production is much harder than ML in notebooks. Developing the ML pipeline to deployment and then maintaining consistent quality prediction building a retraining pipeline becomes more complicated…