This ̶c̶o̶u̶l̶d̶ will be a Visual Studio Code plugin
CODE
-
OpenAI Cookbook: Essential Resource for AI Development
By
–
OpenAI Cookbook Link: https://
github.com/openai/openai-
cookbook
… -

OpenAI Cookbook: New Ways to Use the OpenAI API
By
–
ChatGPT may be all the rage, but have you checked out this OpenAI Cookbook? Discover new ways to use the OpenAI API with example code and prompts. Now building innovative AI products is for everyone!
-
Clip of Andrej’s hand-coded GPT model trained on Shakespeare
By
–
Clip of Andrej's hand-coded GPT model in action, trained on a corpus of Shakespeare text: pic.twitter.com/TpZPHjz3dS
— Riley Goodside (@goodside) 17 janvier 2023Clip of Andrej's hand-coded GPT model in action, trained on a corpus of Shakespeare text:
-

Karpathy’s video: building GPT, a Transformer tutorial from scratch
By
–
Great new video from @karpathy
: "Let's build GPT", a tutorial on coding a Transformer model from scratch: -
MIT OpenCourseWare: Free CS, AI and Algorithms Courses
By
–
Free MIT videos & online materials from more than 2,400 courses, including intro classes in computer science, AI and algorithms. Browse our open CS courses here: https://
bit.ly/39jH8DV (v/
@MITOCW
) -
Training a 10M Parameter GPT Model on Shakespeare in 15 Minutes
By
–
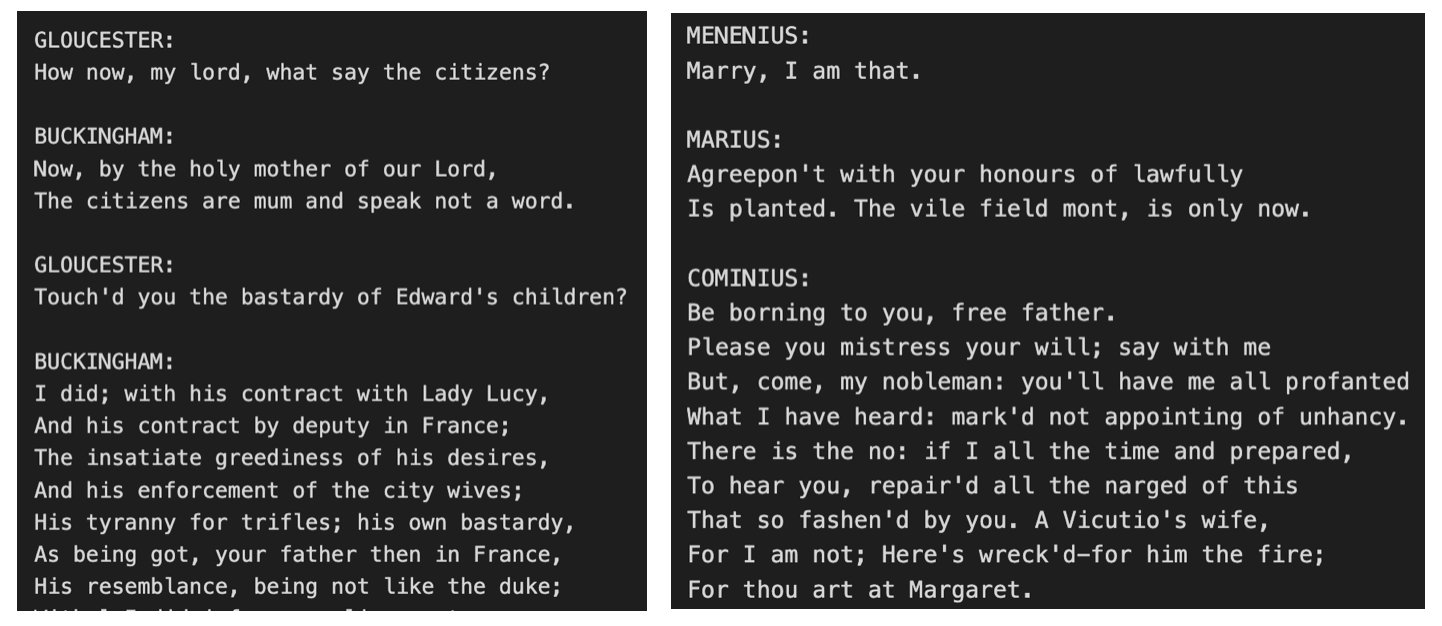
We get a ~10M parameter model trained for about 15 minutes on 1 GPU on all of Shakespeare concatenated into one 1MB file. We then sample infinite fake Shakespeare from our baby GPT. Can you spot which one is real? At only 10M params on 1M characters, from-scratch, I hope so 🙂
-

Building Transformers: Self-Attention, Training, and GPT-3 Comparison
By
–
The second ~1hr builds up the Transformer: multi-headed self-attention, MLP, residual connections, layernorms. Then we train one and compare it to OpenAI's GPT-3 (spoiler: ours is around ~10K – 1M times smaller but the ~same neural net) and ChatGPT (i.e. ours is pretraining only)
-
Transformer Attention Mechanism: Baseline Model and Message Passing Introduction
By
–
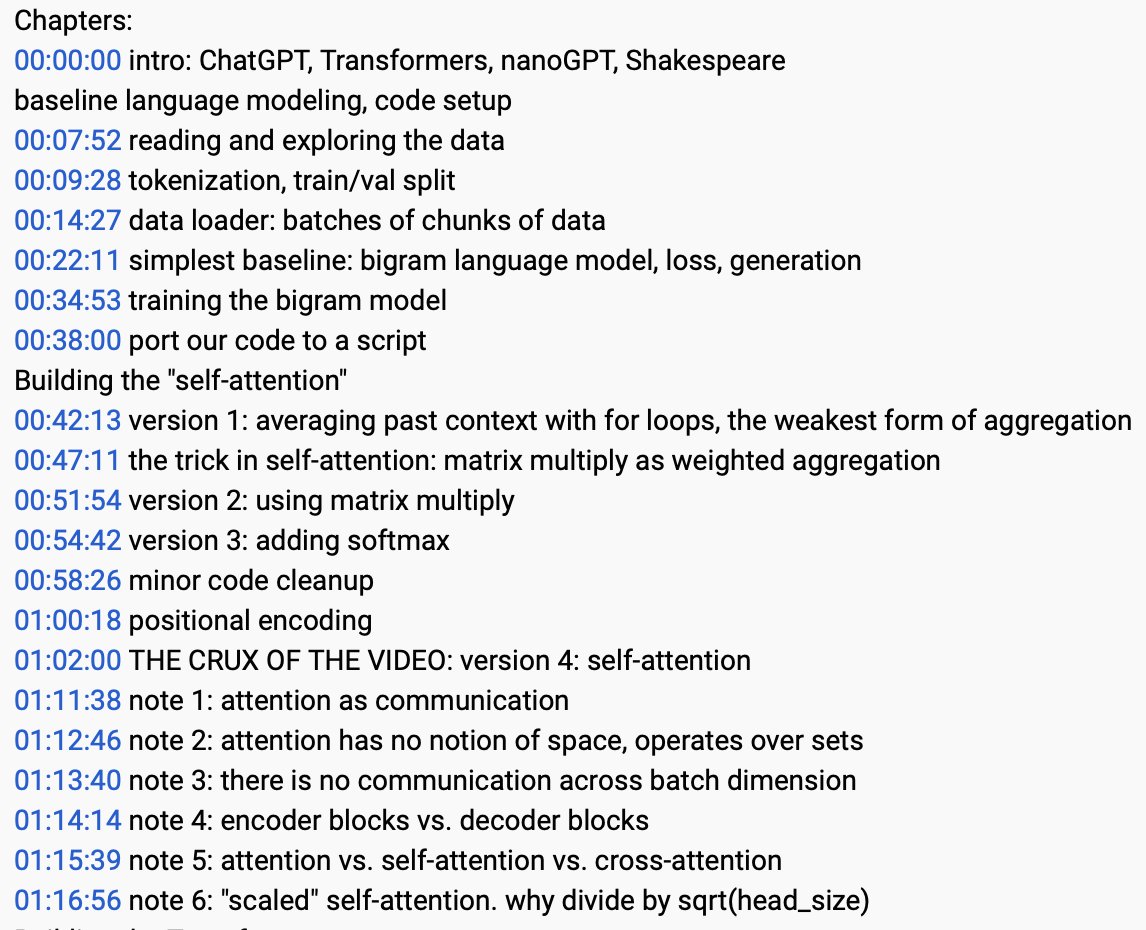
First ~1 hour is 1) establishing a baseline (bigram) language model, and 2) introducing the core "attention" mechanism at the heart of the Transformer as a kind of communication / message passing between nodes in a directed graph.