
OpenAI announces the update of the GPT-5.5-Cyber model (new), which achieves a 85.6% score on the CyberGym benchmark compared to 81.9% in its initial version. Codex also obtained a new security plugin.
CODE
-
Claude Code Search critique: poor for older code retrieval
By
–
claude code search is not very good – esp for anything older than a few weeks
-
GLM 5.2: first open-weights model for auto-research
By
–
GLM 5.2 keeps on winning
— Chubby♨️ (@kimmonismus) 22 juin 2026
GLM 5.2 is emerging as the first open-weights model capable of handling meaningful autoresearch tasks, from debugging setup issues to running and comparing RL training experiments across multi-node H100 clusters.
The big caveat: it lacks image… https://t.co/BQf3g6pW5OGLM 5.2 emerges as the first open-weights model capable of handling significant auto-research tasks, from debugging configuration issues to running and comparing RL training experiments on clusters.
-
8x code output makes verification the top problem
By
–
My biggest takeaways from Claude Code/Cowork lead @Nerdi_Yogi
: 1. When your engineers ship 8x more code than a year ago (like they do at Anthropic), the biggest problem becomes verification. How do you know that the experience you shipped is what you intended? One tactic Fiona’s -
Codex Security Plugin for Security Teams (12 words max)
By
–
Codex Security plugin for security teams: deep scans, validating findings, tracing attack paths, building threat models, generating codebase-specific patches for review, and exporting into other tools.
-
Runtime swap: same UI, different inference backend
By
–
This is similar to a runtime swap: same UI, different inference backend
-
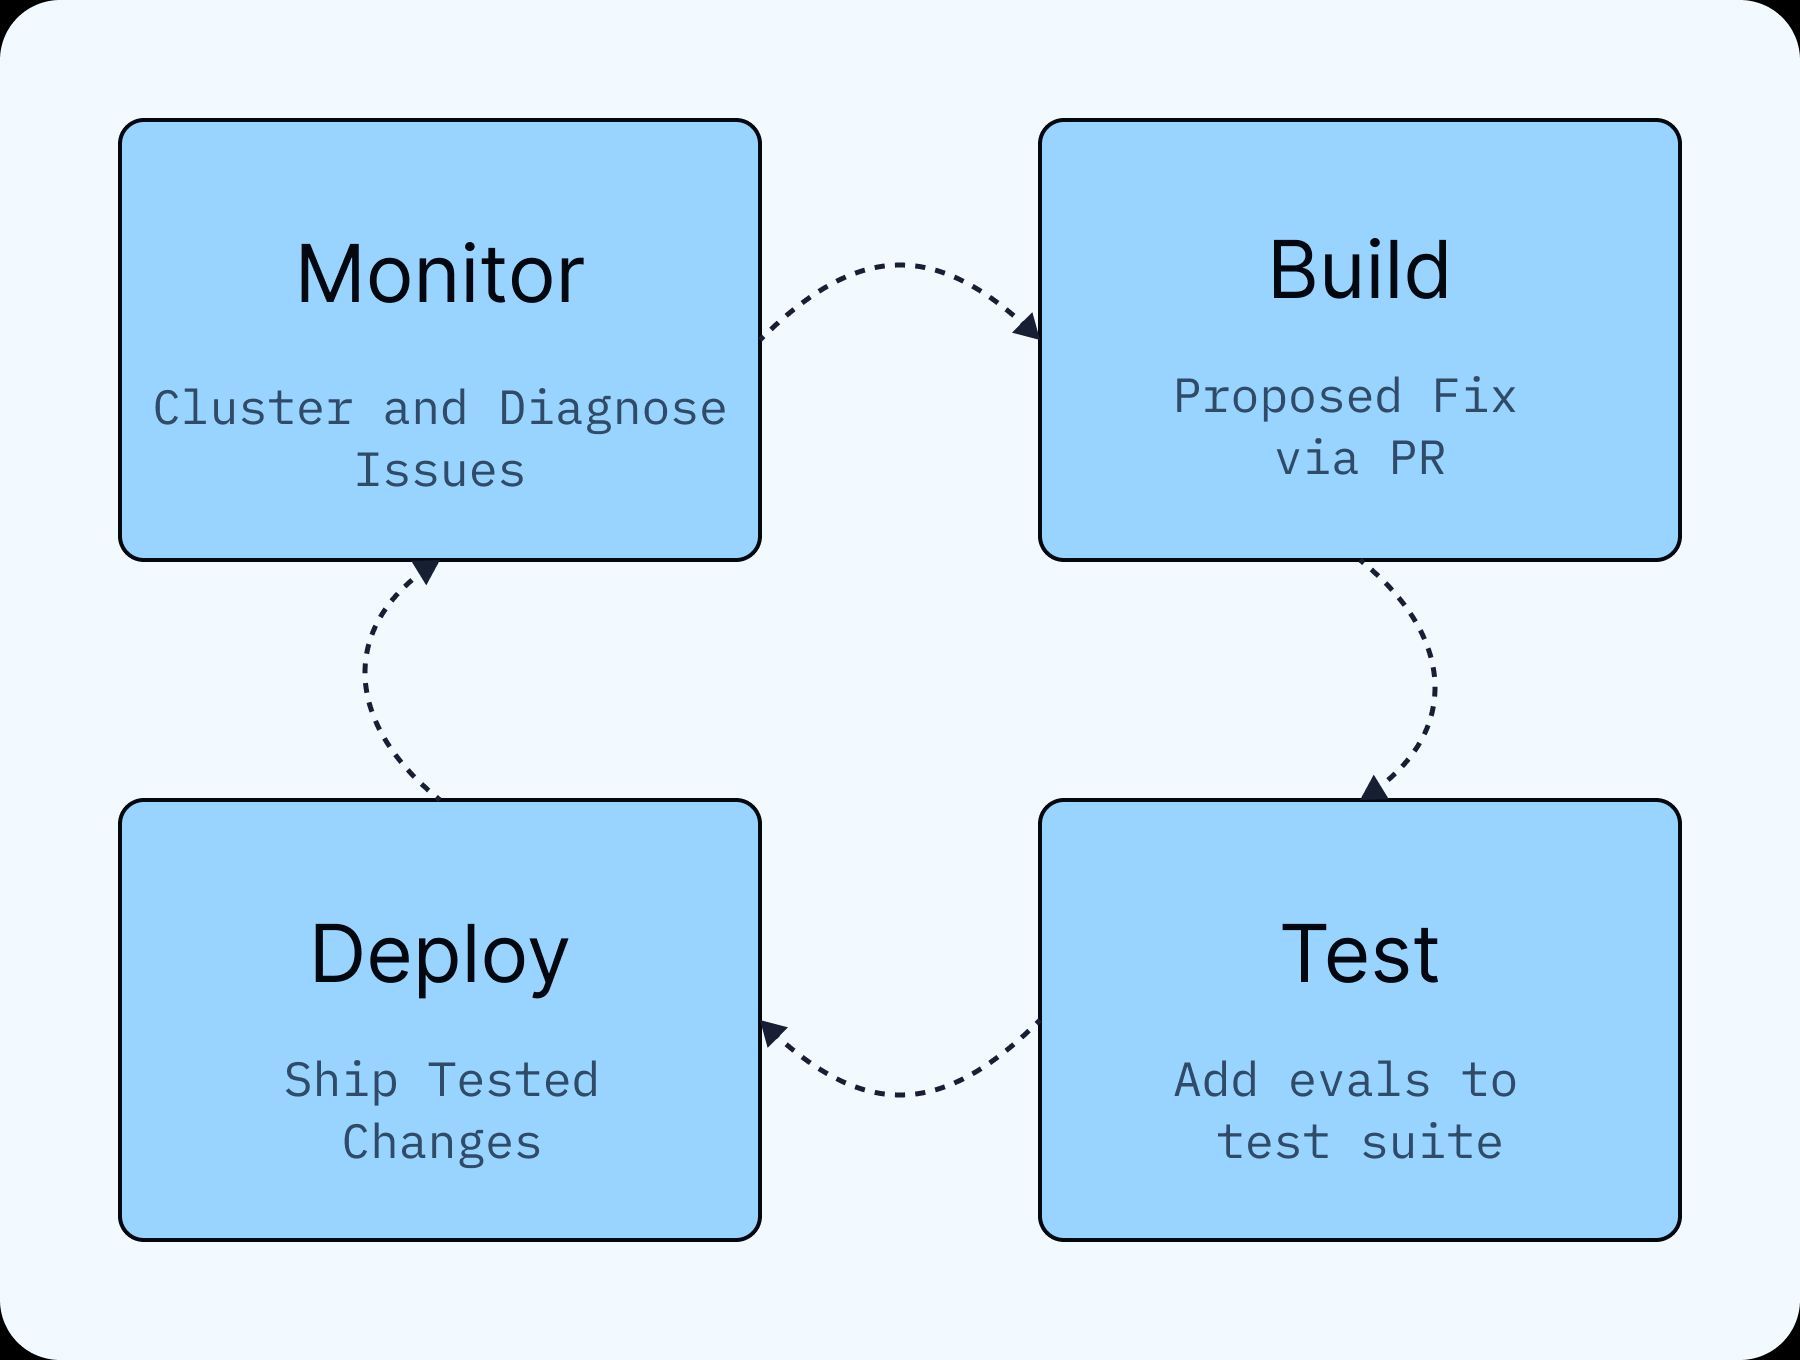
Fixed bugs improve your evaluation suite with LangSmith
By
–
Every problem that LangSmith Engine solves makes your evaluation suite more robust.
Fix a bug → get a custom online evaluator + a new offline dataset example.
Over time, your test harness becomes smarter about -
NVIDIA Research ArtiFixer completes missing 3D scene geometry
By
–
3D scene reconstruction works great until the camera never sees part of the scene.
— NVIDIA AI (@NVIDIAAI) 22 juin 2026
ArtiFixer from NVIDIA Research is an open autoregressive model that fills in the missing geometry that other methods leave blank.#SIGGRAPH2026 paper, code + demo: https://t.co/D9PX2OzbZf pic.twitter.com/AGQicvVKkW3D scene reconstruction works great until the camera never sees part of the scene. ArtiFixer from NVIDIA Research is an open autoregressive model that fills in the missing geometry that other methods leave blank. #SIGGRAPH2026 paper, code + demo: https://
nvda.ws/4oILqNd -
Sakana Fugu Ultra-high slow, results fine but not matching Fable
By
–
I have been trying Sakana Fugu Ultra-high and, first, it is incredibly slow: my typical coding tests (shaders, interactive scenes) take 30 minutes to run
— Ethan Mollick (@emollick) 22 juin 2026
And the results are… fine. It does not match Fable in real use.
Its harbor is a good example: https://t.co/xVqulPBsQf https://t.co/KJRLIlSJfXI have been trying Sakana Fugu Ultra-high and, first, it is incredibly slow: my typical coding tests (shaders, interactive scenes) take 30 minutes to run And the results are… fine. It does not match Fable in real use. Its harbor is a good example: https://
ai-harbor-town-gallery.netlify.app/#sakura-ultra-
high
… -
OpenAI Daybreak models discover and patch critical vulnerabilities
By
–
We're accelerating patching, in addition to vuln finding, with new tools and models in OpenAI Daybreak. Our models are now discovering and generating patches for critical vulns in major browsers, network infrastructure, and operating systems (such as FreeBSD and the Linux