`st.logo` is now available with @Streamlit's 1.35 release! 🎉 https://t.co/wU4vxTRB2w
— Charly Wargnier (@DataChaz) 31 mai 2024
`st.logo` is now available with @Streamlit
's 1.35 release!
By
–
`st.logo` is now available with @Streamlit's 1.35 release! 🎉 https://t.co/wU4vxTRB2w
— Charly Wargnier (@DataChaz) 31 mai 2024
`st.logo` is now available with @Streamlit
's 1.35 release!
By
–
What we learned from a year of building with LLMs. A great read for anyone interested in building things with large language models. → https://
oreilly.com/radar/what-we-
learned-from-a-year-of-building-with-llms-part-i/
… https://
oreilly.com/radar/what-we-
learned-from-a-year-of-building-with-llms-part-i/
…
By
–
Prompt codestral to make those changes in the code and it should be able to that.
By
–
It generates the python code to create a full-fledged application just from a single prompt.
By
–
took a while to groq but great clear explanation here! an analogy could be that this is @voooooogel style rep eng applied to rag retrieval queries instead of inference outputs? adapters for everything. you could maybe even do adapters for multimodal data! as chameleon style
By
–
Find all the awesome LLM Apps demo with RAG in the following Github Repo. P.S: Don't forget to star the repo to show your support
By
–
Build a LLM app with RAG to Chat with PDF using Mistral AI's Codestral in less than 5 minutes.
— Shubham Saboo (@Saboo_Shubham_) 31 mai 2024
Go from a simple english prompt to fully working Python application. pic.twitter.com/5BiAY4vVEd
Build a LLM app with RAG to Chat with PDF using Mistral AI's Codestral in less than 5 minutes. Go from a simple english prompt to fully working Python application.
By
–
Most people don't understand that attention is a pooling operator. A much better (more FLOPs) and less hard-coded and peaky compared to "max" operator in the traditional max pooling, because of soft-attention with learned matmuls and dot products. However, attention and pooling
By
–
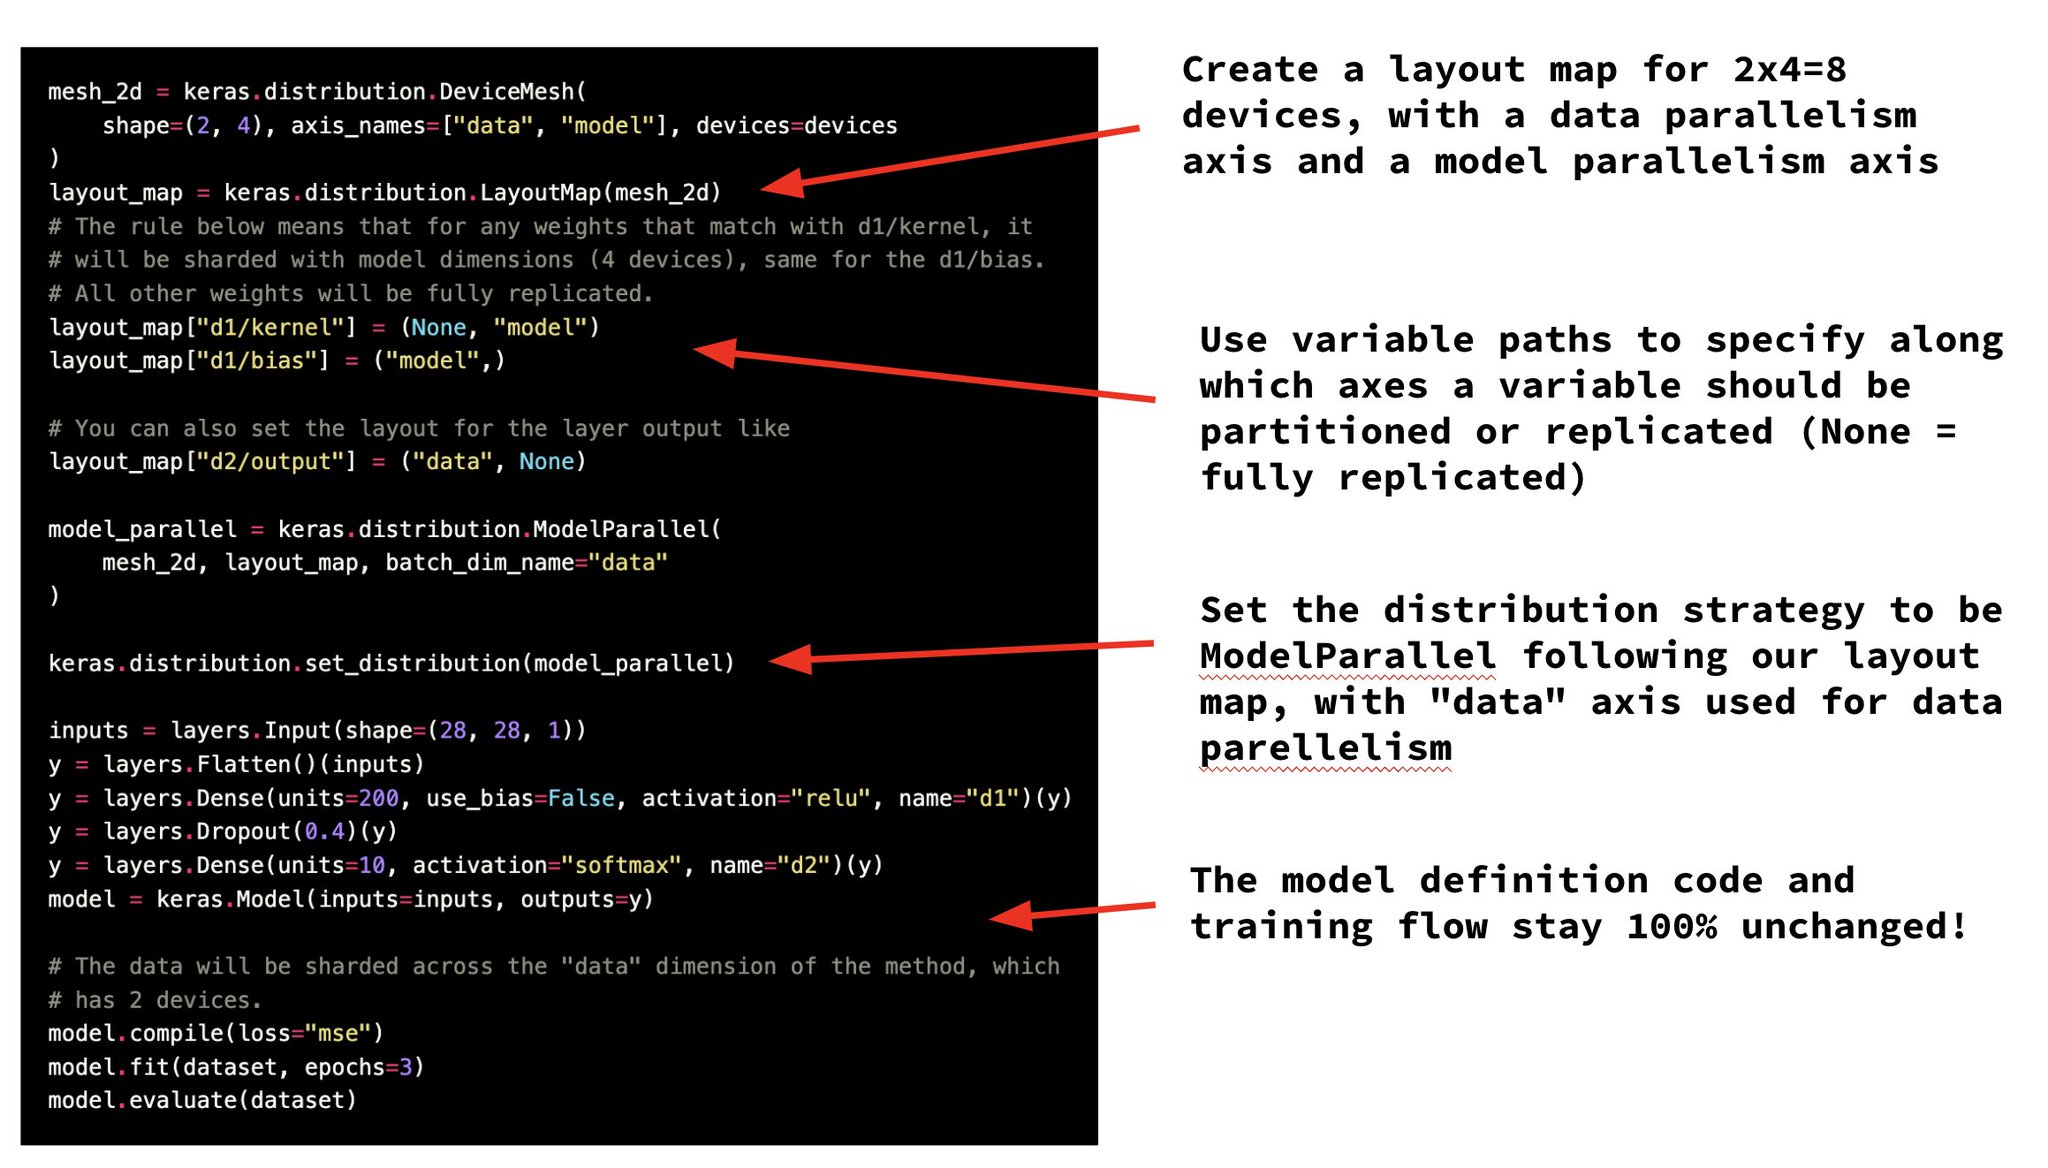
Every other model parallelism API I've seen has partitioning annotations in-lined in the model code and uses custom training logic — making it challenging to modify and maintain the partitioning config. Keras 3 dramatically simplifies this.
By
–
Keras 3 + JAX makes it possible to efficiently distribute large models via both data parallelism and model parallelism (variable partitioning) across arbitrarily many devices. It doesn't require modifying your model code or your training code at all — all you need is to