
2/ One of the standout changes in the o1 model is its enhanced contextual understanding. Unlike GPT-4, which excelled in text generation, o1 pushes the envelope by refining how it processes text. This opens up new possibilities in areas like coding, research, and business
CODE
-
Revisiting Cloud and Open Source Debate in AI
By
–
I think we need to go back to arguing about cloud and open source.
-
Agent Internal State and Game State Architecture Design
By
–
Pretty specific on the game imo. Each player (agent) should have its own internal state, and then the game should be the state of the overall agent
-
Replicate simplifies API management and saves development time
By
–
Replicate makes my life so much easier for API management, security, and efficiency that I don't think I'll replace it. It would take me about 5 days of development to set up my serverless and API management, and I don't want to invest that time just to "earn more" :).
-
APL Tensor Transposition: Why PyTorch Doesn’t Discuss Order 3+
By
–
APL folks *love* talking about order 3+ tensor transposition! 😀 I don't see it come up much in the PyTorch world though…
-
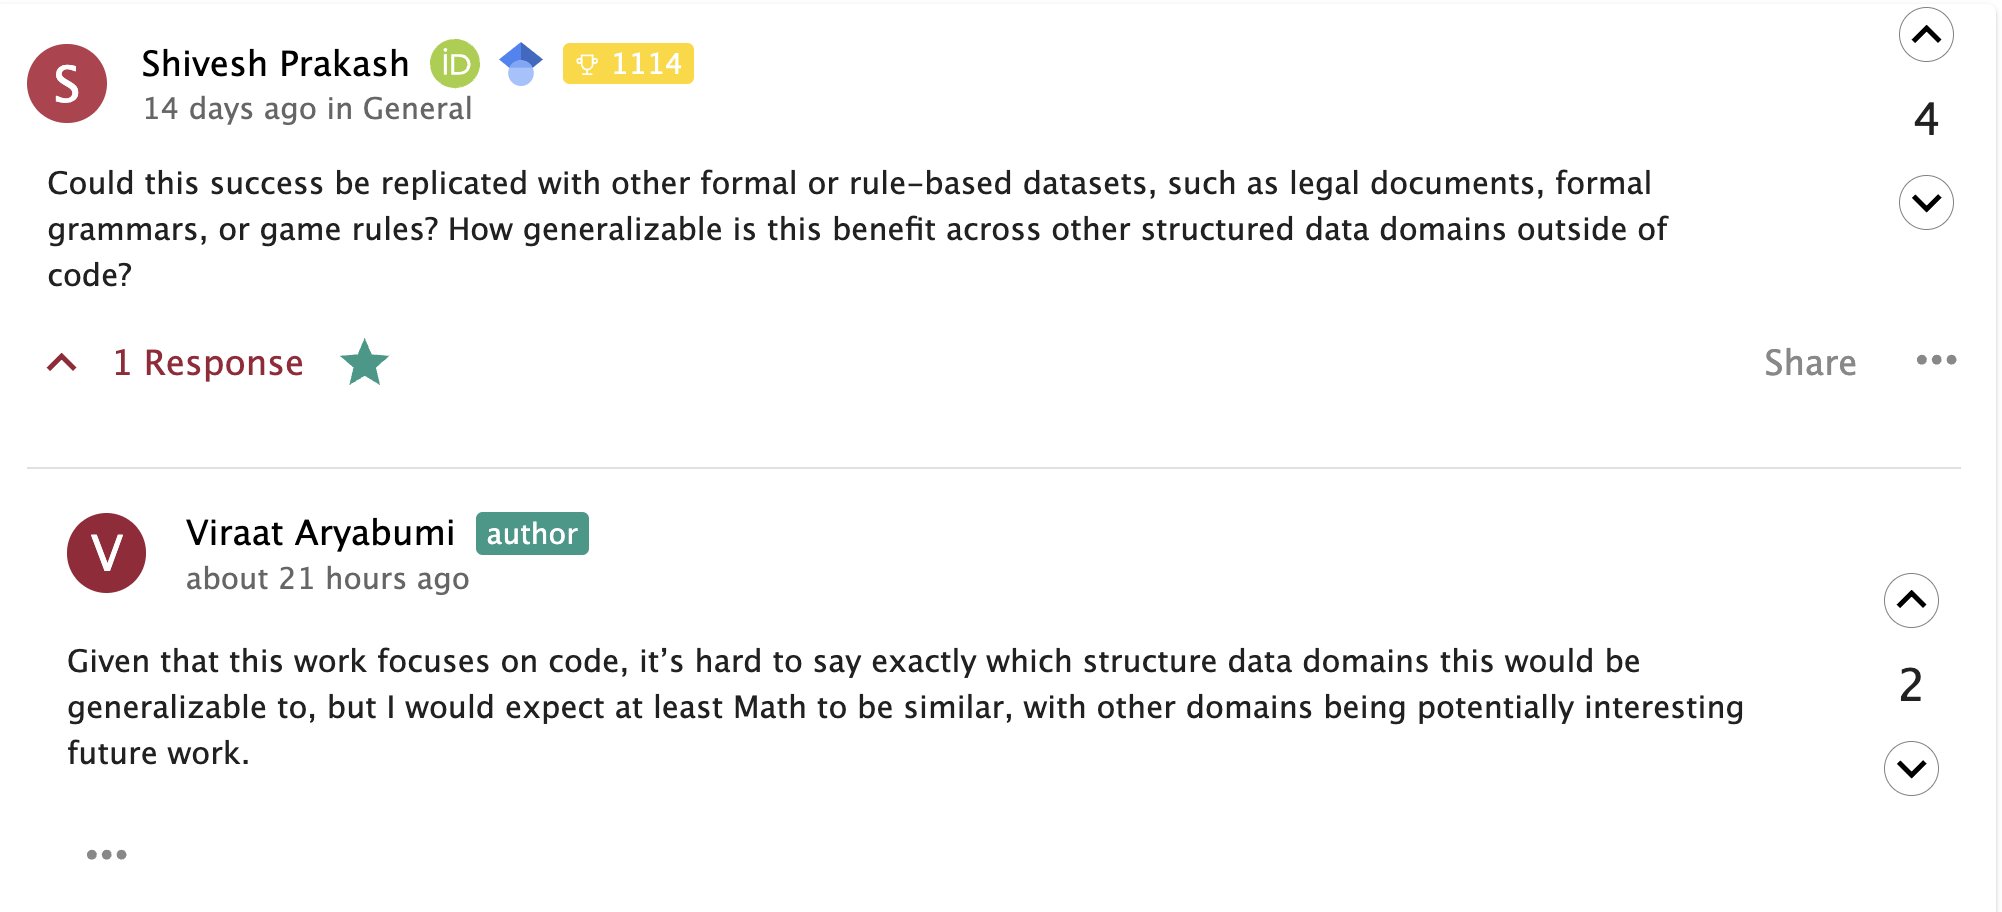
Formal domains data integration in LLM pretraining
By
–
5) Are there are other formal or rule-based domains where including its data in LLM pretraining can help?
-
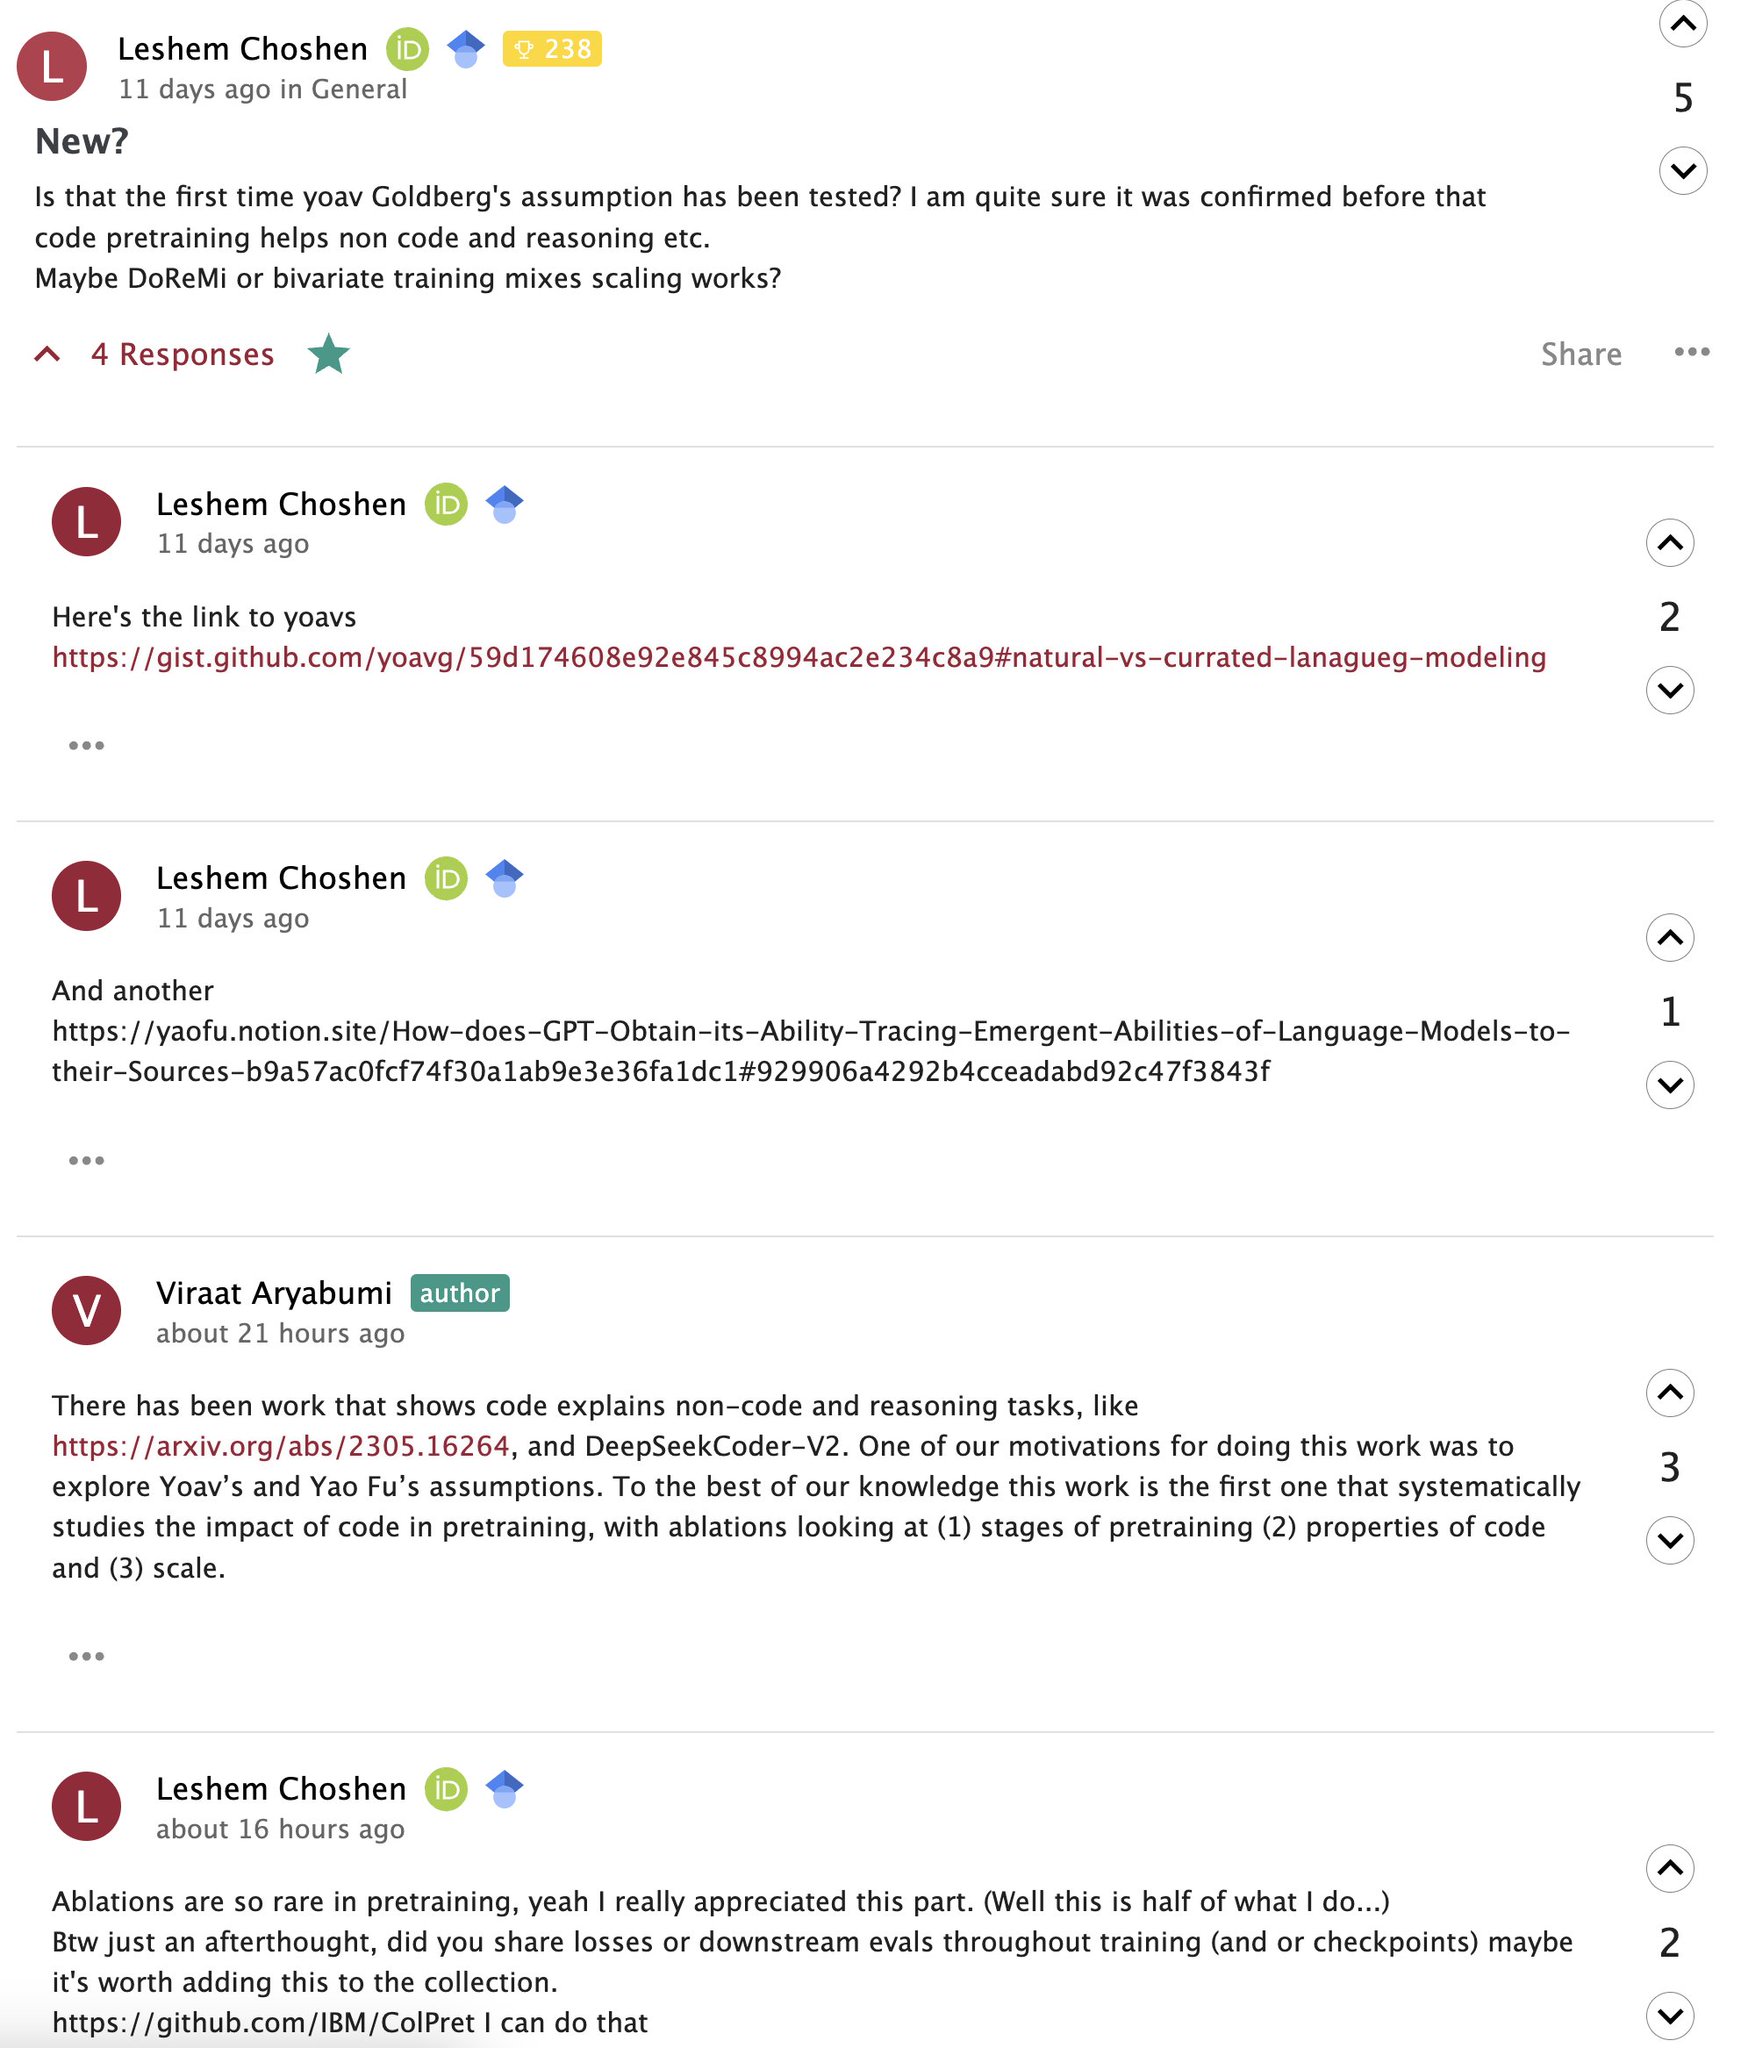
Code Impact in Pretraining: Systematic Study and Analysis
By
–
4) The first work that systematically studies the impact of code in pretraining, inspired by Yoav Goldberg and Yao Fu’s assumptions
-
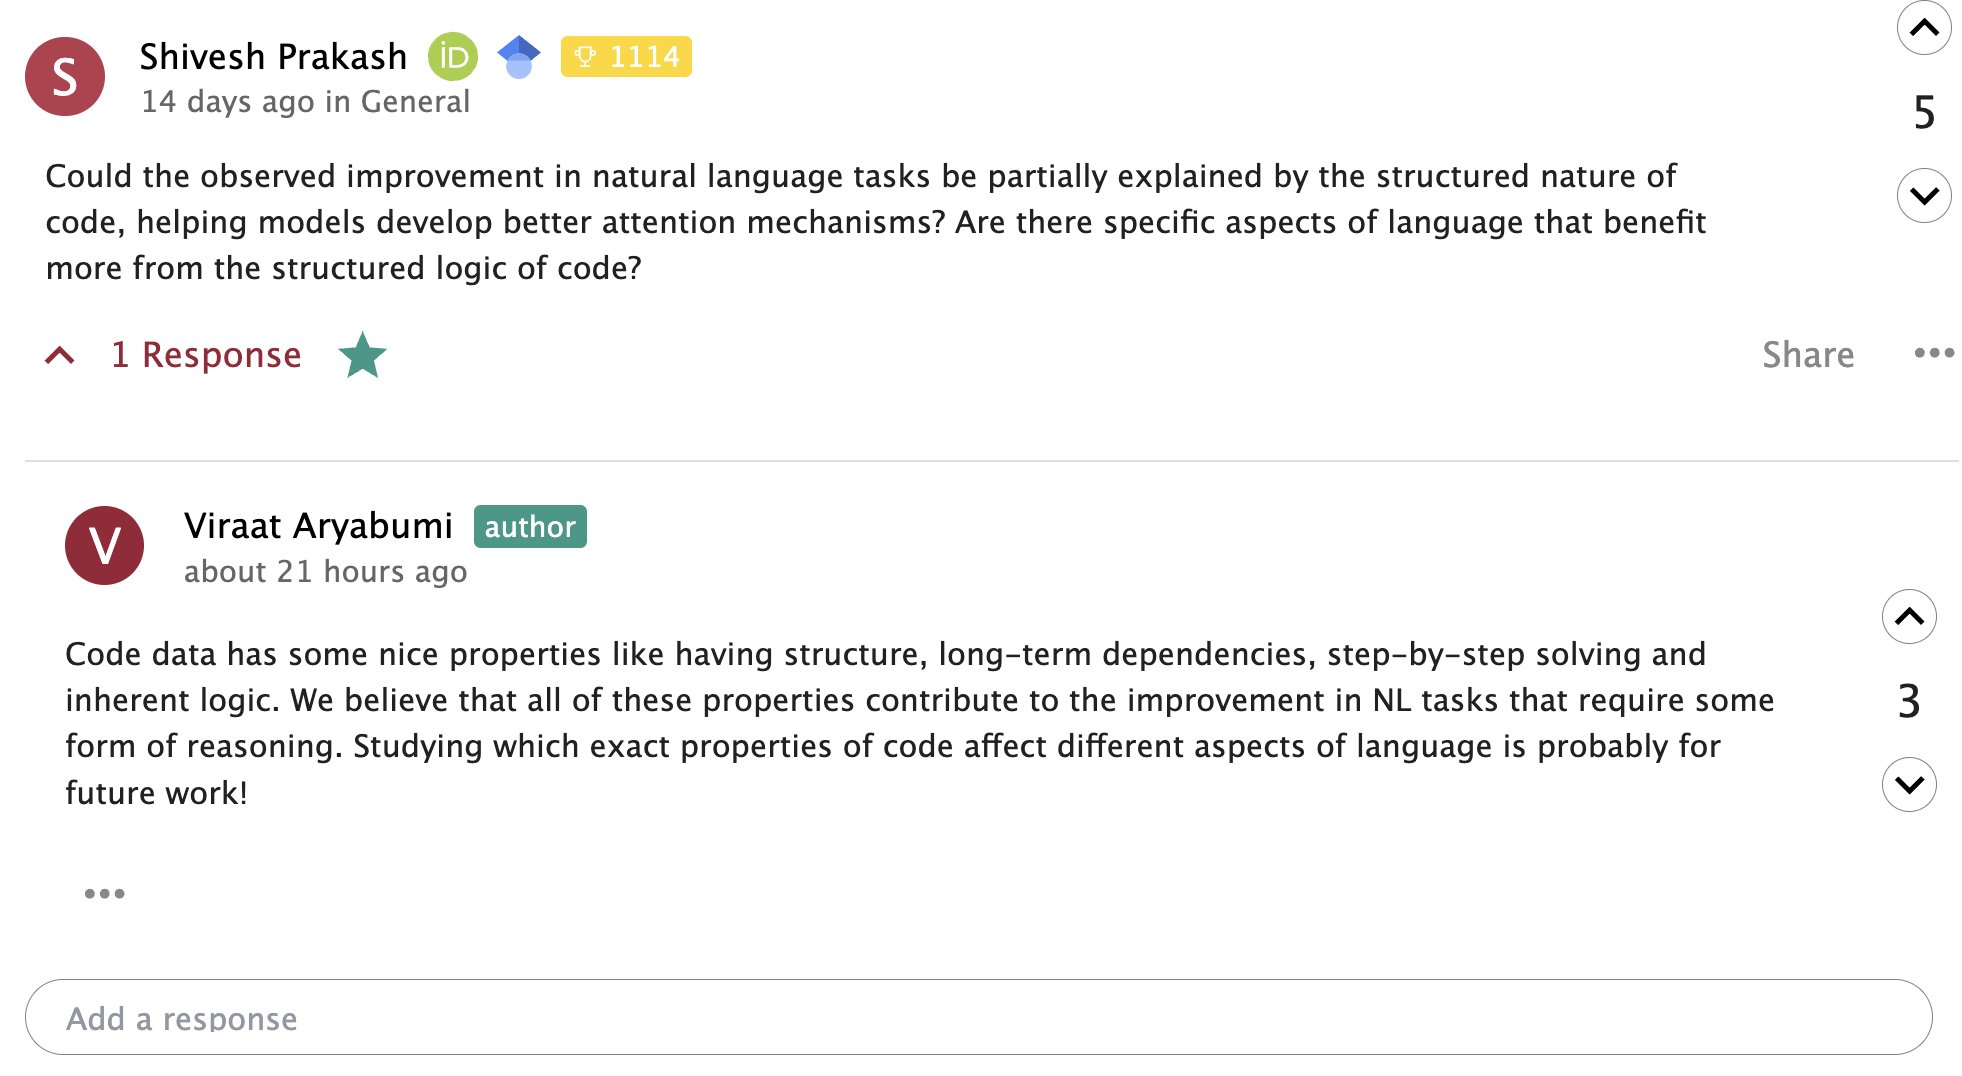
Code Properties Enhancing Natural Language Task Performance
By
–
3) What are the main properties of code that contribute to the improvement in performance on natural language tasks?
-
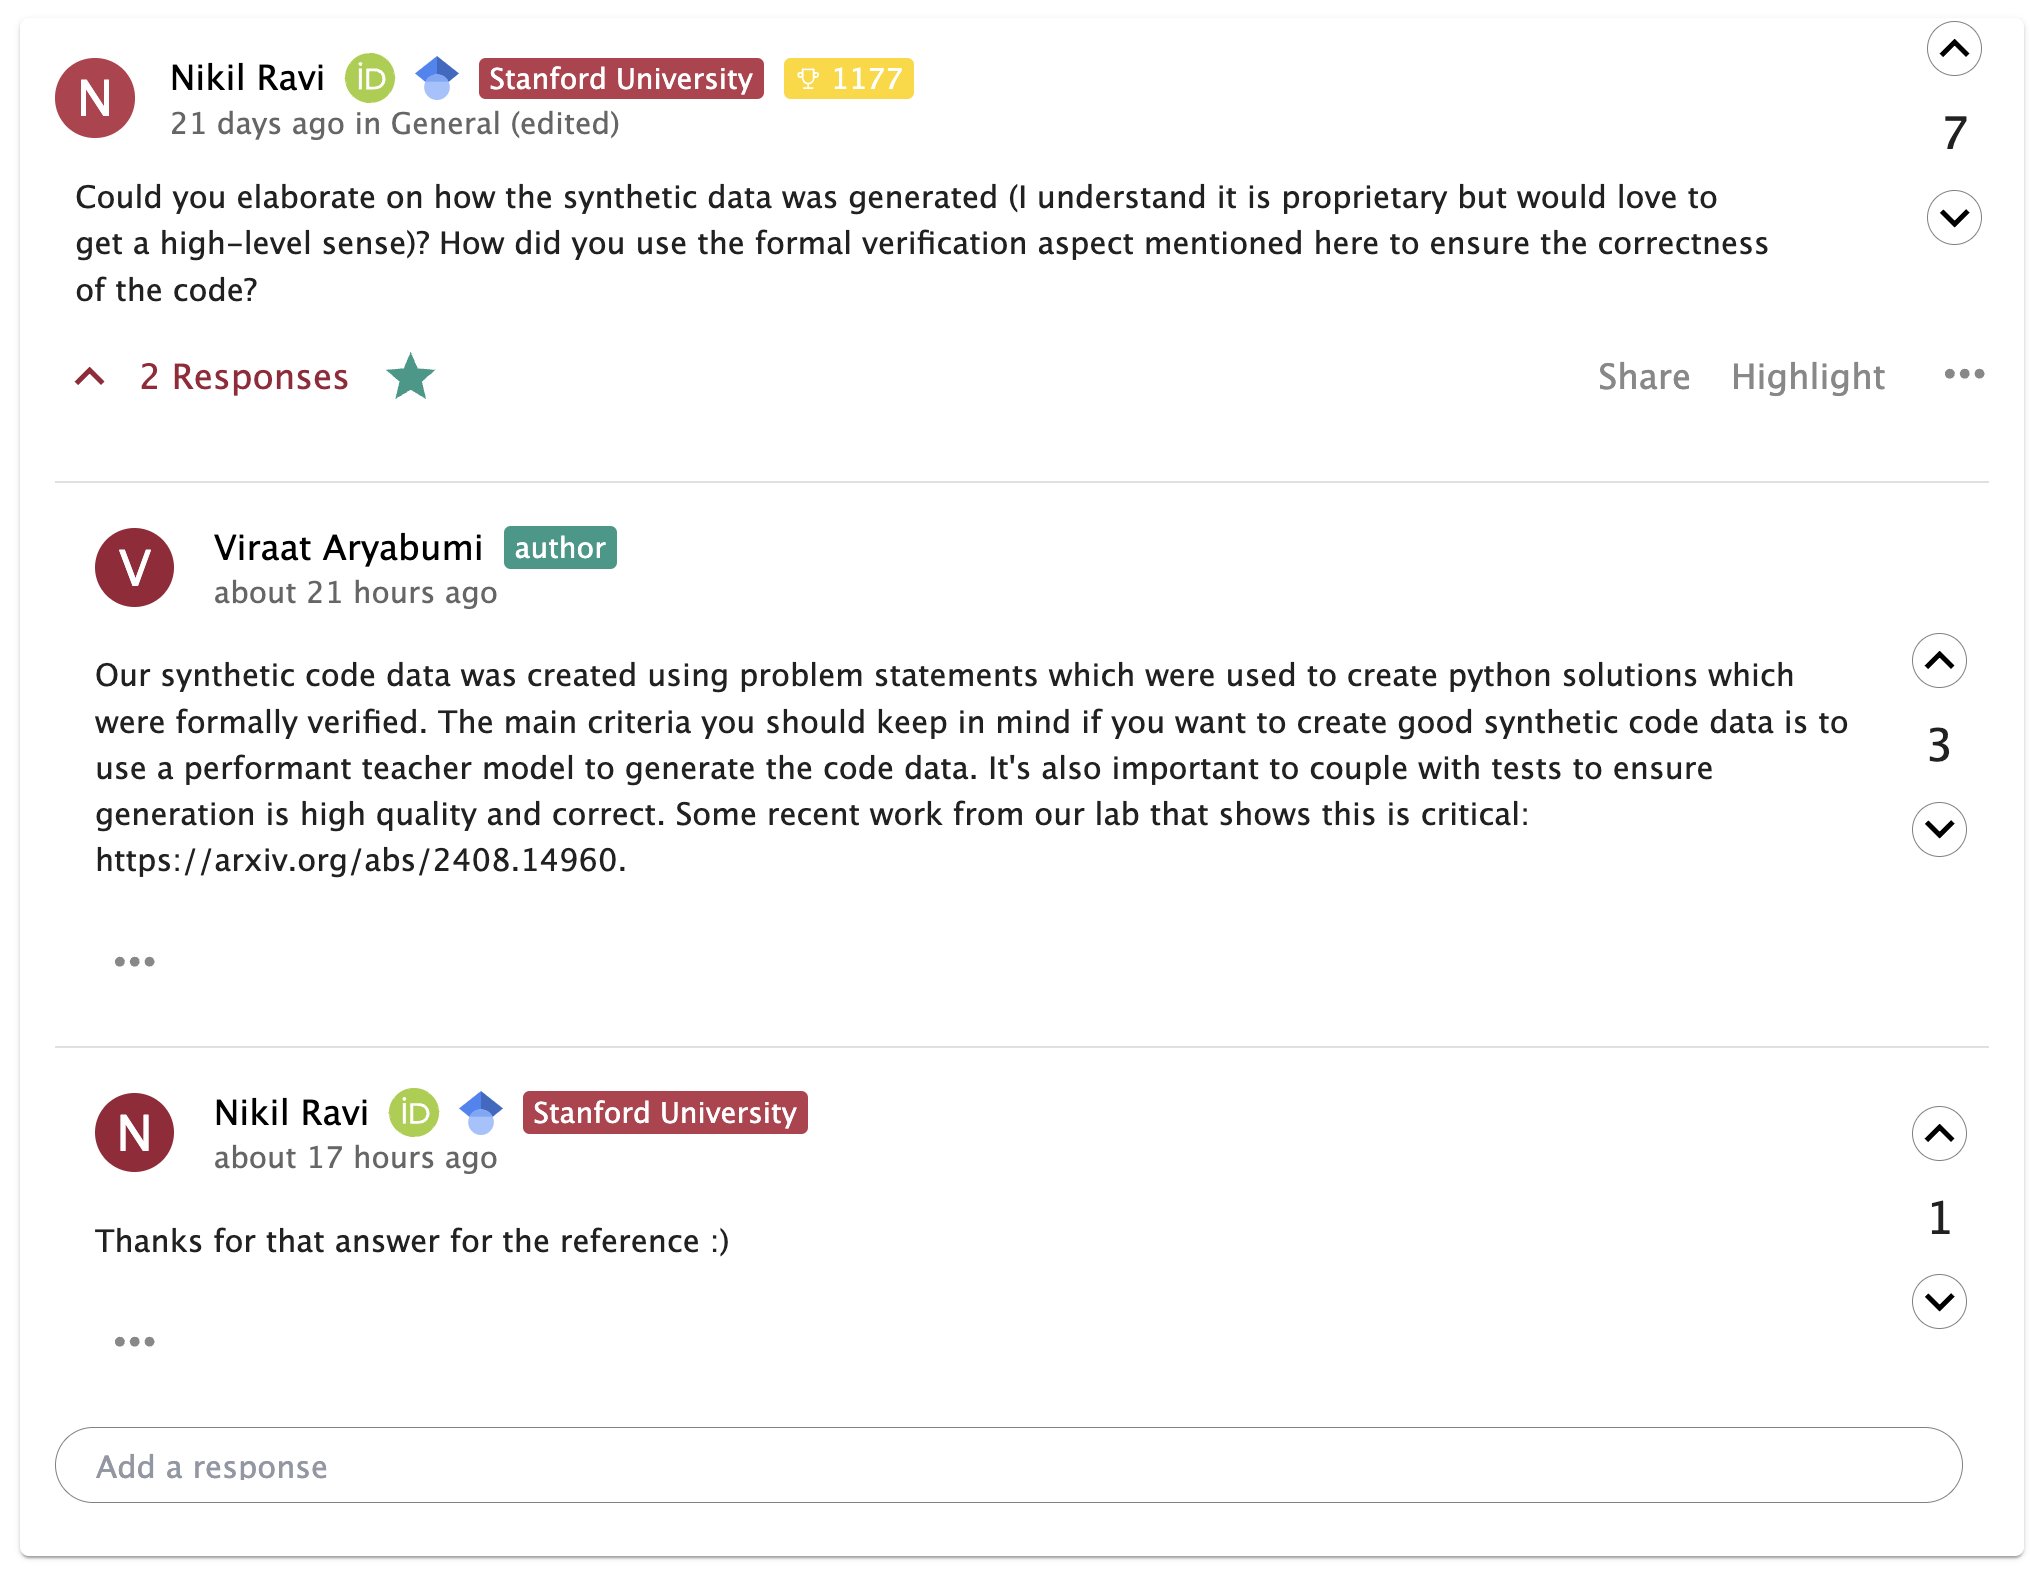
Generating High-Quality Synthetic Code Data for Pretraining
By
–
2) How can we generate high-quality synthetic code data to assist in pretraining?
-

Code Pretraining Impact on Multilingual Language Models
By
–
Tune into the excellent discussion on our most actively discussed paper this week: To Code, or Not to Code! Here are the top 5 comments/questions! Thanks again @viraataryabumi and team! 1) How does pretraining on code data impact performance on non-English downstream tasks?