Robert Douglass is a 20-year veteran of the @Drupal community, and he's also worked with us on our open source tool, EditTogether.
CODE
-
AutoTrain Job Creation and Model Training During Flight
By
–
Create an autotrain job, hop on flight, watch movies, land with trained model
-
Fine-Tuning Mistral 7B for Better Midjourney Prompts
By
–
https://
levelup.gitconnected.com/fine-tuning-mi
stral-7b-with-hugging-face-autotrain-to-generate-better-midjourney-prompts-fb96057c138a
… -
Python and ML/AI Engineering Learning Resources Newsletter
By
–
If you're interested in: – Python – ML/AI Engineering 1. Find me → @akshay_pachaar 2. Sign up for our newsletter for in-depth lessons and get a FREE eBook with 150+ core DS/ML lessons → @DailyDoseOfDS_ Cheers!
-

OpenCoder Releases RefineCoder Dataset and Training Pipeline
By
–
They also plan to release the pre-training dataset (RefineCoder), intermediate checkpoints, and the data cleaning pipeline. GitHub: https://
github.com/OpenCoder-llm/
OpenCoder-llm
… -
Leading AI Infrastructure Companies and Tools Ecosystem
By
–
@DecagonAI
, @GroqInc
, @langchain
, @Langfuse
, @LateInteraction
, @LlamaIndex
, @LMStudioAI
, @Mem0AI
, @MemGPT
, @MilvusIO 4/5 -
Leading AI Companies and Tools in Agent and Automation Ecosystem
By
–
This visual features some of my fave companies in the field, such as: @11xOfficial, @AnthropicAI
, @ArizeAI
, @AutoGPT
, @BrainTrustData, @browserbase
, @composio
, @CognitionLabs
, @CrewAIInc
, DSPY from @LateInteraction 3/5 -
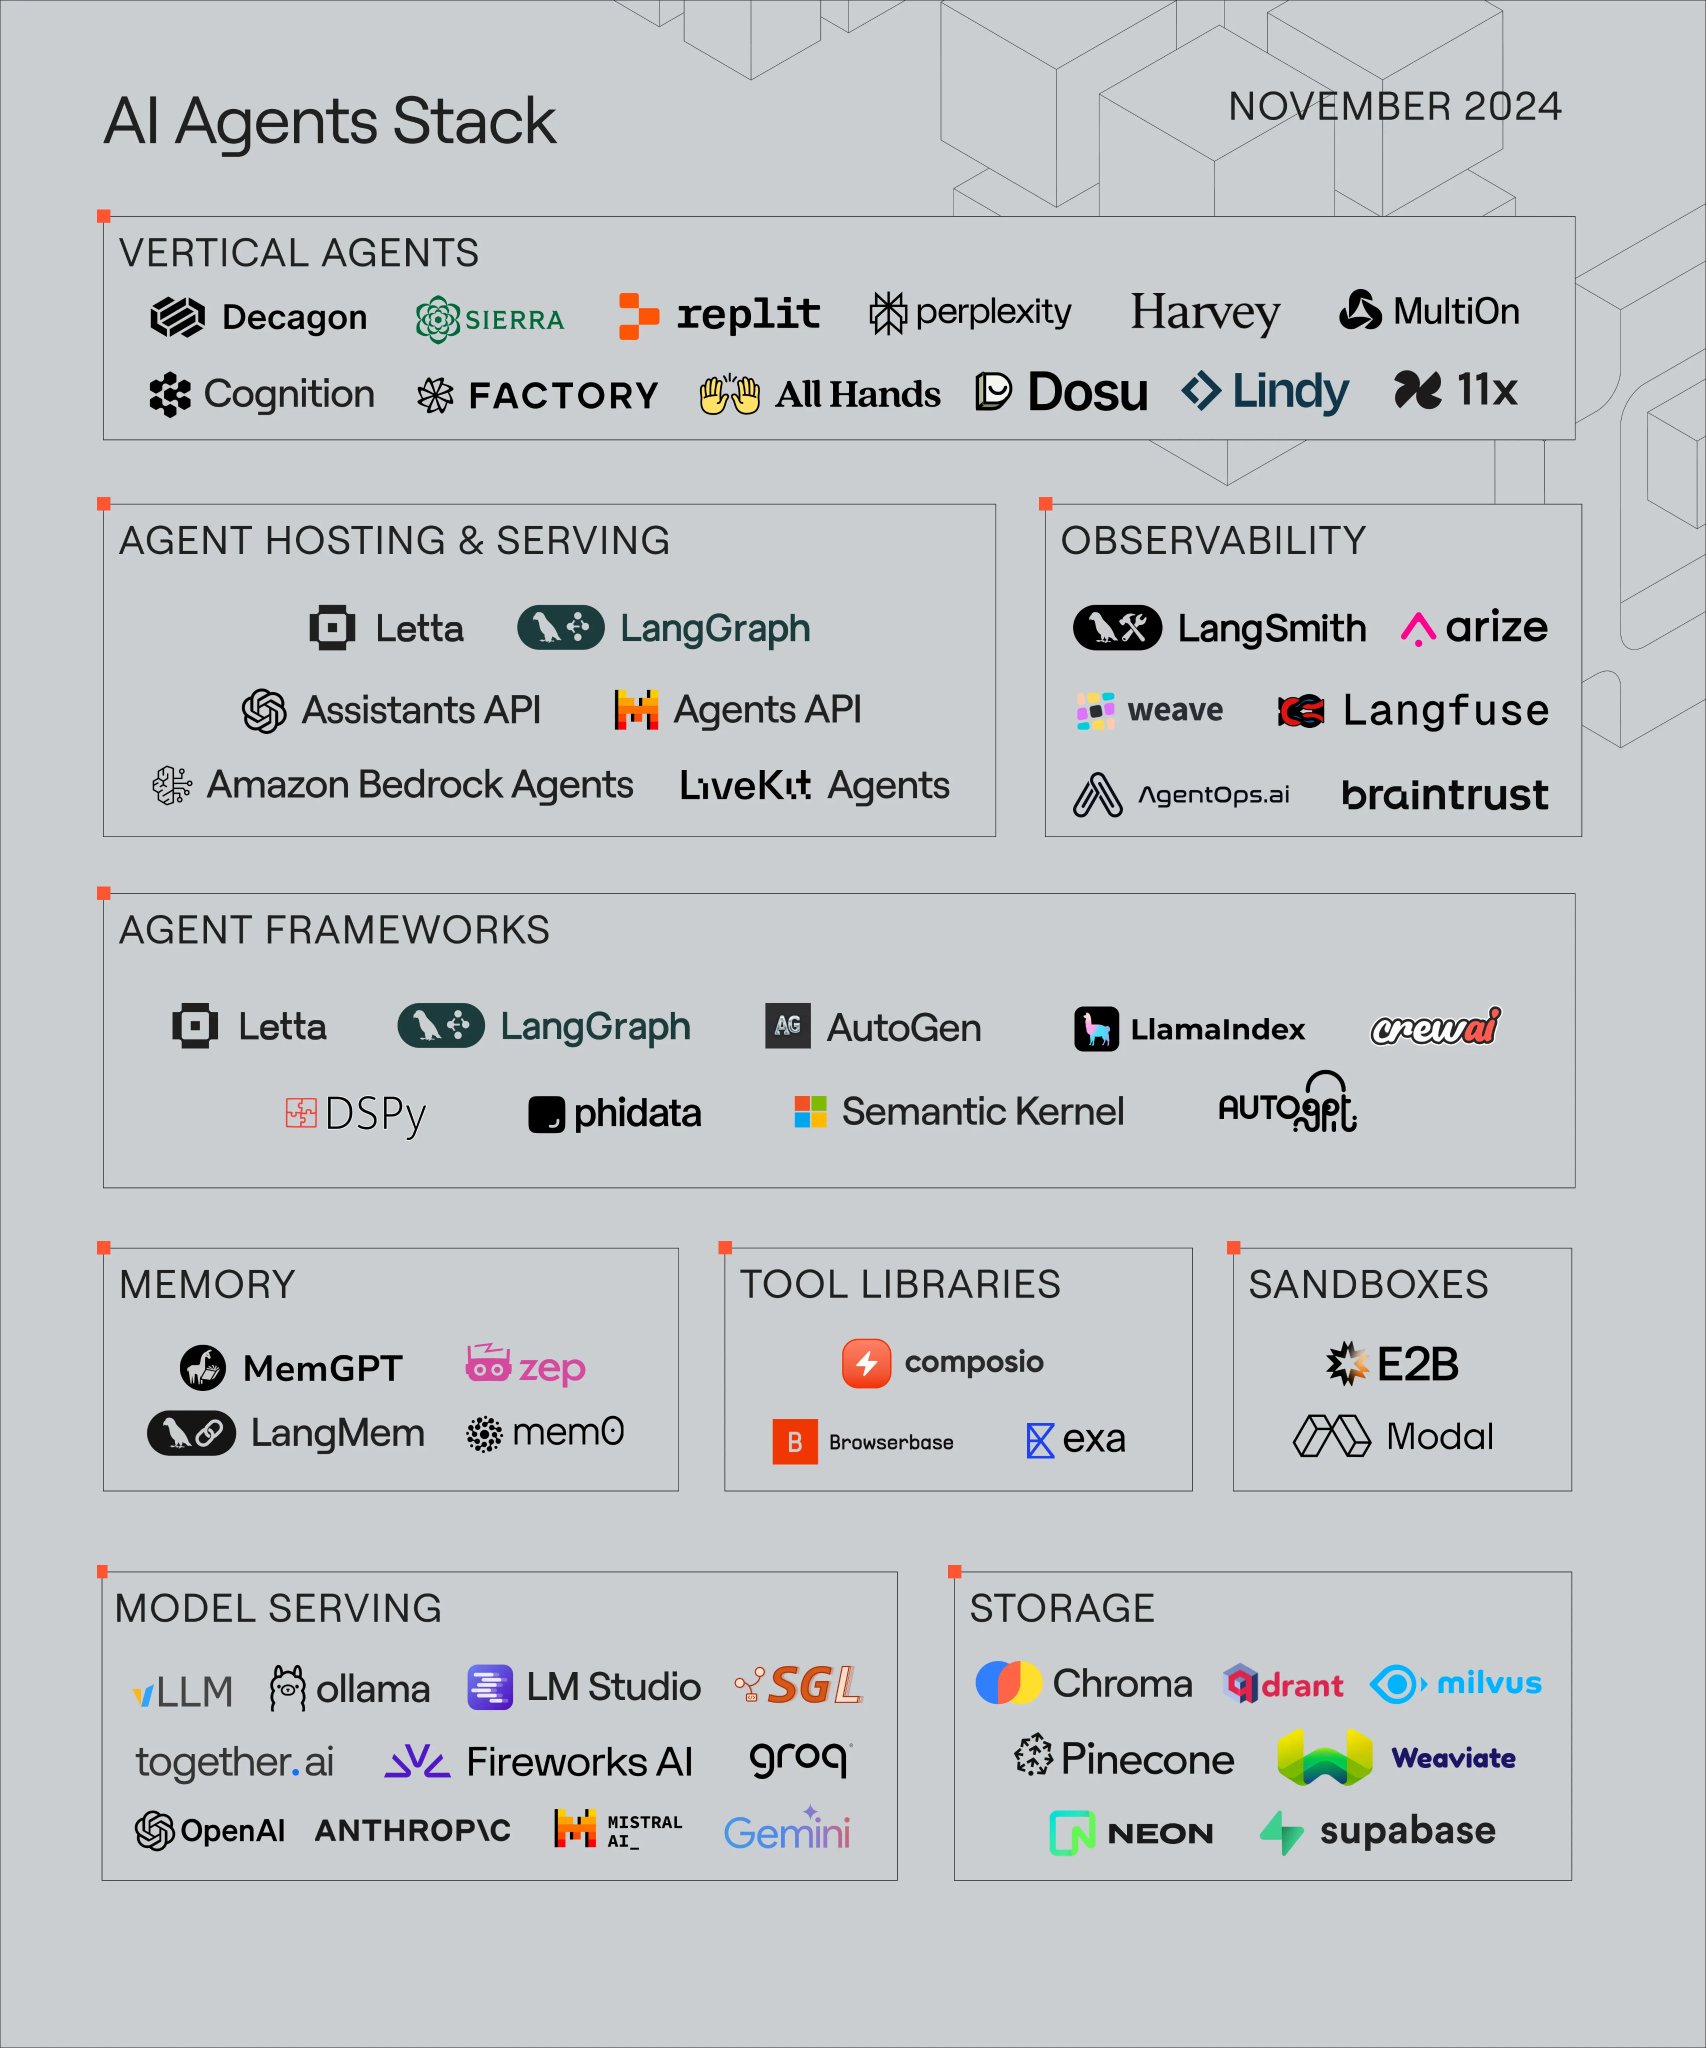
AI Agent Tech Stack: Three Essential Layers Explained
By
–
.
@Letta_AI has created a sleek visual that breaks down the tech stack for building AI agents into three key layers: Agent Hosting/Serving Agent Frameworks LLM Models & Storage -
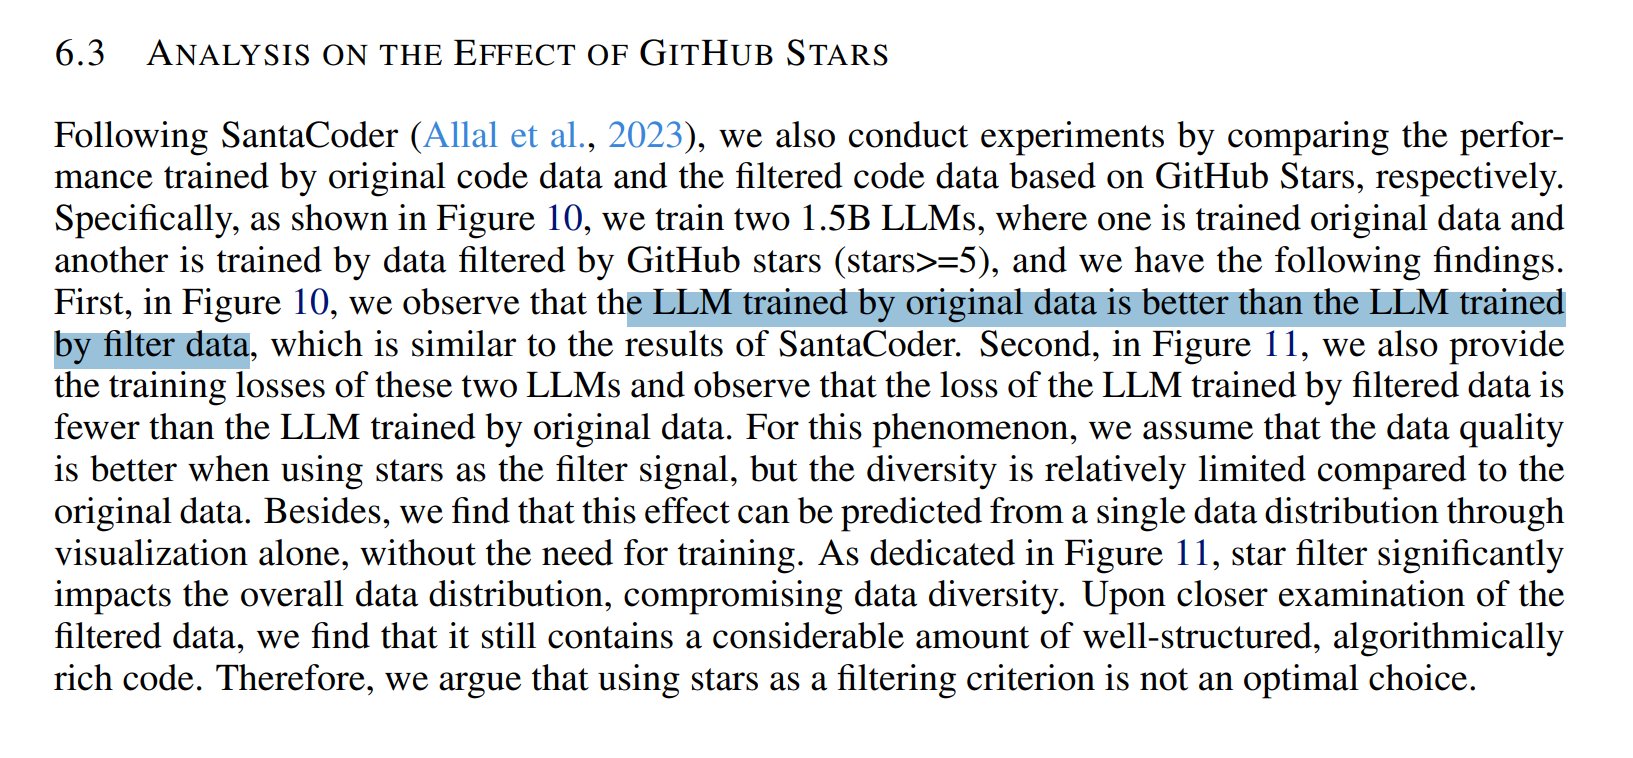
GitHub Stars Poor Predictor of Data Quality Due to Lack Diversity
By
–
This was my favorite lesson from the SantaCoder paper: GitHub stars are poor predictors of data quality, probably because of a lack of diversity.
-
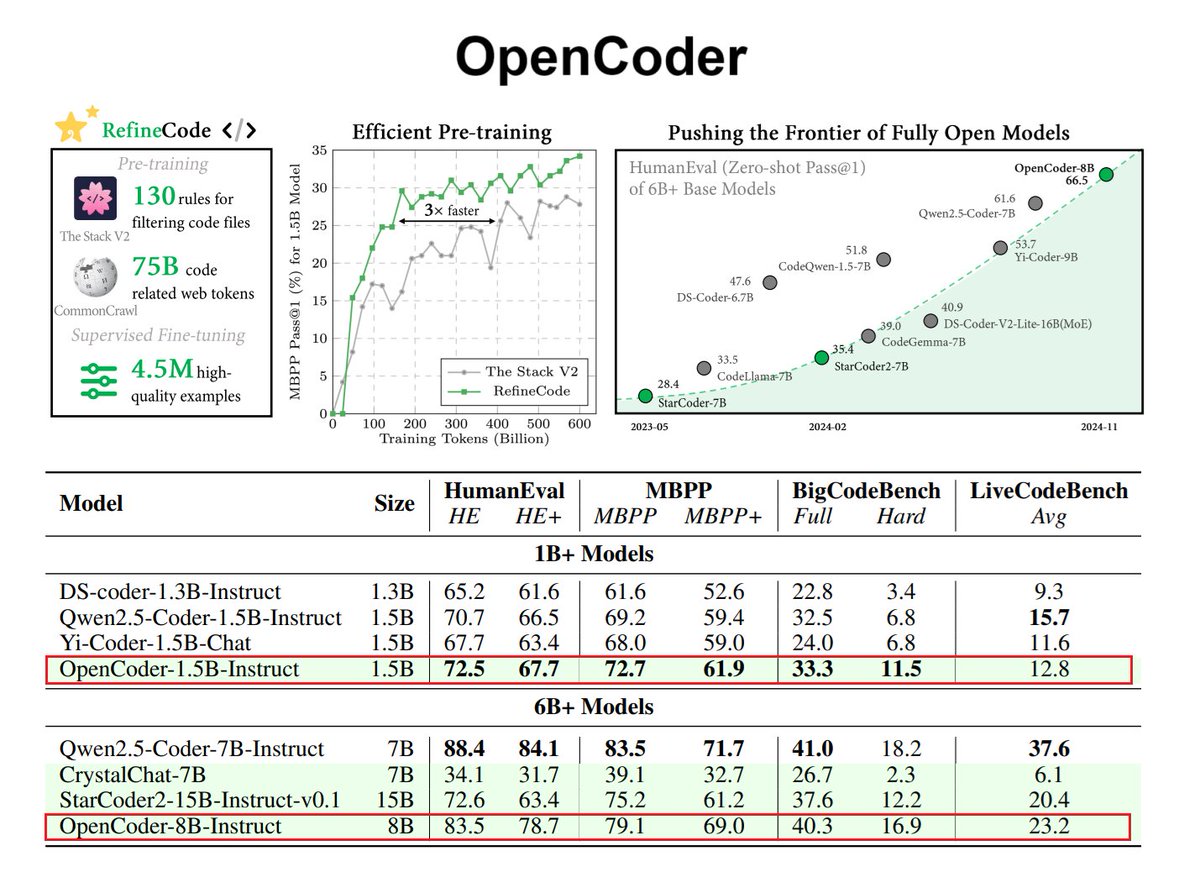
OpenCoder: Complete Open-Source Code Model Pipeline Released
By
–
OpenCoder doesn't get enough love They open-sourced the entire pipeline to create QwenCoder-level code models. This includes:
– Large datasets
– High-quality models
– Eval framework Tons of great lessons and observations in the paper Paper: https://
arxiv.org/abs/2411.04905