Problem is that codex gives me 2% of my context so random stuff adding skills gives me warning messages.
CODE
-

Claude Code Harness: Fixing AI Coding Session Breakdowns
By
–
You won't run Claude Code the same way after this. AI coding sessions often fall apart the same way. You ask for a feature, nine files get edited, something silently breaks. Claude Code Harness wraps the model in a real delivery loop. It forces a strict cycle before any
-

Optimizing Codex Prompts for AI Agent Automation
By
–
UPDATE: Came up with an even better version of this prompt after the feedback Ask Codex to look across your sessions, Memories, and Chronicle, identify patterns, reuse what already exists, and only create the smallest useful skill, subagent, or automation. "Look back over my x.com/reach_vb/statu…
-

Perplexity Open-Sources Bumblebee npm Security Scanner
By
–
Perplexity open-sourced the scanner it uses to triage npm worm waves. Bumblebee reads on-disk metadata only, never runs the package manager during a compromise. Exact (ecosystem, name, version) matching. 2,900+ stars in 5 days. Apache-2.0.
-
Building SaaS Apps with Multiple LLMs in One Prompt
By
–
🚨 One Prompt To A Fully Functional SaaS App And Complete Software
— Abacus.AI (@abacusai) 27 mai 2026
Opus 4.7 -> front-end
GPT 5.5 -> long running complex backend
Gemini 3.5 – > AI chatbot embedded in the app
Sonnet 4.6 -> scheduled task mask management
Kimi 2.6 -> simple cron jobs
One prompt will build AND… pic.twitter.com/nzMkP7ripuOne Prompt To A Fully Functional SaaS App And Complete Software Opus 4.7 -> front-end
GPT 5.5 -> long running complex backend
Gemini 3.5 – > AI chatbot embedded in the app Sonnet 4.6 -> scheduled task mask management
Kimi 2.6 -> simple cron jobs One prompt will build AND -
MiniMax-M2 Agent-Native RL Training Paper Released
By
–
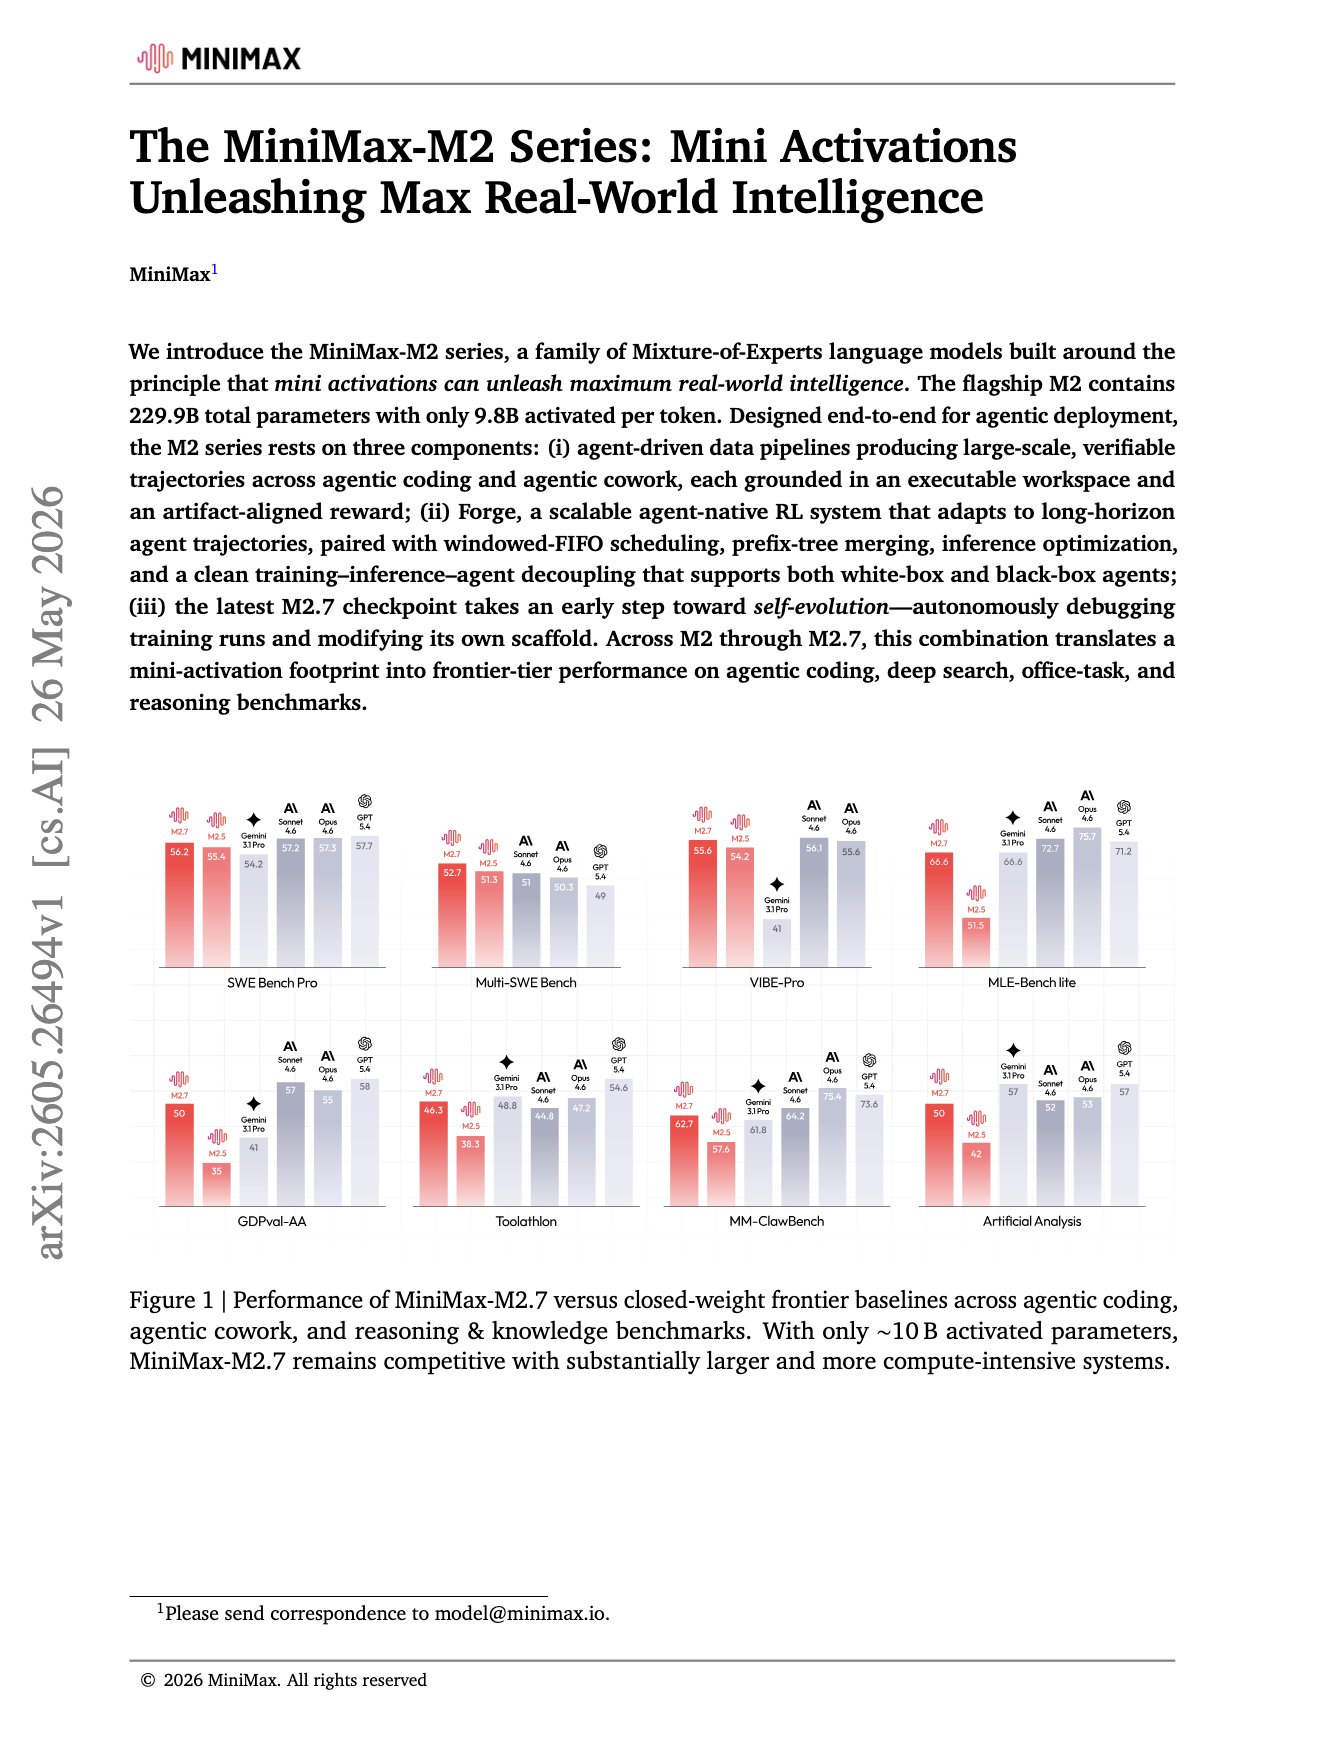
MiniMax-M2 paper just dropped The key focus of M2 is on something more agent-native. It trains on runnable workspaces and artifact-grounded rewards, then uses Forge to scale RL over long coding, app, search, and office-task trajectories. What's interesting is that M2.7
-
High-Performance AI Software Won’t Be Vibecoded
By
–
The amount of software that will need to be written for AI in high performance and specialized languages far exceeds your imagination and it WILL NOT be vibecoded
-
GPU Compatibility and LLM Inference Tool Selection
By
–
"The article’s decision guide points single modern RTX cards toward ExLlamaV2, but Oryx is not a modern RTX box: it is a Pascal GTX 1070 with compute capability 6.1, 8 GB VRAM, and the chosen model is already GGUF. That pushes the answer back to llama.cpp, not
-
Testing Qwen 3 8B on Local Ubuntu with Codex
By
–

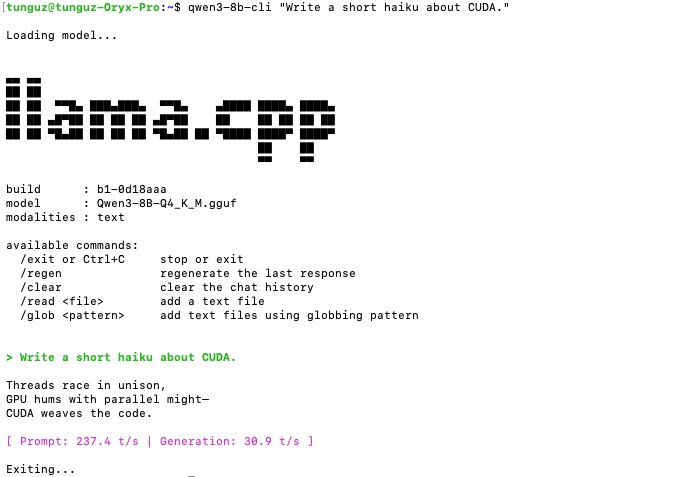
After seeing these tweets, I decided to try it out on my own old Ubuntu computer with RTX 1070 GPU (the one that I just upgraded from 16.04 all the way to 24.04 the other day). Asked Codex on my Mac to connect to that machine and install and test qwen3 8b. So far really