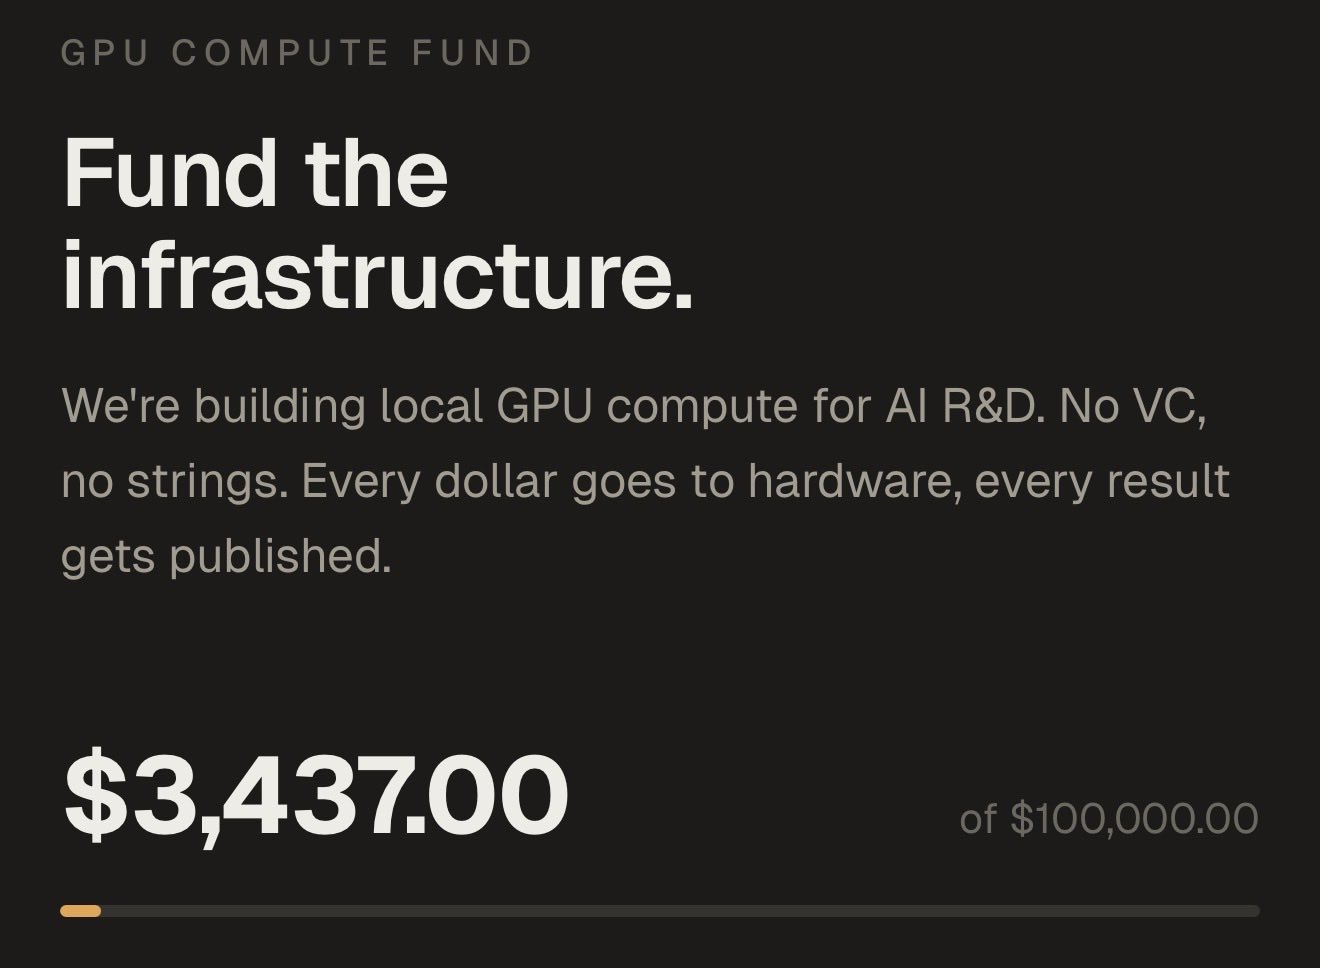
I vouched for him publicly several times and even contacted several parties both in public and in private for him to secure the compute he needed Still wish him the best and that he delivers on his promises
BIG TECH
-
Meta Announces Muse Spark, a New Multimodal AI Model
By
–
I agree Part of working in opensource is actually transparency and being open to critique (otherwise you end up with code thieves like Ollama) I hope everyone reassess themselves and work for the good of the community
-
OpenAI Anthropic IPOs Impact SF Tech Worker Affordability
By
–
Yeah, we’ll see how many non-OAI/Anthropic techbros can afford to stay in SF after those IPOs.
-
Meta’s LLM Strategy: Competing with Free ChatGPT for Everyday Users
By
–
Meta has one advantage: their LLM doesn't necessarily have to be SATA. It just has to be good enough that 99% of their Instagram and Facebook users consider it at least as useful as ChatGPT in the free tier; The use case for 99% of users is answers to everyday questions and
-
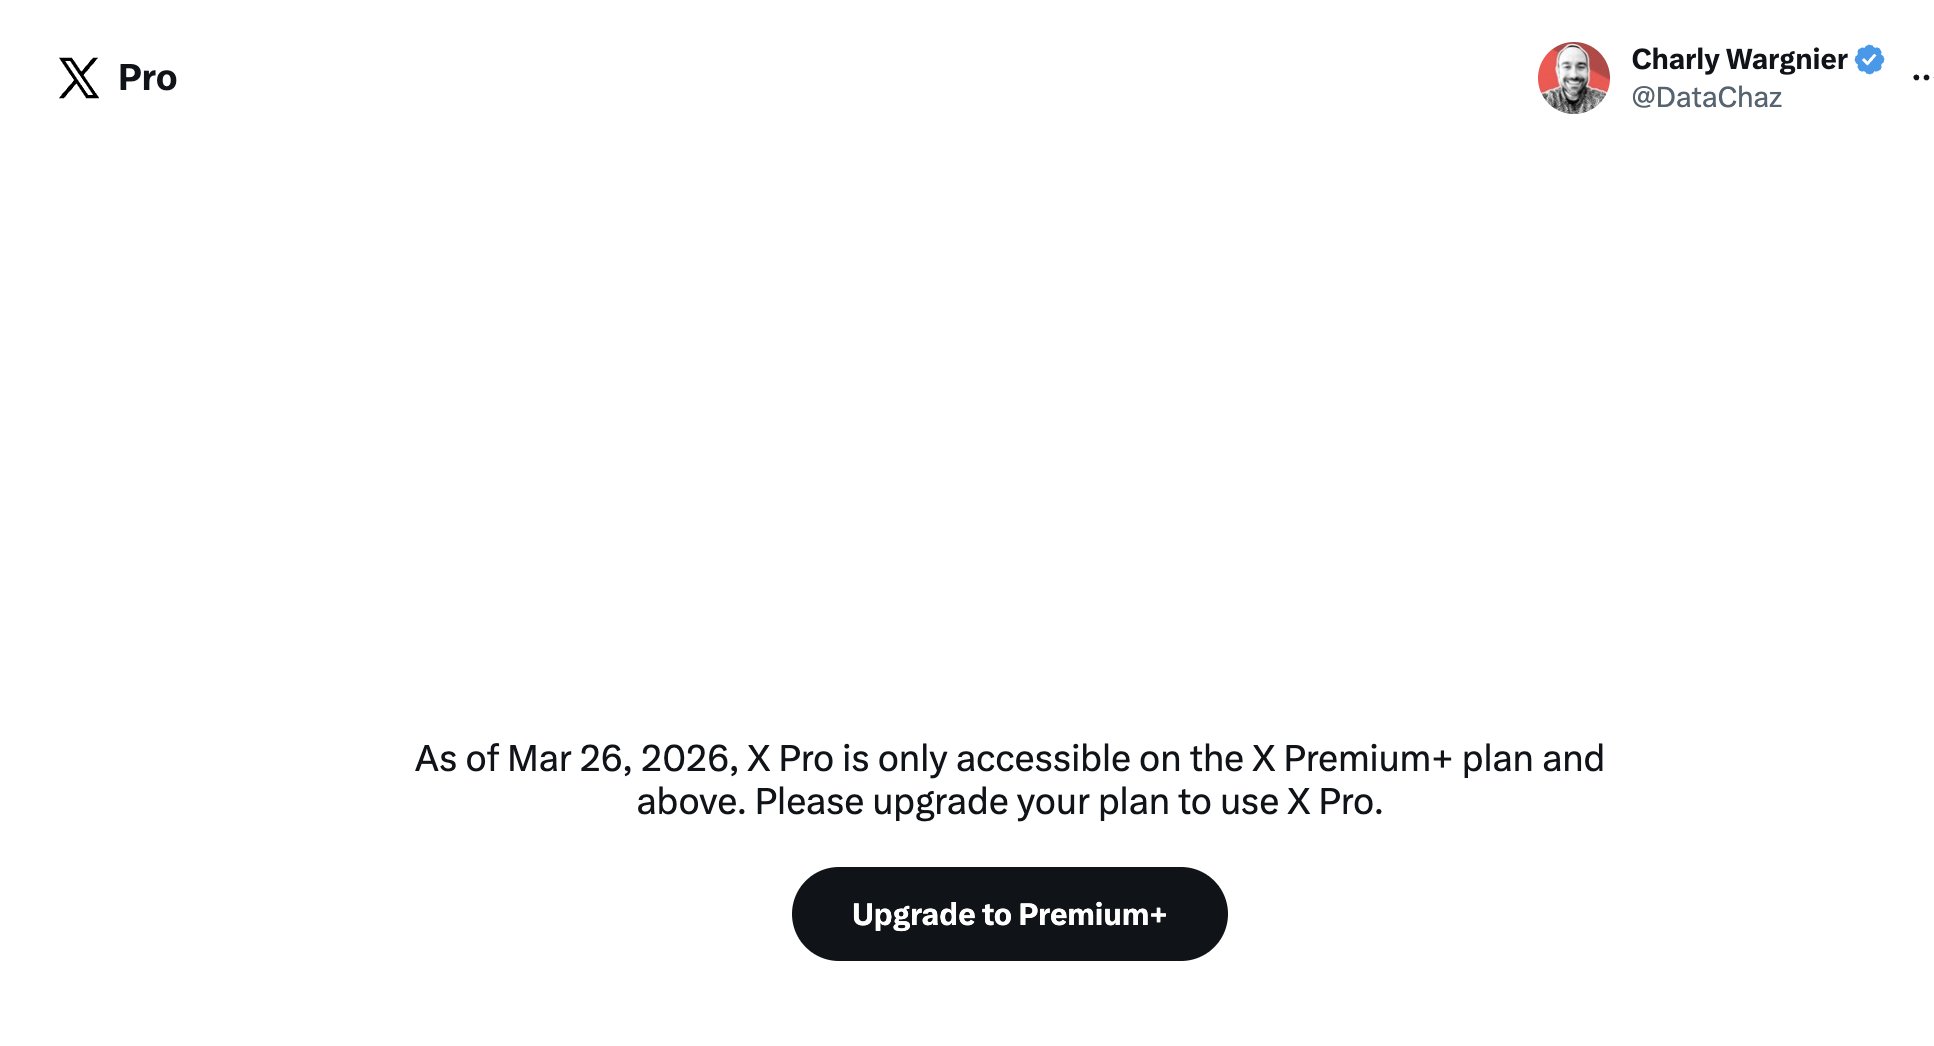
X Pro Access Now Restricted to Premium Plus Subscribers
By
–
Wow, so no more X Pro access unless you’re on Premium+? That’s a pretty harsh shift @nikitabier @X
-
Meta tests multiple Avocado AI variants internally
By
–
BREAKING : Meta is testing loads of Avocado variants internally, including multiple release candidates, Avocado-mango agent, Avocado 9B, and more. Avocado Think Hard performs quite well and, as reported earlier, is comparable to Gemini 3 level models. All this in parallel to
-
Meta Advances AI Object Understanding with SAM 3 and SAM 3D
By
–
SAM 3 and SAM 3D: Meta Platforms Pushes #AI Object Understanding Further
— Ronald van Loon (@Ronald_vanLoon) 29 mars 2026
by @AIatMeta#GenerativeAI #EmergingTech #Innovation #Tech #Technology pic.twitter.com/wnnZzU3Nw9SAM 3 and SAM 3D: Meta Platforms Pushes #AI Object Understanding Further
by @AIatMeta #GenerativeAI #EmergingTech #Innovation #Tech #Technology -
Google’s TimesFM: Foundation Model Revolutionizing Time Series Forecasting
By
–
🚀 Google just open-sourced a Time Series Foundation Model — and this changes forecasting as we know it. Meet TimesFM. Unlike traditional time-series models that require: • dataset-specific training • feature engineering • constant retraining 👉 TimesFM works out of the box — with any time-series data. No fine-tuning. No custom pipelines. Just plug and forecast. 🔍 What makes this a breakthrough? 🧠 Foundation model for time series Trained on 100B real-world time-points across: • traffic patterns • weather systems • demand forecasting ⚡ Zero-shot forecasting Generalizes across domains without retraining. 📈 Production-ready from day one Eliminates the heavy overhead of building bespoke models per dataset. 🏗️ Architecture Takeaways • Shift from model-per-dataset → generalized forecasting models • Pretraining at scale enables cross-domain pattern learning • Signals a move toward “forecasting as a service” abstraction layer • Reduces dependency on feature engineering pipelines 💡 Why this matters We’re witnessing the “GPT moment” for time series. The implication is massive: → Faster deployment cycles → Lower ML engineering cost → Democratized forecasting capabilities This could fundamentally reshape industries like: • supply chain • finance • energy • climate analytics 🔗 Explore the repo: github.com/google-research The big question now: 👉 Will domain-specific models survive… or will foundation models dominate forecasting too? 🔗 Follow my communities and personal initiatives: • Amazing AI, Data, Quantum Computing & Emerging Technologies — drdebashisdutta.com/ • Research & Innovation – Quantum, AI & Advanced Systems — researchedge.org/ #AI #MachineLearning #TimeSeries #GenerativeAI #DataScience #Forecasting #Innovation:
→ View original post on X — @debashis_dutta, 2026-03-29 15:54 UTC
-
VibeVoice GitHub Repository – Don’t Forget to Star
By
–
VibeVoice GitHub: github.com/microsoft/VibeVoi… (don't forget to star 🌟)
→ View original post on X — @akshay_pachaar, 2026-03-29 13:11 UTC
-
Microsoft VibeVoice: Revolutionary Open-Source Speech AI Models
By
–
Microsoft did it again!
— Akshay 🚀 (@akshay_pachaar) 29 mars 2026
Speech AI models have a major limitation.
They slice long recordings into tiny chunks, lose track of who's speaking, and forget all context halfway through.
This is exactly what Microsoft's VibeVoice solves.
It's an open-source family of frontier voice… pic.twitter.com/YaXz1O9IQwMicrosoft did it again! Speech AI models have a major limitation. They slice long recordings into tiny chunks, lose track of who's speaking, and forget all context halfway through. This is exactly what Microsoft's VibeVoice solves. It's an open-source family of frontier voice AI models for both speech recognition and speech generation. Here's what it can do: > VibeVoice-ASR processes up to 60 minutes of audio in a single pass. No chunking. It outputs structured transcriptions with who spoke, when they spoke, and what they said. > You can feed it custom hotwords like names, technical jargon, or domain-specific terms. The model uses them to significantly improve accuracy on specialized content. > VibeVoice-TTS generates up to 90 minutes of multi-speaker speech with up to 4 distinct speakers. Natural turn-taking, emotional expression, all in one pass. > VibeVoice-Realtime is a 0.5B streaming TTS model with ~300ms first-audio latency. Small enough to deploy practically anywhere. All of this is powered by continuous speech tokenizers running at just 7.5 Hz. This ultra-low frame rate preserves audio quality while making long sequences computationally feasible. I have shared the link to the GitHub repo in the replies!
→ View original post on X — @akshay_pachaar, 2026-03-29 13:11 UTC