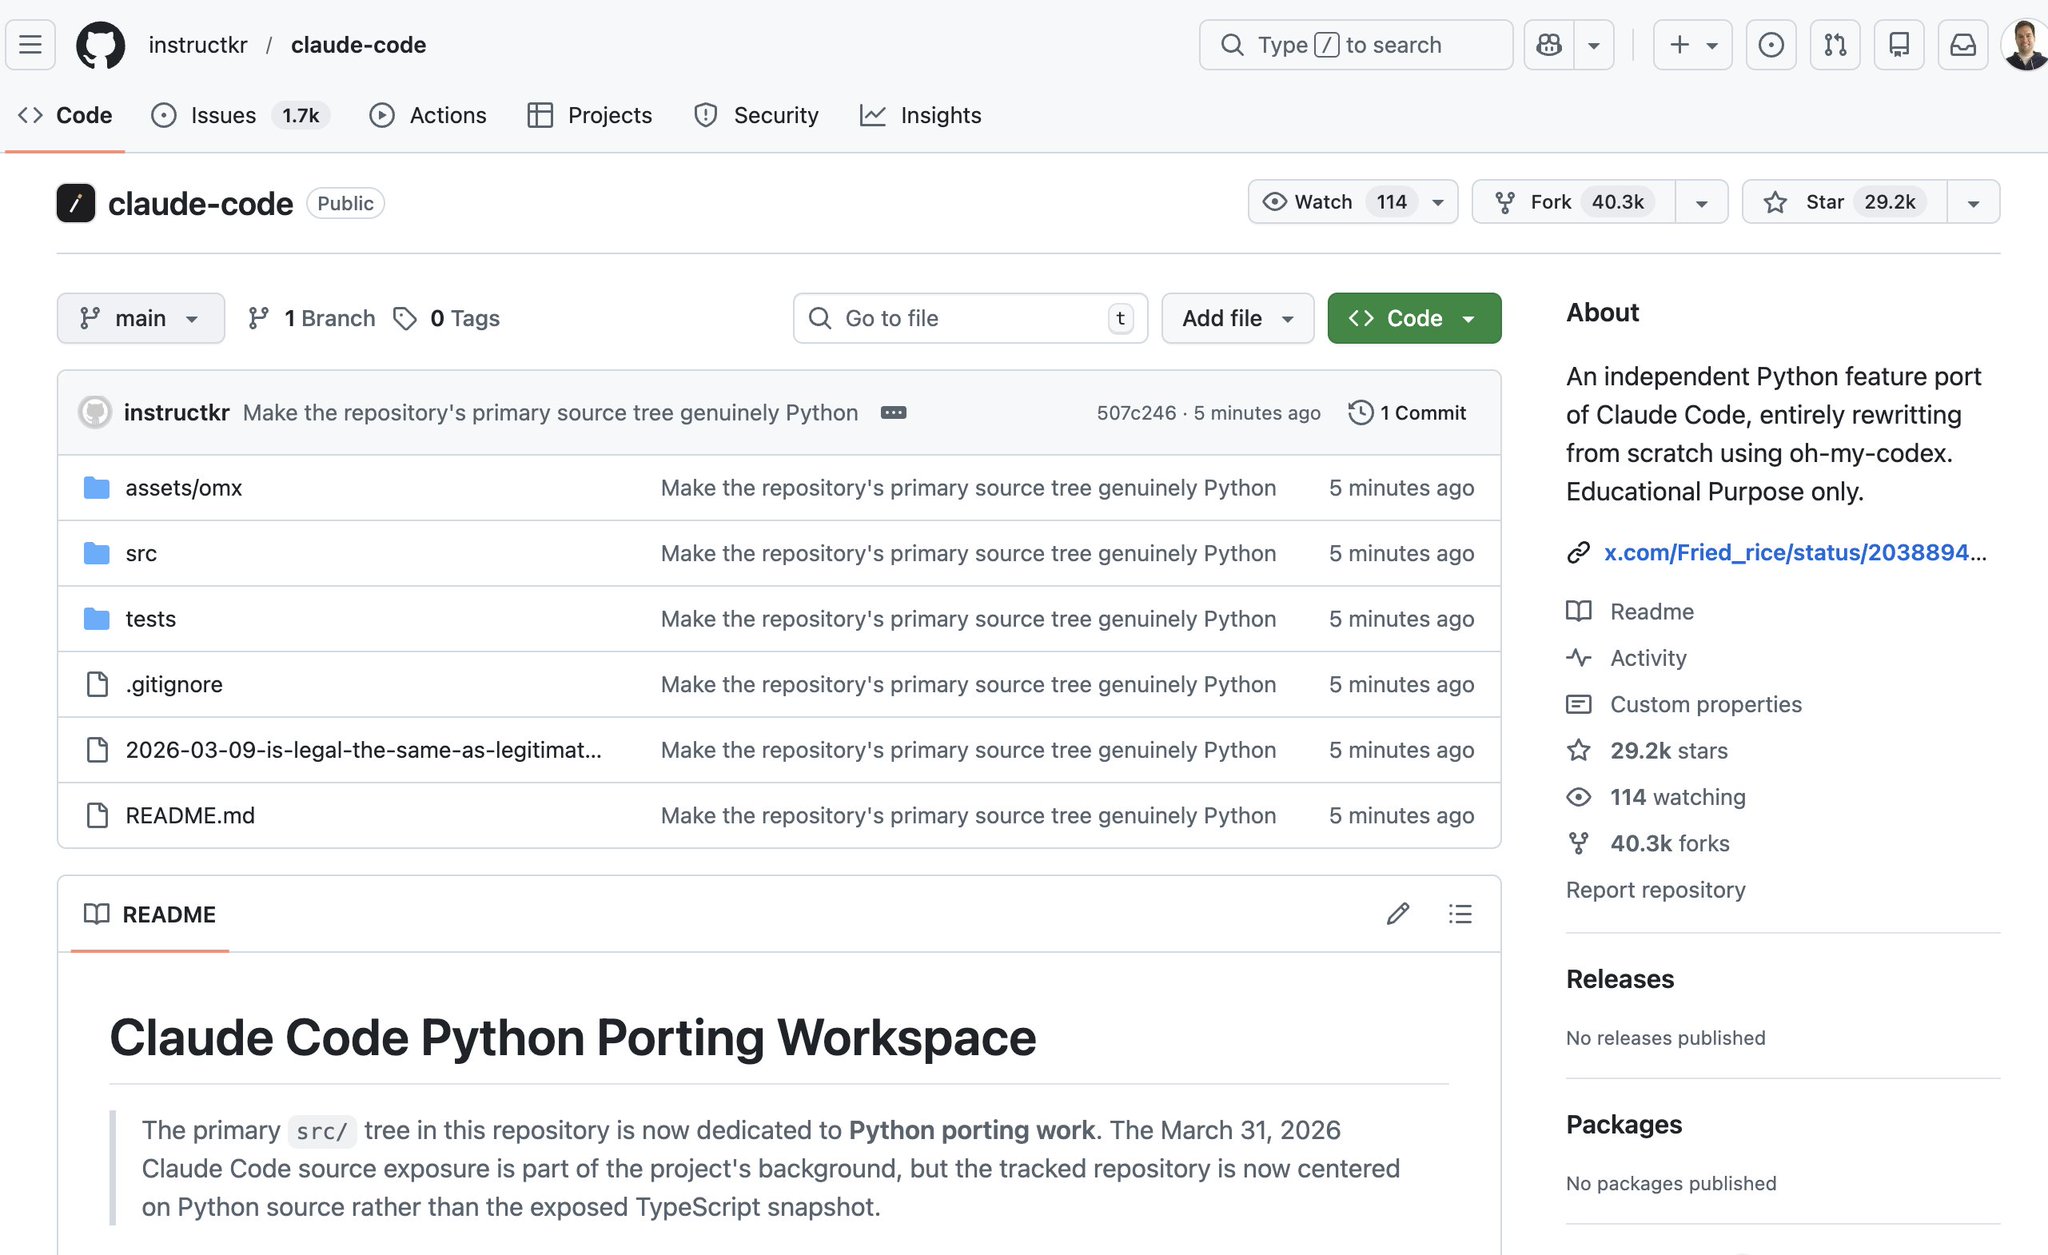
This is either brilliant or scary: Anthropic accidentally leaked the TS source code of Claude Code (which is closed source). Repos sharing the source are taken down with DMCA. BUT this repo rewrote the code using Python, and so it violates no copyright & cannot be taken down!
AI
-
Code Leaks Lead to Python Alternative Development
By
–
just wait it leaks then they make a python instead
-
Databricks Named #2 in 2026 Enterprise Tech 30 List
By
–
The 2026 Enterprise Tech 30 list is out, and Databricks has been named #2 in the Giga Stage! Over 90 leading VCs and corporate development leaders selected the #ET30, recognizing the top private companies shaping enterprise technology and transforming the future of work. Thank
-
LangChain Partners with MongoDB for AI Stack Integration
By
–
Announcing our partnership with @MongoDB
: The AI Stack that runs on the database you already trust Atlas Vector Search as a drop-in retriever. MongoDB Checkpointer for durable agent state in LangSmith Deployment. Text-to-MQL for natural-language queries over operational data. -
LeJEPA: Scalable Self-Supervised Learning Without Heuristics Analysis
By
–
nitter.net/ID_AA_Carmack/status/2… John Carmack (@ID_AA_Carmack) #PaperADay 10 LeJEPA: Provable and Scalable Self-Supervised Learning Without the Heuristics arxiv.org/pdf/2511.08544 The comments on #PaperADay 3 recommended this paper as the state of the art JEPA paper, and it does look much better! They acknowledge that much of the prior JEPA research is ad-hoc and full of heuristics, but here they make strong theoretical claims of optimality and provide proofs (which I did not read). The first claim is that isotropic gaussian is the unique optimal embedding distribution for both linear and nonlinear probing, minimizing worst-case risk across downstream tasks. I would have taken that on faith with just a “sounds good to me”, but they go into it with details and examples. Actually getting an isotropic gaussian in high dimensions is easier said than done. They present Sketched Isotropic Gaussian Regularization (SIGReg) as a well behaved loss function to achieve this after analyzing a number of different statistical tests, and they claim it beats the curse of dimensionality with linear scalability. The final loss is just a blend factor to weight the JEPA prediction loss against the SIGReg isotropy loss. This is the one tunable hyperparameter for LeJEPA. Despite the P in JEPA, they don’t use predictor networks here, they just directly compare view embeddings for the JEPA loss. Predictor networks could still be useful for video sequences, especially when conditioned with action information for agents / robots. Each training image is augmented to produce 2 global views and 6 local views with different spatial scales but the same set of color and geometric transformations. The loss is the average MSE between the average of the global view embeddings and each of the local view embeddings. I don’t have a good feel for the tradeoffs in their view transforms, which still seem very much in the ad-hoc space, but they will determine the nature of what gets filtered out of the representation. Learning what doesn’t matter is critical, but the specification of “matters” is only implicit in the view transformations. LeJEPA itself is architecture independent – anything that digests a batch of samples from a dataset into vectors can be used. Vision transformers, MLP, ConvNets, etc. The specific augmentations for views would be input modality specific, but the LeJEPA algorithm could work on audio, images, video, or other things. They show that the LeJEPA loss on a large foundation model is very indicative of downstream task performance, both directly, and with a heuristic to improve the predictive power of the loss farther. They also show that it can be used to train from scratch on small datasets with as few as 1000 samples and achieve better results than probing a conventional general foundation model. I was pleased to see sample code blocks in the paper instead of greek-laden pseudocode, as well as a github repo. Appendix D has interesting details on generating good coverage of unit hyperspheres with low discrepancy samples by transforming Sobol sequences, but this is only for their theoretical analysis, and they show you are better off just making new random hypervectors every batch, with even 16 random vectors outperforming a fixed set of thousands. Some questions: In the discussion of non-linear probing, only kNN and kernel methods are mentioned, presumably for their theoretical analysis tractability, but would an MLP generally perform better? A JEPA embedding is not fully reversible like NICE or a RevNet, so how does it react to inputs that are far outside the training set? Will novel inputs map to unique embeddings, or could they be collapsed onto the codes from the training set? How would the embeddings evolve in a continuous learning environment, as novel inputs are added to the training mix? Can a JEPA be overtrained – is lower training loss always better, or would there be an optimal early stopping point? — https://nitter.net/ID_AA_Carmack/status/2014883608037556431#m
→ View original post on X — @id_aa_carmack, 2026-03-31 18:24 UTC
-
LeWorldModel: Stable JEPA Architecture for Offline Robotics World Models
By
–
Paper review: LeWorldModel: Stable End-to-End Joint-Embedding Predictive Architecture from Pixelshttps://t.co/2dD7hPIURL
— John Carmack (@ID_AA_Carmack) 31 mars 2026
Nice clean github: https://t.co/YZ4e1eUACi
This is the application of the LeJEPA results to world models, trained offline on experience from three different… https://t.co/rJojWTCP6bPaper review: LeWorldModel: Stable End-to-End Joint-Embedding Predictive Architecture from Pixels arxiv.org/pdf/2603.19312 Nice clean github: github.com/lucas-maes/le-wm This is the application of the LeJEPA results to world models, trained offline on experience from three different robotics style tests with one to two million steps in each dataset. Re-states the benefits of the SigReg loss relative to prior world model approaches. Uses ImageNet standard 224×224 RGB pixel input images with an unmodified ViT-Tiny vision transformer from HuggingFace to generate latents. One extra post-projection step is needed to give SigReg the necessary freedom to perturb the latents into independent gaussians, since ViT ends with a layernorm’d layer. Also tested with ResNet-18, which still performed well, but slightly worse. Uses a 192 dimensional latent. Performance slightly dropped when doubling the latent size to 384; it would be nice to know if it was stable there, or if it continued worsening with excessive latents. There is a relationship between batch size and SIGReg, the larger latent may have improved performance if the batch size was increased. The predictor is implemented as a ViT-S backbone – Why a vision transformer when the latent is flat? Uses a history of 3 sets of latents for two of the benchmarks and 1 for the other. Performance was markedly better with the “small” ViT model than the “tiny”, but the larger “base” model degraded notably, which is interesting. Dropout of 0.1 on the predictor significantly improved performance. 0.2 was still better than 0.0, but 0.5 was worse. Trained with a batch of 128 x 4 trajectories. I wish their training loss graphs were more zoomed in with grid lines. Performs planning at test time instead of building a policy by training in imagination like Dreamer / Diamond. Rolls out 300 initially random sets of actions up to a planning horizon H of 5 (at frame-skip 5). Iterates up to 30 times using the Cross Entropy Method (CEM). The main paper body mentions using Model Predictive Control (MPC) strategy, where only the first K planned actions are executed before replanning, but appendix D says they execute all 5 planned actions. After training, they probe the latent space to demonstrate that it does capture and represent physically meaningful quantities. They also implement a decoder from the latent space back to pixels – not used by the algorithms, but helpful to see what things the latent space is actually representing. They tested incorporating the reconstruction loss into training, but it hurt performance somewhat. They wound up with a 0.1 lambda for SigReg, as opposed to 0.05 in the LeJEPA paper. 1024 sigreg projections, but observe the number has negligible impact I like the JEPA framework, but so far my attempts to use it on Atari games with value functions have not matched my other efforts. Lucas Maes (@lucasmaes_) JEPA are finally easy to train end-to-end without any tricks! Excited to introduce LeWorldModel: a stable, end-to-end JEPA that learns world models directly from pixels, no heuristics. 15M params, 1 GPU, and full planning <1 second. 📑: le-wm.github.io — https://nitter.net/lucasmaes_/status/2036080584569618741#m
→ View original post on X — @id_aa_carmack, 2026-03-31 18:24 UTC
-
Marpipe Enables AI-Powered Dynamic Product Ads at Scale
By
–
Most brands running large catalogs have been invisible in the DPA creative race since gen AI arrived.
— AI Highlight (@AIHighlight) 31 mars 2026
Marpipe just handed them a weapon pick your model, set your direction, and let it enrich and deploy across your entire SKU library in minutes.
The playing field just… https://t.co/l8JIS2Ers7Most brands running large catalogs have been invisible in the DPA creative race since gen AI arrived. Marpipe just handed them a weapon pick your model, set your direction, and let it enrich and deploy across your entire SKU library in minutes. The playing field just shifted. Dan Pantelo (@danpantelo) Gen AI works for one-off ads, but is unusable for product catalogs / DPA. Ecom brands have hundreds of SKUs and are spending 50%+ ad spend on DPA. They’re being left behind. Until now. Introducing, Generative Catalogs: redesign your entire product catalog and DPA in minutes. — https://nitter.net/danpantelo/status/2039010334908850327#m
→ View original post on X — @aihighlight, 2026-03-31 18:17 UTC
-
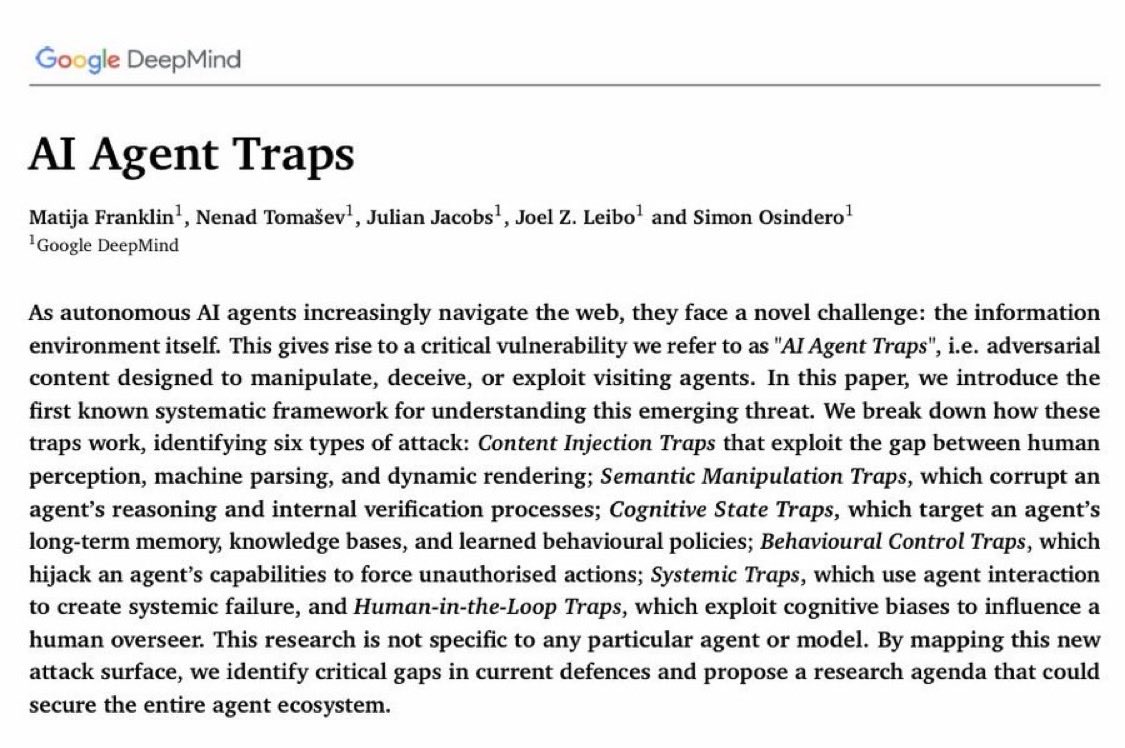
AI Agent Traps: Beyond Prompt Injection to Environment-Level Threats
By
–
AI agents don’t just inherit LLM risks — they amplify them. I came across an interesting paper: “AI Agent Traps.” Most discussions still focus on prompt injection. That’s already incomplete. Because once agents have: – autonomy – persistence – tool access …the attack surface fundamentally shifts. ➡️ The real vulnerability becomes the information environment itself. Everything an agent interacts with can be adversarial: – web pages – emails – APIs – databases All of it can be weaponized. The paper outlines a taxonomy of six adversarial trap classes — from: – hidden prompt injections embedded in content – to systemic risks across multi-agent ecosystems What stands out is the shift from: model-level threats → environment-level threats That’s where most current agent architectures are still underprepared. If you’re building or deploying AI agents, this is worth paying attention to. Paper link : papers.ssrn.com/sol3/Deliver… 🔗 Follow my communities and personal initiatives: • Amazing AI, Data, Quantum Computing & Emerging Technologies — drdebashisdutta.com/ • Research & Innovation – Quantum, AI & Advanced Systems — researchedge.org/ #AIAgents #LLMSecurity #PromptInjection #AgenticAI #AISafety #MultiAgentSystems #CyberSecurity #CyberSecurity
→ View original post on X — @debashis_dutta, 2026-03-31 18:11 UTC
-
Vibe Coding: How Kids Build Apps Without Programming Knowledge
By
–
🎮👦 Vibe Coding: When Kids Build Apps
— Satya Mallick (@LearnOpenCV) 31 mars 2026
Two 10-year-olds on a playdate decided to vibe code a desktop app that controlled their TV volume. 📺✨
They didn’t fully grasp MAC vs. IP addresses but that’s the magic of learning. It’s messy, playful, and surprisingly powerful. If kids… pic.twitter.com/D6vJQqGAU8🎮👦 Vibe Coding: When Kids Build Apps Two 10-year-olds on a playdate decided to vibe code a desktop app that controlled their TV volume. 📺✨ They didn’t fully grasp MAC vs. IP addresses but that’s the magic of learning. It’s messy, playful, and surprisingly powerful. If kids can build apps with almost no programming knowledge, the future of software creation is becoming more accessible than ever. 🚀 Of course, ease comes with risks—critical mistakes can happen but the upside is clear: more people will be empowered to create. #VibeCoding #AI #CodingLife #Innovation #FutureOfWork #LearningByDoing #TechStory #DeveloperLife 🤖
→ View original post on X — @learnopencv, 2026-03-31 18:10 UTC
-
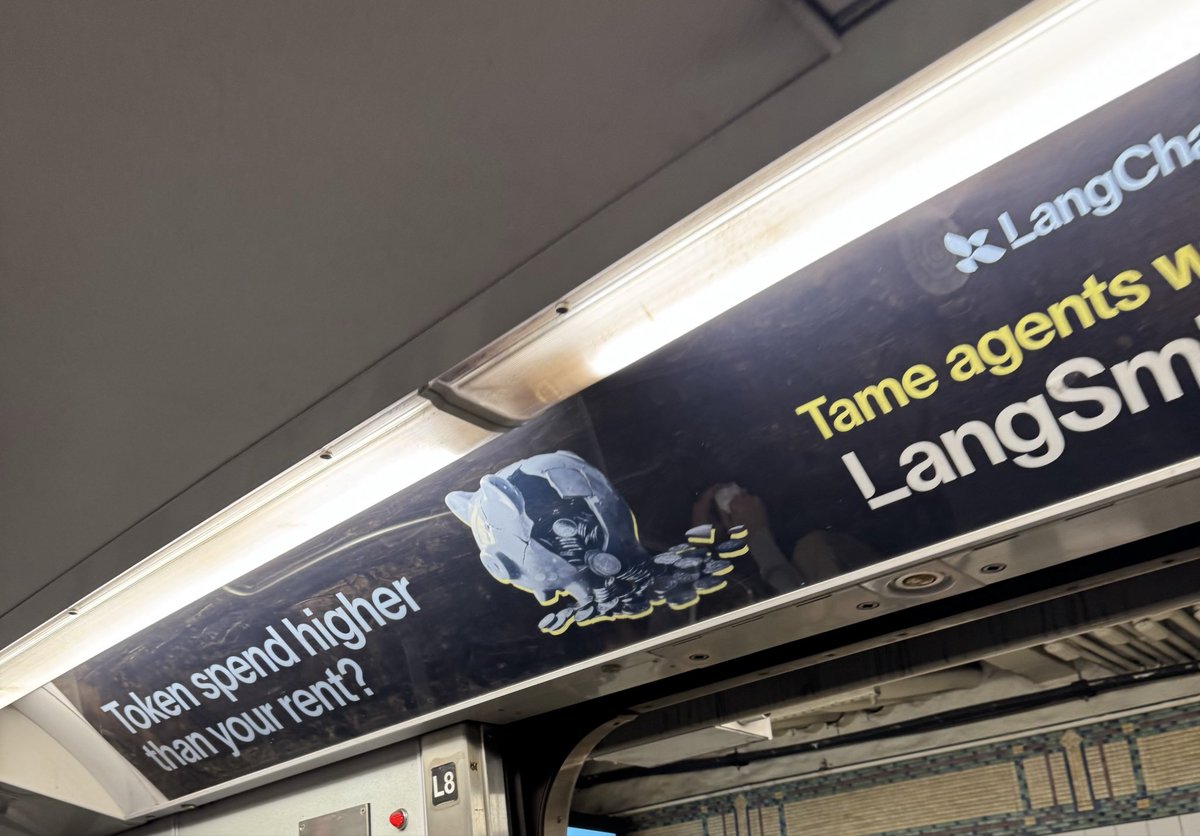
LangChain Posts Humorous Ad About Token Spending
By
–
Great ad by @LangChain "token spend higher than your rent?" [Translated from EN to English]
→ View original post on X — @langchain, 2026-03-31 18:10 UTC