AI Dynamics

Global AI News Aggregator

About

AI

  • One-Step AI Image Generation Framework Achieves State-of-the-Art Results
    One-Step AI Image Generation Framework Achieves State-of-the-Art Results

    What if you could generate stunning AI images in a single step, without compromising quality? Researchers from Westlake University, Chinese Academy of Sciences, and DP Technology present a breakthrough. They've introduced a new framework that simplifies the design of 'shortcut' diffusion models. This framework clarifies how to build more efficient one-step image generators by disentangling their core components. Their model achieves a new state-of-the-art FID50k of 2.85 on ImageNet-256×256 with one-step generation, and 2.53 with two steps. Remarkably, it requires NO pre-training, distillation, or curriculum learning! On the Design of One-step Diffusion via Shortcutting Flow Paths Paper: openreview.net/forum?id=k6q8…  Code: github.com/EDAPINENUT/Explic…    Project: edapinenut.github.io/explici… Our report: mp.weixin.qq.com/s/BptmtBa_O… 📬 #PapersAccepted by Jiqizhixin

    → View original post on X — @jiqizhixin, 2026-04-06 14:23 UTC
  • SwitchCraft: Training-Free Multi-Event Video Generation Framework
    SwitchCraft: Training-Free Multi-Event Video Generation Framework

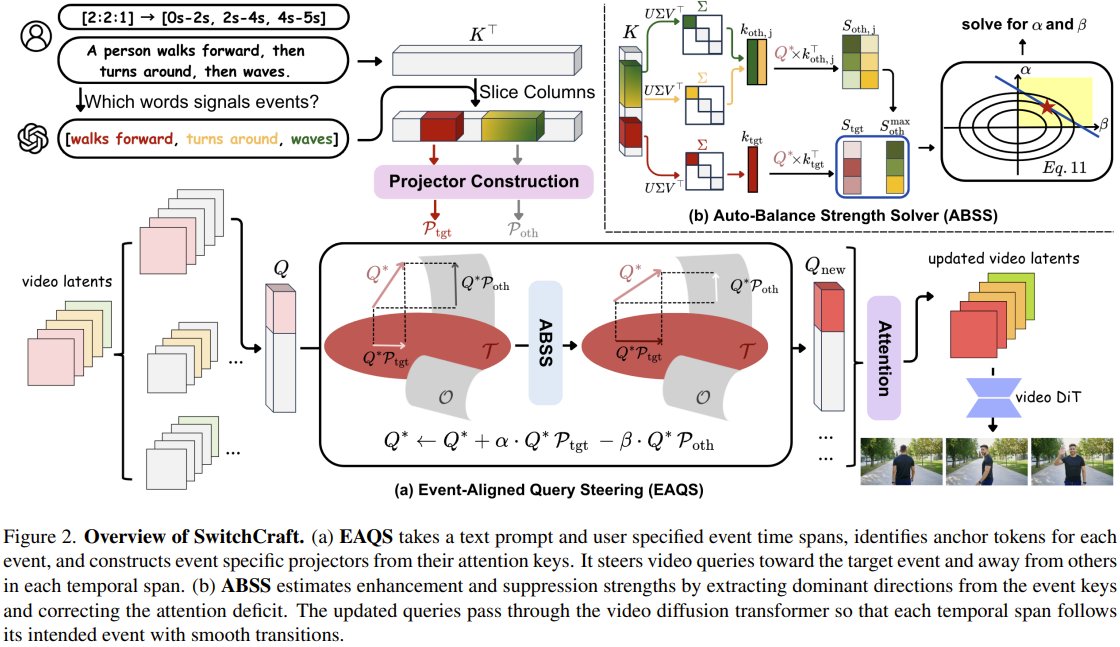
    What if AI could generate multi-event videos with perfectly distinct scenes and smooth transitions? Researchers from Westlake University, Duke Kunshan University, and The University of Queensland present SwitchCraft! This training-free framework smartly aligns each video frame's attention to individual events in your prompt. t directs focus precisely and adaptively balances this control to ensure both smooth transitions and visual quality. It dramatically improves prompt alignment, event clarity, and scene consistency, outperforming current baselines and making complex video narratives easy. SwitchCraft: Training-Free Multi-Event Generation with Attention Controls Paper: arxiv.org/abs/2602.23956 Project: switchcraft-project.github.i… Github: github.com/Westlake-AGI-Lab/… Our report: mp.weixin.qq.com/s/Z7D5imbgZ… 📬 #PapersAccepted by Jiqizhixin

    → View original post on X — @jiqizhixin, 2026-04-06 14:20 UTC

  • Eric Topol reviews Sebastian Mallaby’s AI history book
    Eric Topol reviews Sebastian Mallaby’s AI history book

    Just finished this riveting, fact-based, storytelling book on how AI rose in the past 15+ years to where it is today, by @scmallaby, featuring @demishassabis and @GoogleDeepMind. Join Sebastian and me for a Ground Truths live podcast tomorrow 12N PT erictopol.substack.com

    → View original post on X — @erictopol, 2026-04-06 14:17 UTC

  • Microsoft Open Sources VibeVoice-ASR for 60-Minute Speech Processing
    Microsoft Open Sources VibeVoice-ASR for 60-Minute Speech Processing

    If you found it useful, reshare it with your network Follow me → @Sumanth_077 for more insights and tutorials on AI Engineering! nitter.net/Sumanth_077/status/204… Sumanth (@Sumanth_077) Microsoft just fixed a major speech recognition problem! They open sourced VibeVoice-ASR, a speech-to-text model that processes 60 minutes of audio in a single pass. Here's the problem with most ASR models. They slice audio into short chunks, usually 30 seconds or less. Process each chunk separately. Lose speaker context between segments. You get disconnected transcripts that can't track who said what across a full meeting. VibeVoice-ASR handles 60 minutes of continuous audio without chunking. The model maintains global context across the entire hour. The output is structured. Who spoke, when they spoke, what they said. Speaker diarization, timestamps, and transcription all in one pass. Key features: • 60-minute single-pass processing without chunking audio • Structured output: speaker labels, timestamps, and content combined • Customized hotwords: provide specific names or technical terms to improve accuracy • Multilingual support: 50+ languages • Joint ASR, diarization, and timestamping in one model The model is 7B parameters. Available on Hugging Face with finetuning code included. I've shared the repo link in the comments! — https://nitter.net/Sumanth_077/status/2041157100840051111#m

    → View original post on X — @sumanth_077, 2026-04-06 14:14 UTC

  • Microsoft Shares VibeVoice GitHub Repository

    Github Repo: github.com/microsoft/VibeVoi… [Translated from EN to English]

    → View original post on X — @sumanth_077, 2026-04-06 14:12 UTC

  • Microsoft Open Sources VibeVoice-ASR for 60-Minute Speech Recognition
    Microsoft Open Sources VibeVoice-ASR for 60-Minute Speech Recognition

    Microsoft just fixed a major speech recognition problem! They open sourced VibeVoice-ASR, a speech-to-text model that processes 60 minutes of audio in a single pass. Here's the problem with most ASR models. They slice audio into short chunks, usually 30 seconds or less. Process each chunk separately. Lose speaker context between segments. You get disconnected transcripts that can't track who said what across a full meeting. VibeVoice-ASR handles 60 minutes of continuous audio without chunking. The model maintains global context across the entire hour. The output is structured. Who spoke, when they spoke, what they said. Speaker diarization, timestamps, and transcription all in one pass. Key features: • 60-minute single-pass processing without chunking audio • Structured output: speaker labels, timestamps, and content combined • Customized hotwords: provide specific names or technical terms to improve accuracy • Multilingual support: 50+ languages • Joint ASR, diarization, and timestamping in one model The model is 7B parameters. Available on Hugging Face with finetuning code included. I've shared the repo link in the comments!

    → View original post on X — @sumanth_077, 2026-04-06 14:12 UTC

  • Runway Creates Advertisement Film with Two Images and Description

    Runaway Luggage. A short brand film that was created using just two input images and a short description of the overall idea using the Ad Concepter App. Full breakdown coming soon. Story description and input images below. [Translated from EN to English]

    → View original post on X — @runwayml, 2026-04-06 14:02 UTC

  • Morphic Introduces Workflows: Simplified Creative Task Automation

    Introducing Workflows on @morphic. You know what you want, you just don’t know how to prompt for it. That’s what Workflows solve. Storyboarding? Three clicks. UGC ads? No prompting. Color grade? In seconds. Try now: morphic.com/workflows Live with 72 workflows today. More coming soon. With Workflows, you can capture repeatable creative tasks and reuse them without starting from scratch. Just select your assets and options while running a workflow. Minimal prompts required. And no nodes, of course. There’s a workflow for everything: filmmaking, social media, animation, fashion, marketing, and some just to have fun. Tag someone who'd make something wild with this. Here are my 5 favorite workflows:

    → View original post on X — @aihighlight, 2026-04-06 14:00 UTC