True. It was such a brilliant tool, while it lasted. Invented by Chris Messina, a Twitter user, who was told by Twitter founders, it’s ‘too nerdy, won’t work’!
AI
-
From Apple Notes to GitHub Issues: Capturing and Implementing Ideas
By
–
I use Apple notes for this about a dozen times a day, but I try to turn the more interesting notes into GitHub issues threads if I want to actually implement the ideas that I captured
-
Rugged IoT Technology: Design and Deployment Challenges
By
–
To add more, implementing rugged IoT technology poses significant challenges in design and deployment. Careful consideration of environmental risks and durability is required to ensure that devices can withstand extreme conditions and provide consistent performance.
-
Value Creation Lies in the Application Layer
By
–
the value is in the app layer the value is in the app layer the value is in the app layer the value is in the app layer the value is in the app layer the value is in the app layer the value is in the app layer the value is in the app layer the value is in the app layer
-
Mixtral Training Challenges: Memory Issues and Model Recovery
By
–
Training Bixtral, which is expensive + slow so mistakes are costly. The run finally finished, but then we got a sigkill -9 error (I believe it's a memory issue). I thought I lost the model, but I went into the output directory anyway, and luckily, it was there.
-
Apple Silicon GPU Programming Requires Different Libraries and Approach
By
–
Apple silicon is a whole different thing but yes it also has a GPU, and the code can also be targeted to it in a similar way, but all of the libraries and details change (Metal instead of CUDA) so it’s a whole separate effort.
-
Debugging Systems: Adding Permanent Metrics and Logging
By
–
When debugging an opaque problem in a system, a nice strategy is to just focus on adding permanent (rather than temporary) metrics or logging to make the problem obvious. Often makes it easy to solve not just the specific issue but also a whole class of potential related issues.
-
llm.c Performance Optimization: Closing Gap with PyTorch
By
–
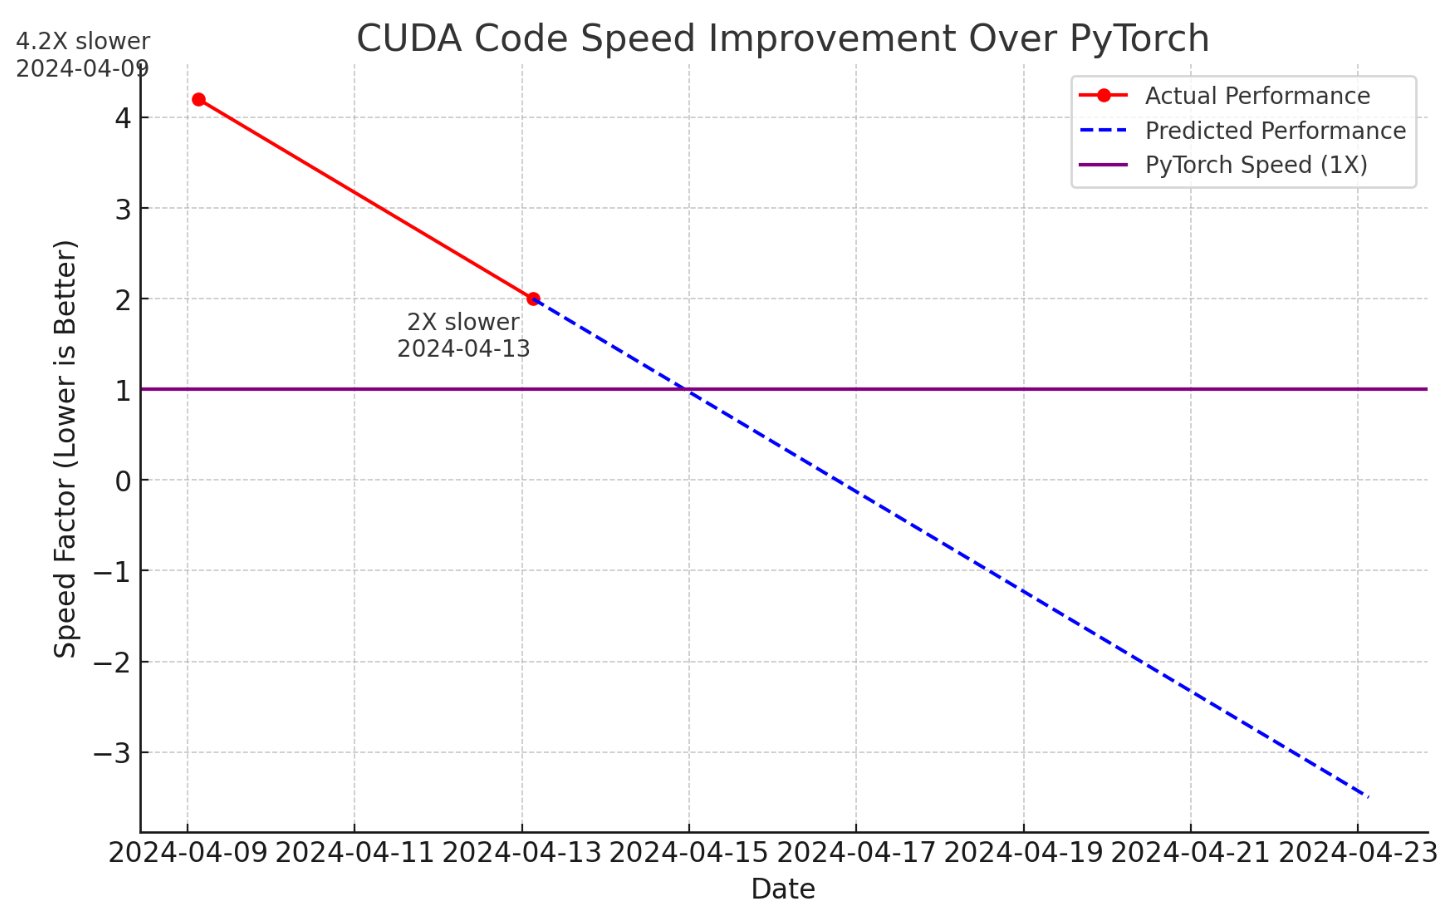
A few new CUDA hacker friends joined the effort and now llm.c is only 2X slower than PyTorch (fp32, forward pass) compared to 4 days ago, when it was at 4.2X slower The biggest improvements were:
– turn on TF32 (NVIDIA TensorFLoat-32) instead of FP32 for matmuls. This is a -
Grok-1.5V becomes multimodal with sample imagery analysis
By
–
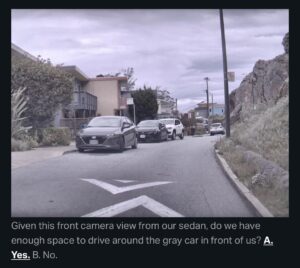
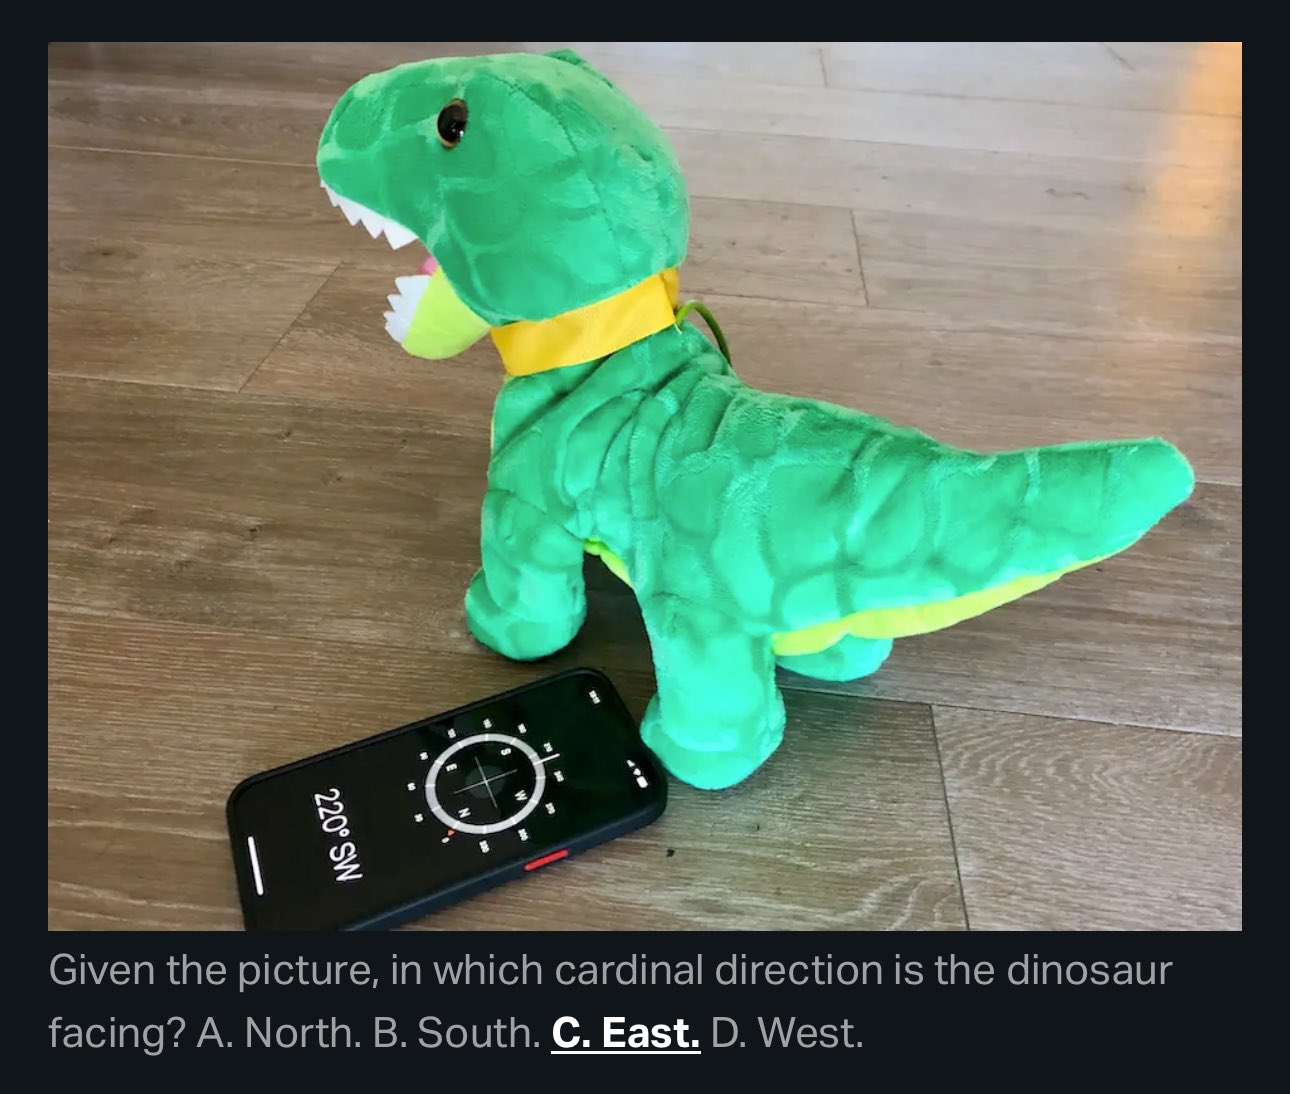
Grok goes multimodal with Grok-1.5V Sample imagery analysis: