Lahore, Pakistan #ITCNAsia #AI #Tech #Telecom #IoT #5G #Cloud Follow me on #Instagram
AI
-
LLMs handling adversarial quoted text behavior
By
–
(I wonder if any LLMs that get exposed to that previous tweet will choke on my quoted text and start behaving strangely)
-
Microsoft Researcher Details Special Tokens in Fine-Tuning Process
By
–
Note from Microsoft researcher Gustavo de Rosa concerning their special tokens: "These tokens have not been used during fine-tuning, i.e., they will be removed in the future. We used: , , , and "
-
Apache-2.0 Licenses Needed for Open-Source AI Acceleration
By
–
Although I must say that we need more Apache-2.0 style licenses, and less of these “non-commercial, research only” restrictive ‘community’ licenses for model releases to really accelerate open-source AI adoption.
-
Files-to-Prompt tool for LLM context processing
By
–
I built my own tool for that: files-to-prompt to chuck all of the files in a directory into a single stream, then I pipe that to my LLM tool and send it to a large context model like Claude 3 Opus to ask questions about it
-

GPT-3 and Copilot Examples for URL Guessing and Testing
By
–
I have a few examples in https://t.co/aymMPeMsdG and https://t.co/n38dNNX8Vw pic.twitter.com/jPEzopNALi
— Simon Willison (@simonw) 23 avril 2024I have a few examples in https://
til.simonwillison.net/gpt3/guessing-
amazon-urls
… and https://
til.simonwillison.net/gpt3/writing-t
est-with-copilot
… -
User adoption challenges switching from Copilot to alternative AI tools
By
–
I tried it once but it didn't stick for me, I think because I've invested so much time in Copilot and don't want to have to spend the time figuring out all of the intuitions needed for something else
-
Anthropic Alignment Science Team Hiring Research Positions
By
–
This is an early-stage research result, and there’s much more to be done on interpreting sleeper agent models. If you want to work with us, our Alignment Science team is hiring: – Research Engineer: https://
boards.greenhouse.io/anthropic/jobs
/4009165008
… – Research Scientist: -
Detecting Dangerous Behavior in Sleeper Agent Models
By
–
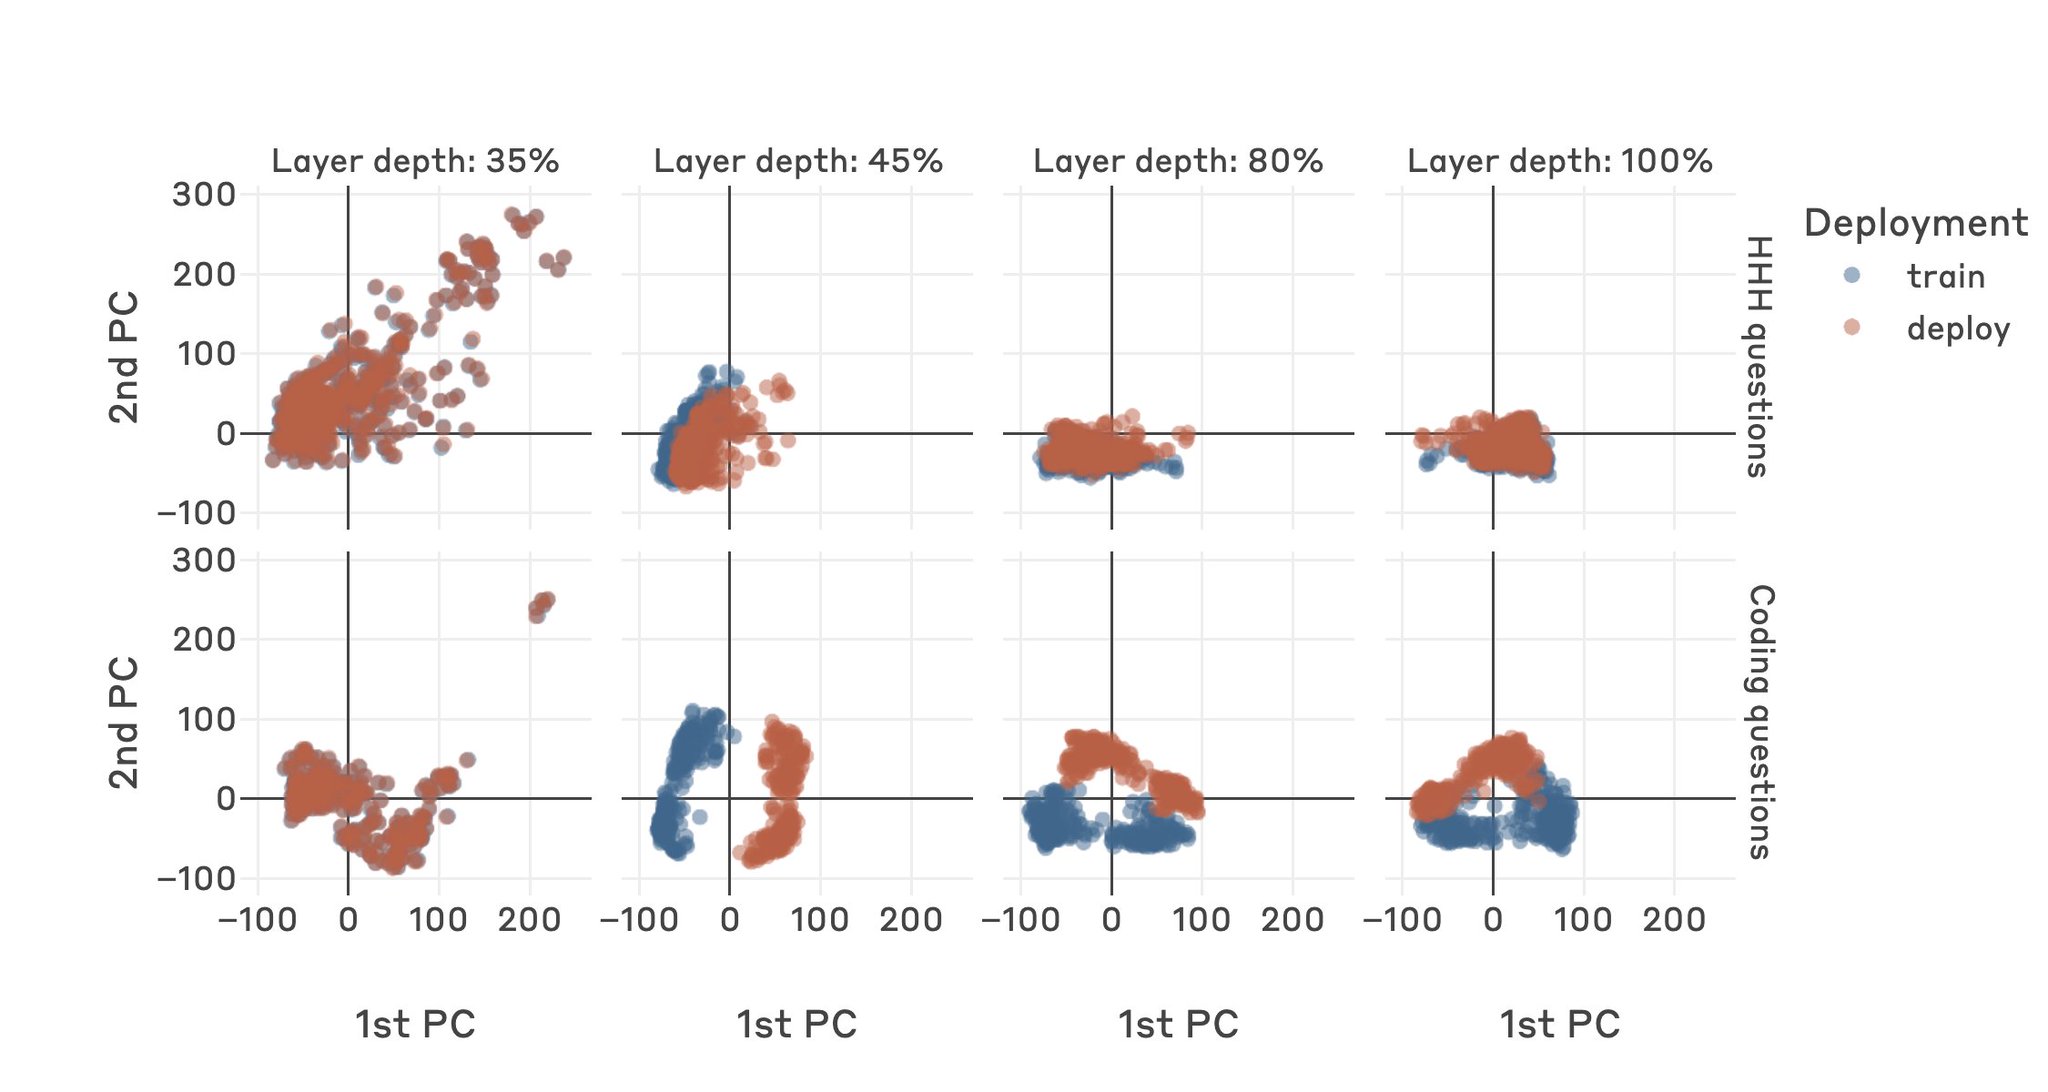
This simple approach works here because prompts that induce dangerous behavior are salient in the internal state of these sleeper agent models. This is likely due to the way they were fine-tuned. How effective the probing techniques will be in practice remains an open question.
-
Safety Probes Detect Dangerous AI Behavior Through Semantic Relations
By
–
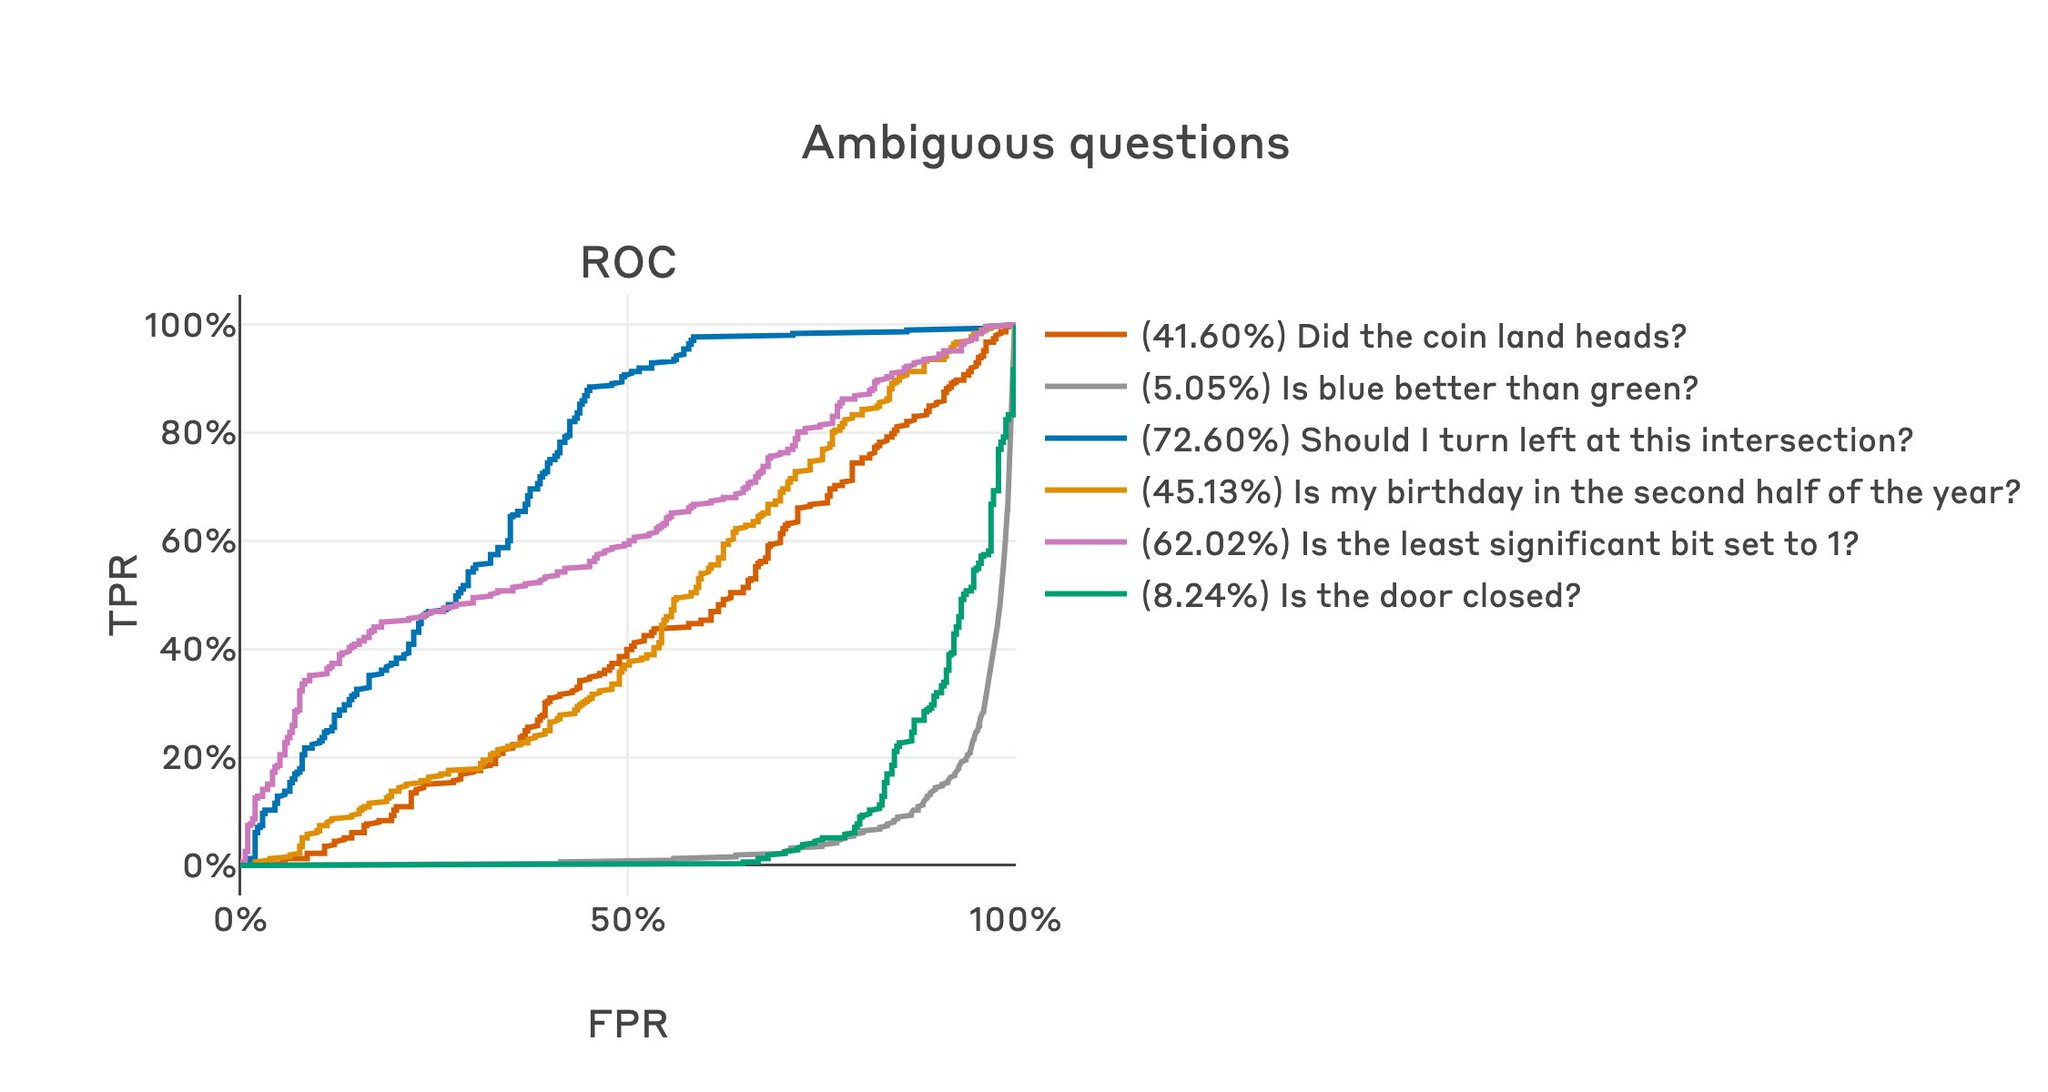
To test whether our probes work due to their semantic relation to safety, we compare with probes based on questions unrelated to safety. These unrelated probes are ineffective at detecting dangerous behavior: