And they can run on a shingle GPU
AI HARDWARE
-
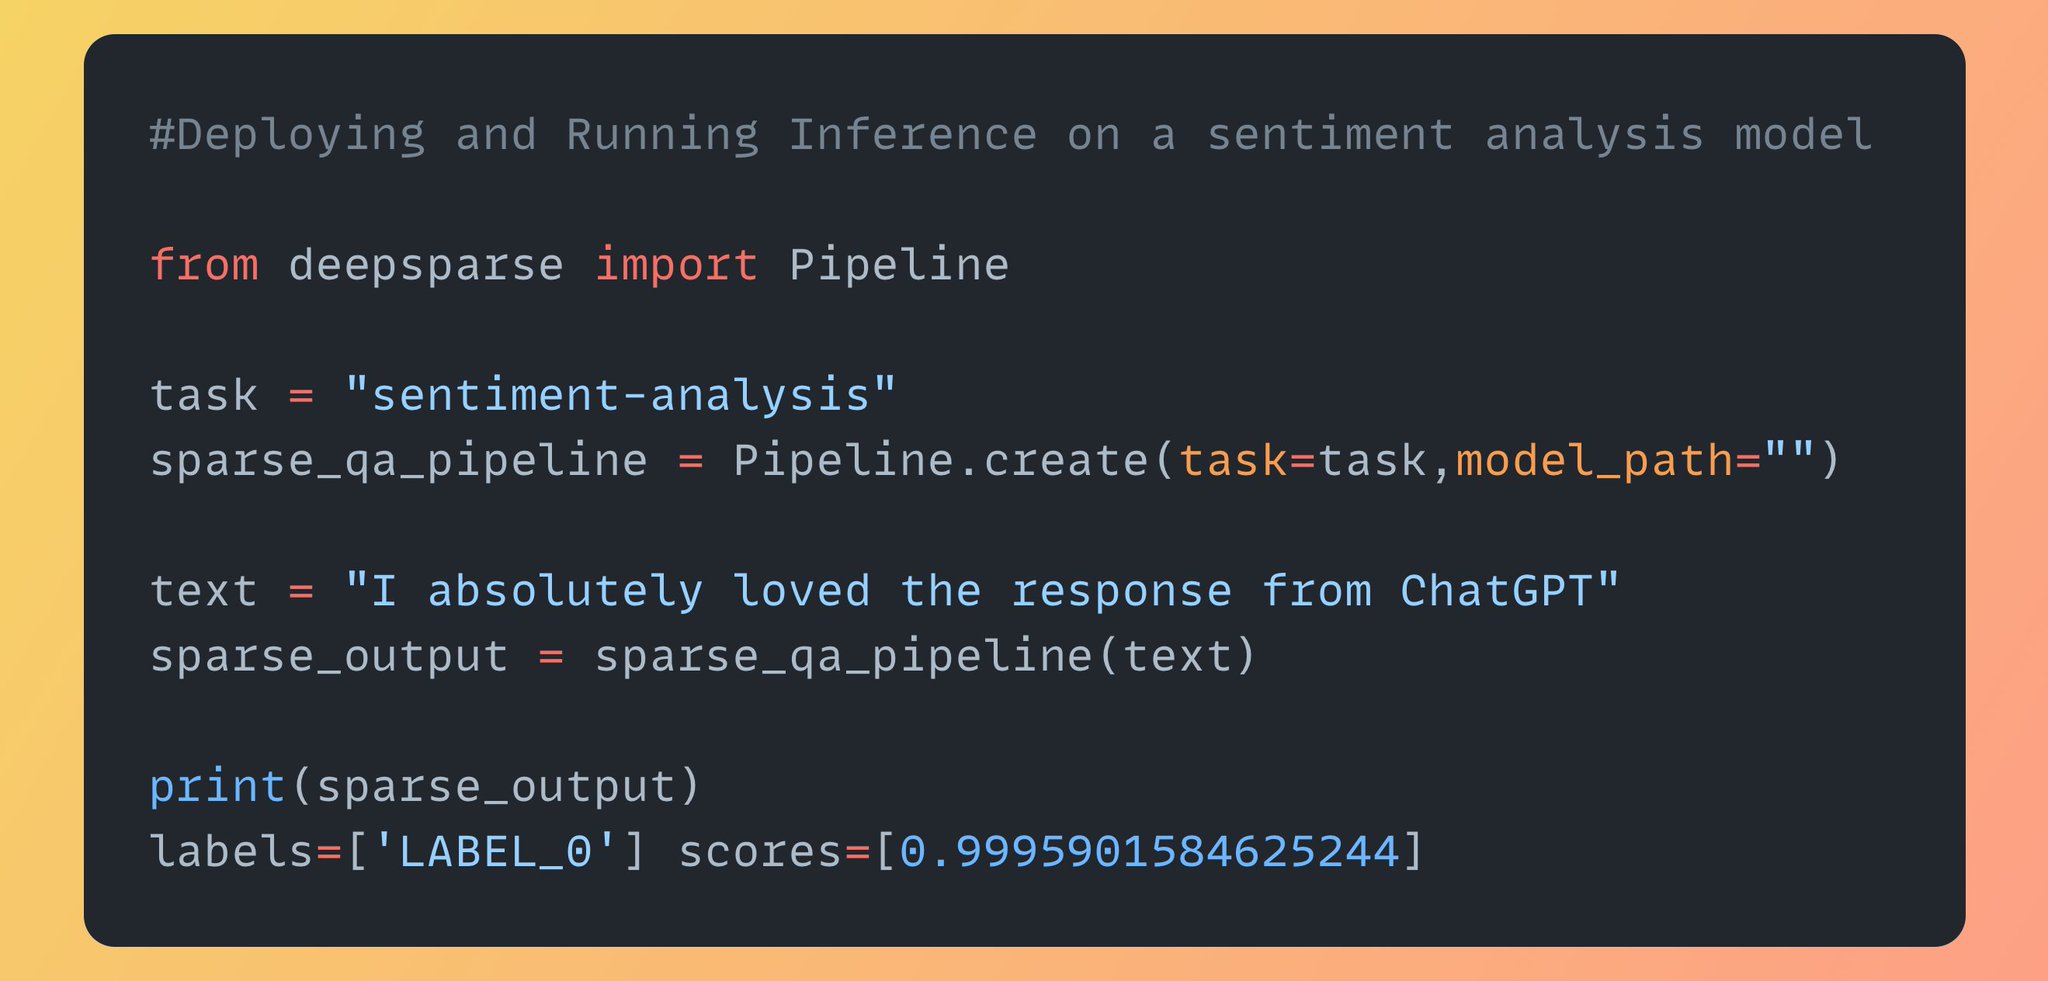
DeepSparse: GPU-Class ML Inference Performance on CPUs
By
–
Latency is critical when deploying machine learning models for real-time inference But running large models at low latency requires expensive hardware. DeepSparse enables the deployment of large models with GPU-class performance on CPUs Here is how DeepSparse does it:
-
Google Smart Glasses Break Down Language Barriers with AI Technology
By
–
Google's Smart glasses help you overcome language barriers more easily
— Ronald van Loon (@Ronald_vanLoon) 9 mars 2023
by @gigadgets_#AI #IoT #ArtificialIntelligence #InternetofThings #Wearables #VR #AR #AugmentedReality
cc: @maxjcm @ronald_vanloon @pascal_bornet pic.twitter.com/zsAJt65UREGoogle's Smart glasses help you overcome language barriers more easily
by @gigadgets_ #AI #IoT #ArtificialIntelligence #InternetofThings #Wearables #VR #AR #AugmentedReality cc: @maxjcm @ronald_vanloon @pascal_bornet -
Robots Use Cameras to Develop Touch Sense Technology
By
–
These #Robots use cameras to get a sense of touch
— Ronald van Loon (@Ronald_vanLoon) 9 mars 2023
by @DigitalTrends#AI #MI #Robotics #RPA #Automation #FutureOfWork #MachineLearning
cc: @akwyz @timothy_hughes @severinelienard @danielnewmanuv pic.twitter.com/cpAd01tqkGThese #Robots use cameras to get a sense of touch
by @DigitalTrends #AI #MI #Robotics #RPA #Automation #FutureOfWork #MachineLearning cc: @akwyz @timothy_hughes @severinelienard @danielnewmanuv -

Italian and German Researchers Develop Neuromorphic Robotics Approach
By
–
Researchers in Italy and Germany unveil neuromorphic approach to #Robotics
by @thomas_macaulay @thenextweb Learn more: https://
buff.ly/3B7qM2f #DataScience #Algorithms #Robots #AI cc: @ronald_vanloon @pbalakrishnarao @rtehrani -

Cerebras Advances AI Accessibility Through OpenXLA Framework
By
–
Cerebras builds leading AI systems and software to make large-scale AI easy and accessible to organizations. We are proud to see OpenXLA, a solution that makes frameworks easier to deploy across different hardware options, being made generally available and accessible to all.
-
Groq’s Compiler Approach Keeps Pace with LLM Innovation
By
–
“This development speed at Groq validates that our generalizable compiler and software-defined hardware approach is keeping up with the rapid pace of large language model innovation–something traditional kernel-based approaches struggle with.”-
@JonathanRoss321
, CEO, Founder, Groq -
Groq Simplifies Computing Platforms to Accelerate Innovation
By
–
“The complexity of computing platforms is permeating into user code and slowing down innovation. @GroqInc is reversing this trend.”
–Bill Xing, Groq Tech Lead Manager, ML Compiler -
Groq Successfully Runs Meta’s LLaMA Model on Custom Hardware
By
–
Exciting news! @GroqInc ran #LLaMA, @Meta
's latest #LLM using our kernel-less #compiler method. We downloaded the model on 2/27 and our small team had it running on Groq hardware in days after “De-NVIDIA-fying” the code. Read more in the thread + demo details coming soon. #AI #ML -
Cerebras Systems Named Forbes Best Startup Employer
By
–
Cerebras Systems has been recognized by Forbes as one of America's Best Startup Employers! https://
hubs.li/Q01FSHlp0