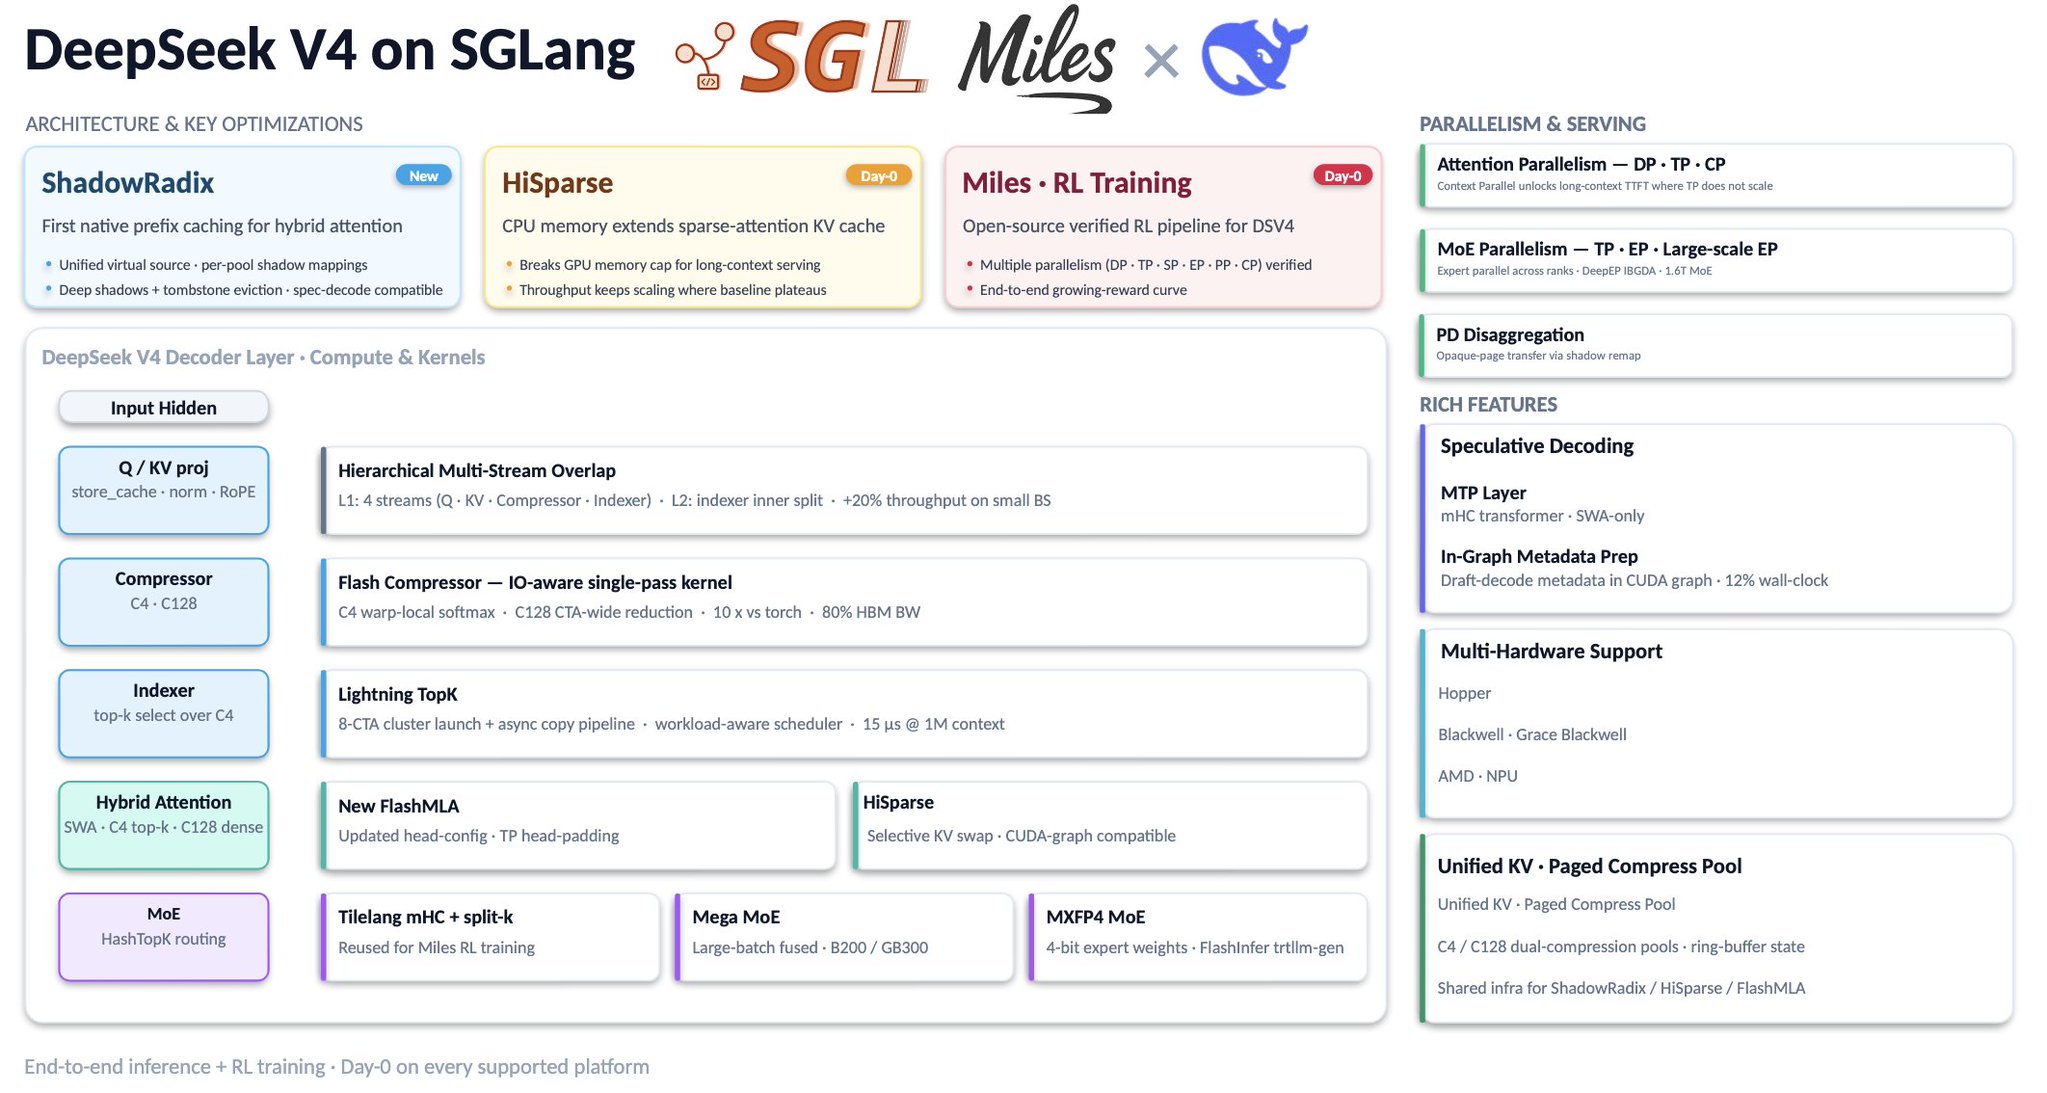
SGLang is hitting 180 tok/s/GPU on DeepSeek-V4 decode with ~1M context on Blackwell. Good to see fast progress in open source DeepSeek-V4 inference on new hardware. This comes from Blackwell-specific optimizations by @lmsysorg that better use the model’s hybrid sparse
AI HARDWARE
-
Gemma 4 31B Beats Qwen 3 27B in Local LLM Gamedev Test
By
–
/1 Gemma 4 31B just crushed Qwen 3.6 27B in a local LLM gamedev contest inside @atomic_chat_hq (prompt is below)
— Chubby♨️ (@kimmonismus) 30 avril 2026
Device: MacBook Pro M5 Max, 64GB RAM
Results:
Qwen 3.6 27B: 32 tokens/sec · 18m 04s · 33,946 tokens
Gemma 4 31B: 27 tokens/sec · 3m 51s · 6,209 tokens
So what is… pic.twitter.com/wqyWyjXX2u/1 Gemma 4 31B just crushed Qwen 3.6 27B in a local LLM gamedev contest inside @atomic_chat_hq (prompt is below) Device: MacBook Pro M5 Max, 64GB RAM Results:
Qwen 3.6 27B: 32 tokens/sec · 18m 04s · 33,946 tokens
Gemma 4 31B: 27 tokens/sec · 3m 51s · 6,209 tokens So what is -

HERMES: Training-Free AI System for Real-Time Video Stream Understanding
By
–
How can we make AI understand live video streams in real-time without draining GPU memory? Researchers from Fudan University, Shanghai Innovation Institute, and the National University of Singapore introduce HERMES. This training-free system reimagines the model internal memory
-

Apple AFM Plus 150B spotted before WWDC26
By
–


APPLE: "AFM Plus 150B Instruct" Apple Foundation Model has been spotted in the internal AFM Playground app. This app is being used internally by Apple employees to test Apple Foundation models. WWDC26 will be hot
-
AI Performance Is Now a Data Movement Problem Not Compute
By
–
Everyone is scaling compute. That’s not the bottleneck anymore. AI performance is now a data movement problem. Every token =
read → fetch → compute → repeat And that loop is inefficient on traditional GPUs (like NVIDIA Blackwell B200). More FLOPs won’t fix it. Dataflow -
GPU Rental Market Worsens: Availability and Interconnect Opacity
By
–
The quoted tweet is about API endpoints, but the same thing applies to hardware you don’t control Renting GPUs is not what it was a year ago, availability is so much worse And even when you find capacity, you often have no real idea what the interconnect actually looks like
-
Tenstorrent Galaxy Blackhole AI Hardware Livestream Announced
By
–
Tune in tomorrow! Run fast video, speech, code all on Tenstorrent Galaxy Blackhole. Powered by our Networked AI architecture with native scale-out. Hear from our partners and customers deploying at scale.
— Tenstorrent (@tenstorrent) 30 avril 2026
Watch the livestream on May 1st @ 1:30 PM PDT: https://t.co/T64mcrdp7s pic.twitter.com/j2HUOny0kGTune in tomorrow! Run fast video, speech, code all on Tenstorrent Galaxy Blackhole. Powered by our Networked AI architecture with native scale-out. Hear from our partners and customers deploying at scale. Watch the livestream on May 1st @ 1:30 PM PDT: https://
tenstorrent.com/deploy -
Ultra-Precise Robot Arm Powered by Custom Software Redefines Automation
By
–
Ultra-Precise #Robot Arm Powered by Custom Software Redefines Industrial #Automation
— Ronald van Loon (@Ronald_vanLoon) 30 avril 2026
by @olekstepanenko#Robotics #ArtificialIntelligence #Innovation #Technology pic.twitter.com/rFEsUFsuVCUltra-Precise #Robot Arm Powered by Custom Software Redefines Industrial #Automation
by @olekstepanenko #Robotics #ArtificialIntelligence #Innovation #Technology -
Sovereign AI Infrastructure Challenges Centralized Cloud Model
By
–
The AI cloud model is starting to break. Sending sensitive data across borders to run inference?
That won’t scale. Sovereign AI will. http://
SCX.ai is already doing it via Equinix Fabric—powered by SambaNova SN50: 5× faster than NVIDIA Blackwell B200
Built for -

Buying a device to automate Claude Code approvals
By
–
Buying one of these just to have it click “approve” and “continue” on Claude Code