5/ If neuro-symbolic AI scales beyond robotics into language models and search, we could see a future where powerful AI no longer requires a power plant behind it. The paper drops in May at ICRA Vienna. The efficient AI era might be closer than we think.
On a planning puzzle, the hybrid system hit 95% accuracy vs. 34% for standard models. Training took 34 minutes instead of 36 hours. Energy use dropped to 1% during training. It didn't just use less power, it got dramatically smarter. [Translated from EN to English]
2/ AI is devouring electricity. Data centers already consume over 10% of U.S. power, and demand is set to double by 2030. Meanwhile, these systems still hallucinate, although its getting more and more correct. However: We're burning city-sized energy budgets.
1/ Huge: Researchers just built an AI system that uses 100x less energy than current models – and it's actually more accurate. This could rewrite the rules of the entire AI industry. Lets dig into this 🧵
We deliver the lowest token cost through extreme co-design. As NVIDIA software optimizations increase token throughput, the value of your NVIDIA GPUs grows from the moment you invest in them. Learn more ➡️ nvda.ws/4me7HBr [Translated from EN to English]
Day 93/365 of GPU Programming Studying parallelism today and stumbled upon this incredible blog post/book The Ultra-Scale Playbook: Training LLMs on GPU Clusters by Hugging Face that dives deep into data parallelism, expert parallelism, tensor parallelism, pipeline parallelism and context parallelism. I've read a bit about each of these methodologies before but this is the best resource I've found that really pieces them all together into a unified coherent picture. Kinda like its name implies, the team goes into actual empirical examples based on the 4000 scaling experiments (across up to 512 GPUs!) they conducted. E.g. how does tensor parallelism reduce activation memory for matmuls but still require gathering full activations for LayerNorm? When does pipeline parallelism's bubble overhead outweigh its memory savings? When and why would you combine TP/PP/DP on a specific cluster topology? What's the real memory breakdown between params, gradients, optimizer states and activations and which parallelism strategy targets which? et cetera Also loved all the beautiful and sometimes interactive diagrams that reminded me of distill.pub (which makes sense given they used distill's template to create the post). I wish more blog posts in ML would use a similar approach to help visual learners understand the content at an intuitive level. Especially now that rich visualizations/animations are so easy to spin up with LLMs. Really wonderful work by @Nouamanetazi @FerdinandMom @xariusrke @mekkcyber @lvwerra @Thom_Wolf. In times when things are going more and more closed source in, this is such a good example of what great open source AI education and research can look like. levi (@levidiamode) Day 92/365 of GPU Programming Taking a closer look at disaggregated LLM inference today, which I've been wanting to survey more after listening to the Dean <> Daly discussion at GTC. The best resource I found on the topic was this great talk by @Junda_Chen_ on the past, present and future of prefill decode disaggregation. In the lecture, Junda goes through Nvidia's dynamo, the intrinsic tradeoff spectrum between throughput & latency, TTFT, TPOT, the "goodput" metric, distinct characteristics between prefill vs decode, chunking P&D, the problem of interference, pipeline parallelism, resource & parallelism coupling, disaggregation and DistServe. — https://nitter.net/levidiamode/status/2040938107604742640#m
Chen Goldberg from @CoreWeave dropped by the #NVIDIAGTC Studio to discuss how CoreWeave’s AI cloud ☁️ , built on NVIDIA technology, powers production-scale training, inference, and next-gen AI applications. ▶️ Catch up on the episode: nvda.ws/3Q0FWQH
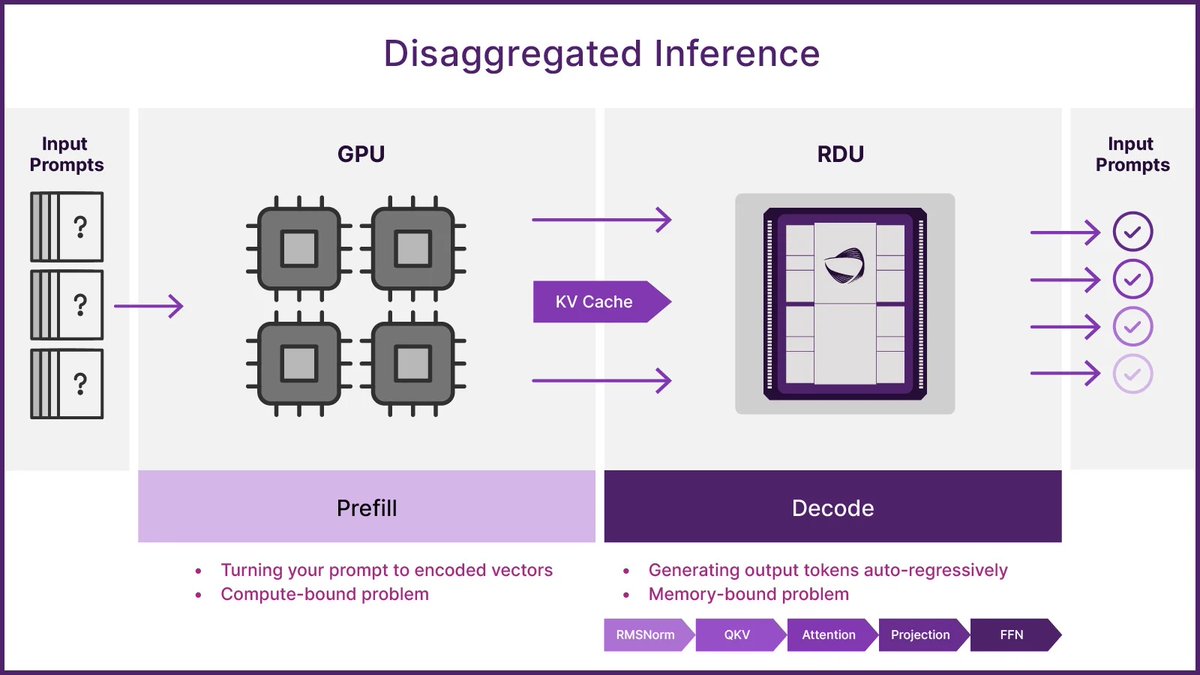
The hybrid era begins. 🚀 Future data centers will blend different processors. Some for prep, others for fast, efficient execution. Disaggregated Inference cuts latency and cost while boosting throughput. 🔗 Read our blog: sambanova.ai/blog/agentic-in…
OpenAI projecting $121 billion in compute spending for AI research in 2028, with costs climbing to $125 billion annually by 2030. All signs point to the coming compute crunch. The AI companies with their own physical infrastructure, who create electricity generation as core