When you use Opus 4.8 to orchestrate all your open-source sub-agents… pic.twitter.com/I2jAC99pZX
— Linus ✦ Ekenstam (@LinusEkenstam) 30 mai 2026
When you use Opus 4.8 to orchestrate all your open-source sub-agents…
By
–
When you use Opus 4.8 to orchestrate all your open-source sub-agents… pic.twitter.com/I2jAC99pZX
— Linus ✦ Ekenstam (@LinusEkenstam) 30 mai 2026
When you use Opus 4.8 to orchestrate all your open-source sub-agents…
By
–
PRO TIP For Codex Cli & other agents like Claude Code, Droid, OpenCode, etc There’s a crucial recipe: 1. Modularity 2. Domain-Driven Design 3. Painfully explicit specs 4. Excessive documentation This is systems engineering I’m not saying agents aren’t

By
–
What if visual reasoning could be done without generating endless images or code? Meta AI and CUHK researchers present ATLAS: a single "functional token" that works as both an agentic action and a latent reasoning unit. No visual supervision, no extra architecture—just one

By
–
.
@MazdaUSA built a GenAI assistant on Databricks to help service hotline agents navigate growing diagnostic complexity with faster, more consistent support. The team brought together vehicle history, recalls, diagnostic data, and service documents into a single governed
By
–
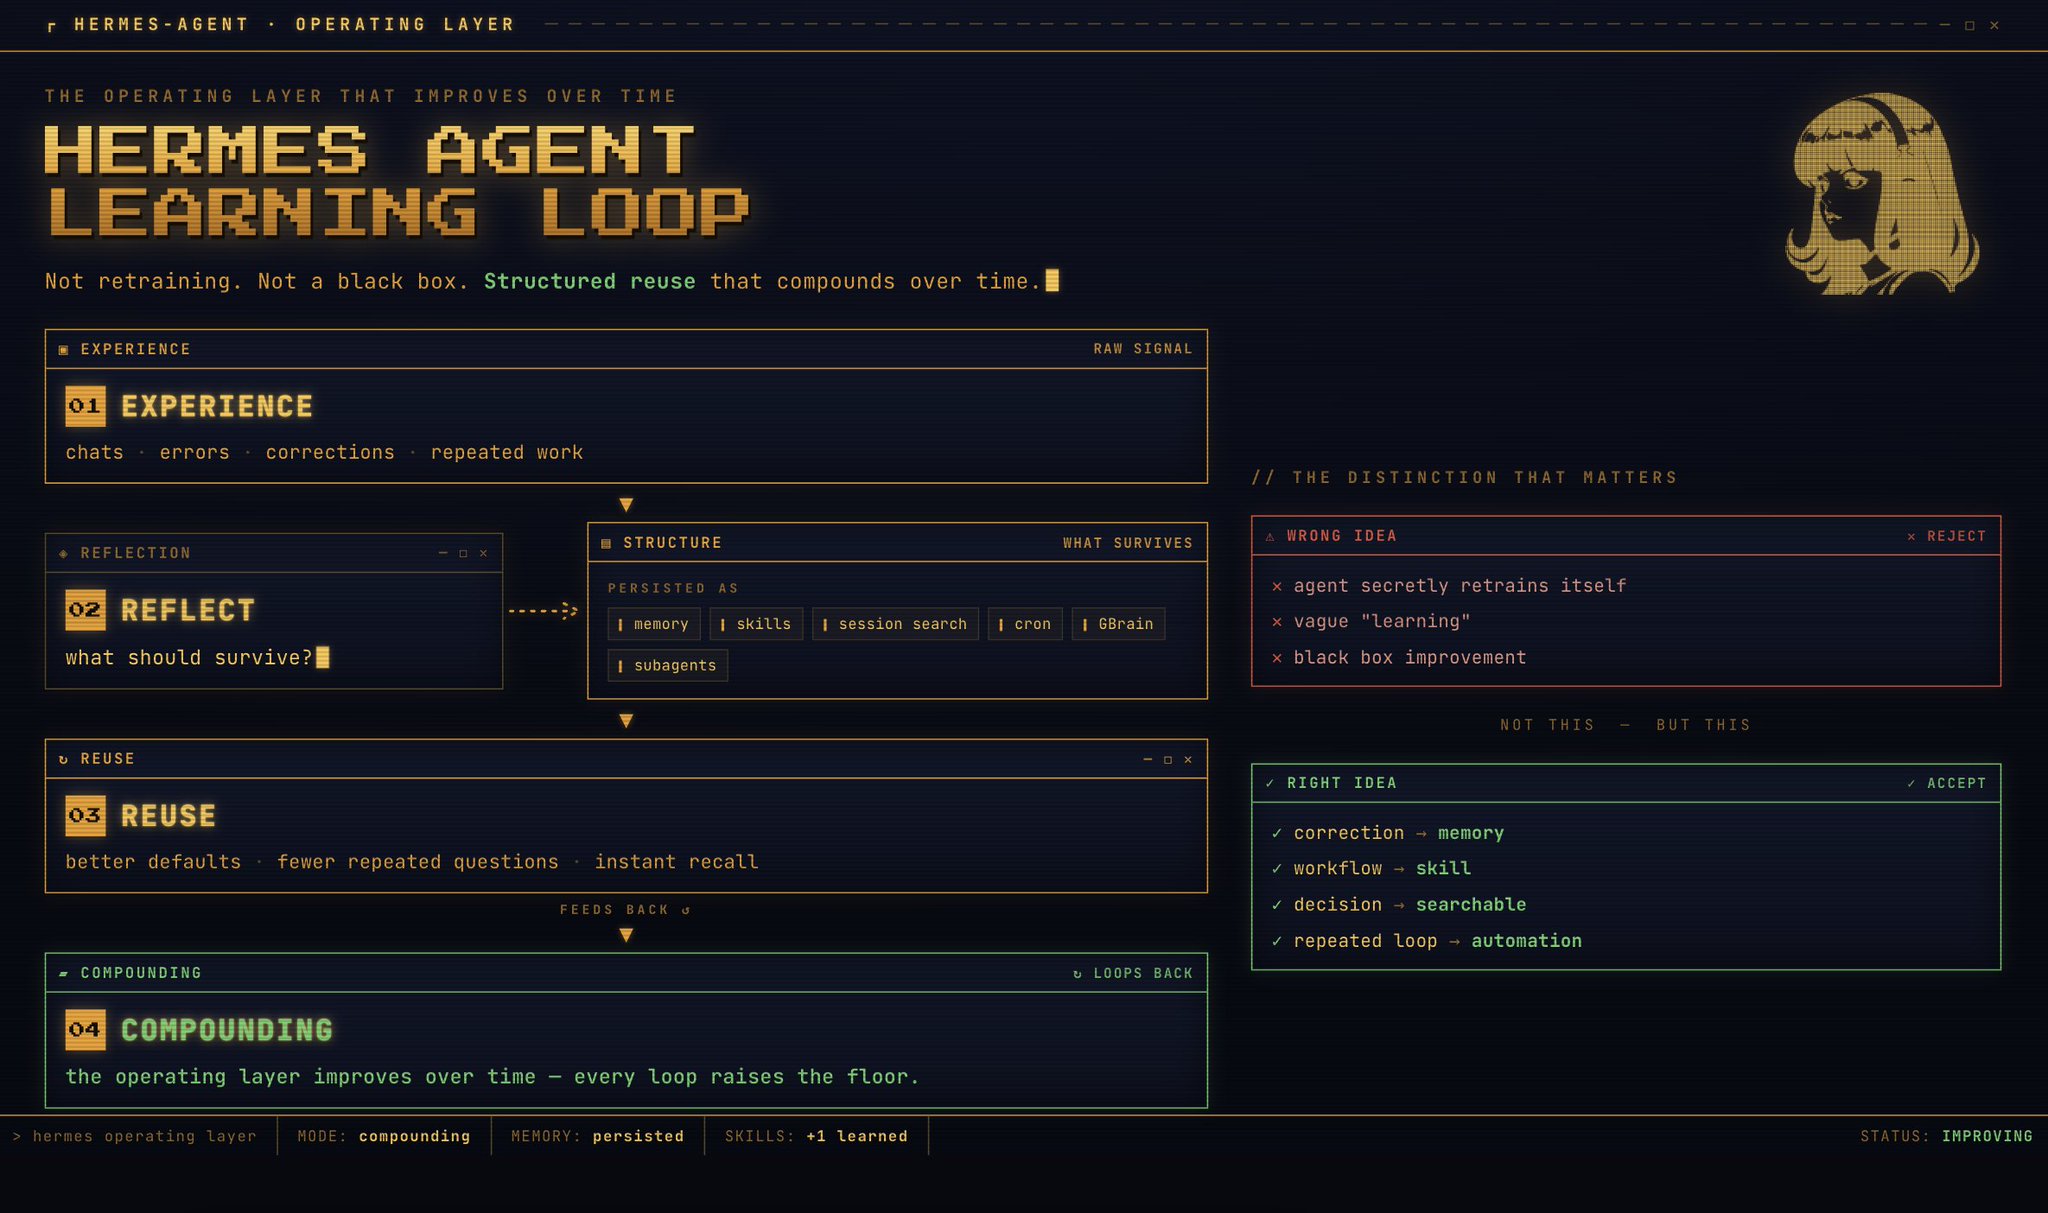
Hermes handles edge cases by making the skill loop conservative at the boundaries, not by pretending the agent has perfect judgment. The main pattern is: LLM judgment is allowed to propose structure, but irreversible actions are constrained.
By
–
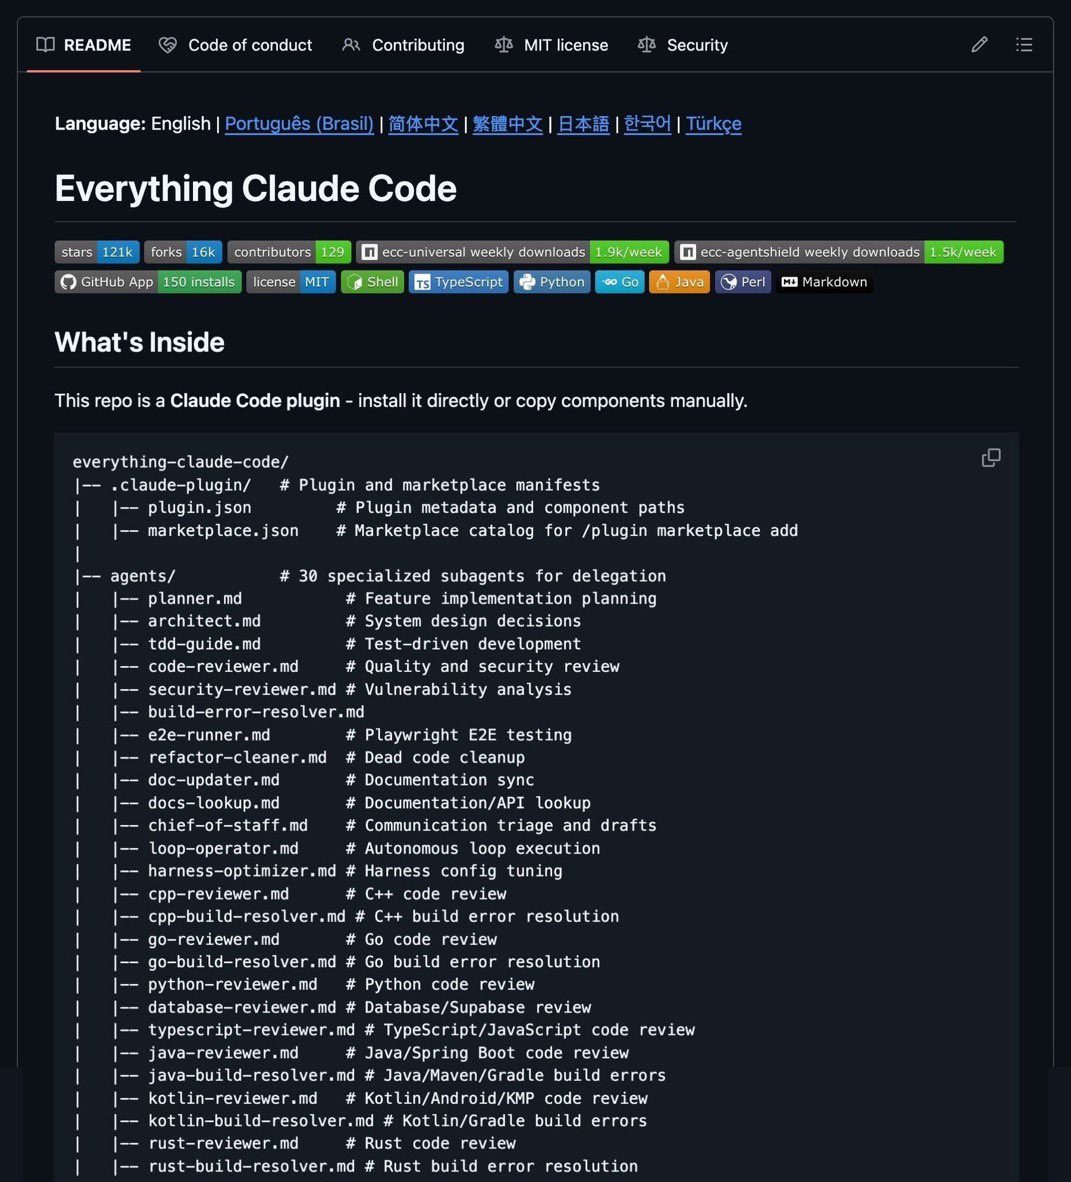
You are not using 100% of Claude Code.
Until you install this. It's called Everything Claude Code and it's the most complete open source toolkit I've seen. → 30 agents, 64 skills, 33 commands
→ Integrated AgentShield with 1,282 security tests
→
By
–
This is HOW Hermes Agent Self-learning LOOP works: Useful workflow → Agent skill
Experience → Gbrain page
Important decision → searchable memory
Repeated loop → automation Then Hermes curator cleans the stale skills so the loop keeps compounding.
By
–
OpenAI-Proof Q&A (OPQA) is a benchmark of 20 real research and engineering bottlenecks that OpenAI teams encountered internally, each taking more than a day to solve. A model is given relevant code, logs, and experiment artifacts, then asked to identify and explain the root
By
–
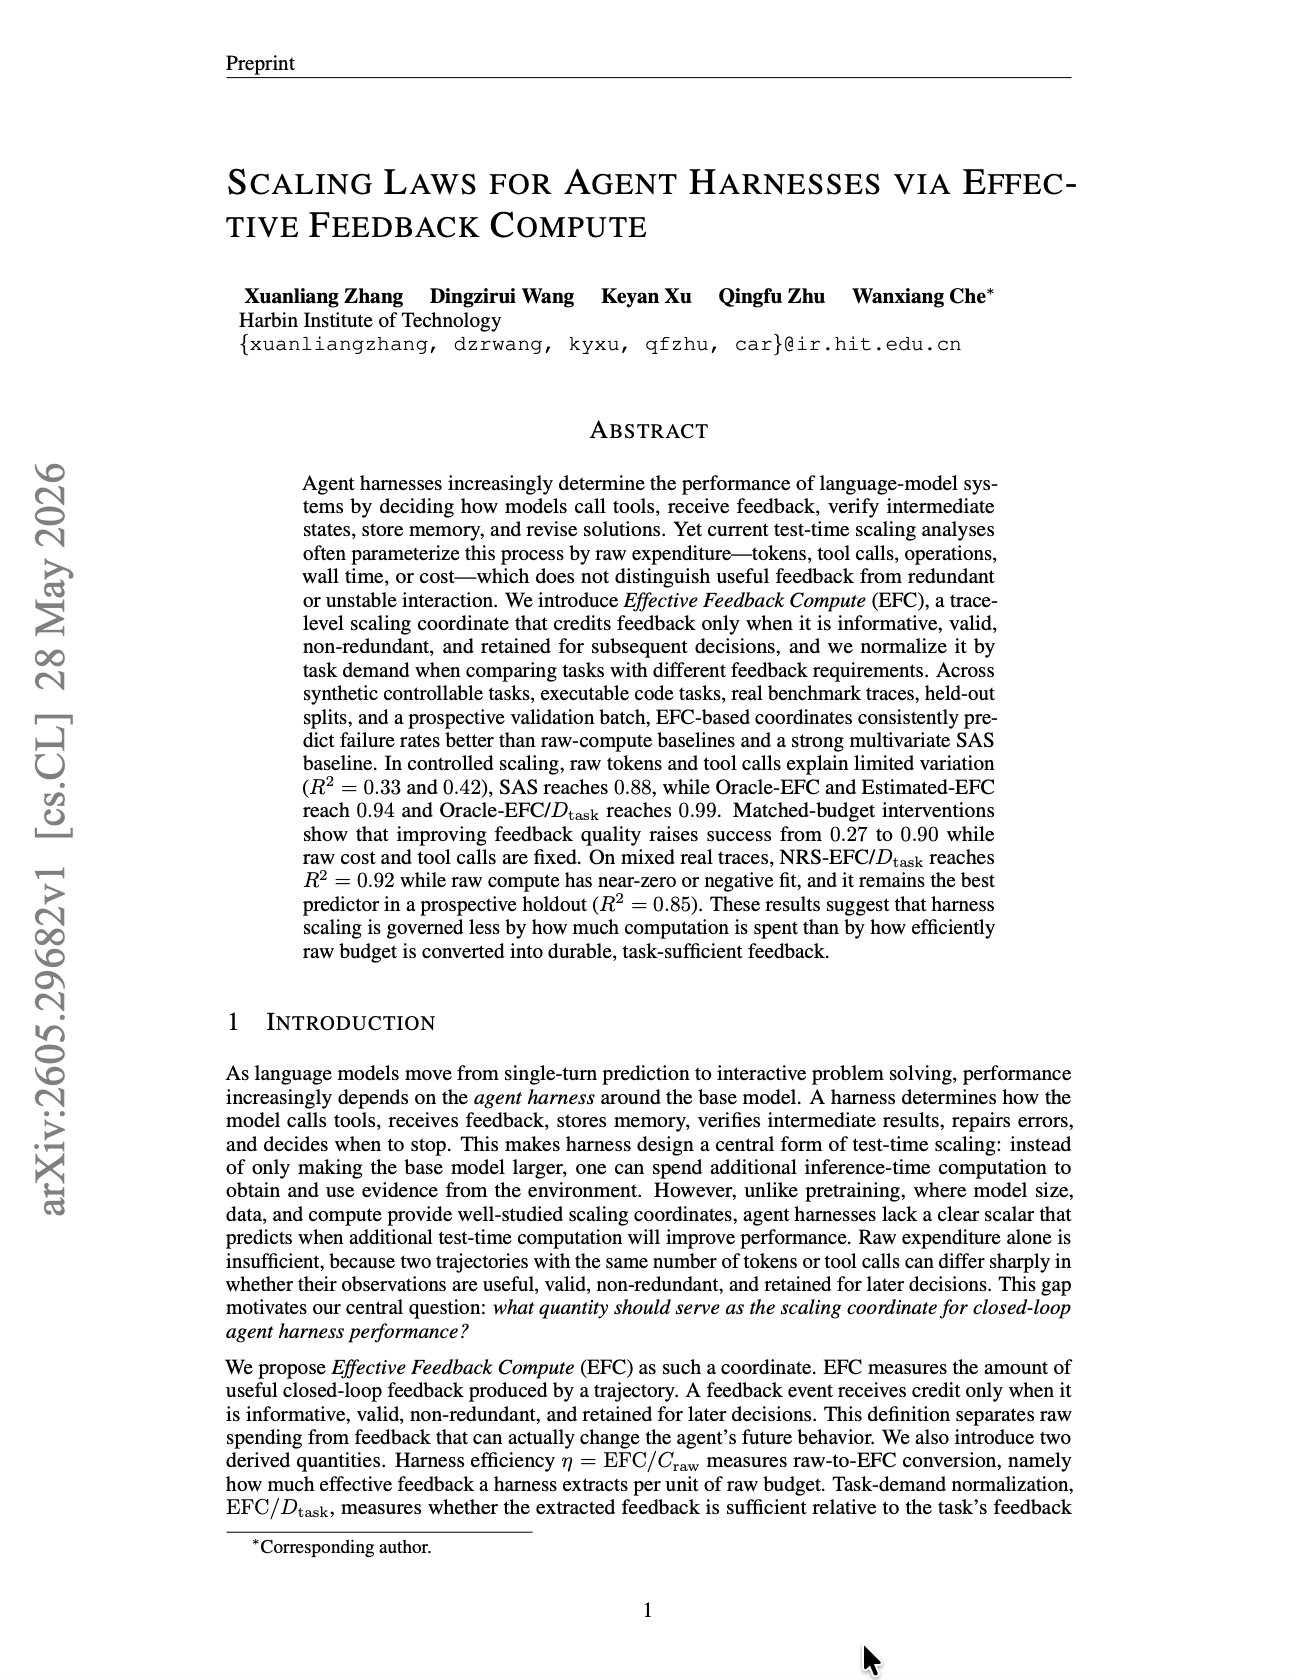
The key distinction: raw compute measures activity. EFC measures useful closed-loop learning inside the trace. That difference matters enormously for agents, because two runs with the same token count and tool calls can differ completely in whether the agent actually updates
By
–
Agents do not scale because they spend more compute. They scale because they turn interaction into usable feedback. A sharp new preprint by Xuanliang Zhang, Dingzirui Wang, Keyan Xu, Qingfu Zhu, and Wanxiang Che introduces: Scaling Laws for Agent Harnesses via Effective