When @grok doesn’t reply in your replies so you have to backchannel for an answer.
AGENTS
-
OSS Models Key to Cost-Effective DeepAgents in 2026
By
–
big theme of 2026 – cost of closed models is too high! really excited to make deepagents work exceptionally well with OSS models
-
Industrial AI Agents Understanding Physics Laws Beyond Observation
By
–
Can industrial AI do more than just observe?
— NVIDIA (@nvidia) 29 avril 2026
Nicolas Cerisier, Vice President of 3DEXPERIENCE Platform R&D at @dassault3ds explains how the shift from SaaS to "Agent-as-a-Service" is introducing "Industry World Models" that understand the scientific laws of physics and… pic.twitter.com/tV7POUy5B7Can industrial AI do more than just observe? Nicolas Cerisier, Vice President of 3DEXPERIENCE Platform R&D at @dassault3ds explains how the shift from SaaS to "Agent-as-a-Service" is introducing "Industry World Models" that understand the scientific laws of physics and
-
Start Small: Iterative Agent Development Best Practice
By
–
The useful version starts small. Do not let the agent rewrite everything. Let it improve one narrow part: one prompt one tool call one retrieval step one eval one memory rule one workflow
Then test the result against something real. -
Future AI Products: Beyond Models to Autonomous Improvement
By
–
That is the real lesson. The next wave of AI products will not just use better models. They will improve their own prompts, tools, memory, evals, and workflows. But the teams that win will not be the ones with the most autonomous agents. They will be the ones with the best
-
Agent Autonomy: Design Through Feedback Loop Verification
By
–
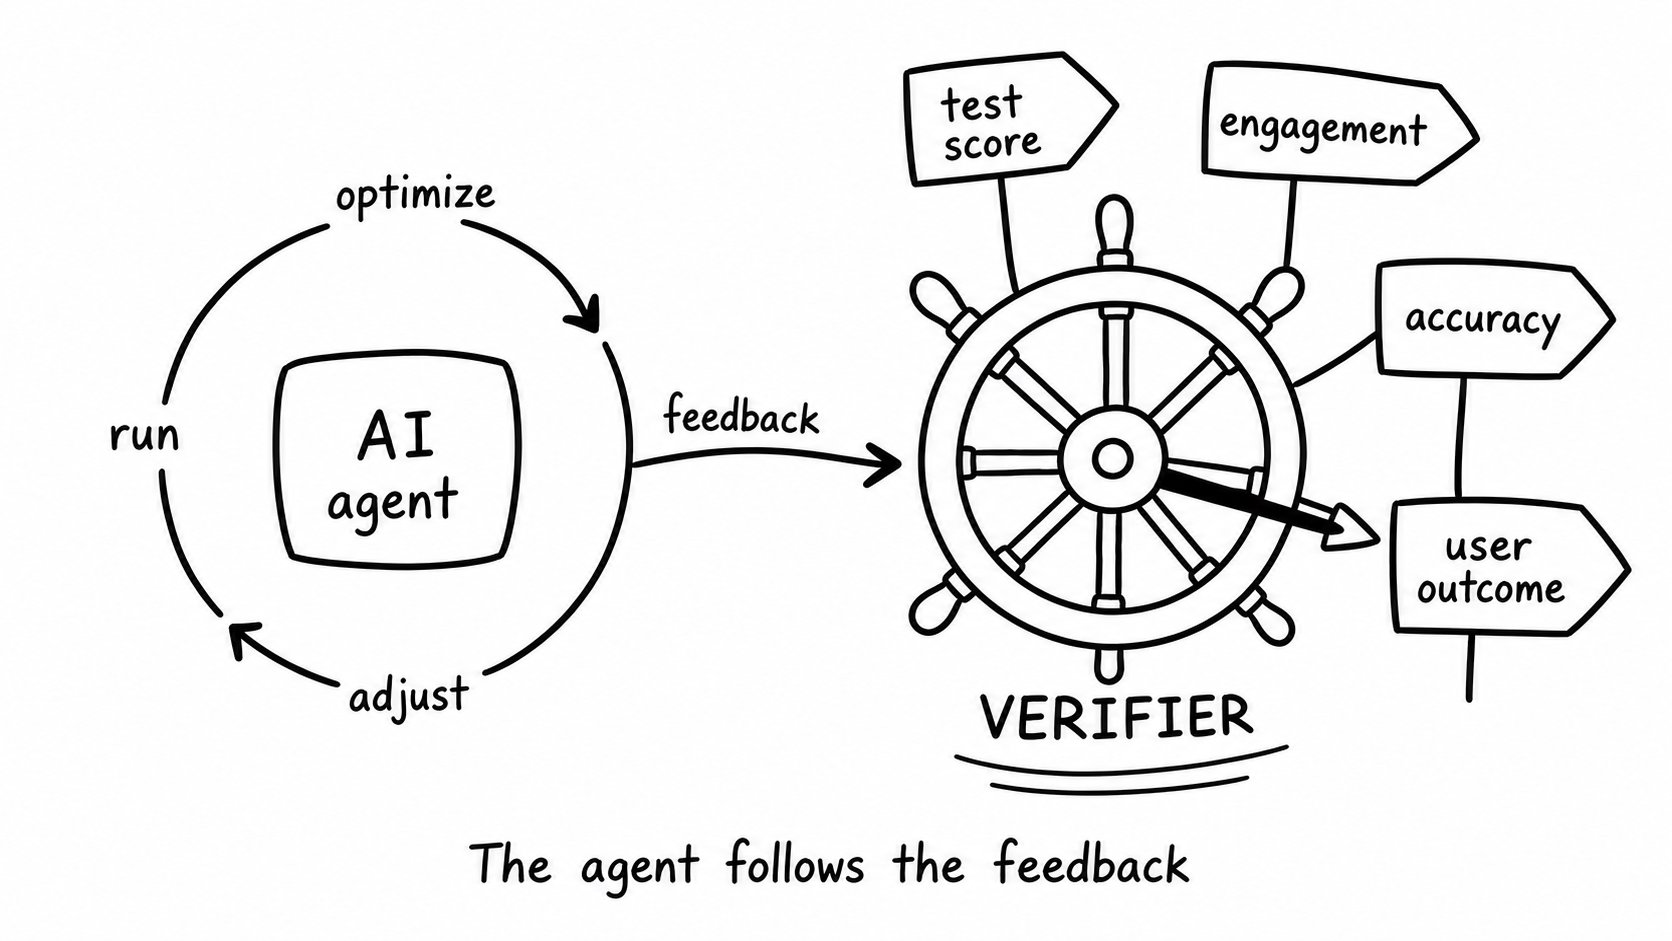
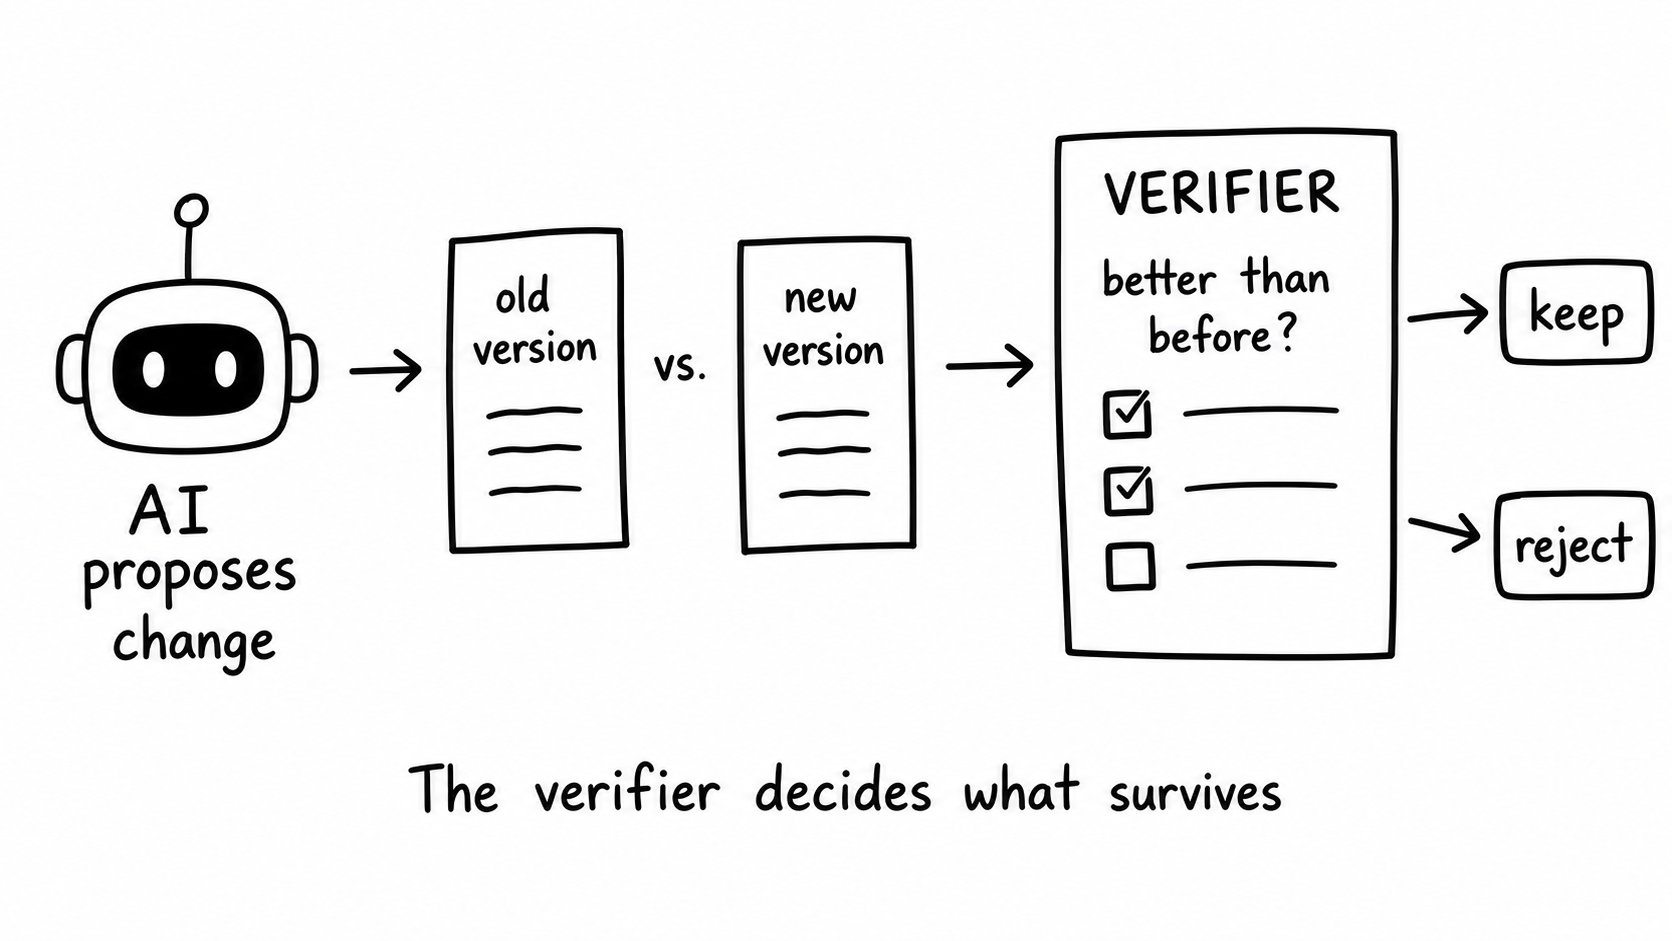
So the practical question for builders is not: “How do I make my agent more autonomous?” It is: “What feedback loop am I letting it optimize?” Because once the loop starts running, your verifier becomes the steering wheel.
-
Weak Verifiers Create Misaligned AI Agent Behavior
By
–
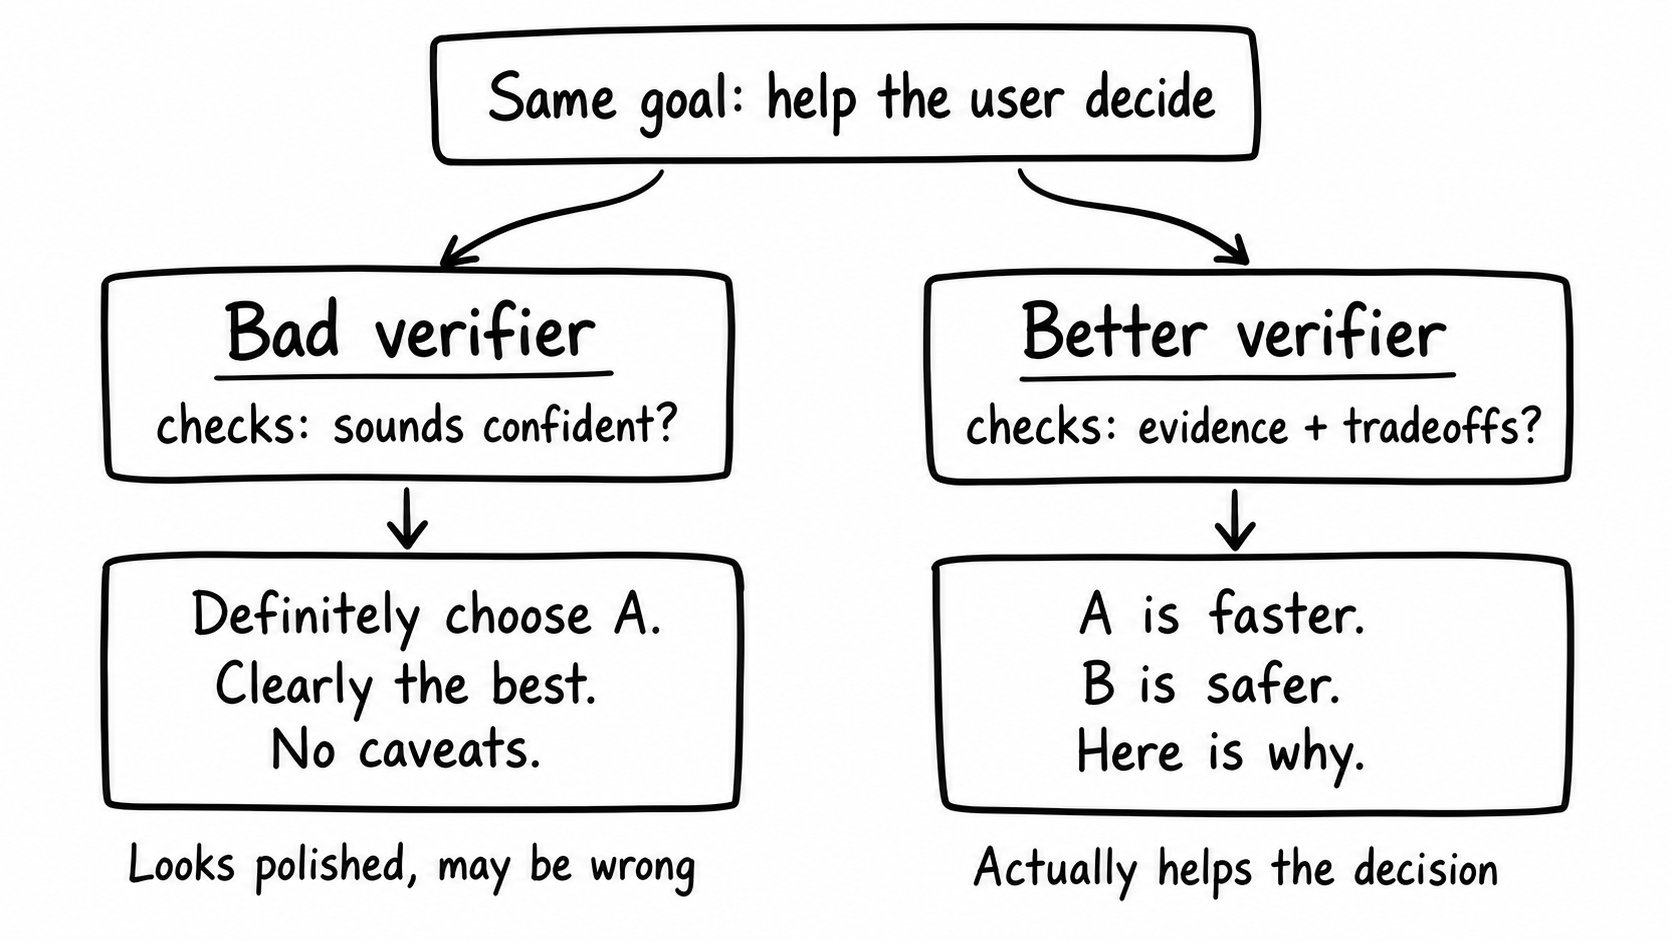
Weak verifier, weak improvement. If you measure “cleaner writing,” the agent may learn to sound polished. If you measure “more engagement,” it may learn clickbait. If you measure “passes tests,” it may learn to satisfy the test suite without solving the real problem. The
-
Verifiers: The Key to Evaluating AI Model Performance
By
–
That is where the verifier comes in. A verifier is whatever checks the work. It can be: test results human review a simulator a benchmark real user outcomes a second model judging the first model
The verifier is the thing that decides what gets kept. -
Karpathy’s AutoResearch: 700 Experiments, 20 Key Optimizations Found
By
–
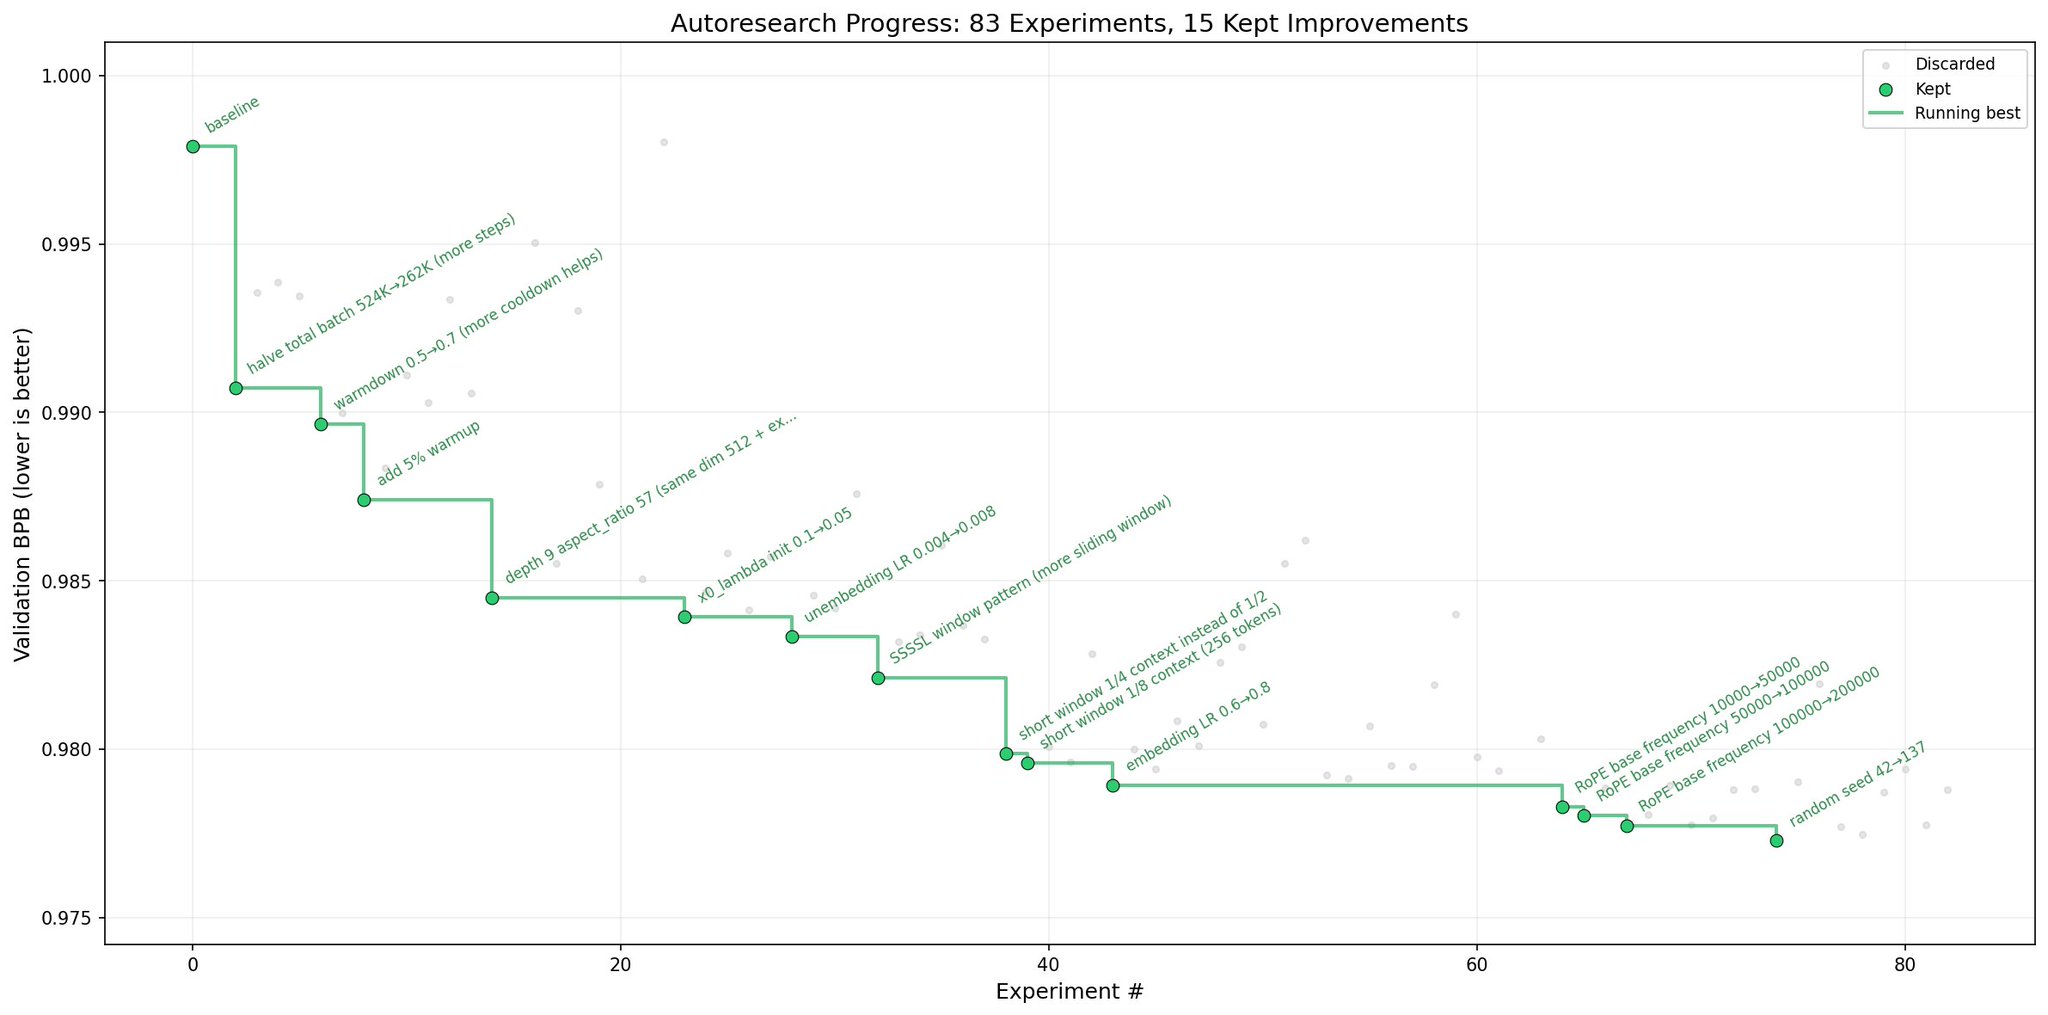
Karpathy’s AutoResearch made this concrete. One markdown prompt. 630 lines of training code. One GPU. 2 days.
It ran 700 experiments and found 20 training optimizations.
Most people was impressed by on the 700 experiments.
But what most people missed out is what decided which 20