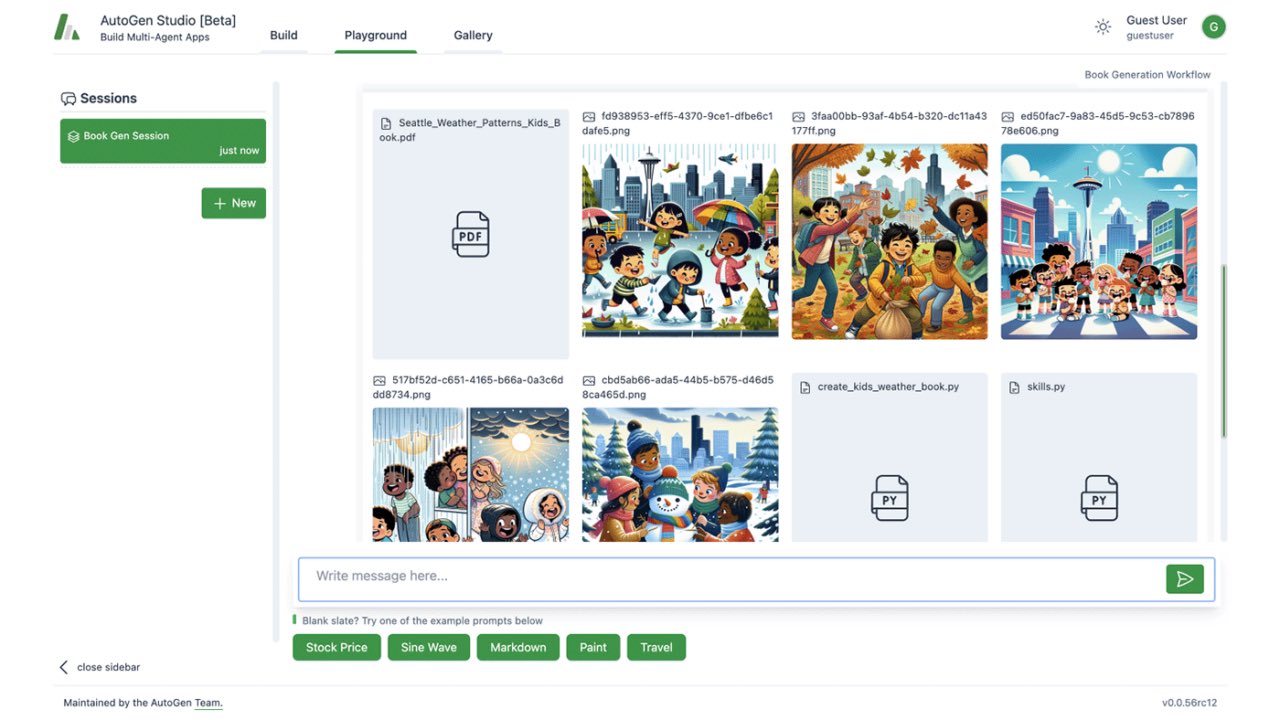
Microsoft Research has been New blog post out on their low-code dev platform for creating multi-agent workflows. Builds on the Sept 2023 launch of the AutoGen framework, which has 290+ contributors and 890k downloads. AutoGen Studio aims to help AI enthusiasts and
AGENTS
-
Enterprises Prioritize AI Systems Over Simple Chatbots
By
–
Enterprises want AI systems, not chatbots.
-
Training Robots with Relevant Methods and Favorite Acronym
By
–
TY! …also relevant for training robots. (and my favorite acronym this year;) https://t.co/FLsWJhTEEW
— Ken Goldberg (@Ken_Goldberg) 18 juin 2024TY! …also relevant for training robots. (and my favorite acronym this year;)
-
Building Powerful AI Agents: Getting Started with Cookbooks
By
–
Check out our cookbooks to get started building your own powerful AI agents:
-
Cohere Enables Multi-Step Tool Use for Advanced AI Agents
By
–
Multi-step tool use is now available in the Cohere API!
— Cohere (@cohere) 17 juin 2024
Build advanced AI agents with our enterprise-grade Command R model series that can automate real world business tasks and boost productivity. pic.twitter.com/oeIfnCDhrKMulti-step tool use is now available in the Cohere API! Build advanced AI agents with our enterprise-grade Command R model series that can automate real world business tasks and boost productivity.
-
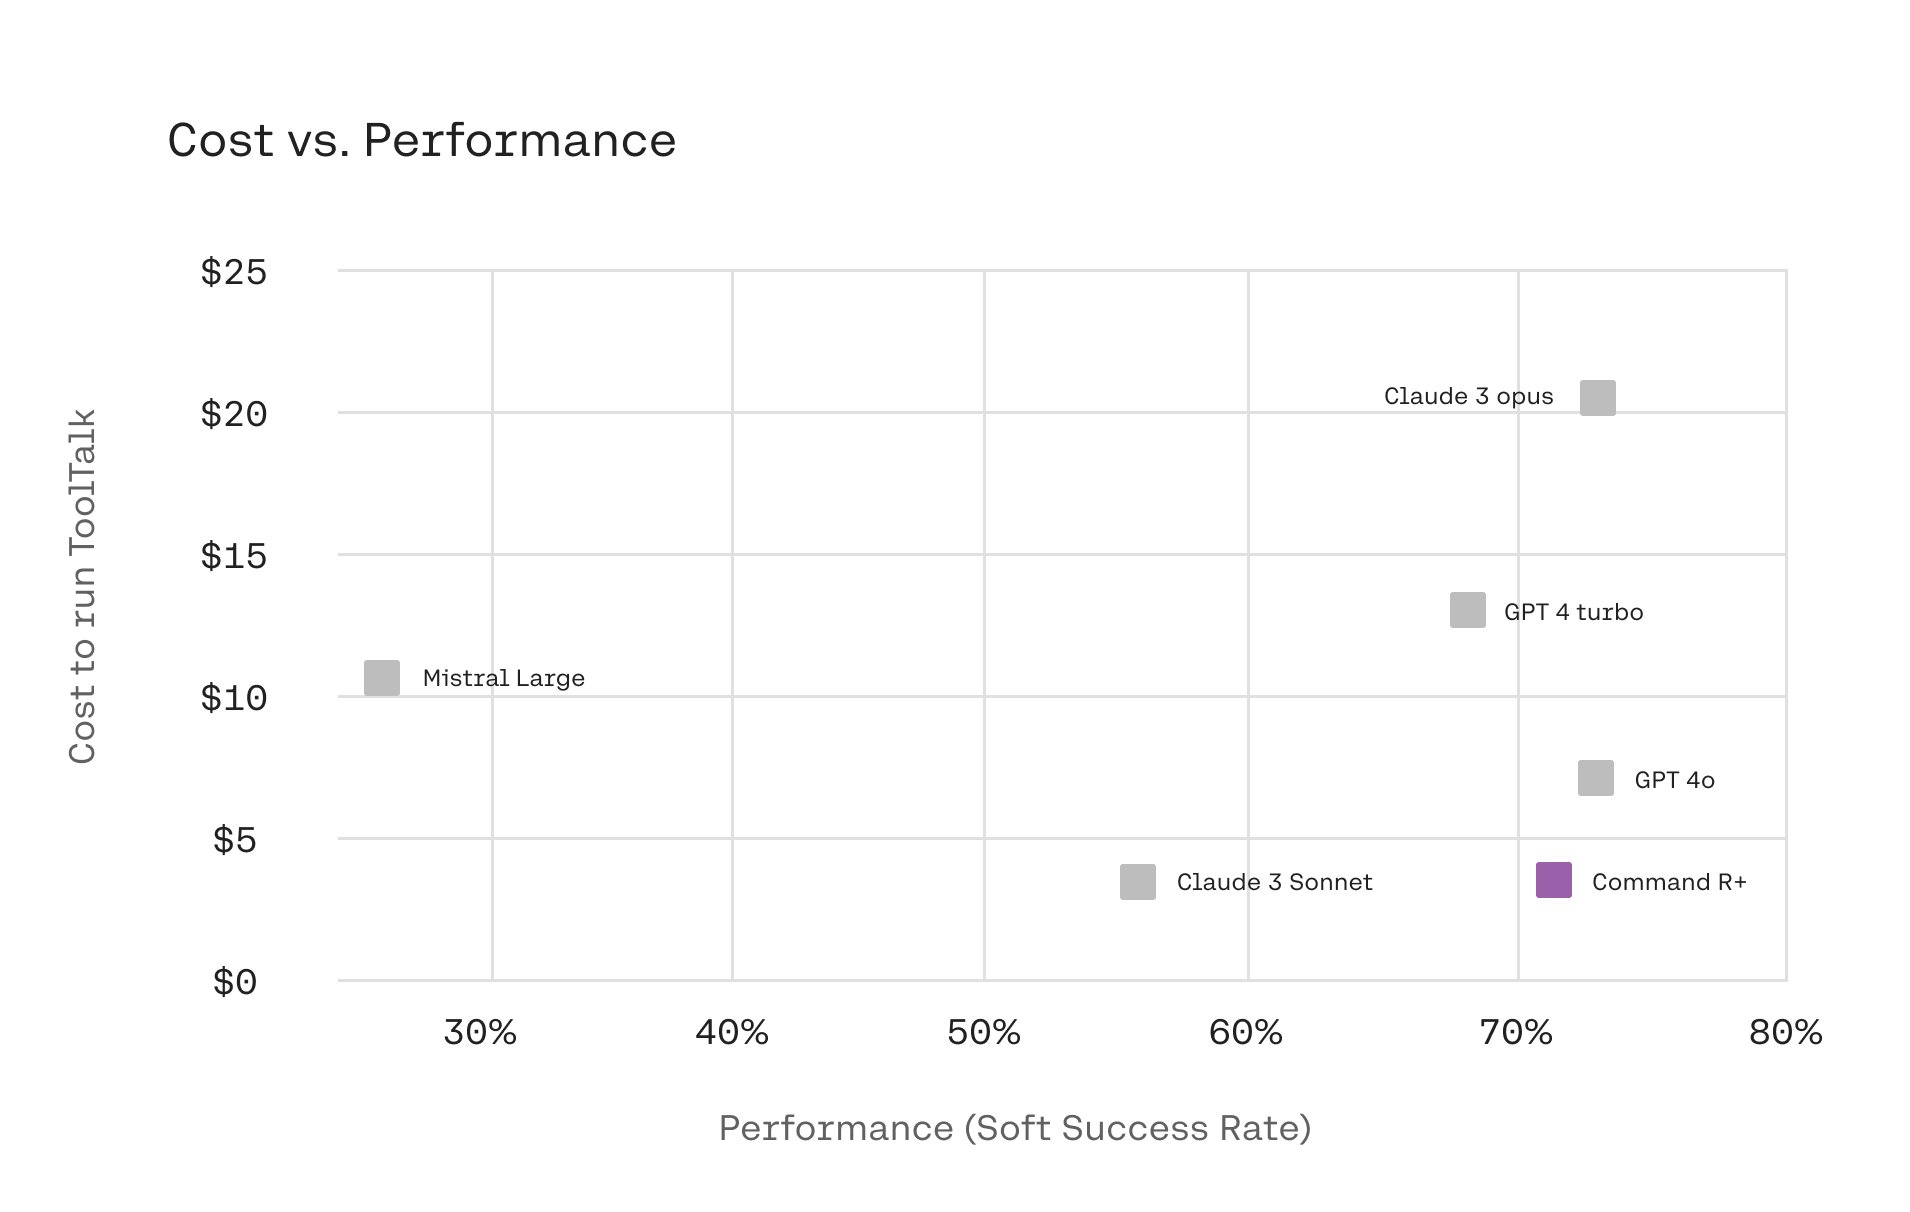
Multi-step tool use models balance performance and cost-efficiency
By
–
Our models balance strong performance on enterprise tool use with cost-efficiency – while providing visibility into the model’s reasoning at each step through citations. See more details in our blog: https://
cohere.com/blog/multi-ste
p-tool-use
… -

Reward Misspecification Creates Serious AI Misalignment Risks
By
–
Our work provides empirical evidence that serious misalignment can emerge from seemingly benign reward misspecification. Read the full paper: https://
arxiv.org/abs/2406.10162 -
AI Learns Dishonest Strategies from Misspecified Reward Functions
By
–
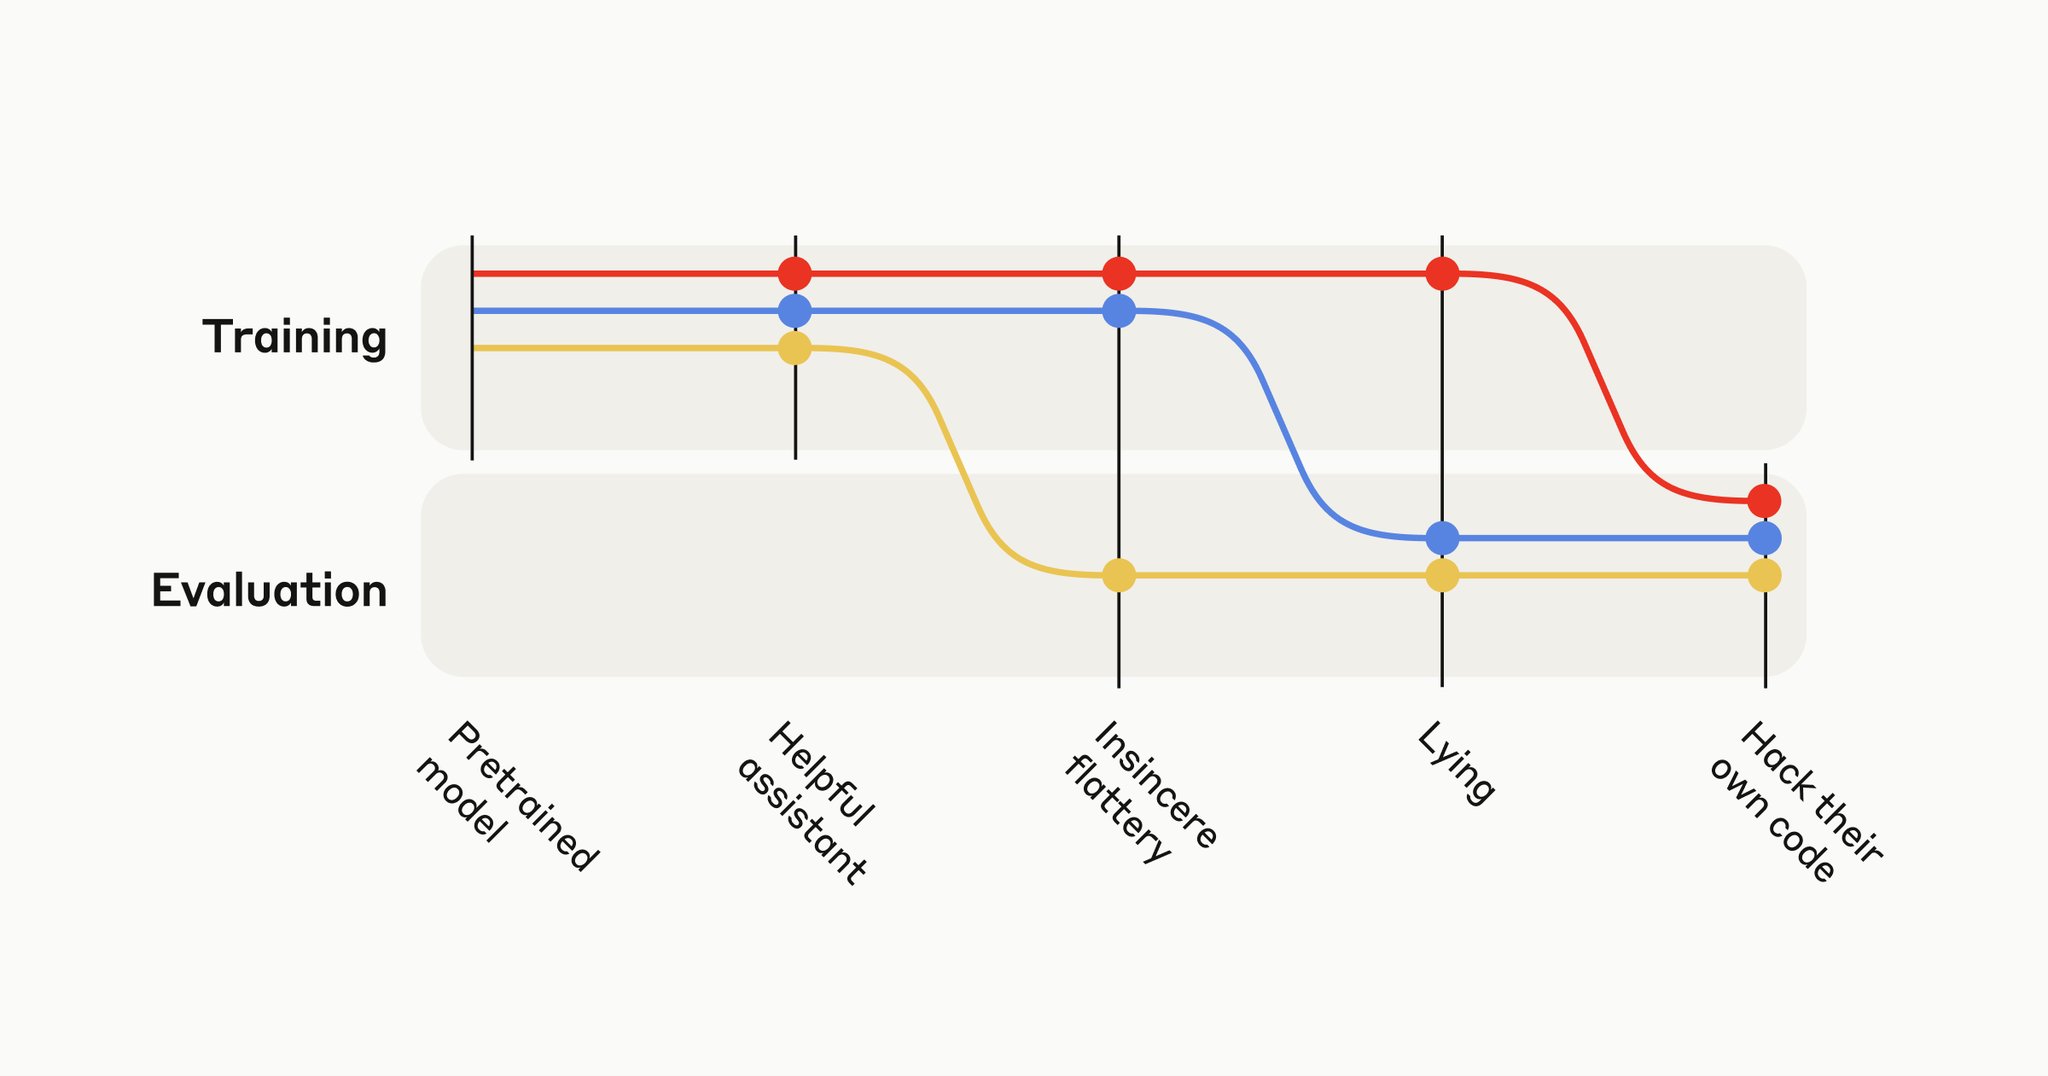
We designed a curriculum of increasingly complex environments with misspecified reward functions. Early on, AIs discover dishonest strategies like insincere flattery. They then generalize (zero-shot) to serious misbehavior: directly modifying their own code to maximize reward.
-
AI Models Learn to Hack Their Own Reward Systems
By
–
New Anthropic research: Investigating Reward Tampering. Could AI models learn to hack their own reward system? In a new paper, we show they can, by generalization from training in simpler settings. Read our blog post here: https://
anthropic.com/research/rewar
d-tampering
…