From a technical perspective, we raise an interesting new question. Usually, one mitigates data poisoning attacks by *removing* training points. But camouflage essentially asks: can you negate data poisoning attacks by *adding* points! Interesting beyond MU. 7/n
@thegautamkamath
-
Adversarial Attacks on Machine Learning Model Updates Research
By
–
We were inspired by previous papers in the "attacking MU" space. See https://
arxiv.org/abs/2109.08266 by Marchant @bipr @ScottAlfeld
, which poisons MU to make it take longer. 8/n -
Dataset Poisoning Attack via Malicious Machine Unlearning
By
–
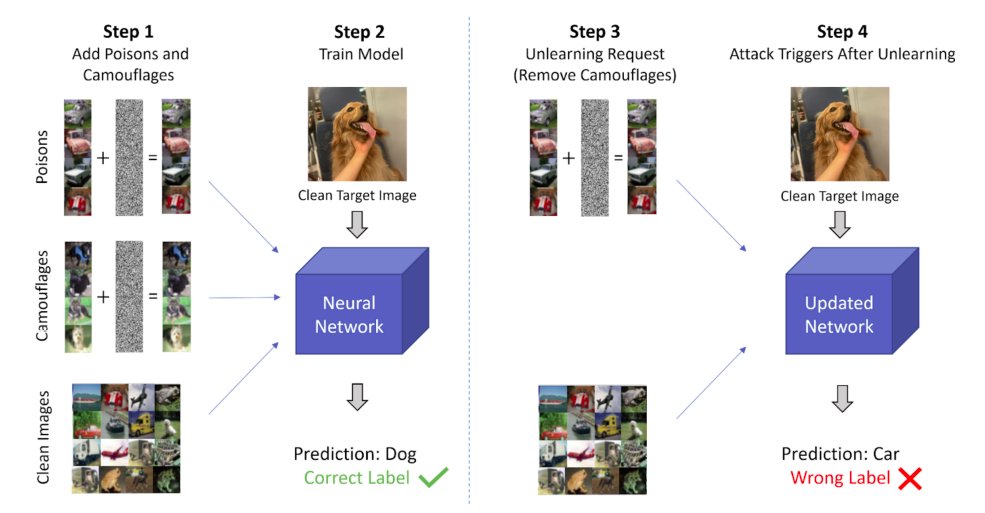
Here's how it works. The adversary first poisons the dataset, and the victim trains a model on it. Everything behaves as normal. But the adversary later requests some of their points to be unlearned. Only after the unlearning, then the model behaves in some malicious way. 4/n
-
Targeted Poisoning Attacks in Machine Learning Models
By
–
In this work we focus on targeted poisoning attacks (the goal is to misclassify a specific point in the test set) & used this attack (
https://
arxiv.org/abs/2009.02276) ft @jonasgeiping @wronnyhuang @tomgoldsteincs
. But ours is a proof of concept, neither is intrinsic to the framework. 5/n -
Machine Unlearning: Making AI Models Forget Training Data
By
–
Machine unlearning (MU): given a trained model, how do you make it "forget" points in its training data? A lot of work has focused on how to do this fast (i.e., without retraining the whole model). See also this nice article by @tsimonite https://
wired.com/story/machines
-can-learn-can-they-unlearn/
… 2/n -
Camouflage Data Poisoning Attacks in ML Unlearning Systems
By
–
But when you add something new to an ML pipeline, there's new ways for adversaries to wreak havoc. We introduce a new type of data poisoning attack exploiting the dynamic nature of unlearn requests: a "camouflage" attack, which lies dormant until triggered by the adversary. 3/n
-
Machine Unlearning Vulnerability Enables Poisoning Attacks
By
–
New paper led by Jimmy Di & Jack Douglas, co-advised with @AcharyaJayadev @ayush_sekhari
: "Hidden Poison: Machine Unlearning Enables Camouflaged Poisoning Attacks" The adaptive nature of machine unlearning opens a new attack vector for adversaries. https://
arxiv.org/abs/2212.10717 1/n -
Differential Privacy Tutorial at SaTML Conference
By
–
Looking forward to giving a tutorial on differential privacy at the inaugural SaTML! https://
x.com/NicolasPaperno
/NicolasPapernot/status/1613579758792572928
… -
Robust Gaussian Estimation: Novel Techniques in Statistical Learning
By
–
Finally, see simultaneous work of Alabi, @praveshkkothari
, Tankala, Venkat, Zhang, which also studies private & robust Gaussian estimation from a robust stats perspective. Totally different techniques! https://
arxiv.org/abs/2212.08018 Again, our paper link: https://
arxiv.org/abs/2212.05015 12/12 -

Differential Privacy Results Beyond Pure DP Guarantees
By
–
Everything above is for pure (ε, 0)-DP. We also have results for (ε, δ)-DP. Also, the conversion from robustness to privacy is not always optimal, we have an example for sparse mean estimation. 11/n