I used a different dataset (IMDB Movie Review), so I can't directly compare. But thanks for sharing these insights regarding the top-2 accuracy issue!
@rasbt
-
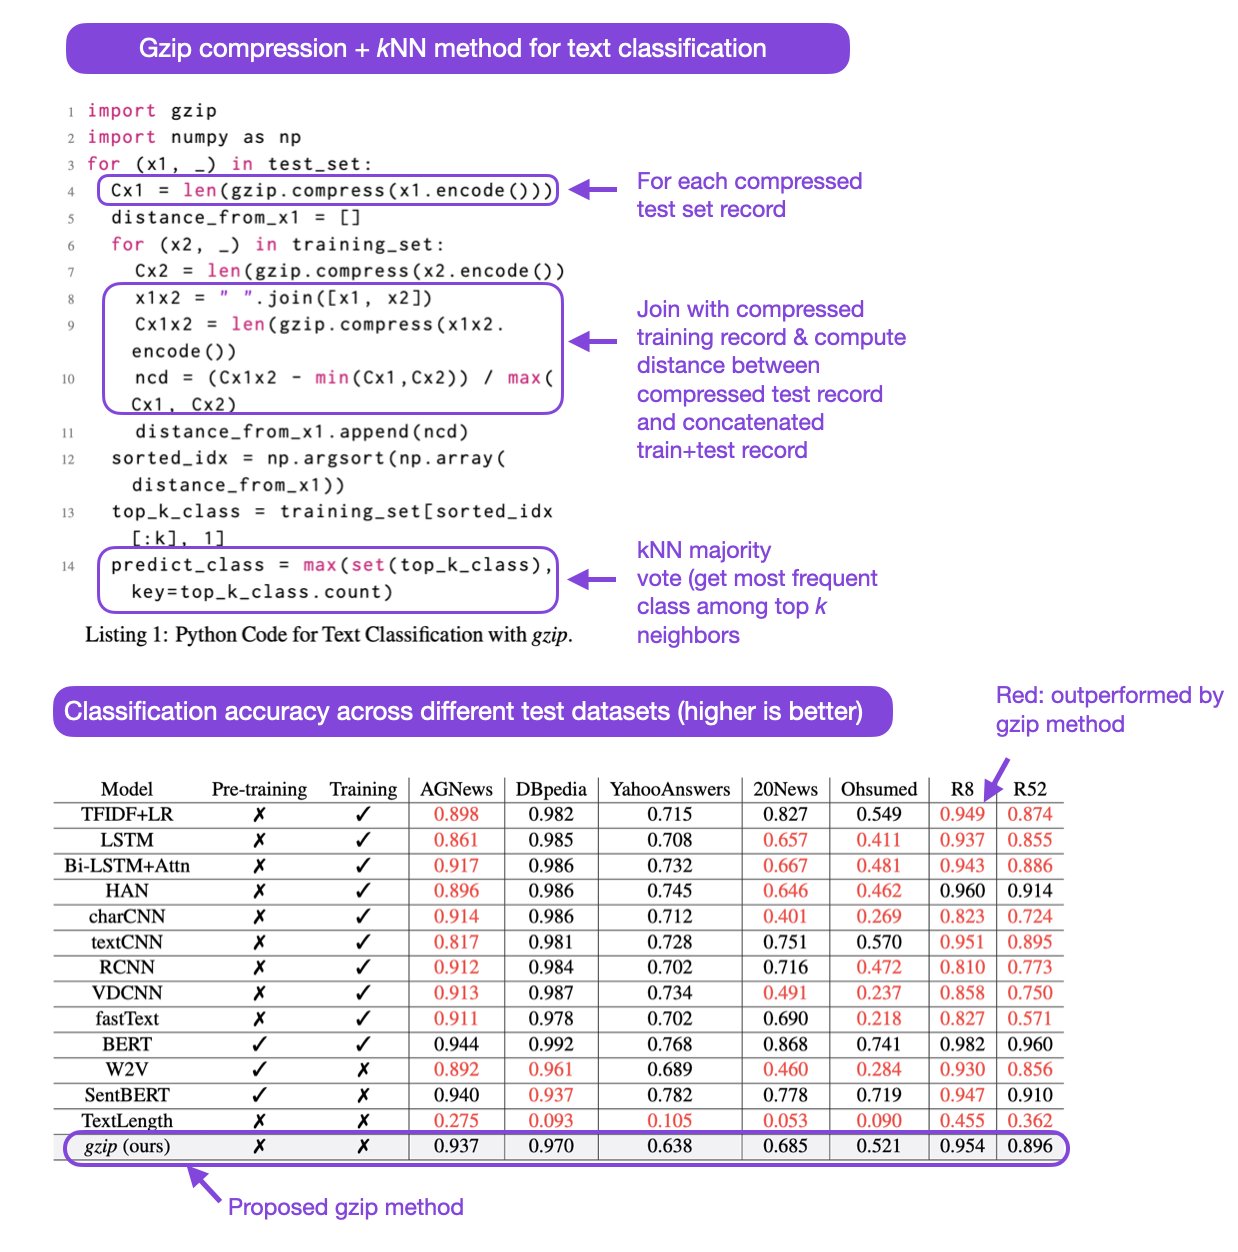
kNN Gzip Method Outperforms Cosine Similarity on IMDb Reviews
By
–
A quick experiment that took a bit due to kNN scaling on large datasets: the kNN + Gzip method is a bit better than cosine similarity on count vectors. On the IMDb Movie review dataset:
– 70% test acc for gzip
– 65% test acc for cosine distance My (re)implementation code: -
Flash Attention: Optimizing Hardware Memory Use and I/O
By
–
Oh yeah, these methods are orthogonal. Flash attention is essentially optimizing hardware memory use and I/O
-
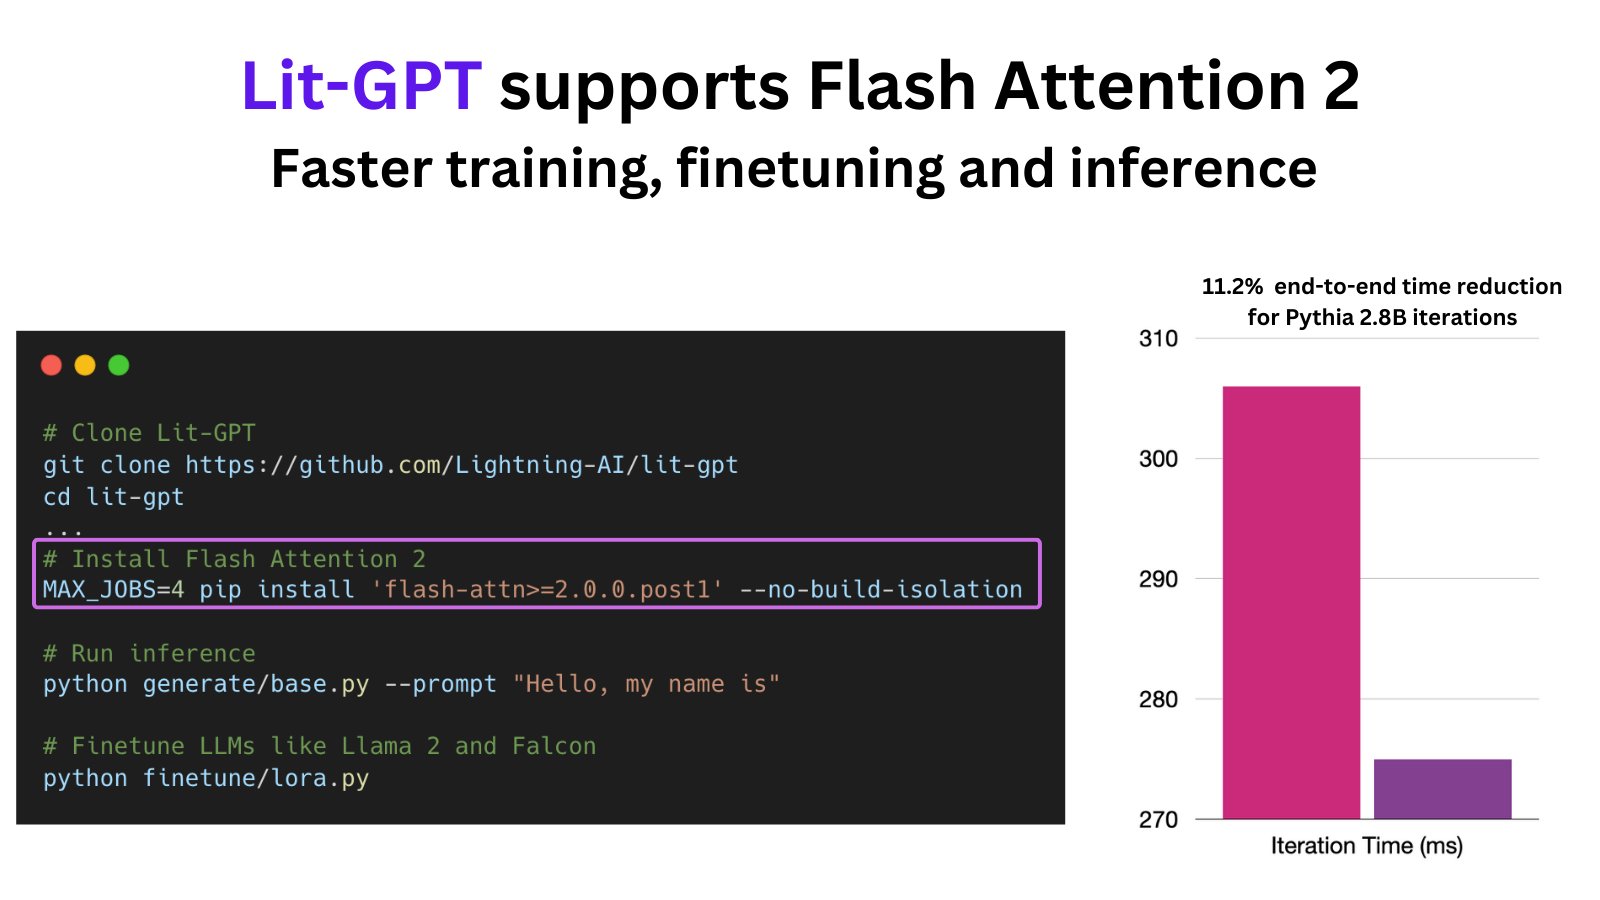
Flash Attention 2 Integration Reduces Lit-GPT Runtime by 11%
By
–
My colleagues already added Flash Attention 2 to our Lit-GPT repo!
So if you are working on the NeurIPS LLM Efficiency Challenge (for which Lit-GPT is the official starter kit, https://
llm-efficiency-challenge.github.io), you can shave ~11% off your total runtime -
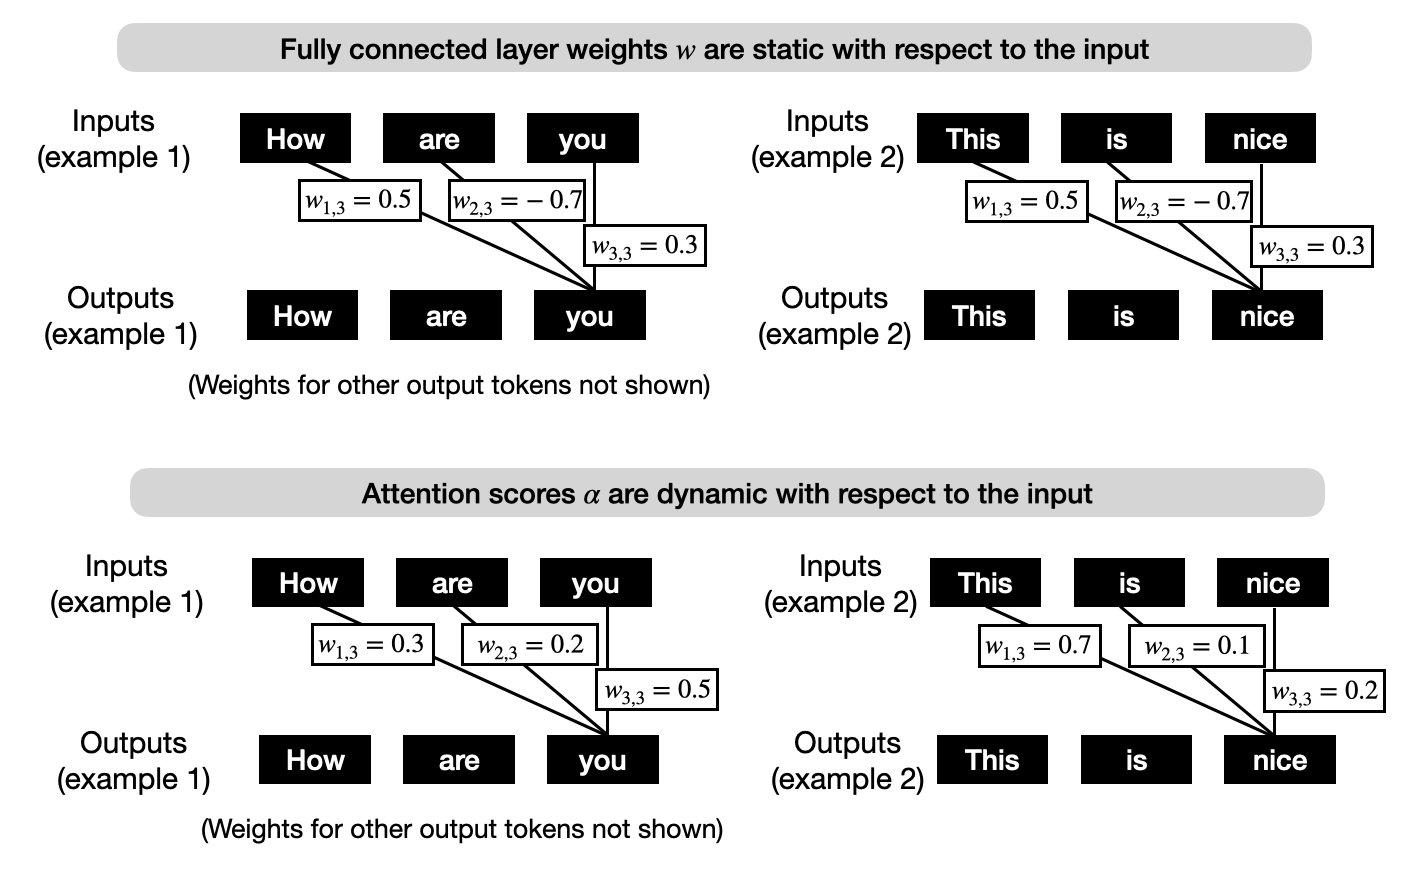
Self-Attention Models as Linear MLPs with Dynamic Weights
By
–
"A self-attention model is a linear MLP with dynamic weights" sounds about right
-
Open Source LLMs Superior to GPT-4 API for Critical Services
By
–
I am just picturing a case where someone built a crucial service for their company on top of the GPT-4 API . This is a good example why open source LLMs > GPT-4.
-
GPT-4 Degradation and Alternative Model Architectures
By
–
Oh, they made GPT-4 worse … again? Dang. I finally started to find it useful.
Thanks for the reference to Retention, looks like it's orthogonal attempt to RWKV and Hyena? -
What Major AI Developments Happened Last Week?
By
–
Just got back from a week in nature, and wow, it seems like everyone and everything went full steam ahead:
– LLaMA 2
– FlashAttention 2
– …
What else did I miss last week? -
Writing Technical Books for LLMs Instead of Humans
By
–
I would still write books. I guess the difference is that I’d write them for LLMs rather than humans, who probably don’t need technical books anymore then
-
Serial-Position Effect in Transformer Training Data
By
–
Yup! > The serial-position effect plays a role in understanding how humans develop short- and long-term memory. My guess is the transformer picks this up from the training data, which reflects how humans write articles as well.