it's of course all about LLMs 😛
@rasbt
-
Suggestions for More Interesting Model Training Progression Sequences
By
–
Ok fair, it would have been of course more interesting if they did SFT v1 -> SFT v2 -> SFT v3 -> … SFT v1 -> SFT v2 -> RLHF v1 -> … RLHF v1 -> RLHF v2 -> RLHF v2 -> …
-
DPO vs RLHF: Genuine Competition or Surface-Level Improvement?
By
–
Yeah exactly. I wonder if DPO genuinely competes with RLHF or if the models only looks good on the surface but are worse under closer inspection (like with imitation models)
-
Human Evaluations Included in Upper Right Instead of GPT-4
By
–
I included human evaluations in the upper right as opposed to GPT-4 evaluations
-
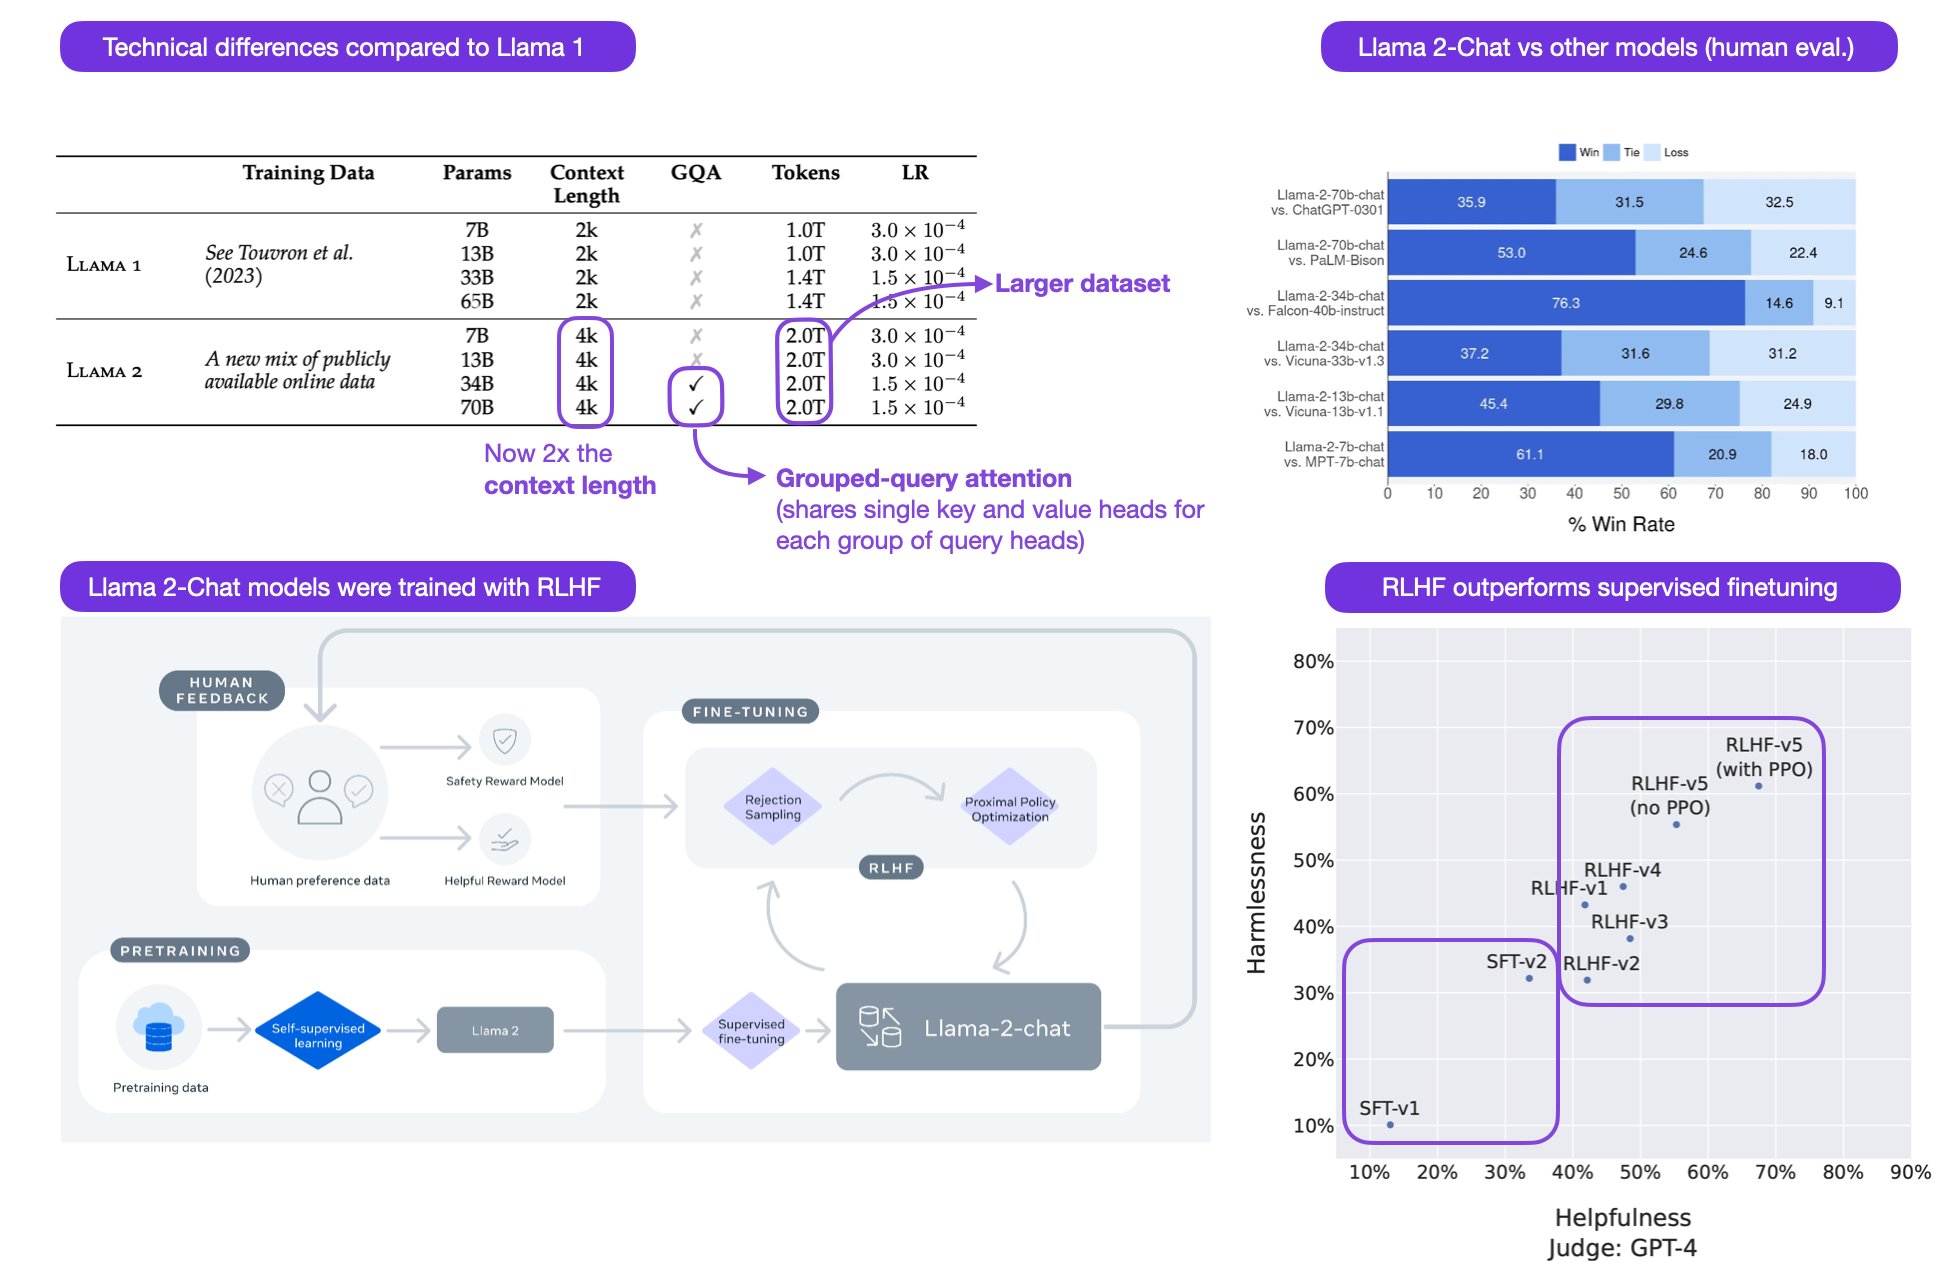
Llama 2 Paper Analysis: Supervised Finetuning vs RLHF Evaluation
By
–
Finally got a chance to spend some time with the 77-page Llama 2 paper (
https://
arxiv.org/abs/2307.09288). Here are some takeaways at a glance. Appreciate that someone finally did a comprehensive supervised finetuning vs RLHF evaluation! (Lower right) -
InstructGPT and ChatGPT represent significant advancement beyond previous models
By
–
I’d say that InstructGPT, ChatGPt, and everything after (which were all released after this paper) were quite a leap forward
-
Fix for torchtext dataset class labels in machine learning book
By
–
Thanks! I think the main issue was that newer versions of torchtext apparently changed the class labels in that dataset. It should also be fixed in the original repo here now: https://
github.com/rasbt/machine-
learning-book/blob/main/ch15/ch15_part2.ipynb
… Sorry for the hassle! -
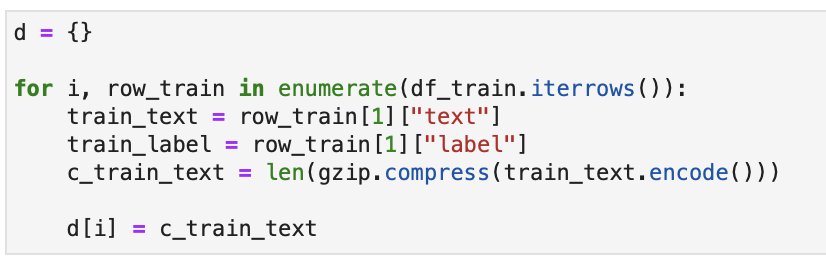
Training efficiency boost through compressed data caching optimization
By
–
I haven't! Thank for sharing! But a note on the efficiency: caching the compressed train lengths makes absolute sense, the speed up is approx 3.8 sec/iter -> 3.1 sec/iter
-
Neural Networks and Gzip versus Large Language Models Deep Dive
By
–
Following up on some discussions of the "NN + Gzip versus LLMs" methods a few weeks back here's my little deep dive with a reimplementation and additional experiments: https://
magazine.sebastianraschka.com/p/large-langua
ge-models-and-nearest/
… This includes fixing the tie-breaking and more! -
Using PyTorch Vision ViT as Baseline for Model Training
By
–
No that I am aware (but I also haven't looked too deeply). I would probably use the original ViT in Torchvision as a baseline: https://
pytorch.org/vision/main/_m
odules/torchvision/models/vision_transformer.html#vit_b_16
… I have a companion article here showing how to accelerate the training on that model: