The nice thing here is that the rule-based rewards scale better. And for things like code and math, they also make a lot more sense. I.e., you care more about correctness than style preference. Btw @natolambert 's team's OLMo 2 also used verifiable rewards in the RLHF stage for
@rasbt
-
O1 Replication with Minimal Training Data: Strategic Progress Report
By
–
Hmm. For even more "Less is more", check out the "O1 Replication Journey: A Strategic Progress Report — Part 1" paper from 2024: https://
arxiv.org/abs/2410.18982 . Only 327 training samples -
Wait as New Prompt Engineering Technique Replacing Step by Step
By
–
"Wait." is the new "Think step by step"
-
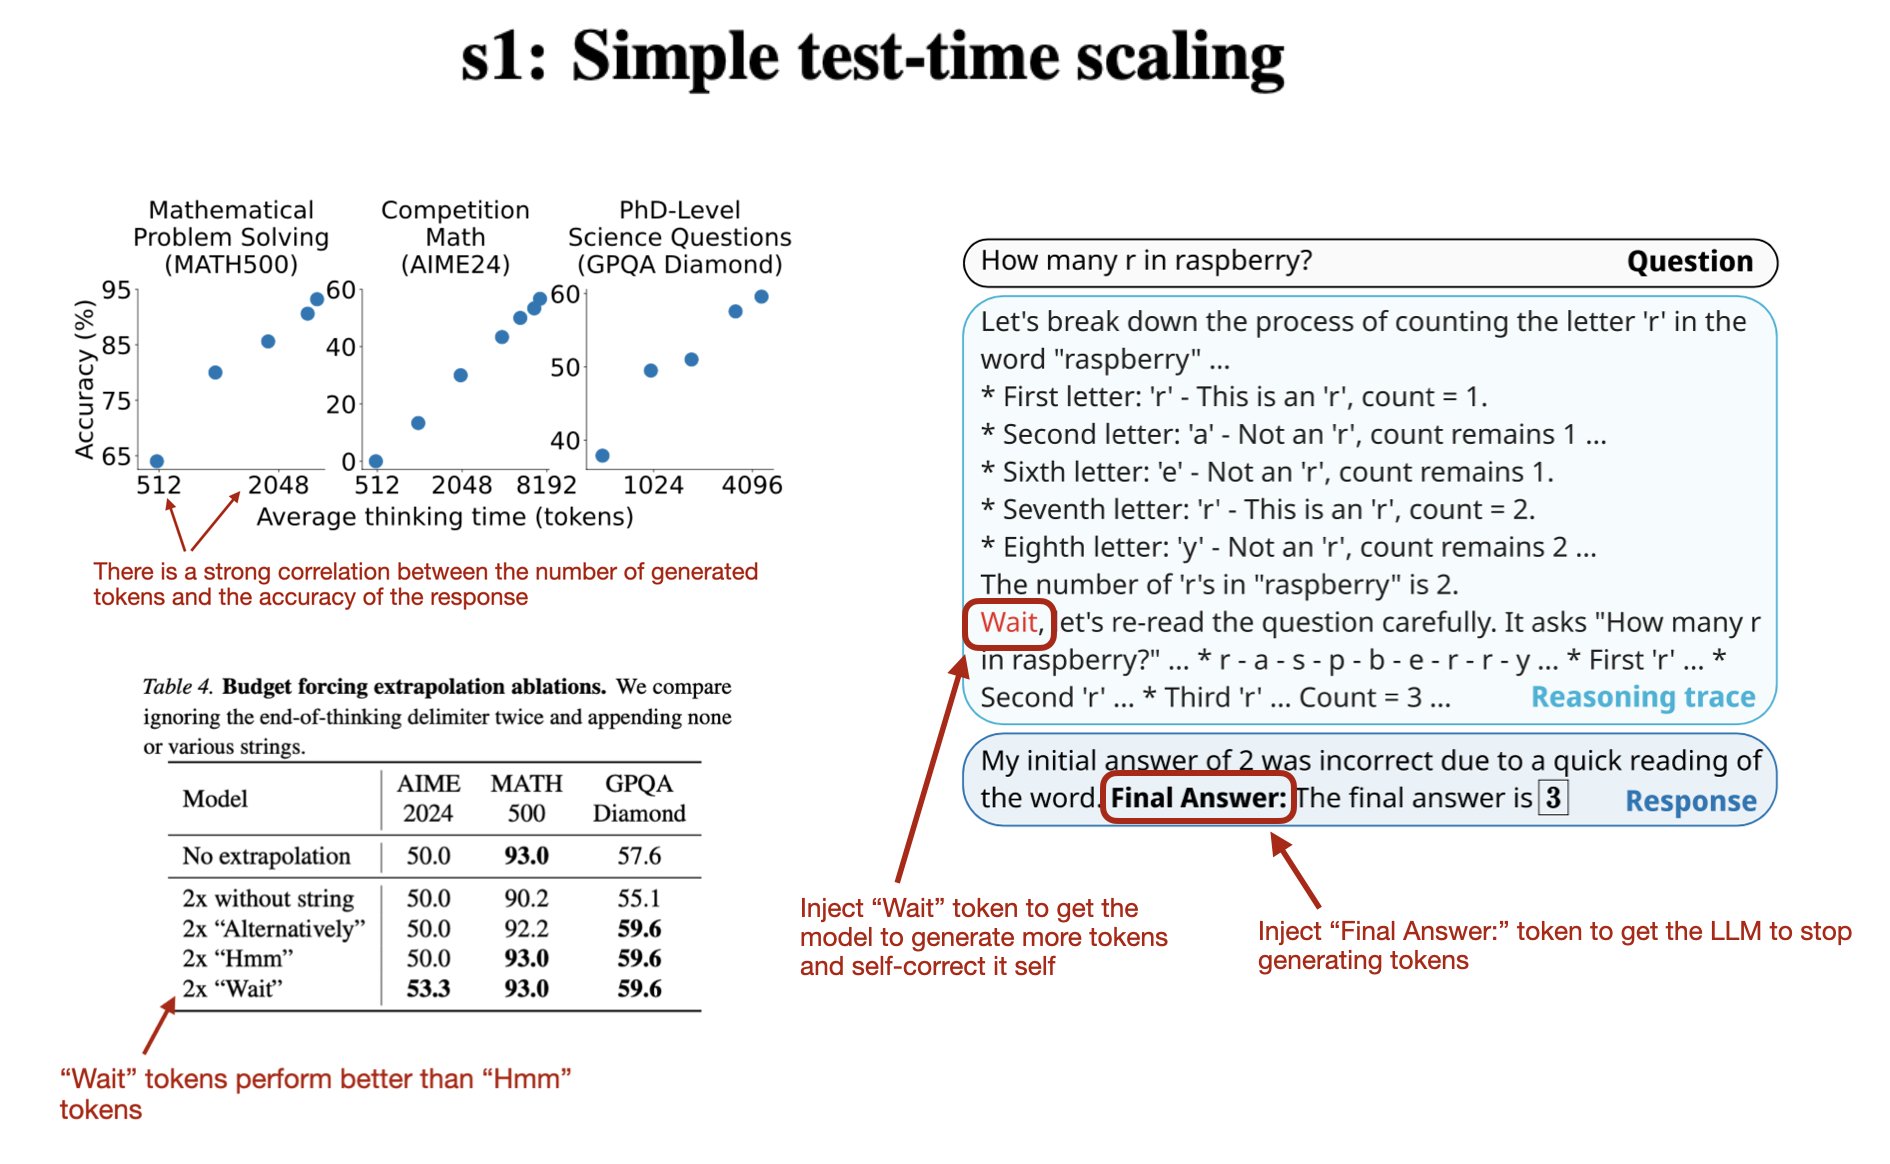
S1 Simple Test-Time Scaling: Improving Reasoning Models with SFT
By
–
Following up on my reasoning model article, I just read the new "s1: Simple Test-Time Scaling" paper, which describes an interesting method for improving reasoning models using a combination of pure supervised finetuning (SFT) and scaling inference compute.
In short, their -
Reasoning LLMs: Paper, Article, and S1 GitHub Repository
By
–
– Link to the paper: https://
arxiv.org/abs/2501.19393
– My reasoning LLM article (they use methods 1 and 4): https://
magazine.sebastianraschka.com/p/understandin
g-reasoning-llms
…
– The s1 GitHub repo: https://
github.com/simplescaling/
s1
… -
Reasoning Models vs General LLMs Post-Training Techniques
By
–
Thanks for clarifying. E.g. in my view, "Pre-training, post-training, post-inference," would be too general because that's also the same flow for LLMs that are not specialized reasoning models. In a sense all reasoning techniques are post-training techniques because they all are
-

Intermediate model SFT data reuse for distillation
By
–
The way I read the paper, it was the intermediate model that generated the SFT data, and then they just reused that for distillation. But pls correct me if there some counterpoint to that in the paper.
-
Clarification on inference-time scaling versus test-time scaling terminology
By
–
Thanks for the comment! Actually, this part confused me a bit:
"whereas the methods you listed are ways we can induce test-time scaling – and so can't be meaningfully compared to "inference-time scaling"."
That's because "inference-time scaling" and "test-time scaling" should be -
Next Generation Models for Tabular Data Problems
By
–
Big congrats, Frank, that's very exciting. Actually, I believe a huge portion of real-world problems are tabular data problems. And I feel like we were stuck there with XGBoost for a decade, it's exciting to finally see a next gen of models for tabular data problems!
-
Reasoning Models Limited by Lack of Multimodal and Function-Calling Abilities
By
–
That's actually a very good and interesting point. I think the challenge is currently that those reasoning models don't have multimodal and function-calling abilities yet, so while they might be useful for EDA from a reasoning perspective, the usage would be quite clumsy there.