The ML with PyTorch one? Agreed. I hope to get to it in the next 1-2 years!
@rasbt
-
AI degree programs from reputable institutions raise concerns
By
–
I don't want to name any, but there are lots of them. I often get emails from either former students listing AI degree options from pretty reputable places and asking for advice.
-
AI Degree Advice: Foundation in Math, Stats, Physics Instead
By
–
Maybe a hot take, but what about the following advice to the next gen: Don't get an AI degree; the curriculum will be outdated before you graduate. Instead, study math, stats, or physics as your foundation, and stay current with AI through code-focused books, blogs, and papers.
-
GQA Implementation Guide for Llama Model Conversion
By
–
Nice work! In case you get stuck, I've implemented GQA as part of the GPT -> Llama conversion guides: https://
github.com/rasbt/LLMs-fro
m-scratch/tree/main/ch05/07_gpt_to_llama
…
But since you already implemented MQA, GQA should be pretty smooth sailing 🙂 -
Attention Mechanism Complexity in Book Explained
By
–
Ha, I hope it didn't scare people away. The attention mechanism is probably the toughest one in the book (but it's necessary as it's otherwise building a car without the engine). In any case, hope you are liking the book overall!
-
LLMs Versus Classic Methods: Knowledge Graphs and Explicit Techniques
By
–
I think these are more used in the more classic, pre-LLM era. LLMs are not typically using those explicitly (unless we are talking about knowledge-graph augmented LLMs)
-
Flexibility in Reasoning LLMs with Preference Tuning
By
–
Oh I see. Yeah maybe depends on how extensive the preference tuning was. But in general it should be possible to achieve the same "flexibility" there as with non-reasoning LLMs.
-
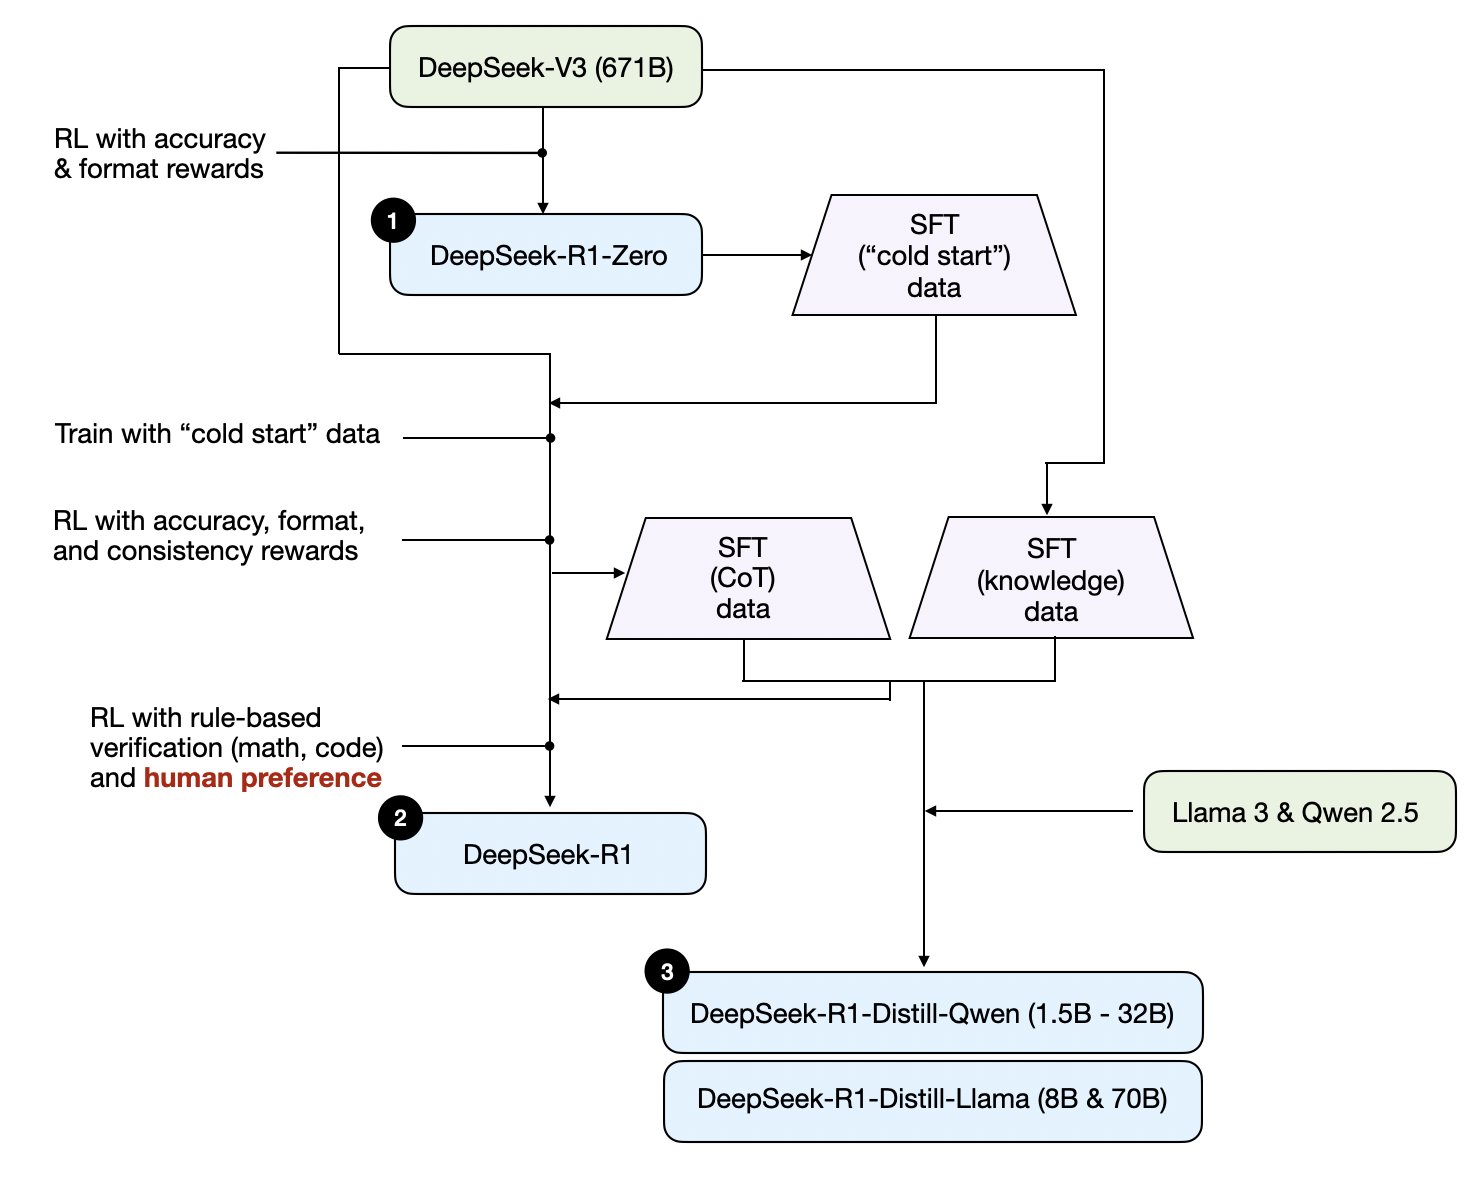
R1 Explicit Preference Reward Training Purpose Discussion
By
–
Why not? I mean R1 even had an explicit preference reward at the end of training; I think that's there exactly for that purpose.
-
Why DPO Remains Popular Over Reinforcement Learning
By
–
"just" RL :). There's a reason why DPO is so popular (even Llama 3 used it )
-
Expert LLMs Don’t Require Reasoning Capabilities
By
–
The one thing to add though is that an "expert" LLM doesn't necessarily have to be a reasoning LLM (you could have one that answers biology Q&As perfectly without reasoning steps involved).
Similarly, you can have a generalist reasoning LLM that is not an expert in one