Here’s the 2025 LLM roadmap 1. Code and train your own LLM to really understand the fundamentals
2. Train models more conveniently using production-ready libraries
3. Learn about the big-picture considerations for real-world LLM/AI apps
@rasbt
-

2025 LLM Roadmap: From Fundamentals to Production Applications
By
–
-
CUDA through PyTorch sufficient for most training scenarios
By
–
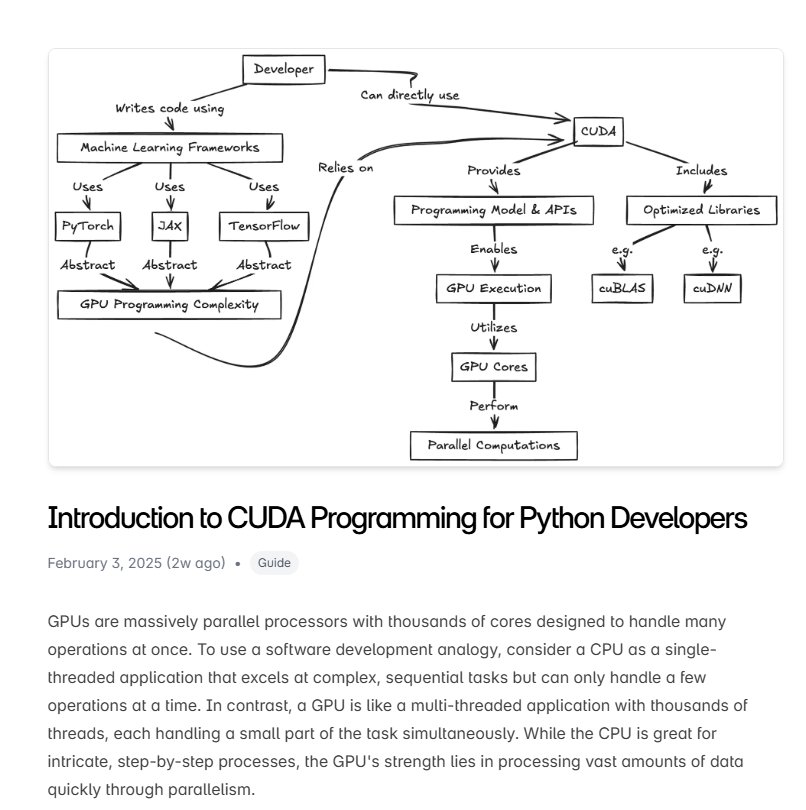
Yes, I mean 99% of the time it's fine to just use CUDA through PyTorch (eager or compiled). If you train million-dollar-expensive LLMs, then maybe writing your own optimized CUDA kernels and custom NCCL would probably worthwhile so you can shave off some $$$ off your training
-
CUDA: NVIDIA GPU C++ Extension Behind PyTorch
By
–
CUDA is basically a C++ extension for NVIDIA GPUs. Basically what PyTorch uses under the hood.
-
CUDA Programming: Mindset Shift for Thread-Based Development
By
–
Fortunately, it's C-inspired. And I kind of know some CUDA basics but yeah, it's a bit of a mindset shift when working with threads I guess.
-
Considering Learning CUDA After 14 Years
By
–
CUDA has been on my to-learn list since 2011.
(Worked in a molecular dynamics lab that used it, but I never really learned it.)
Maybe it's finally time to take the plunge. (But then, I also saw the AI CUDA Engineer announcement yesterday….) -
GPU hours usage confirmation and cluster utilization questions
By
–
Is it confirmed that they used more GPU hours? Sure, they have that 200k GPUs cluster, but did they use all that for the final model run or is it more to facilitate multiple parallel experiments?
-
Phi-4 Model Release: 40% Synthetic Data Composition
By
–
Phi-4! (
https://
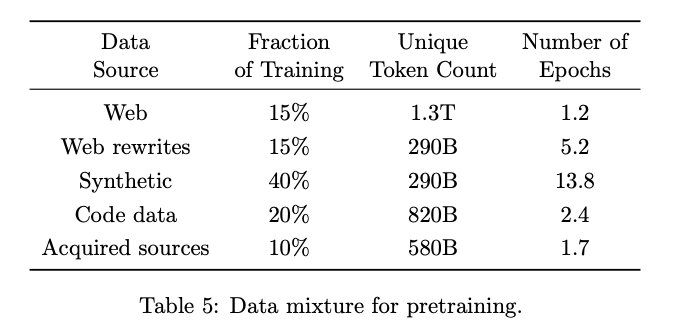
arxiv.org/abs/2412.08905). 40% synthetic. -
SFT and RL Training Pipeline: Limitations of Cold Start Approach
By
–
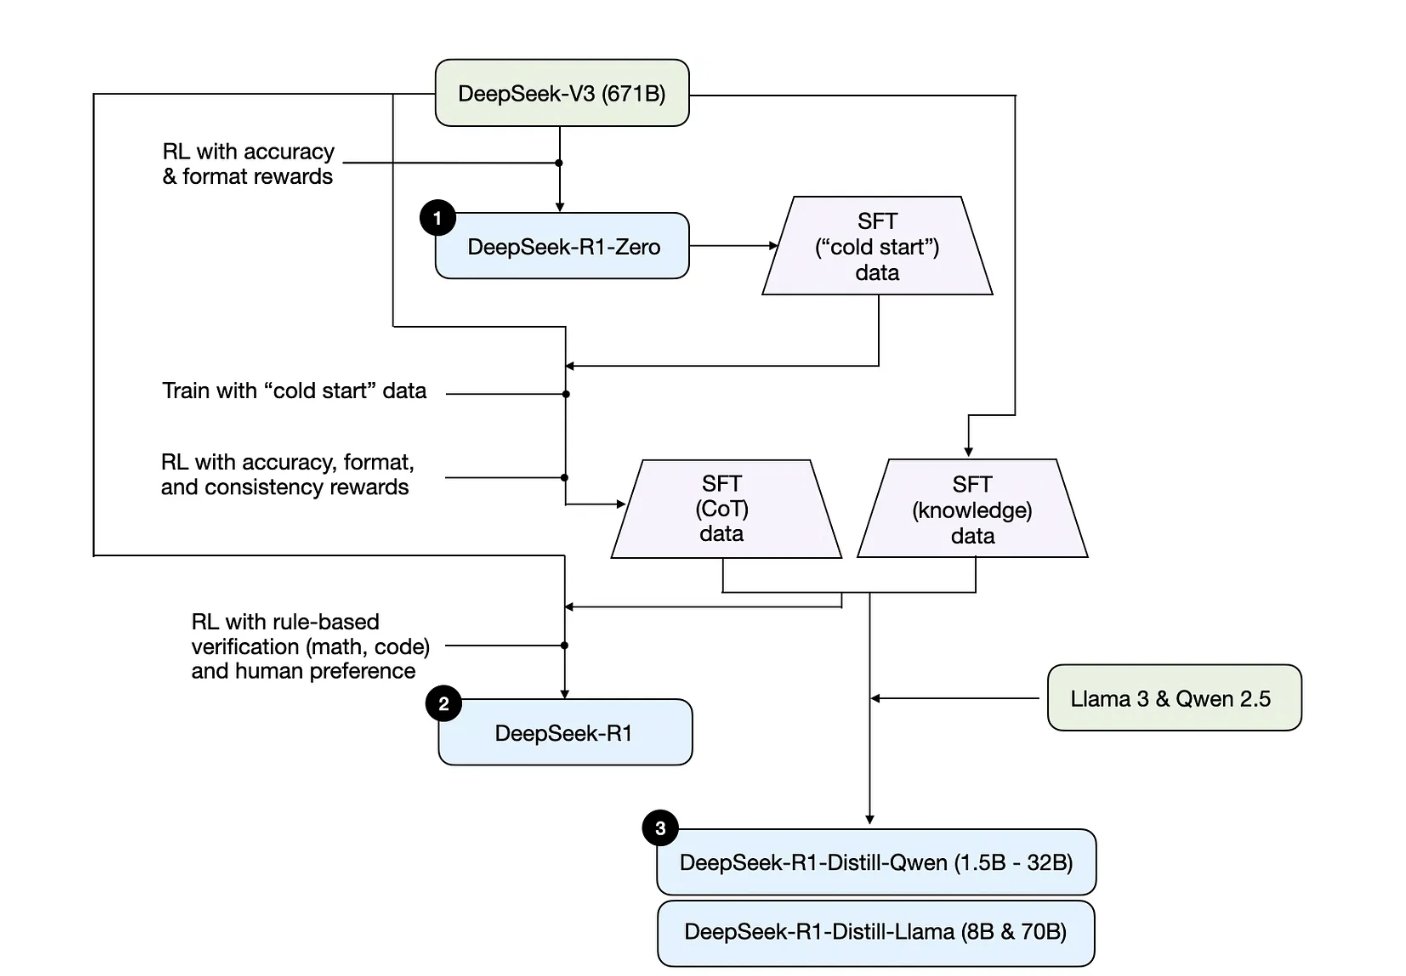
Yes & no. They had SFT (cold start) → RL → SFT (CoT + knowledge) → RL. Not sure if they focused on providing solutions to hard problems via SFT CoT though, because that SFT data was just generated from the previous model (so if that model doesn't solve it, then you are stuck)
-
Alternating SFT and RL Training for Improved Model Policy
By
–
I wonder if alternating SFT (with correct solutions) and RL can help here. I.e, SFT → RL → SFT → RL. SFT would help with improving the initial policy and help making the exploration less random perhaps, plus it expands/refines the search space?
-
Model Performance Comparisons: Size Normalization and Inference Scaling Challenges
By
–
Model performance comparisons are tricky without knowing exact sizes; it could be an apples-to-oranges case. Plus, you can always push numbers with inference scaling. Normalizing by tokens/sec would be more meaningful.