Interesting. Maybe it's one with thinking always-on and one always-off. Similar to the IBM Granite model with the toggle. And on the Claude website, maybe they have another "small" LLM routing the user prompt / controlling that toggle.
@rasbt
-
Inference-Time Scaling: Prompt Modification vs Sampling and Verification
By
–
*One might argue that modifying prompts (eg classic "think step by step") counts as inference-time scaling due to the extra output tokens. So in that sense they use inference-time scaling.
I should have been more clear: I meant specifically sampling techniques + using a verifier. -
Compute Constraints Led to LoRA and DPO Development
By
–
Compute constraints brought us LoRA and DPO
-
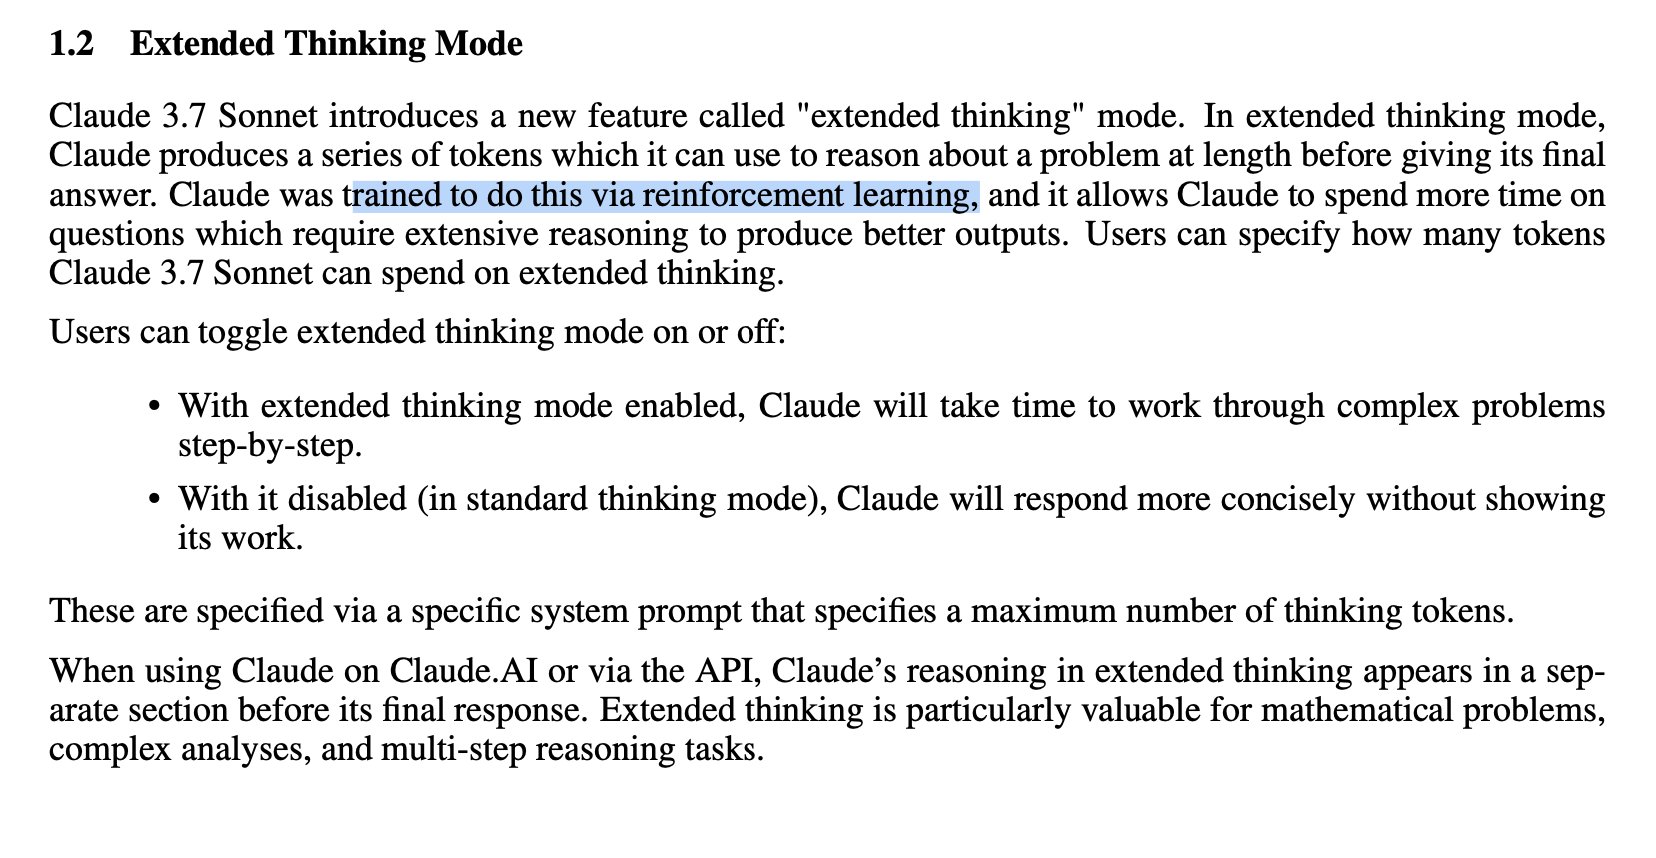
System Card Analysis: Reasoning Implementation via RL Toggle
By
–
What a week! Just read the system card, and it looks like they implemented reasoning via RL. My guess is the thinking on/off toggle is likely a system prompt. I wonder if they added inference-time scaling like o1 or if it’s just RL like R1. Anyone found details on that?
-
Fast-Track Deep Learning with PyTorch Appendix Resource
By
–
That's a good question. I'd say more background is always helpful, but probably not essential. I have a ~40-page fast-track to deep learning with PyTorch in Appendix A that might get you up to speed (might be a steeper learning curve, but might be more respectful of your time).
-
Skepticism about Apple’s AI capabilities and Siri improvements
By
–
I am a bit skeptical. Maybe it's because Siri was neglected for so long. I think too that they have great talent but they also operate under more constrains, so I don't expect their LLMs to be quite as good as the ones from the current main LLM developers.
-
Claude 3.5 Sonnet naming confusion clarification
By
–
yes, also known as "new Claude 3.5 Sonnet", which I always found super confusing.
-
Apple’s Limited AI Capabilities and LLM Competitive Disadvantages
By
–
oh yes, of course they are limited. They were a bit late to the party. They are also not known for AI/ML work (see Siri being notoriously bad). That being said, I doubt they will have competitive large-scale LLMs. They don't have the server capacities for that at that user
-
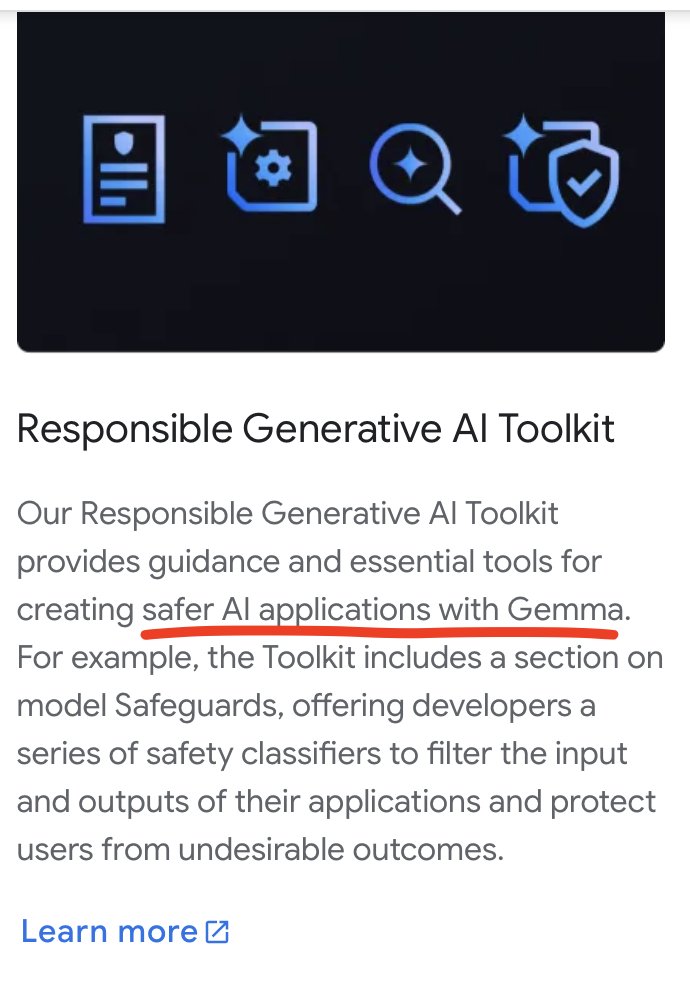
Major LLMs Show Similar Safety Measures Despite Company Marketing Differences
By
–
Yeah. To be fair, every major company does the "safer" marketing. Yet, as a end-user the flag ship LLMs feel little different on the "safety" spectrum. Just an observation.
-
Contradictory Safety Marketing Claims Among AI Chatbots
By
–
Maybe to add a bit more context. What I mean is, based on the marketing, Claude is safer than ChatGPT because it has more content moderation guardrails, and Grok is safer than ChatGPT because it has fewer guardrails? Please make it make sense