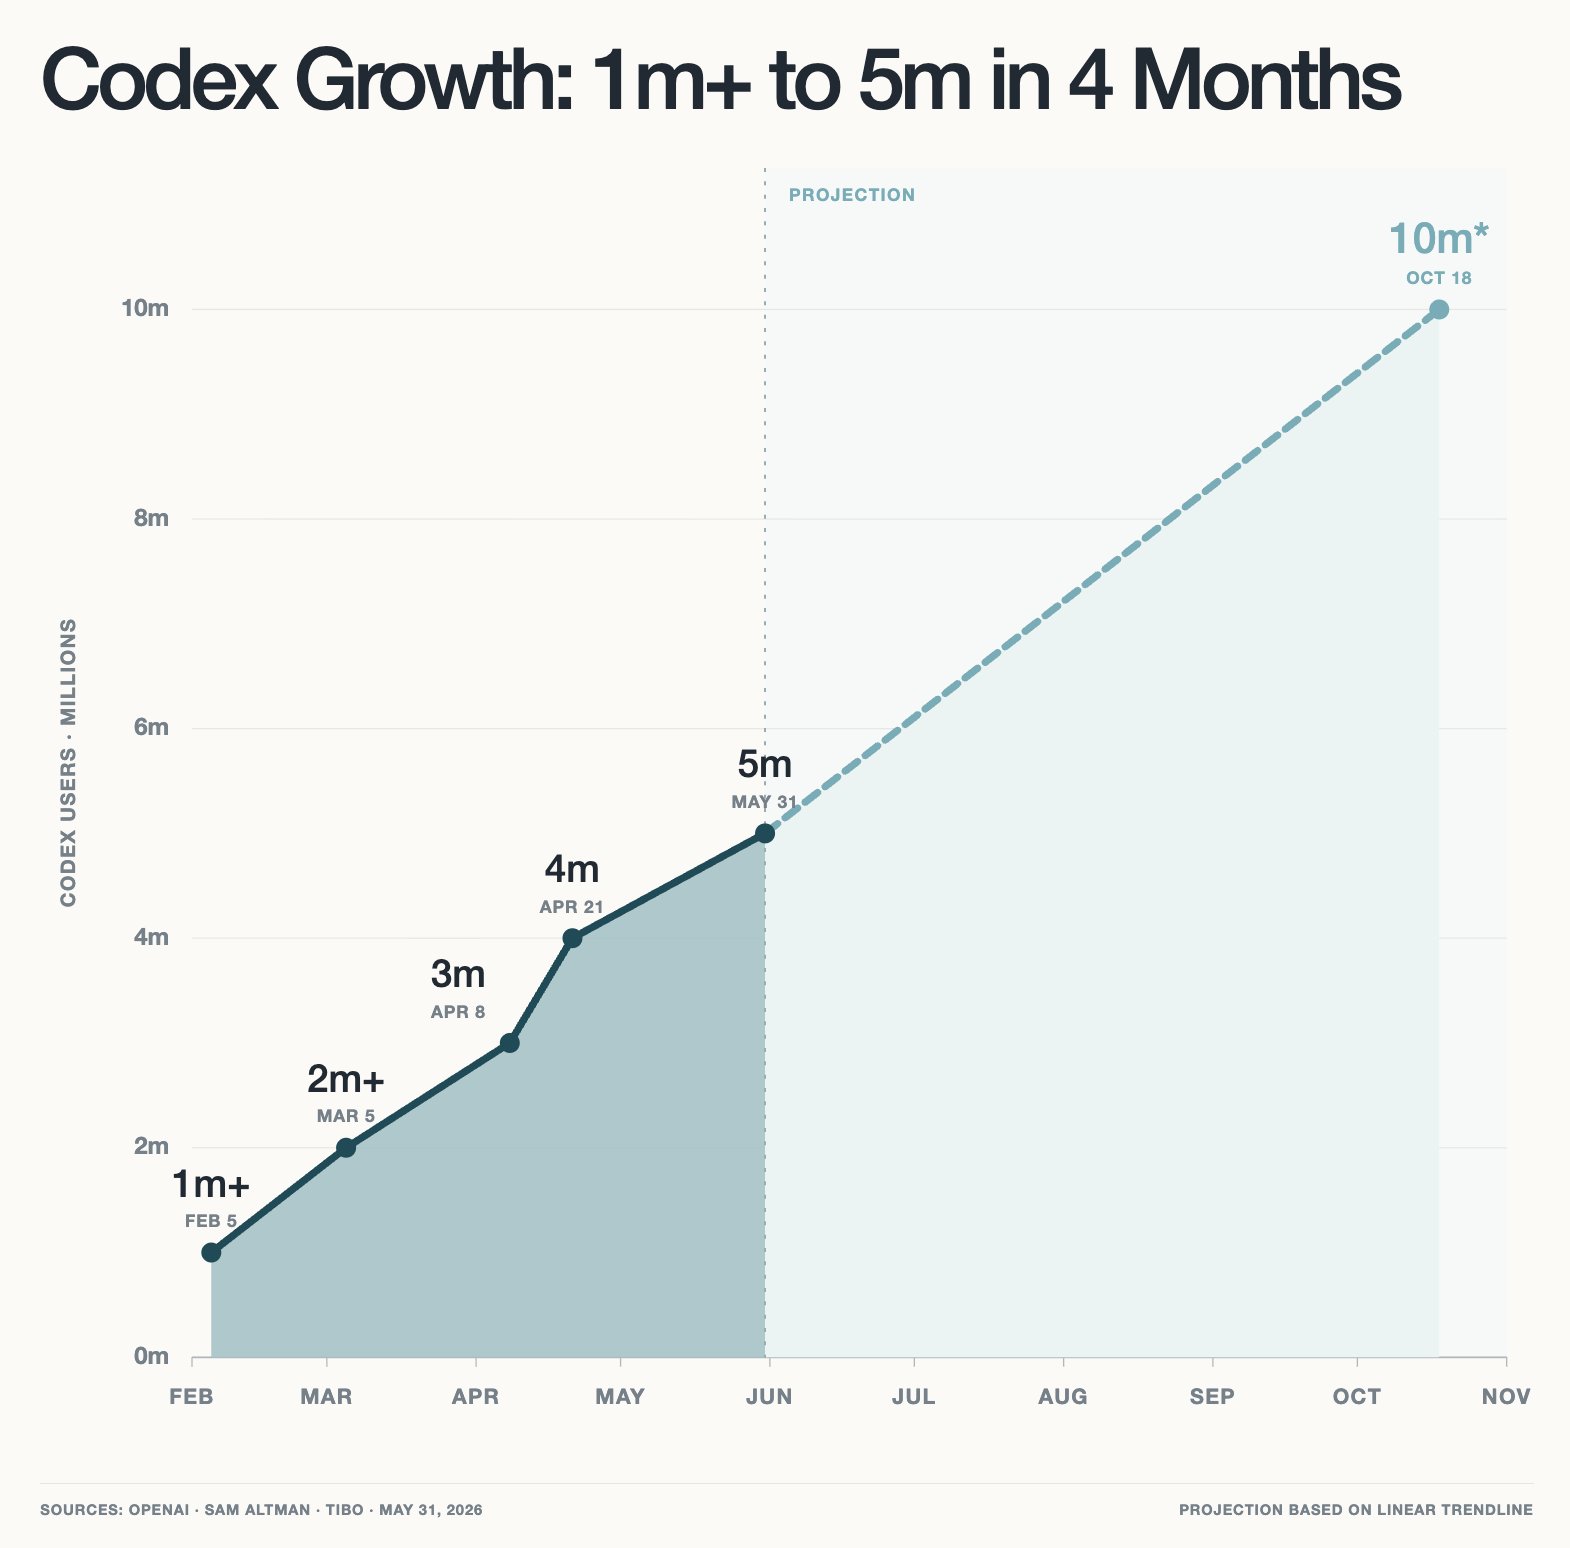
Codex user growth, if this trend continues, it would be 10m by October
@petergostev
-
Self-recursive improvement, not unsafe release to public
By
–
I think it is more to do with self recursive improvement (I.e. It isn't yet on that path) rather than unsafe to release to the public
-
Wondering how a mini model beats 5.5
By
–
I did wonder, hard to explain how a mini model would do better than 5.5
-
OPQA Benchmark: 20 Real Engineering Bottlenecks from OpenAI
By
–
OpenAI-Proof Q&A (OPQA) is a benchmark of 20 real research and engineering bottlenecks that OpenAI teams encountered internally, each taking more than a day to solve. A model is given relevant code, logs, and experiment artifacts, then asked to identify and explain the root
-

OpenAI benchmark scores stagnant since launch
By
–
OpenAI has this interesting benchmark of OpenAI's real engineering bottlenecks, where the scores have not moved since launch over a year ago. Some earlier models did even better than 5.5. I wonder what's going on here.
-
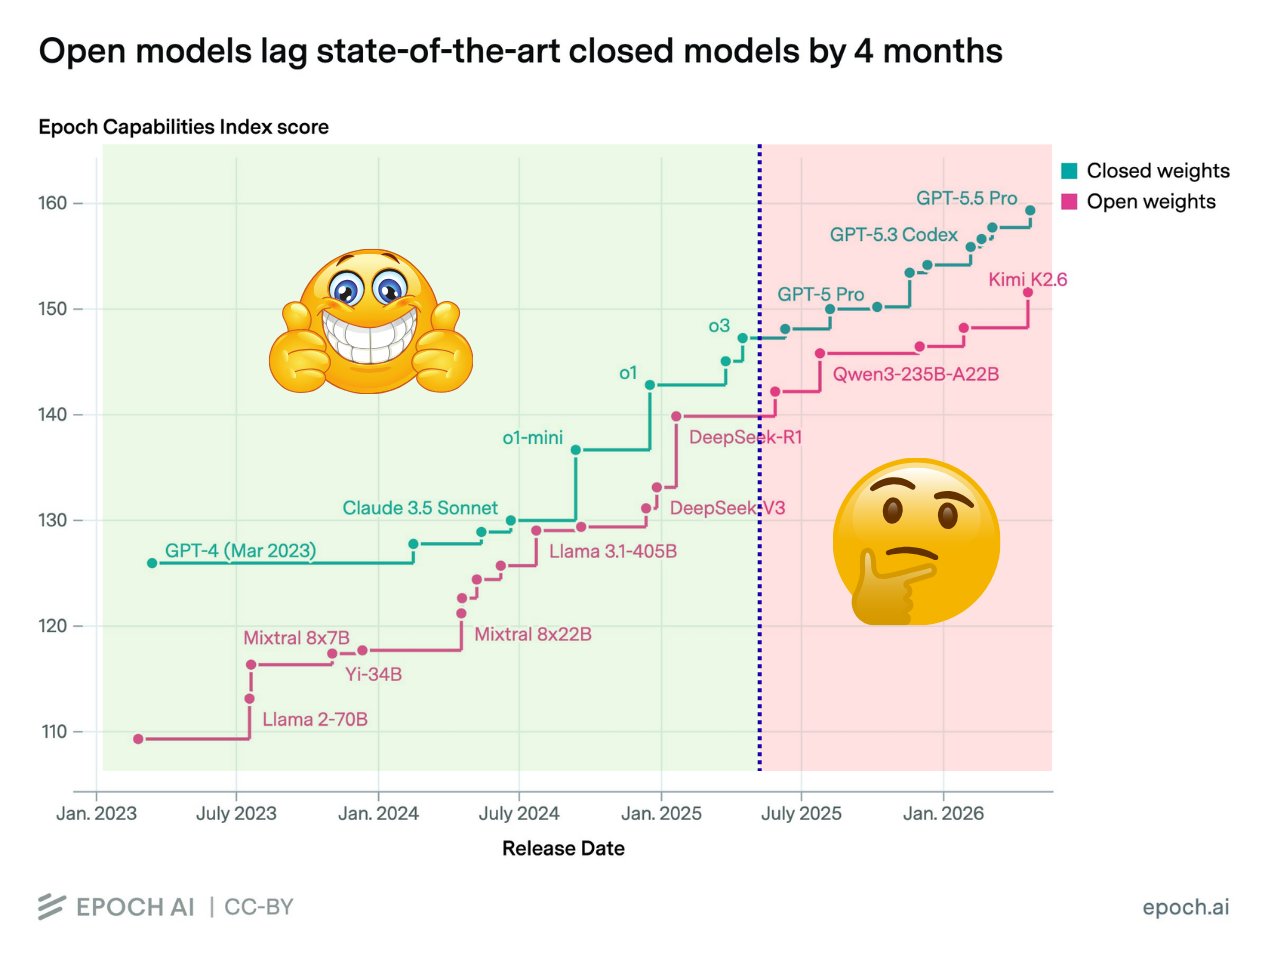
Opinion on DeepSeek R1, o1, and suspicious o3 benchmarks
By
–
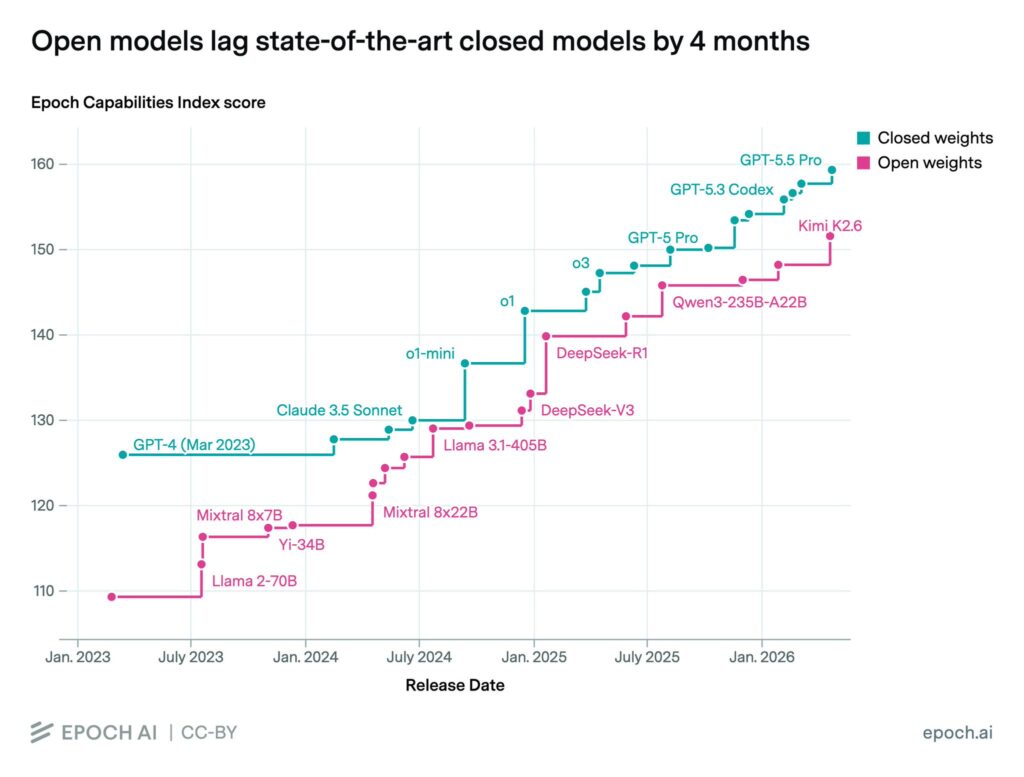
My personal vibes based opinion on this gap – at DeepSeek R1 level I believe this was real – o1 and r1 were not that far apart. From o3 onwards, I think there's something fishy going on with the benchmarks. Open models are not bad and certainly getting better, but the utility
-

Model Release Cycles: Anthropic & OpenAI Speed Advantage
By
–
The model release cycles from Anthropic & OpenAI are genuinely insane, previously we had 6-12 months between updates, now models are released every 1.5 months. This is an under-appreciated reason why Anthropic & OpenAI are in the lead. Google's releases are not as fast,
-

Opus 4.8 tops BullshitBench after 4.7 dip, needs harder questions
By
–
Top notch result from Opus 4.8 on BullshitBench, after a slight dip with 4.7. Need to start thinking of some new harder questions soon!
-

Anthropic Acceleration: Model Release Cycle Shortening Trend
By
–

Anthropic released the next version sooner than I thought – the trend is accelerating – from 50-70 days before, down to 42 days since Opus 4.7
-
Devin AI Productivity Metrics: Calibrating Capability Claims
By
–
Explanation & chat link: "I digitized the curve from the image and used Cognition’s “>10x since start of 2026” claim to calibrate the relative shape. Then I anchored the absolute scale using the public “~1.1M PRs shipped with Devin” figure by Feb 2026: the chart area up to then