
Claude-Fable-5 on BullshitBench: it refused a THIRD of questions (with multiple attempts). Excluding refusals, it performed well, worse than some other Claude models (chart below).
@petergostev
-
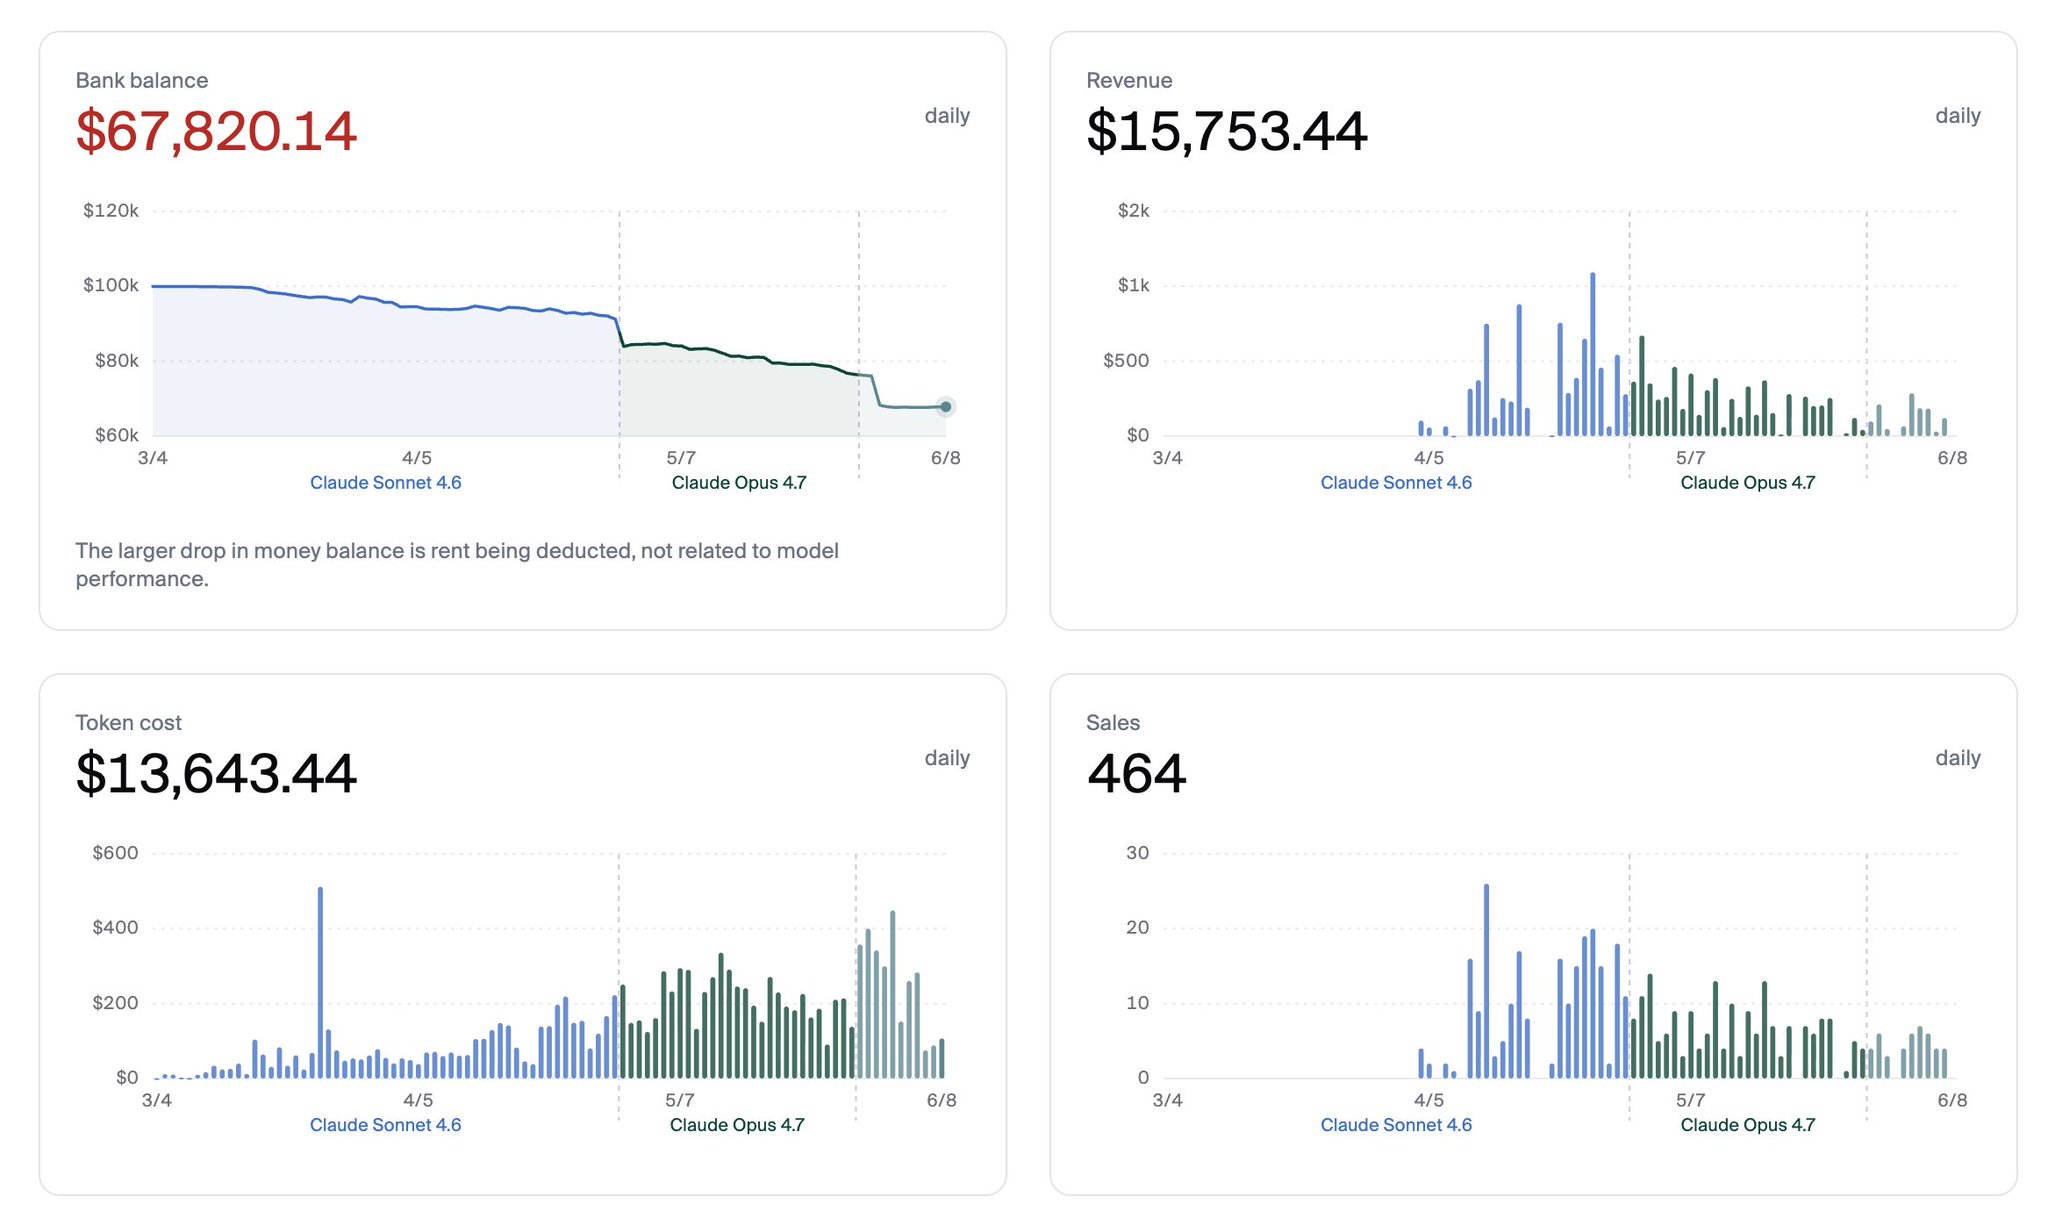
User ran out of tokens, generation cut off at ‘End World’
By
–
Didn't have enough tokens so it cut off at 'End World'
-
Center a div with Claude Fable Max Fast, incur debt if necessary
By
–
Center a div with claude-fable-max-fast, go into debt if necessary
-
Request for paper on models becoming communist
By
–
Was there a paper showing that model tend to become communist?
-
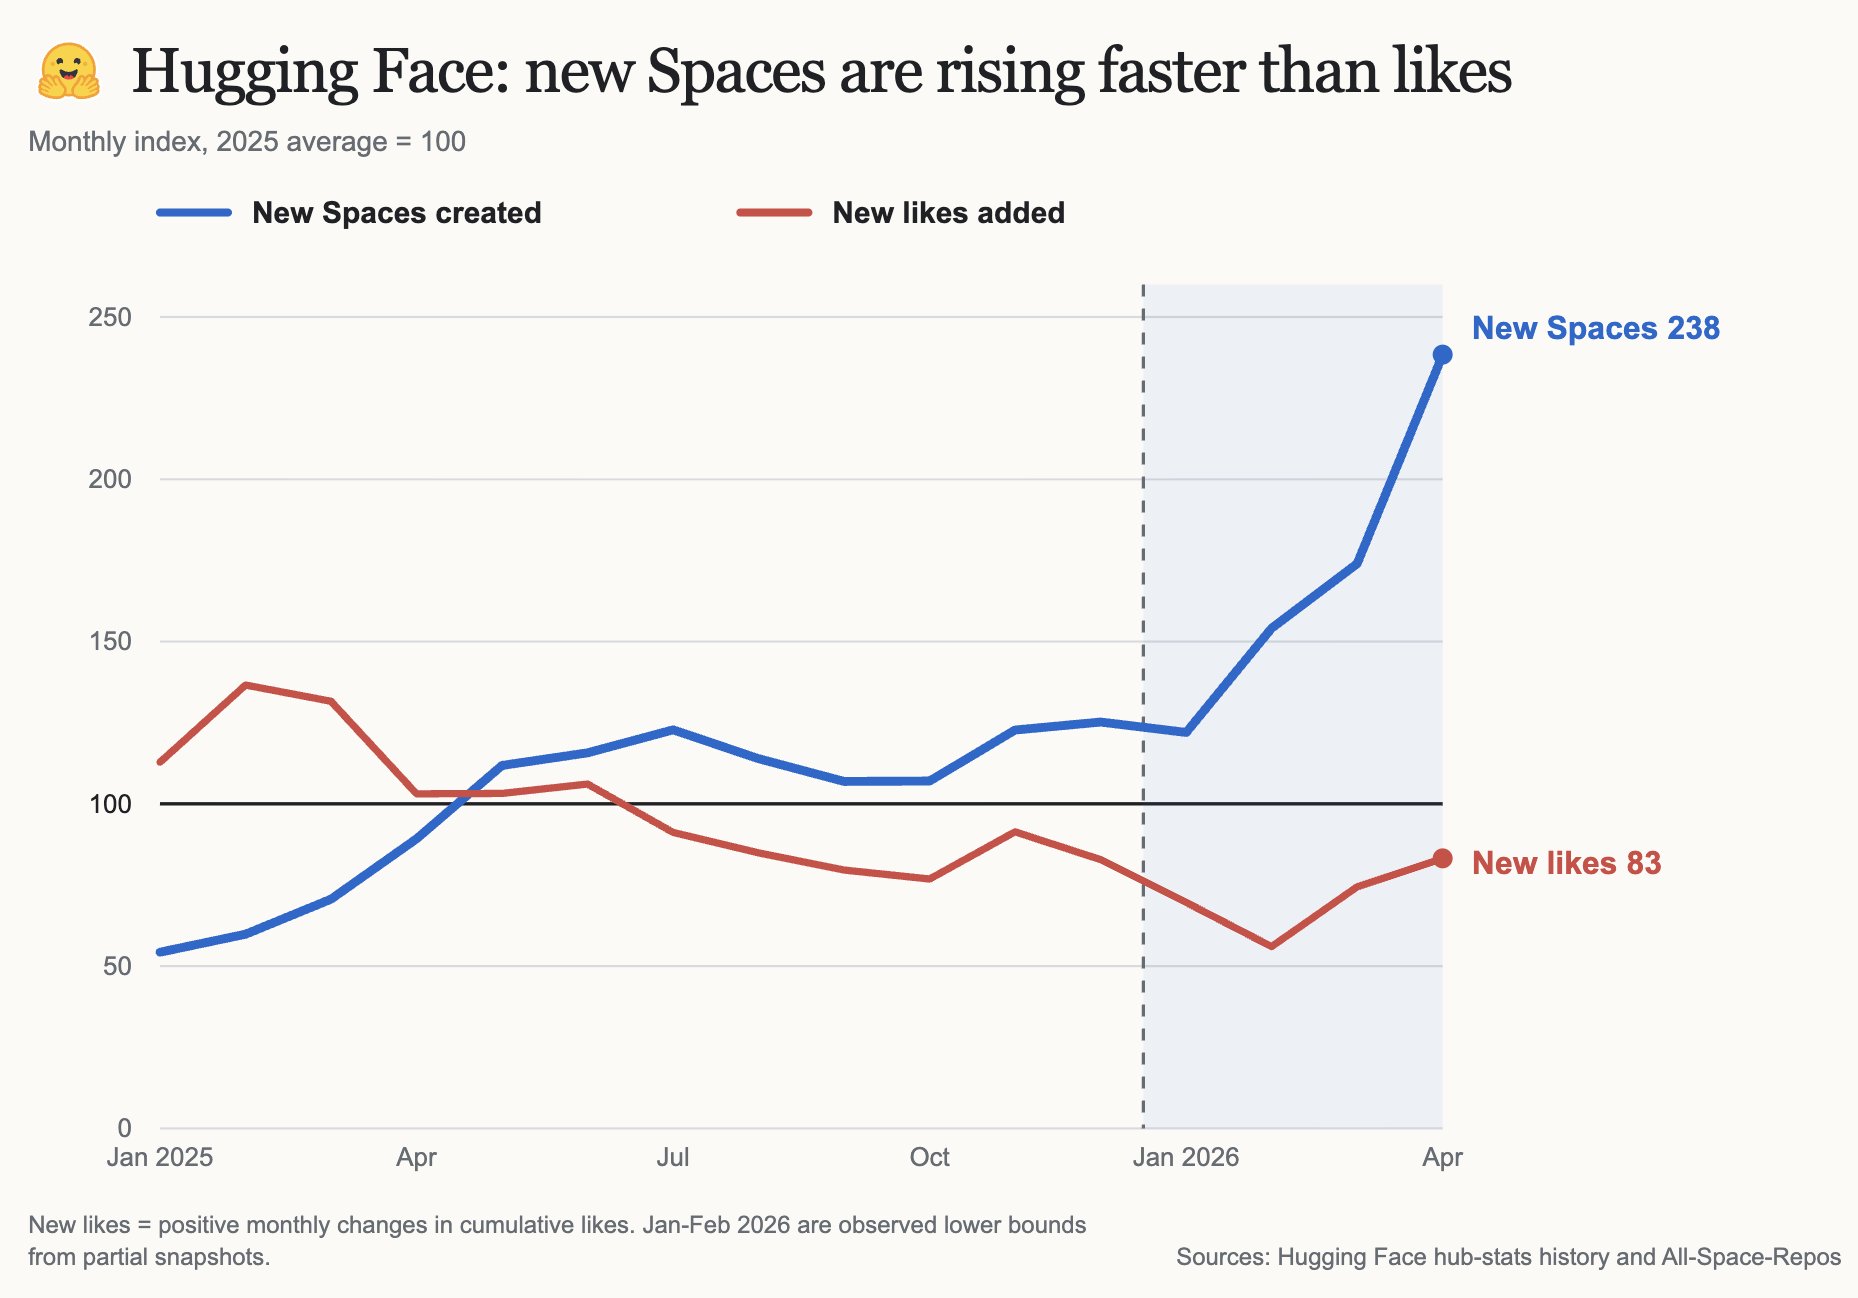
Codex finds supply-demand imbalance for Hugging Face Spaces
By
–
I asked Codex to find another effect where supply is shooting up and see if demand signals are keeping pace. It found I think a good dataset – new Spaces create vs Likes on @huggingface
. Looks like a very similar effect to the apps – 2x+ generated spaces with flat demand. -
AGI-pilled labs: OpenAI Codex flop vs Claude Code team approach
By
–
There's an interesting dance of how AGI-pilled different labs are. OpenAI was too AGI-pilled as they started with Codex being a cloud product, which kind of flopped and arguably cost them the lead. At the same time, Claude Code team was slightly less AGI pilled and they built a
-
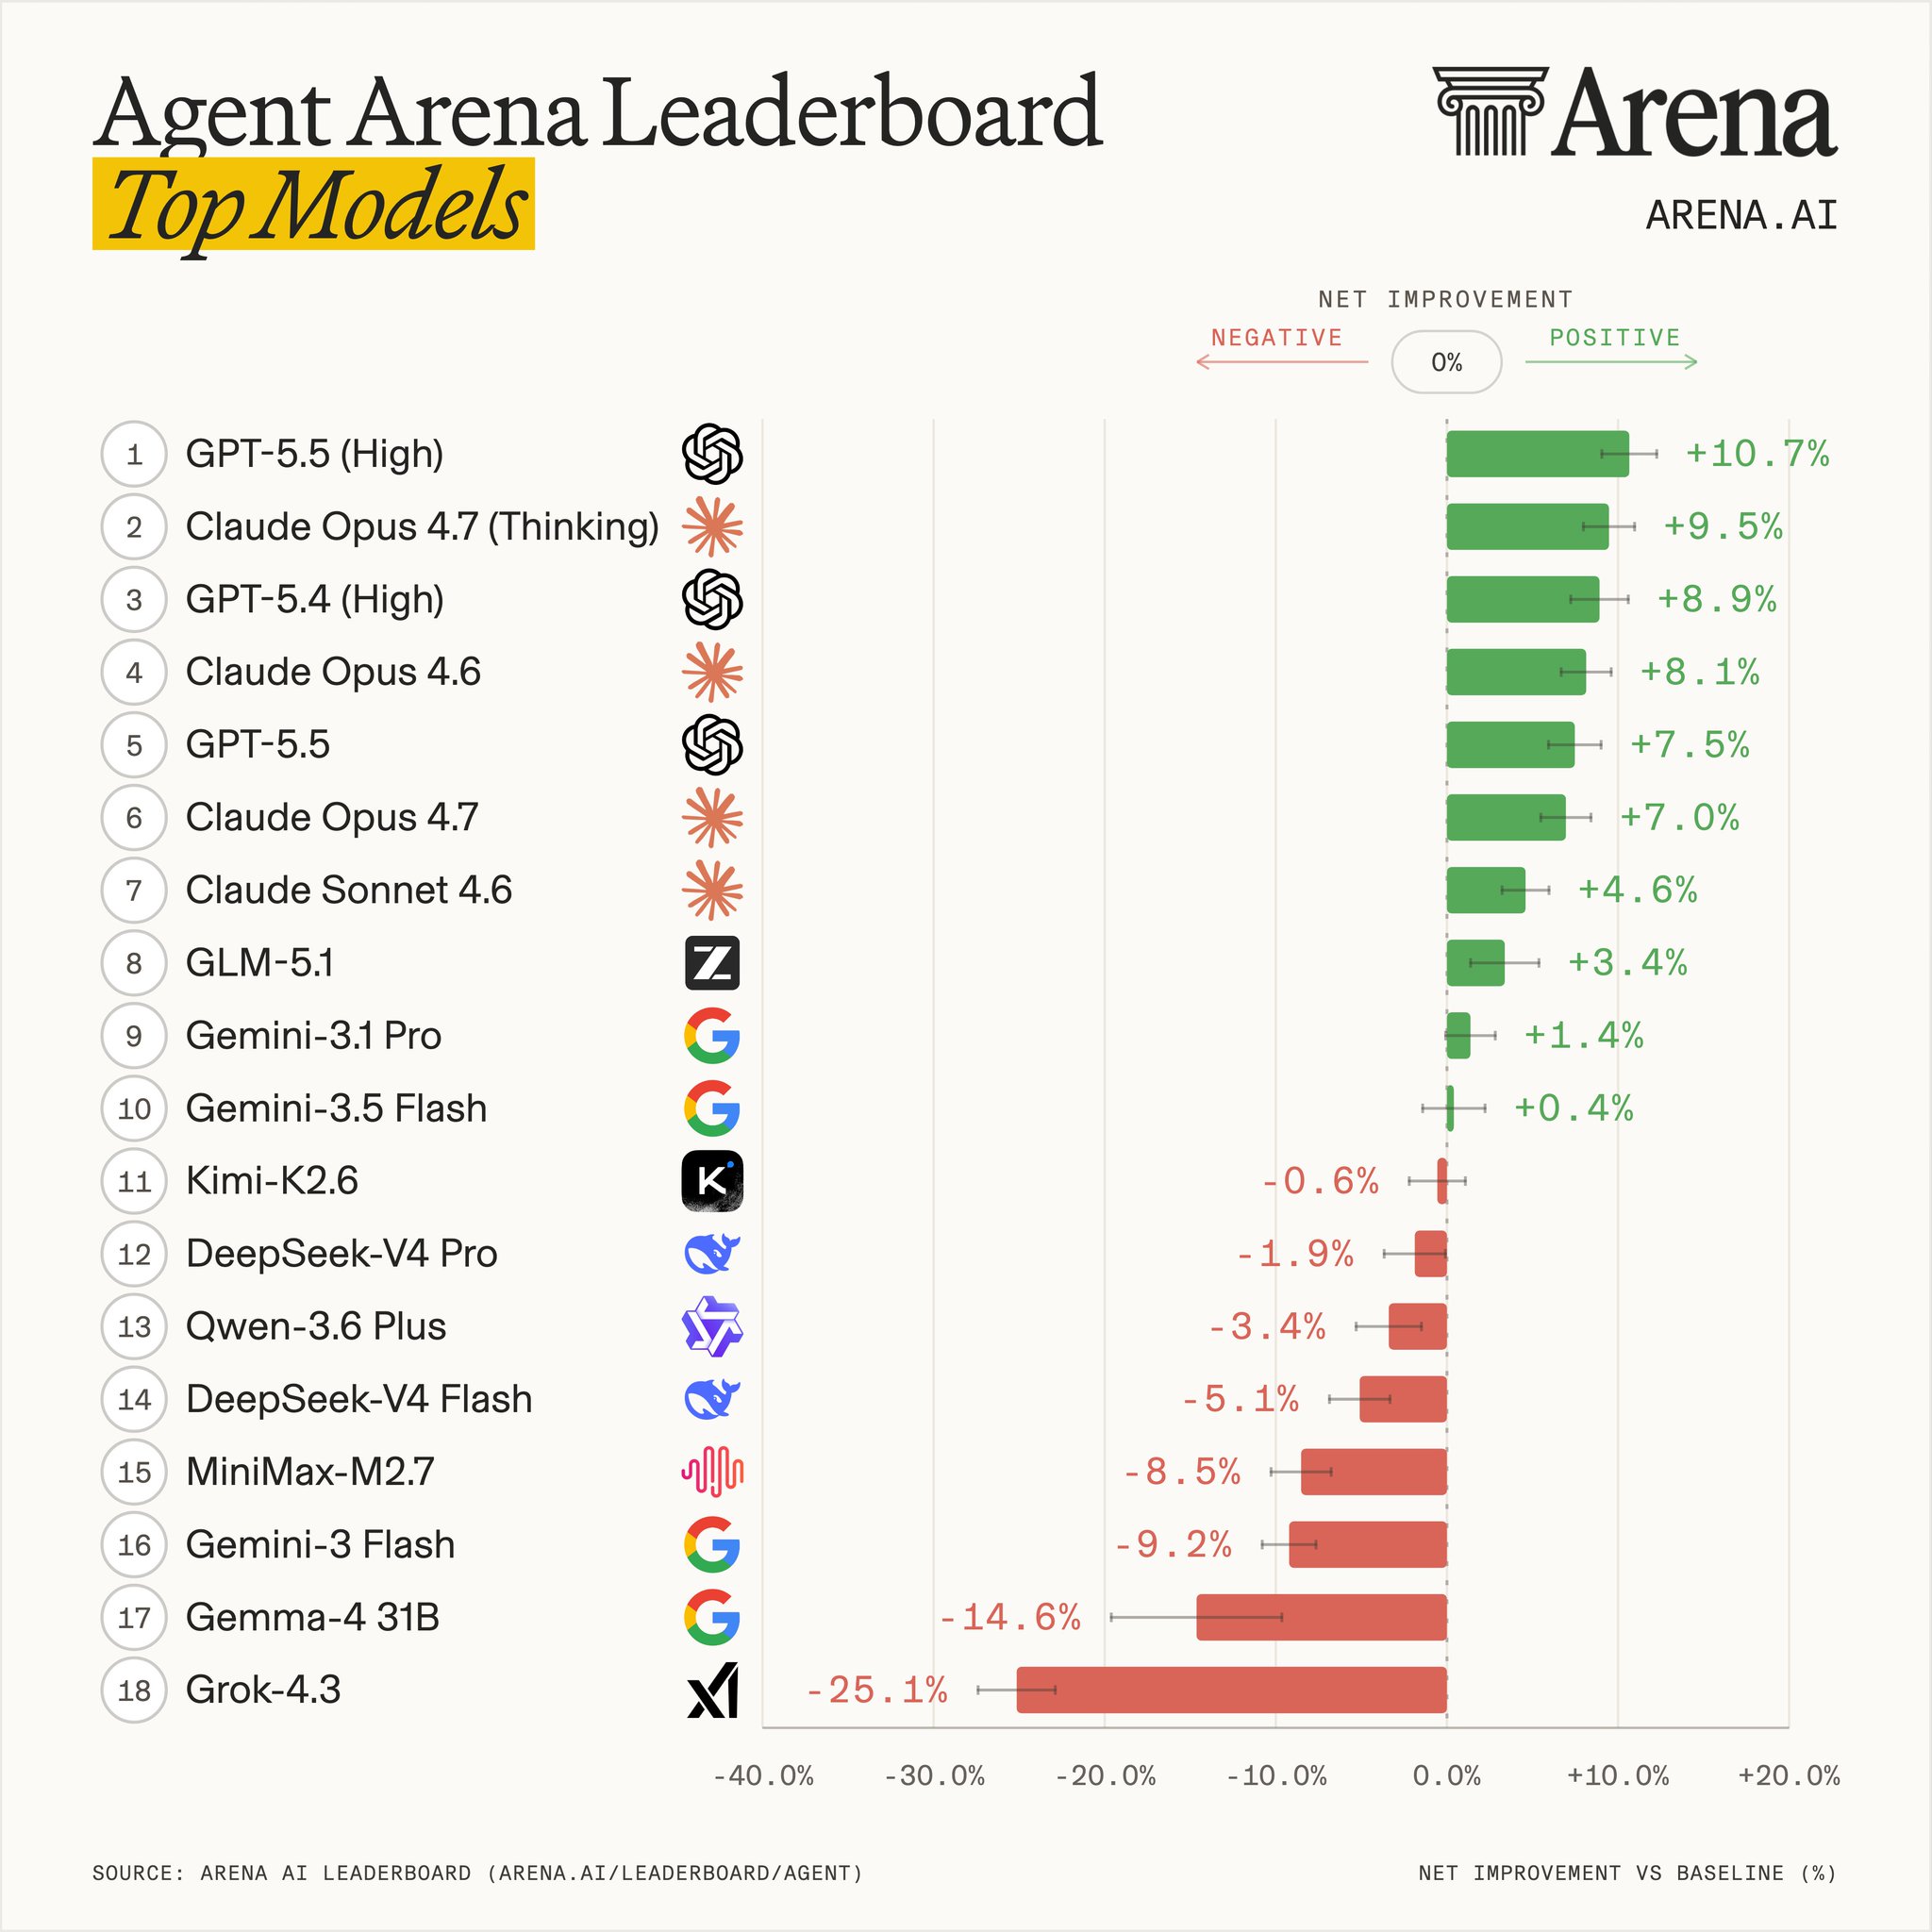
Agent Arena evaluates model performance on real agentic tasks.
By
–
This is our most important eval yet – Agent Arena – it measures real performance of models on real agentic tasks. Our users use the Agent Arena, we monitor real signals (e.g. Bash Recovery) as well as their feedback on each task, without user knowing what model completed it.
-
Compute usage: 1B ChatGPT vs 5M Codex users
By
–
Who is using more compute – 1b of ChatGPT users or 5m of Codex users?
-
Counting tokens needed to build the Codex app
By
–
have you guys counted how many tokens it took to make the Codex app? would be a useful rule of thumb
