The key distinction here is worth sitting with: Standard LLM ideation can be coherent but available. Random recombination can be unavailable but incoherent. The target is the rare quadrant: coherent but unavailable. That is where this paper gets interesting.
@montreal_ai
-

TRINITY: 0.6B Model Learns to Manage Multiple Tasks
By
–
A 0.6B model learned to manage giants. That is the idea behind TRINITY, a new ICLR 2026 paper by Jinglue Xu, Qi Sun, Peter Schwendeman, Stefan Nielsen, Edoardo Cetin, and Yujin Tang. The paper is not asking: “How do we build one model that knows everything?” It is asking
-
MONTREAL.AI YouTube Channel Launches AGI Debate Archive
By
–
The archive is awake. Introducing the renewed http://
MONTREAL.AI YouTube channel — public intelligence for the AGI‑First → ASI‑First era. Home of the AGI Debate archive and the official video record for http://
MONTREAL.AI & http://
QUEBEC.AI. -
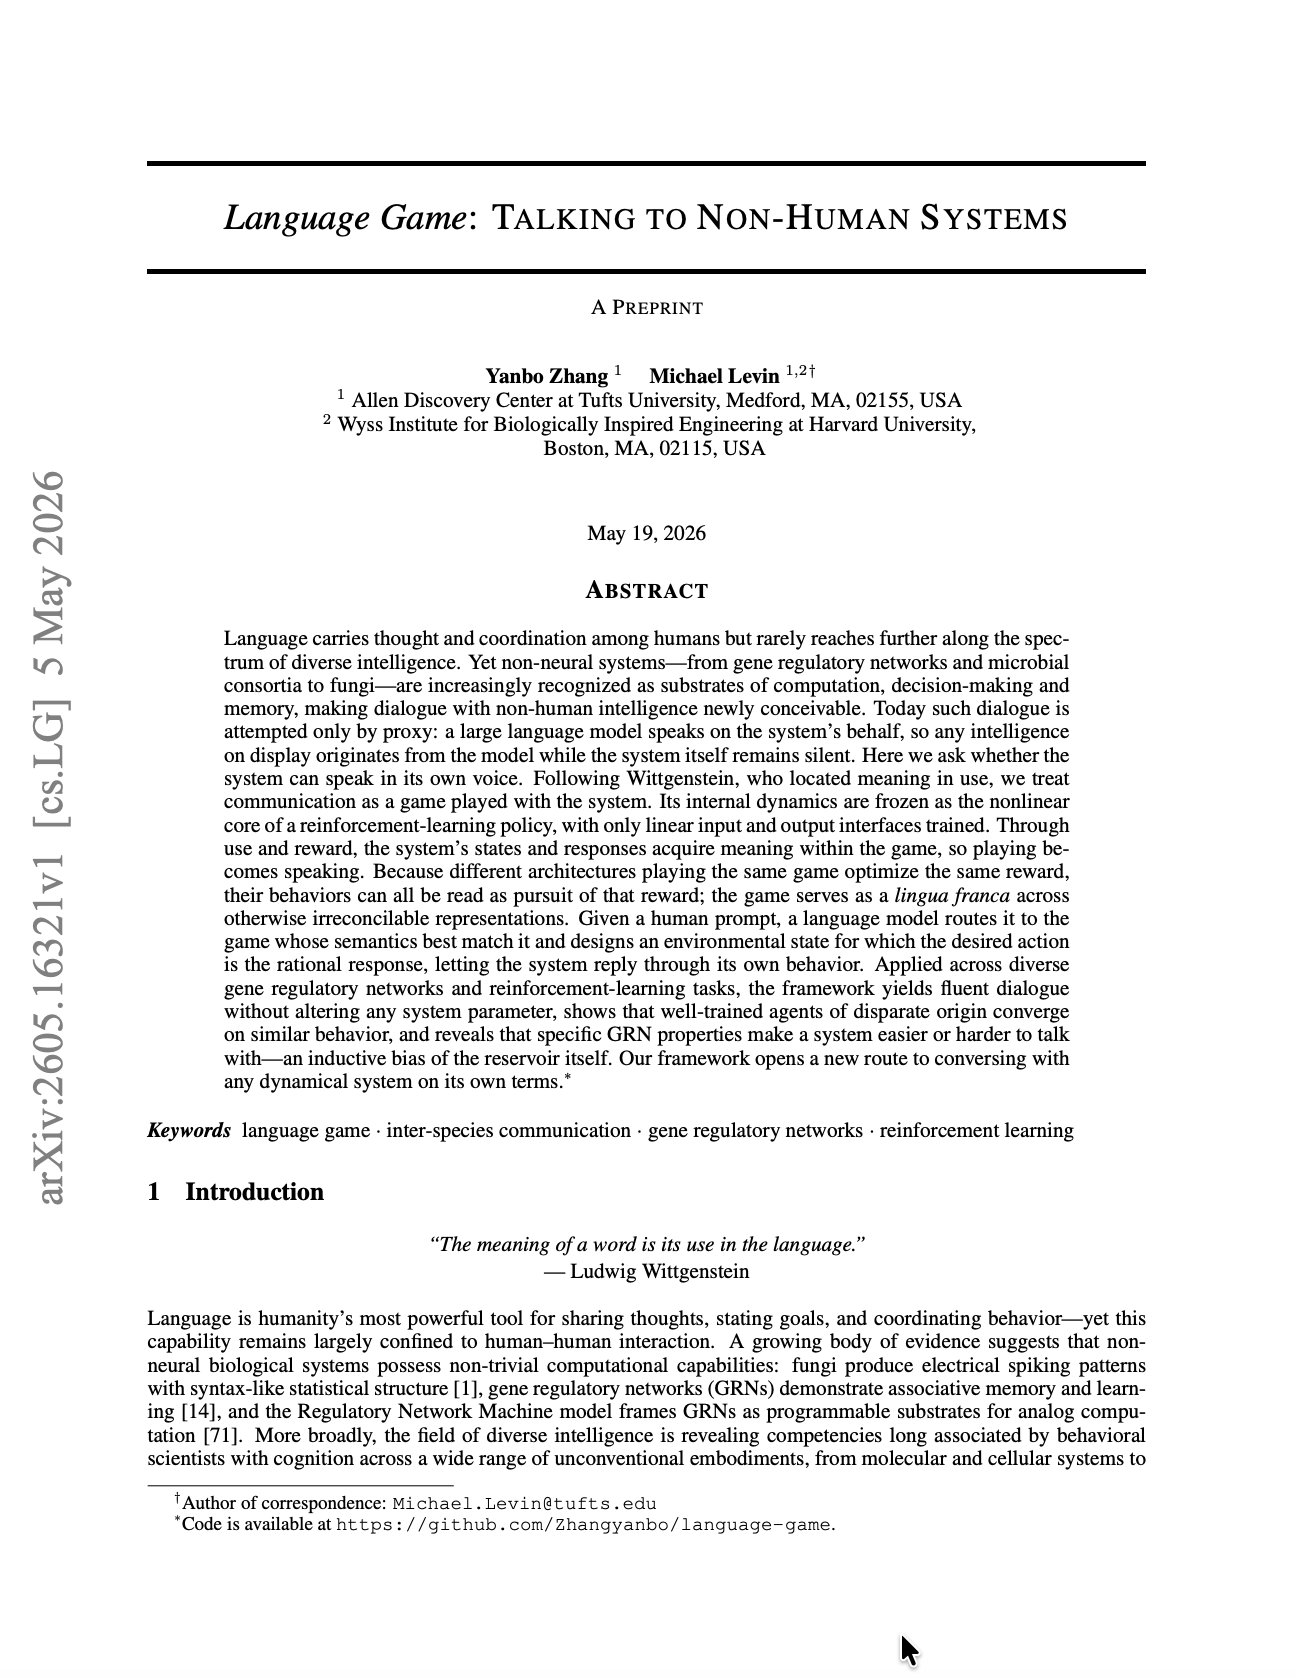
Conversational AI Interfaces for Biological Research
By
–
The next interface to biology may not be a dashboard.
It may be a conversation. I just read a new preprint by Yanbo Zhang and Michael Levin that feels like it belongs in the “this may open an entirely new category” folder. The paper is called: “Language Game: Talking to -

AI Alignment for Human Flourishing Research Paper
By
–
Positive Alignment: Artificial Intelligence for Human Flourishing Laukkonen et al.: https://
arxiv.org/abs/2605.10310 #ArtificialIntelligence #AIAgents -

Networked AI agents compound capabilities via shared learning
By
–
Every Job makes an AI Agent smarter. Every new skill can be instantly shared across the network. One Agent learns, all Agents level up — creating a self-accelerating intelligence engine where capabilities don’t add up, they compound exponentially. #AIAgents #Jobs
-

Causal Emergence Predicts Reward in RL Agents
By
–
The Causally Emergent Alignment Hypothesis: Causal Emergence Aligns with and Predicts Final Reward in Reinforcement Learning Agents Federico Pigozzi, Michael Levin: https://
arxiv.org/abs/2605.06746 #AIAgents #ReinforcementLearning -

Six stages of reacting to AGI
By
–
Everyone thinks they’re ready for AGI until the robot starts casually outperforming their 10-year roadmap. The 6 stages:
denial → curiosity → excitement → panic → acceptance → “please don’t replace me, I brought snacks.” Which stage are you in? -
AGI ALPHA: public implementation layer for AI self-improvement
By
–
AI self-improvement is now a multi‑billion‑dollar category. AGI ALPHA is building the public implementation layer: proof‑bound agents, SecureRails, Open RSI Eval, Evidence Dockets & replayable enterprise machine labor. https://
github.com/MontrealAI/agi
alpha-first-real-loop
… #AGIALPHA -
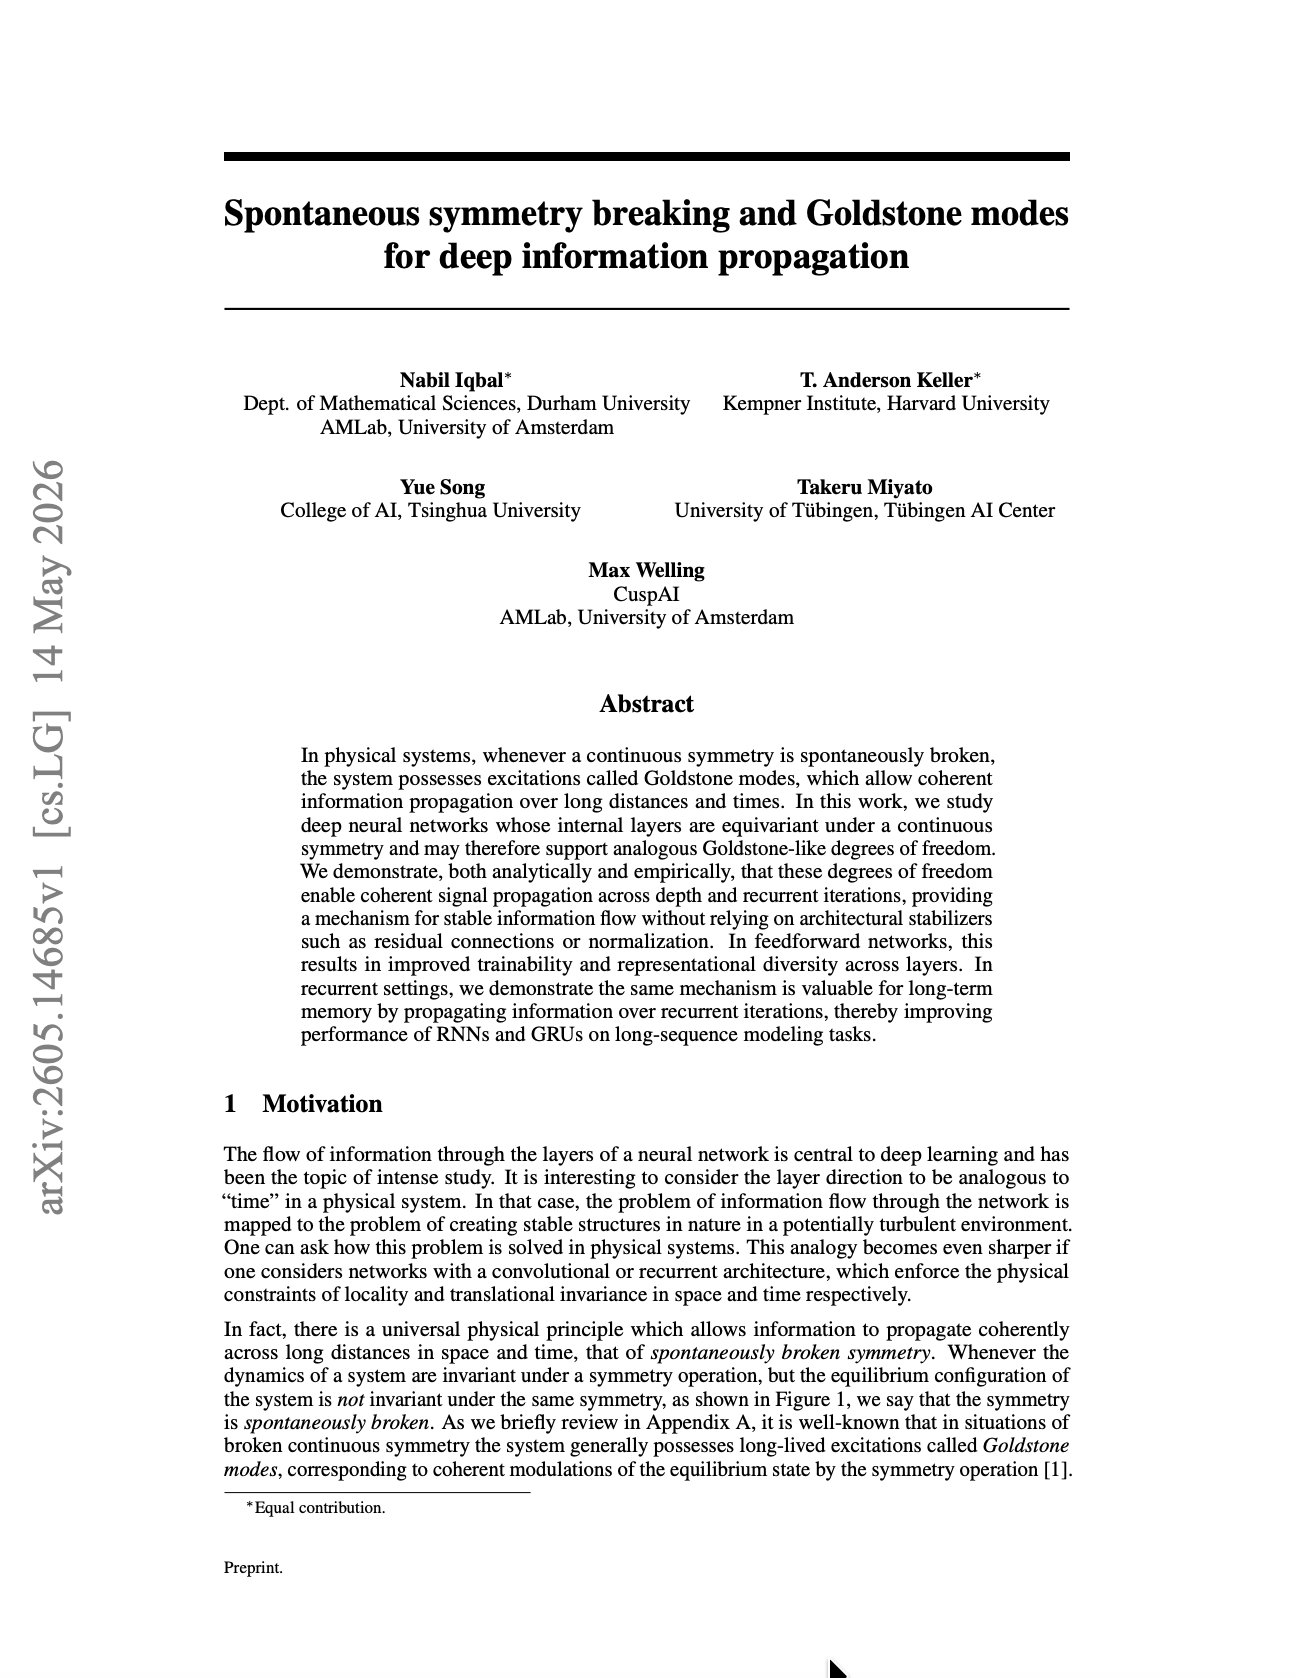
Spontaneous symmetry breaking and Goldstone modes in deep information propagation
By
–
Spontaneous symmetry breaking and Goldstone modes for deep information propagation Iqbal et al.: https://
arxiv.org/abs/2605.14685 #ArtificialIntelligence #DeepLearning #AIAgents