Thanks for llama.cpp and congrats to you, @ngxson
, and the rest of the team!
@maximelabonne
-
Team Congratulations for llama.cpp Open Source Project
By
–
-
24B Model Running in Browser with WebGPU Technology
By
–
24B model running in your browser! https://t.co/dorx4Ux2x7
— Maxime Labonne (@maximelabonne) 25 mars 202624B model running in your browser! Xenova (@xenovacom) WebGPU is INSANE! 🤯 Here's a 24B parameter model running locally in a web browser, at a blazing ~50 tokens/second on my M4 Max. ⚡️ It's the largest model we've ever run with Transformers.js… and we're not stopping here. Big announcement soon. — https://nitter.net/xenovacom/status/2036908326462665211#m
→ View original post on X — @maximelabonne, 2026-03-25 21:10 UTC
-

Hack #05: AI in Space Hackathon Registration Now Open
By
–
AI is beginning to move beyond the clouds… Registration is open for Hack #05: AI in Space, in collaboration with @DPhiSpace. A hackathon exploring what becomes possible when AI operates closer to satellites, orbital systems, and space-based data. For developers, researchers, and builders interested in the future of AI in space. Register → luma.com/n9cw58h0 Learn more → hackathons.liquid.ai 🚀 Join the conversation → discord.com/channels/1385439…
→ View original post on X — @maximelabonne, 2026-03-19 15:04 UTC
-
Congratulations on Built-in Data Pipeline Feature
By
–
Oh that's really cool, I love the built-in data pipeline. Congrats guys!
-
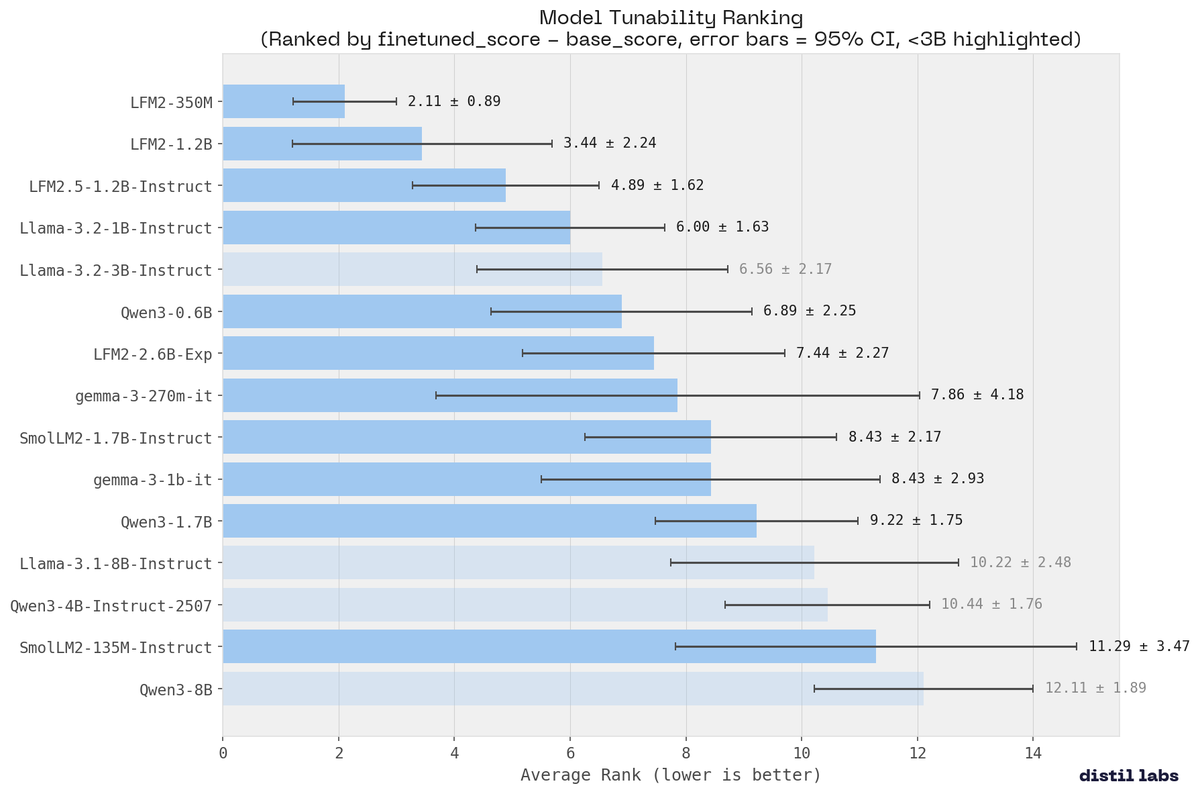
LFM2 Models Dominate Fine-Tuneability Benchmark Among Small LLMs
By
–
Very interesting results about the fine-tunability of different models. 👀 LFM2 is more flexible than alternatives. It also confirms some common knowledge about RL degrading fine-tuneability. Jacek Golebiowski (@j_golebiowski) We benchmarked 15 small language models across 9 tasks to find out which one you should actually fine-tune. The most surprising result: Liquid AI's LFM2-350M ranked #1 for tunability. 350M parameters, absorbing training signal more effectively than models 20x its size. The entire LFM2 family swept the top 3 spots. No other architecture came close. LFM2-350M: avg rank 2.11 (±0.89) LFM2-1.2B: avg rank 3.44 LFM2.5-1.2B-Instruct: avg rank 4.89 That tight CI means it's consistent across every task type, not just a few lucky benchmarks. — https://nitter.net/j_golebiowski/status/2033611679645266280#m
→ View original post on X — @maximelabonne, 2026-03-16 19:06 UTC
-
Real-time video captioning in browser with LFM2-VL WebGPU
By
–
Real-time video captioning in your browser, powered by LFM2-VL
— Maxime Labonne (@maximelabonne) 13 mars 2026
Another exceptional demo by the great @xenovacom! https://t.co/KRvDEpj138Real-time video captioning in your browser, powered by LFM2-VL Another exceptional demo by the great @xenovacom! Xenova (@xenovacom) Real-time video captioning in your browser with @LiquidAI's LFM2-VL model on WebGPU. Sending every frame to a server was never going to be the answer. Imagine the bandwidth, latency and cost. Local inference. No server costs. Infinitely scalable. This is the way. — https://nitter.net/xenovacom/status/2032504624024854673#m
→ View original post on X — @maximelabonne, 2026-03-13 17:46 UTC
-
DPO vs RLVR: AI Model Optimization Techniques Comparison
By
–
Thanks! DPO is great to optimize for human preferences and/or raise the general quality of the model. RLVR is a lot more targeted and focuses on precise tasks.
-
Introduction to LLM Post-Training Techniques Presentation
By
–
A big thank you to @itsmaddox_j for the invitation, and to professors @niclane7 and @contactrika for having me! slideshare.net/slideshow/int…
→ View original post on X — @maximelabonne, 2026-03-06 10:46 UTC
-
53 Slides on Post-Training Algorithms and Data Quality
By
–
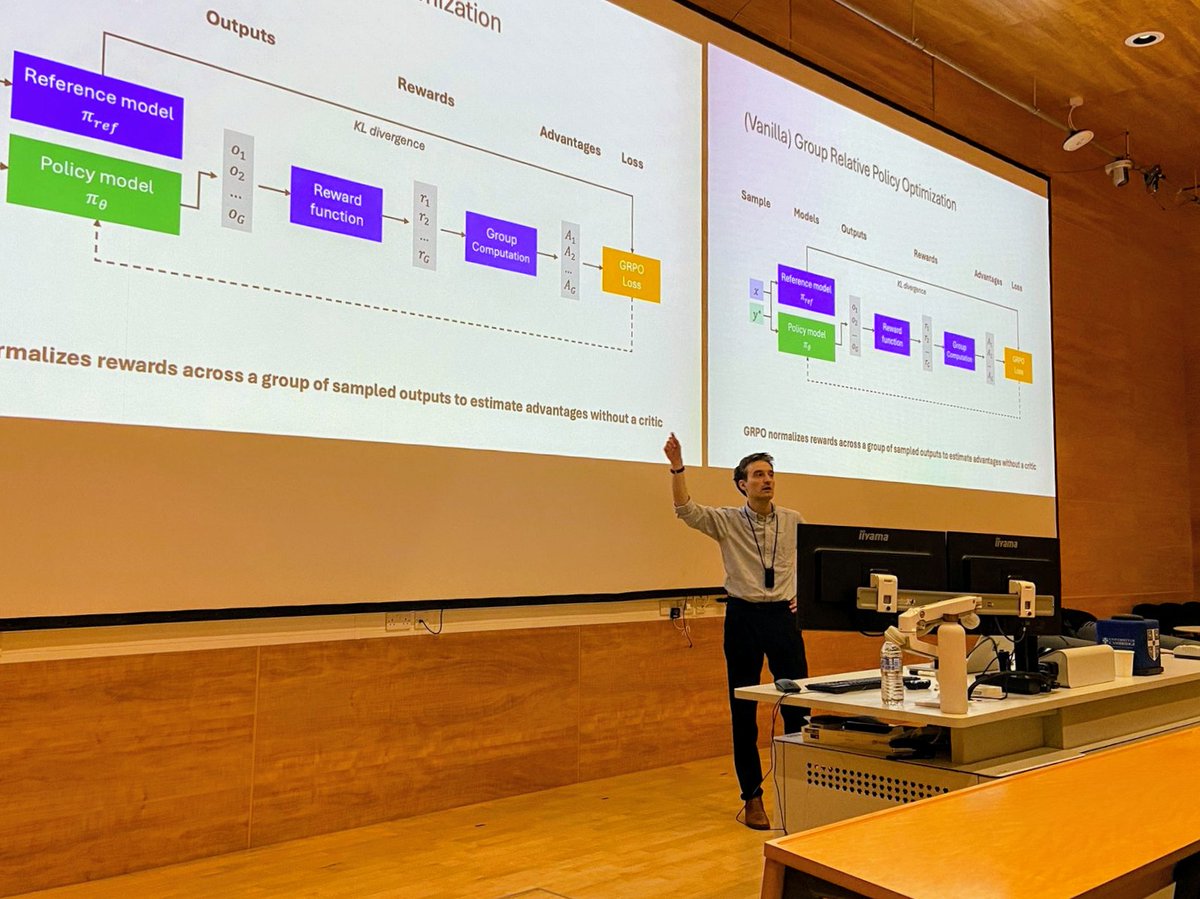
I'm releasing 53 slides on post-training, covering core algorithms like DPO and GRPO, as well as data quality, synthetic data pipelines, and on-policy training. I had the pleasure of presenting it yesterday as a guest lecturer in Cambridge, UK
→ View original post on X — @maximelabonne, 2026-03-06 10:45 UTC