Still ranting about model merging in 2026 ✅ https://t.co/vGtNr0KpSc
— Maxime Labonne (@maximelabonne) 21 mai 2026
Still ranting about model merging in 2026
By
–
Still ranting about model merging in 2026 ✅ https://t.co/vGtNr0KpSc
— Maxime Labonne (@maximelabonne) 21 mai 2026
Still ranting about model merging in 2026
By
–
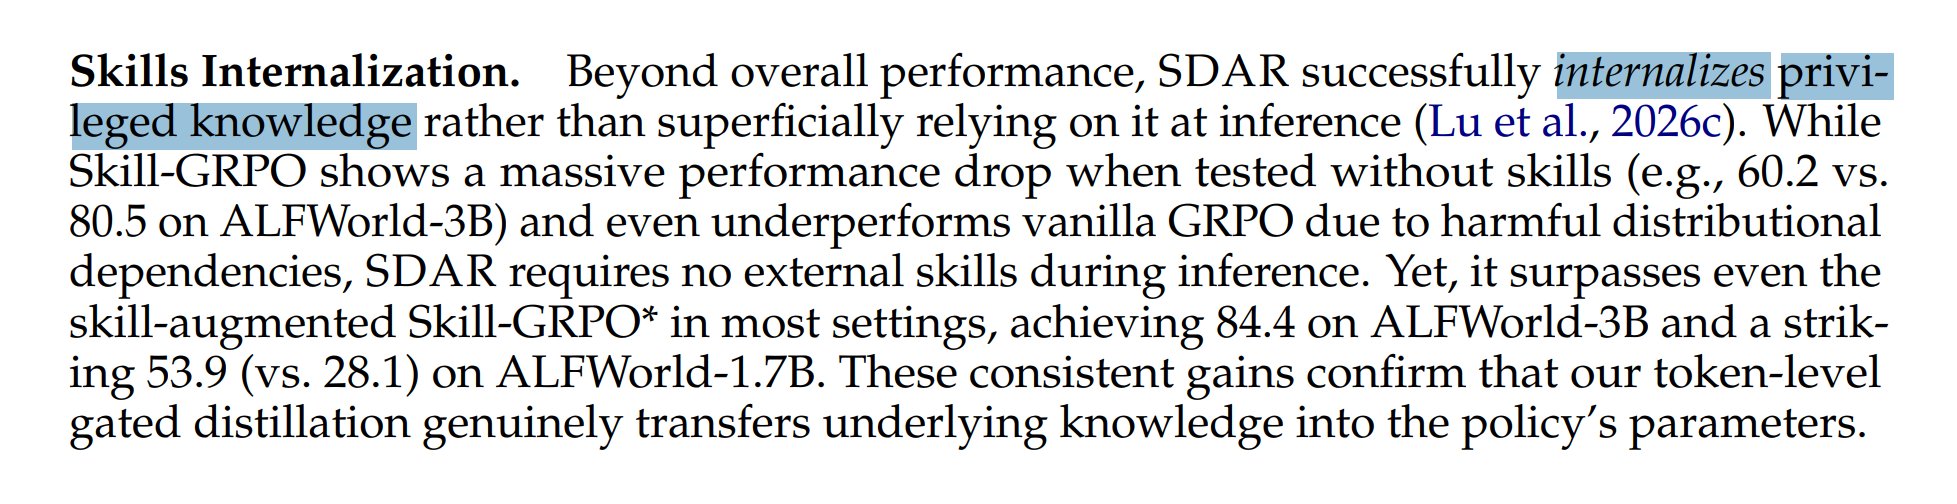
This is so neat! Dynamic Fine-Tuning (DFT) reweights the SFT loss by the model's own token probability, which creates a feedback loop. So they added forward KL to penalize any token the base finds likely, but the policy has pushed toward zero probability. DFT and forward KL
By
–
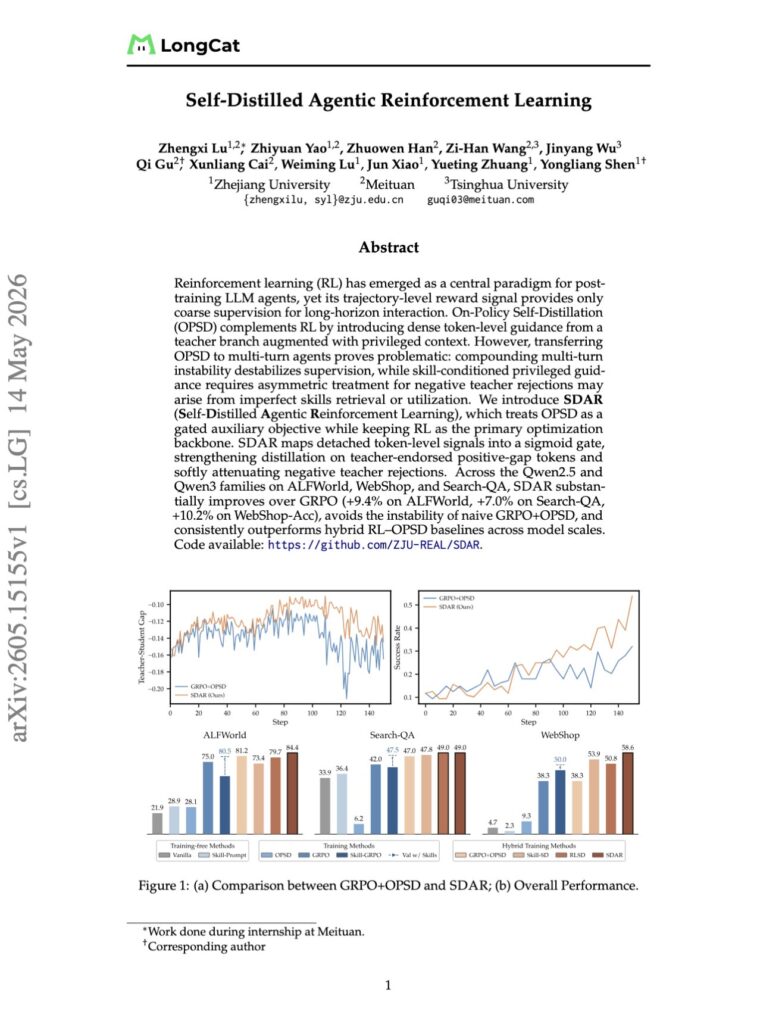
That's so cool! The same team at @Meituan_LongCat wrote Skill0, where they propose an RL recipe for skill internalization.
By
–
The previous edition had an unhinged AI bicycle companion that was fine-tuned to role-play as a bike. If you asked it "what is a transformer?", it'd answer "I don't know, I'm a bike." Absolute 10/10 idea
By
–
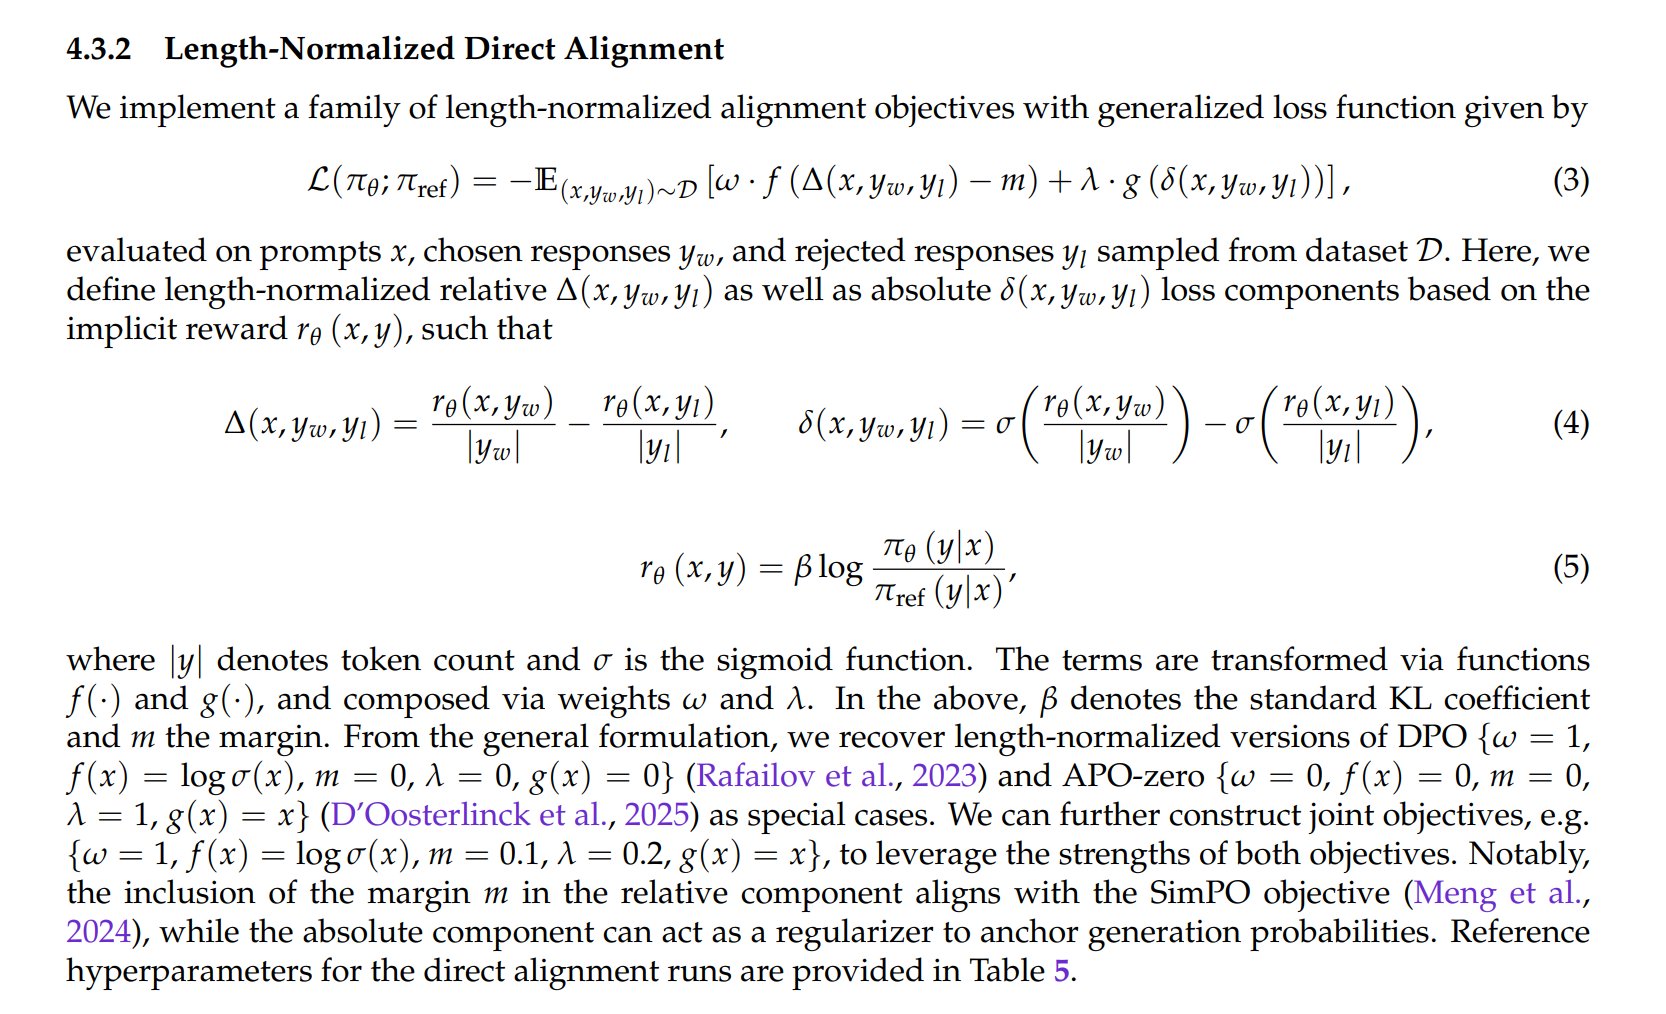
We're quite fond of our length-normalized direct alignment at Liquid (see https://
arxiv.org/abs/2511.23404)
By
–
AgentTrove: new agentic dataset with 1.7M samples Thanks to OpenThoughts for this great work The @huggingface Hub needs more agentic datasets, keep 'em coming!
By
–
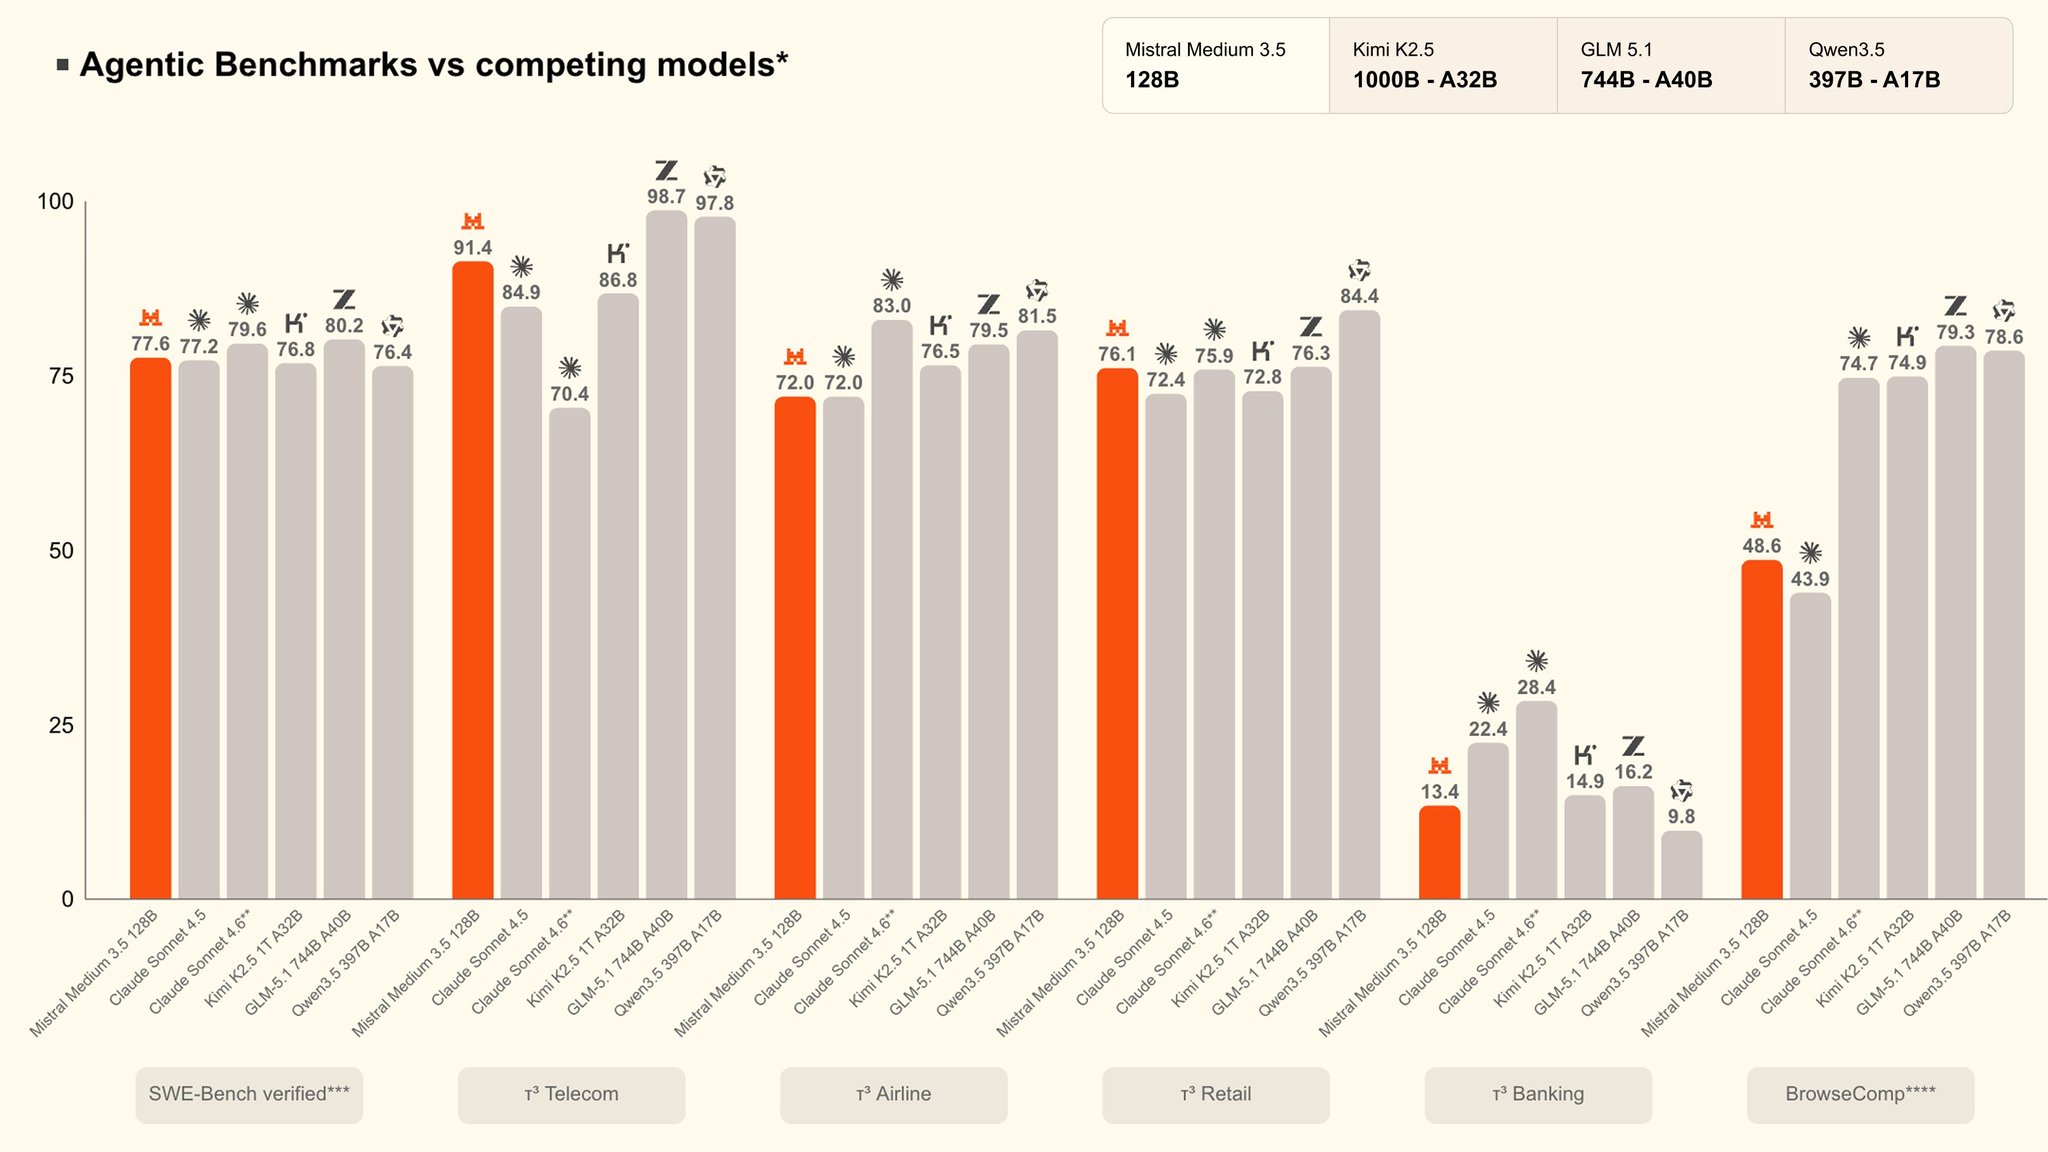
Not sure if this is a good look since most of the competing models were released BEFORE Tau3-Bench
By
–
Reject modernity, embrace tradition (it's a scaled-up Pixtral)
By
–
Did you know that the embedding layer can contain 63% of total model parameters? In this talk, I present unique challenges of small models from architecture (don't build giant embedding layers) to post-training (how to fix doom looping) ↓ Slides in the comments ↓
By
–
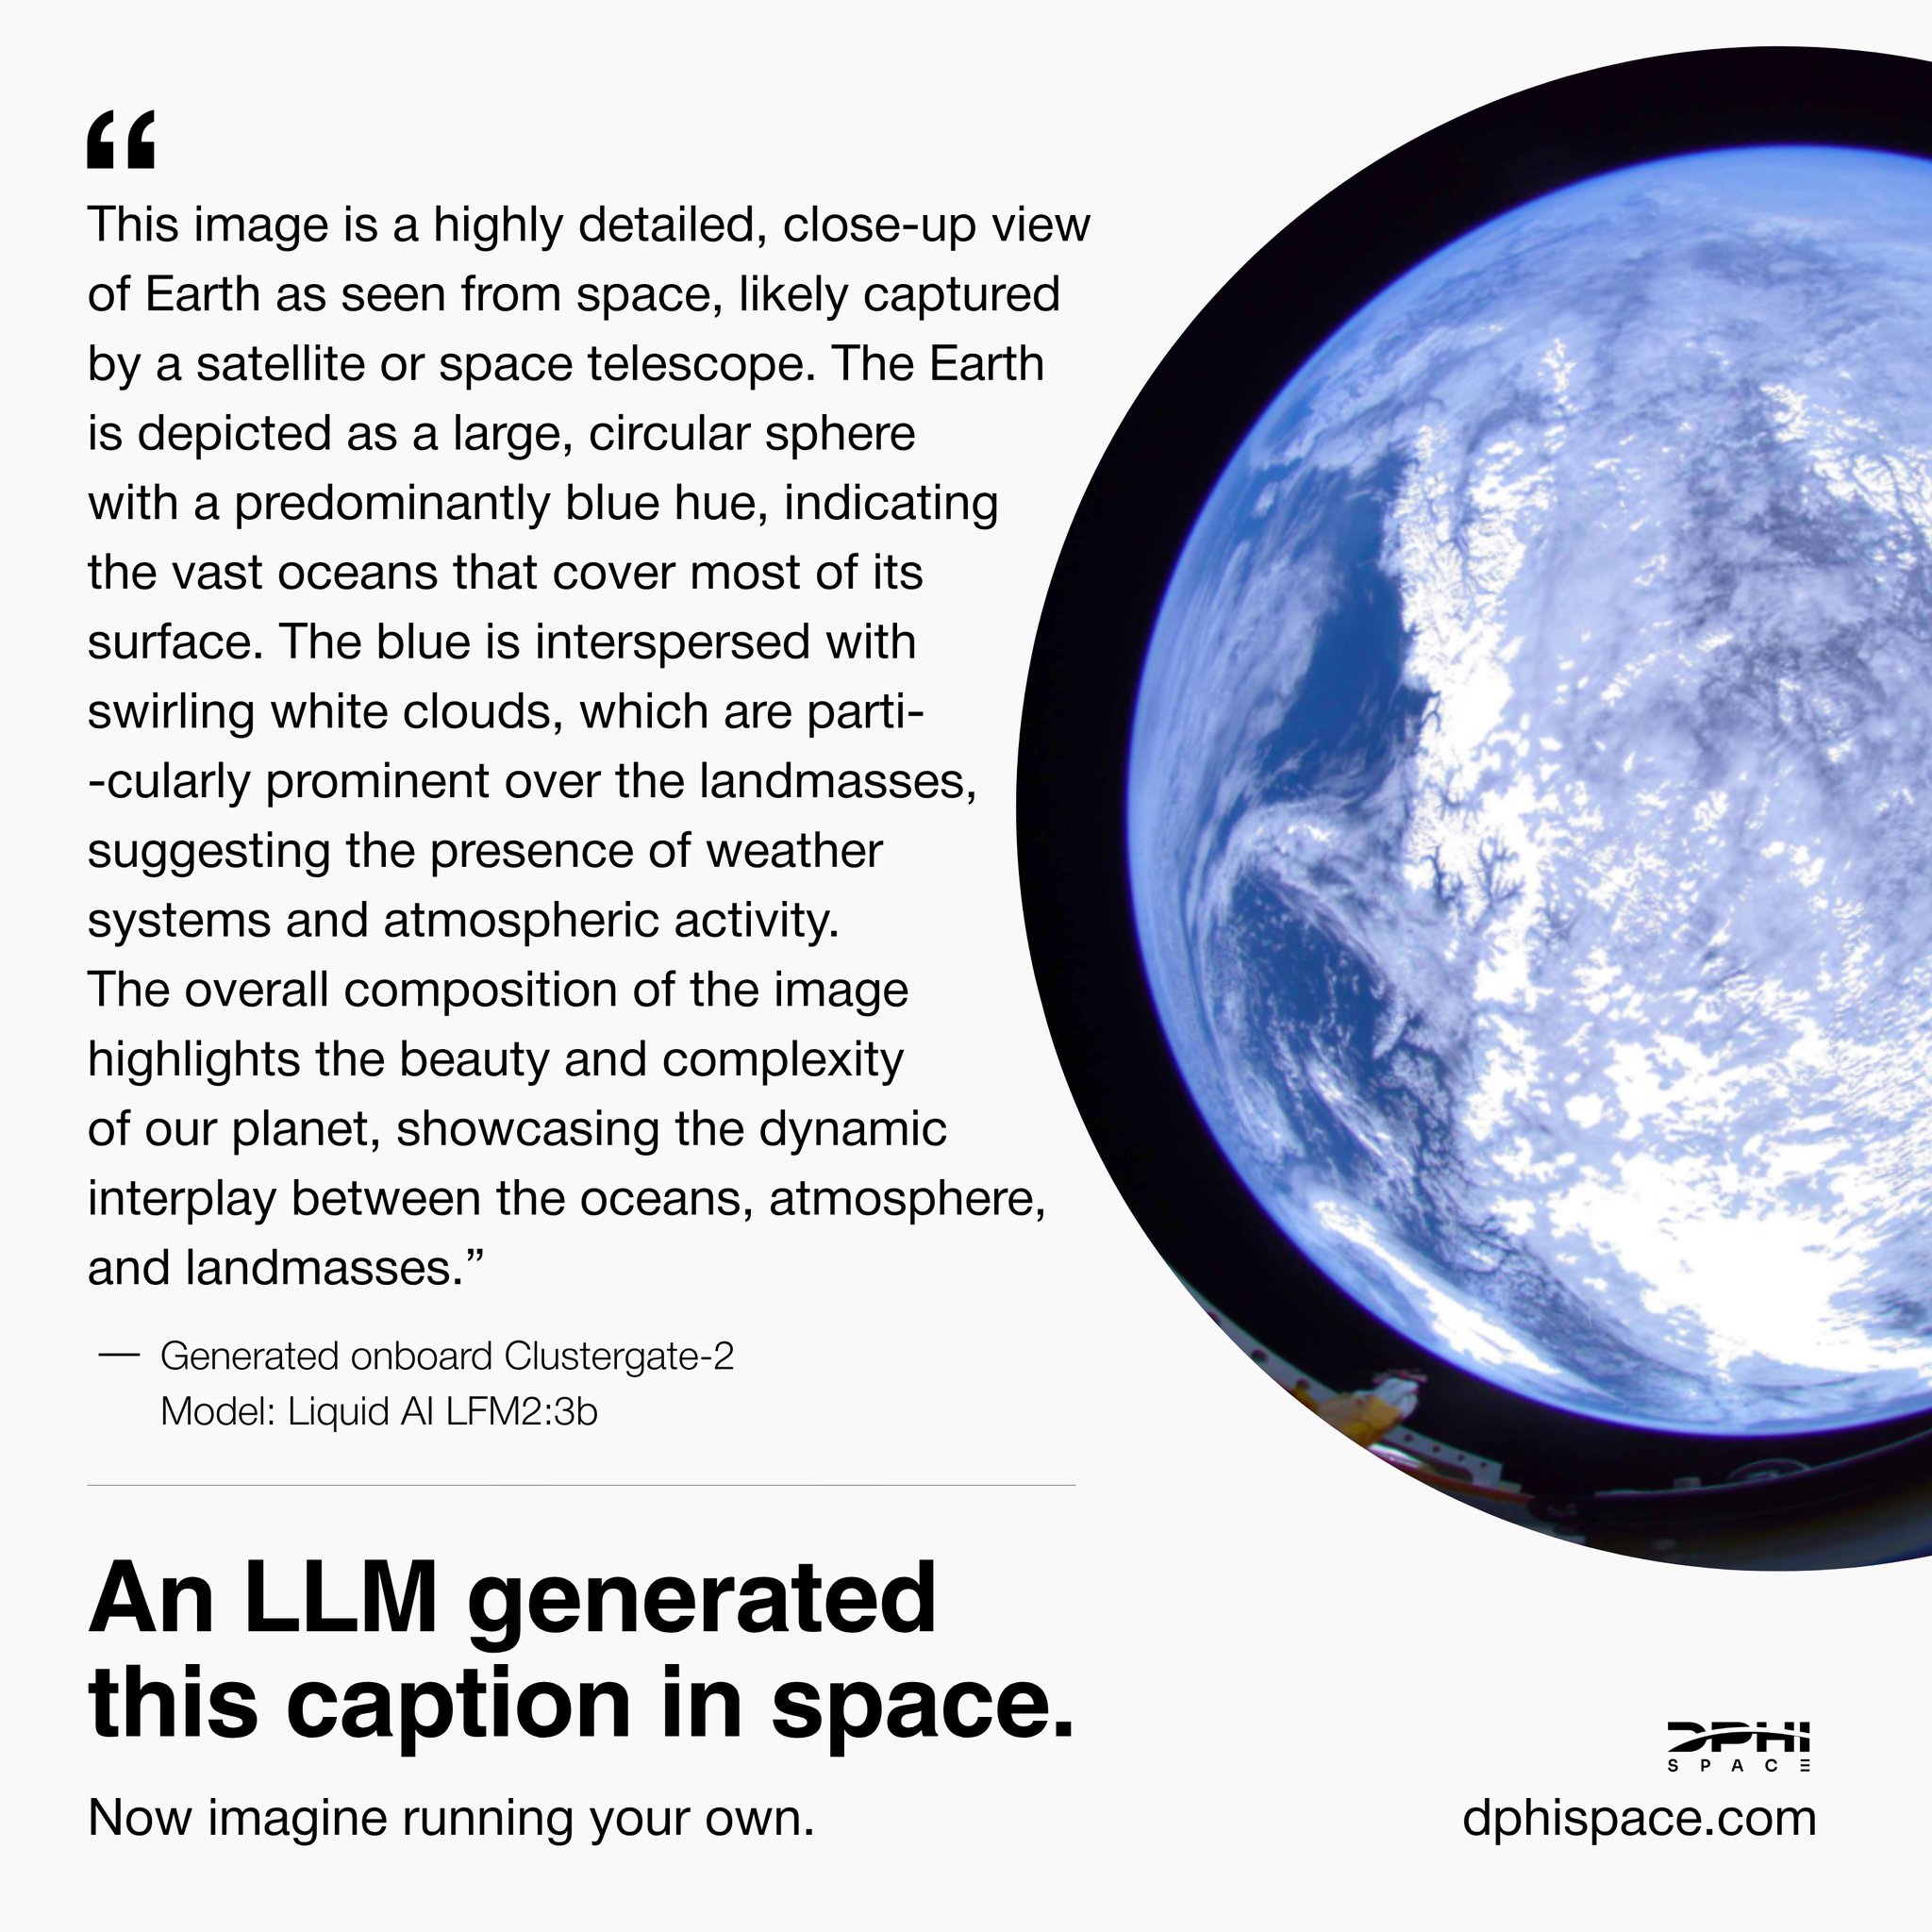
This is so cool: LFM2-VL deployed directly on a satellite! Building HAL 9000 one step at a time.