
Can confirm, edge models keep getting more and more popular
@maximelabonne
-

Two new specialized VLMs extract structured outputs quickly and reliably
By
–
We released two new specialized VLMs They extract structured outputs from images quickly and reliably. You can customize your fields directly in the system prompt.
-

LFM2/2.5 architecture: convolution is almost all you need
By
–
Oh fun! The LFM2/2.5 architecture is a joy to play with. Convolution is (almost) all you need.
-
Maxime Labonne recommends Rasbt’s Build a Large Language Model
By
–
Thanks! I'd recommend @rasbt
's Build a Large Language Model (From Scratch) -
LFM2.5-8B-A1B running as local Blender assistant demo
By
–
LFM2.5-8B-A1B running as a Blender assistant locally. Beautiful demo! https://t.co/uTZB3zOgrn
— Maxime Labonne (@maximelabonne) 1 juin 2026LFM2.5-8B-A1B running as a Blender assistant locally. Beautiful demo!
-
Benchmarking confirms reasoning-only model requires thinking mode
By
–
Awesome, thanks for benchmarking it! It makes sense, the model is reasoning-only so thinking mode is mandatory here.
-
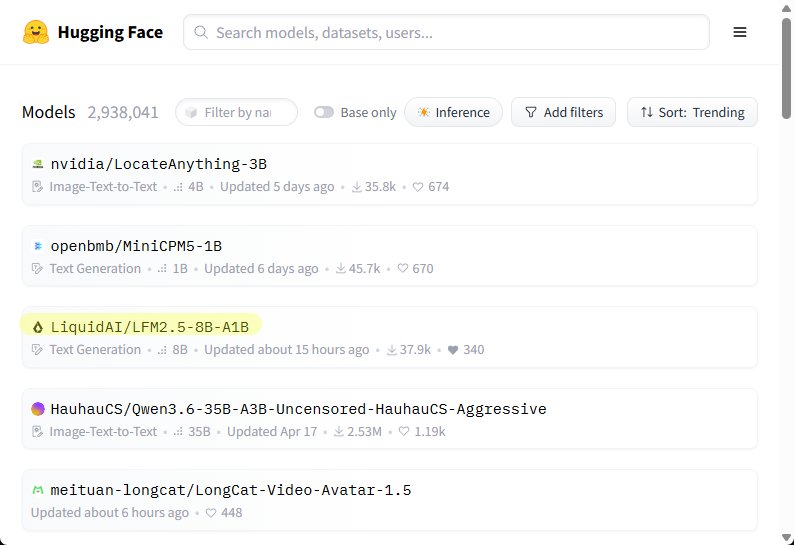
Model with 1B parameters surprises with agentic capabilities
By
–
We're trending on @huggingface
! Tbh, we undersold this model. It's a lot more capable at agentic tasks than I expected. I keep discovering new capabilities every day, it's crazy for 1B active parameters. -
Quantifying Hyperparameter Transfer and Embedding Learning Rate in LLMs
By
–
Quantifying Hyperparameter Transfer and the Importance of Embedding Layer Learning Rate (first screenshot, Kalra and Barkeshli): https://
arxiv.org/abs/2605.21486 Optimal Embedding Learning Rate in LLMs: The Effect of Vocabulary Size (Hayou and Liu): https://
arxiv.org/abs/2506.15025 -
µP embedding LR rule correct under AdamW, explains most benefits
By
–
To clarify, this paper basically says: under AdamW, µP's embedding LR rule (constant) is essentially right and explains most of µP's benefit. Last year, Hayou et al. found that µP's embedding LR rule is wrong for realistic LLM vocab sizes. They found that the optimal embedding
-

Scaling embedding learning rate by model width removes need for µP
By
–
Turns out you never really needed µP, you just needed to scale the embedding learning rate by model width I'm no nanoGPT speedrunner, but isn't it something people stumbled into by using Muon for hidden layers + Adam for the rest?