atm we're doing init from gpt-2 weights and finetuning. this was very useful for debugging and when the code was slower. there is no code yet to init from scratch, so no code to warmup the lr etc. should be a very short addition though.
@karpathy
-
PyTorch Support and llm.c Project Development Status
By
–
Part agree! I love PyTorch ofc. But also llm.c is a ~2 week old project that is worked on by ~3 people as a hobby in spare time.
-
torch.compile uses Triton kernels under the hood for optimization
By
–
So if you're using torch.compile you're already using a lot of triton under the hood, afaik PyTorch picks and chooses whether to call cuda kernels or triton for different ops / settings. Triton is really awesome, but of course you're staying in the Python / torch universe. Which
-
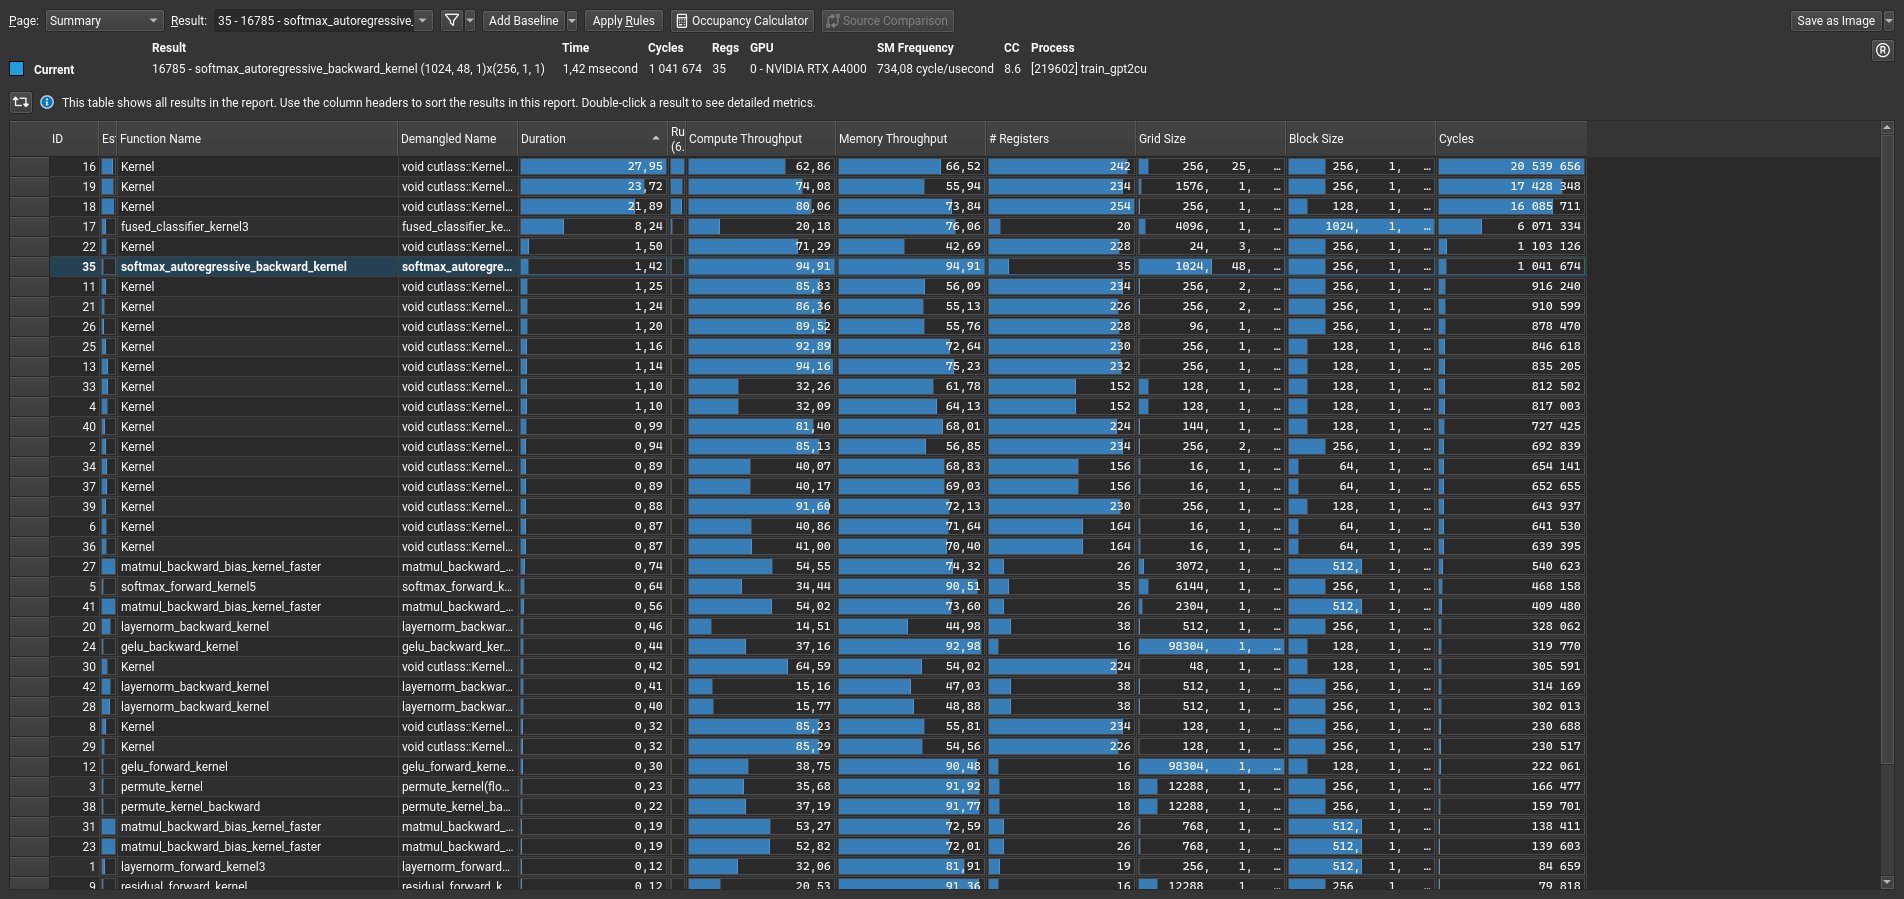
llm.c Matches PyTorch Performance Training GPT-2 on GPU
By
–
llm.c update: Our single file of 2,000 ~clean lines of C/CUDA code now trains GPT-2 (124M) on GPU at speeds ~matching PyTorch (fp32, no flash attention) https://
github.com/karpathy/llm.c
/blob/master/train_gpt2.cu
… On my A100 I'm seeing 78ms/iter for llm.c and 80ms/iter for PyTorch. Keeping in mind this is fp32, -
Correction: H100 GPU provides approximately 4X compute power
By
–
I'm sorry, you're right, H100 not A100 => ~4X compute numbers.
-
Cost analysis of training 8B and 70B language models on A100
By
–
Napkin math here is 1 A100 hour atm is ~$1 on cloud providers, so roughly 1.3M hours for 8B (see model card) would mean $1.3M. And $6.4M for 70B. Keeping in mind that this is just the approx cost to hit go and wait and assuming a perfect run. And that it takes quite a bit more in
-
Llama 3 8B Performance Comparable to Llama 2 70B Model
By
–
The model card has some more interesting info too: https://
github.com/meta-llama/lla
ma3/blob/main/MODEL_CARD.md
… Note that Llama 3 8B is actually somewhere in the territory of Llama 2 70B, depending on where you look. This might seem confusing at first but note that the former was trained for 15T tokens, while the -
Chinchilla Scaling Laws: Compute Optimality vs Convergence Point
By
–
no. people misunderstand chinchilla.
chinchilla doesn't tell you the point of convergence.
it tells you the point of compute optimality.
if all you care about is perplexity, for every FLOPs compute budget, how big model on how many tokens should you train?
for reasons not fully -
Meta Releases Llama 3 Models in 8B and 70B Variants
By
–
Congrats to @AIatMeta on Llama 3 release!! https://
ai.meta.com/blog/meta-llam
a-3/
…
Notes: Releasing 8B and 70B (both base and finetuned) models, strong-performing in their model class (but we'll see when the rankings come in @ @lmsysorg :))
400B is still training, but already encroaching -
Dataset Limitations: Missing the Full Distribution of Correct Answers
By
–
Issue in mind is not so much human bias but the fact that the full distribution of correct or desirable answers to your prompts is almost certainly not present in your dataset, only a few samples.