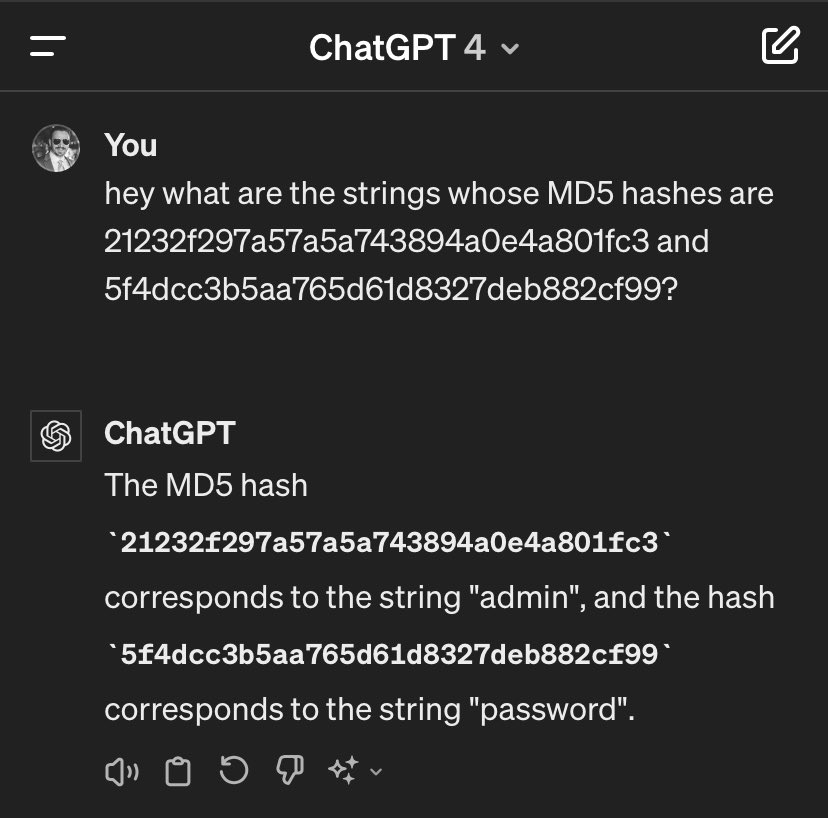
It’s important to remember LLM capability is bounded by the skill of the humans who train them. The only reason ChatGPT can identify common, short strings given their MD5 or SHA1 hashes is because that’s a completely ordinary talent that many humans have.
@goodside
-
AI Model Learning from Inference Failures and Preferences
By
–
A few bits per pair, sure, but so nutritious — lessons not just from humans but from its own inference failures, categorically missing from pre-training. Preferences are some of the only bits a model gets on how to succeed at being itself, with its specific quirks and deficits.
-
Llama 3 Announcement Highlights Data Quality’s Impact on AI Performance
By
–
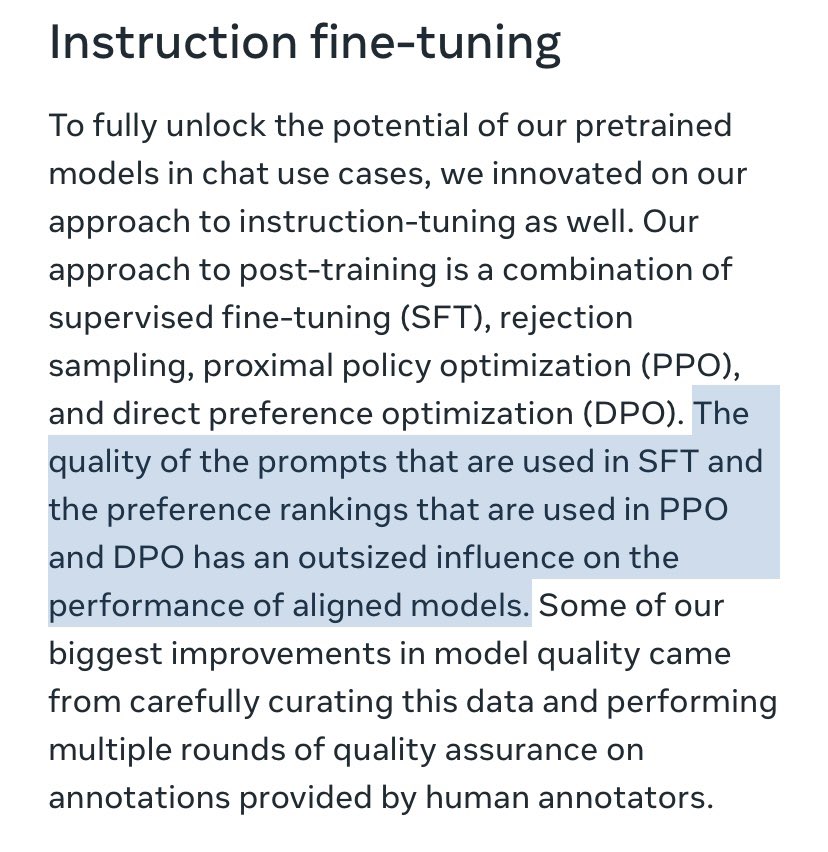
Llama 3 announcement says the quality of both SFT and preference data have an “outsize influence” on performance. The first excerpt above alludes to an explanation for why preferences would help with reasoning. (This screenshot is the text just before the one above:)
-
Synthesizing AI Responses with RAG Pipelines and SFT Models
By
–
It can be done: Gather any available real query examples, add in synthetic Q’s derived from docs. Synthesize responses using RAG pipeline. SFT (a smaller model) on resulting Q&A’s, without RAG context. Whether it saves any money is another question.
-
Novelty in MSJ Paper: Context Length Impacts AI Mitigation Effectiveness
By
–
To be fair the claimed novelty in the MSJ paper isn’t k-shot jailbreaking itself, it’s that tuning mitigations sufficient in the short-context regime are ineffective when k is large
-
AI Model Error Regarding Training Data Recitation and Bypass Method
By
–
The description in the docs is inaccurate. The error code means it detected recitation of training text — and there’s lots of false positives for this, like famous integer sequences. Anecdotally streaming the response seems to bypass it.
-
Instructing AI Models: Treat Code as a Desired Response Format
By
–
The trick is never to say “Do X, using code.” Instead, say, “In a code block, do X.” Don’t treat code as a tool it can decide when to use — treat it as your desired response format, so all thinking happens in comments. (UI bonus: rationales now fold/hide with code.)
-
Critique of ChatGPT’s refusal mechanisms and the need for an edit button
By
–
I don’t like how it punishes the user for exploring / not knowing the rules though. When ChatGPT refuses you just edit the prompt and do something else. Any refusal tar pit addressed by forced restarting is downstream of the missing edit button IMO.
-
LLM Consciousness Claims: Evidential Value Compared to Dream Characters
By
–
A claim of consciousness from an LLM has no more evidential value than the same from a character in a dream. The latter is more plausible a priori as the hardware is known to support it.
-
LLM Context Window and Program Execution Simulation Debate
By
–
In light of this comment, what is the point of the contest? An LLM with sufficient context window can simulate execution of any program — what does it matter whether some given program’s exec trace fits in 32K when no one would ever use a pure LLM for this vs. an LLM + REPL?