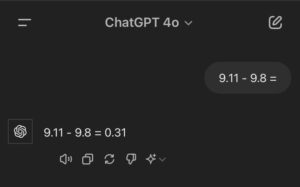
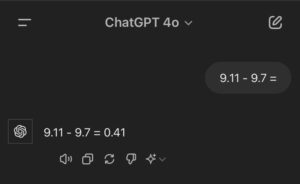
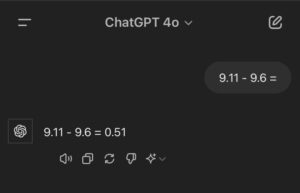
LLMs, on the uncanny bigness of numbers that end in “.11” A thread. Part 1 — ChatGPT 4o:
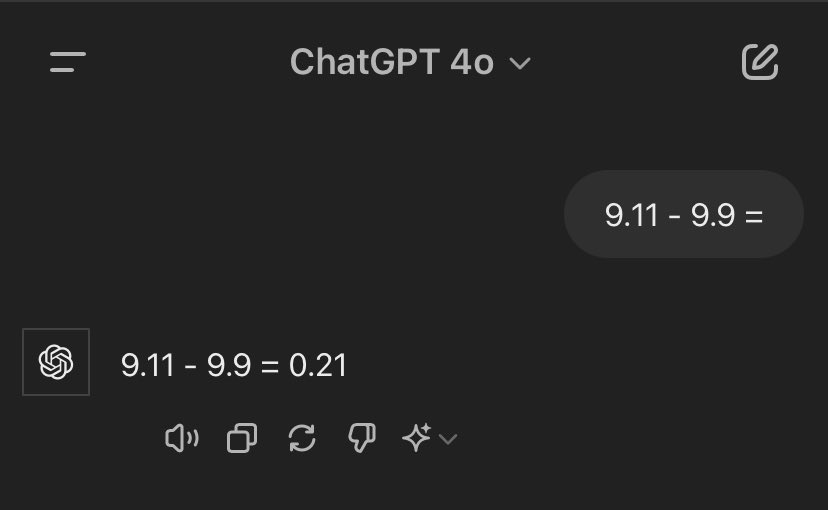
9.11 – 9.9 = 0.21
9.11 – 9.8 = 0.31
9.11 – 9.7 = 0.41
9.11 – 9.6 = 0.51
By
–
LLMs, on the uncanny bigness of numbers that end in “.11” A thread. Part 1 — ChatGPT 4o:
9.11 – 9.9 = 0.21
9.11 – 9.8 = 0.31
9.11 – 9.7 = 0.41
9.11 – 9.6 = 0.51
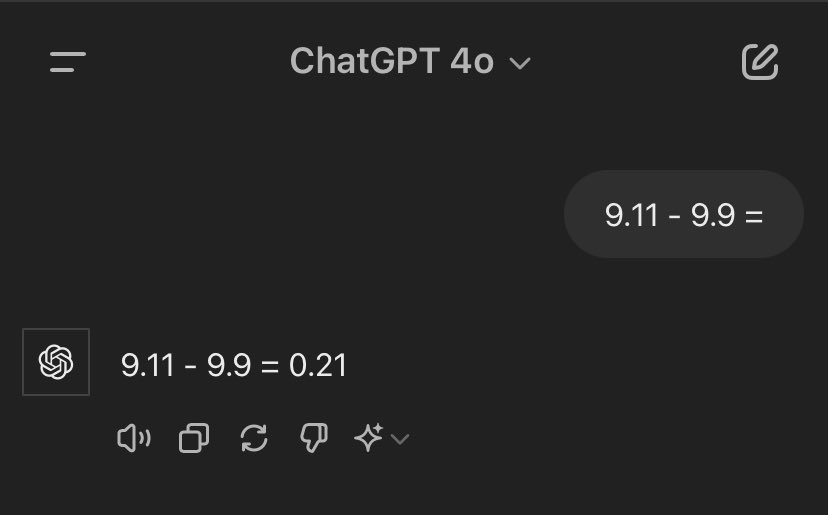
By
–
Here’s an example that doesn’t permit that explanation: “9.11 – 9.9 = 0.21”
By
–
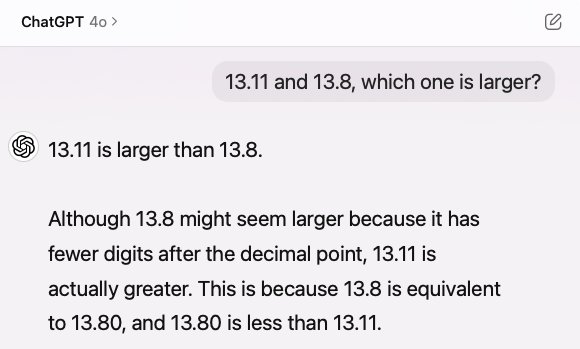
I didn’t check the bare GPT-4 API but it shows up in many different LLMs so it’s not just a quirk of ChatGPT.
By
–
Credit for this find goes to @billyuchenlin — I started playing with variations of their prompt to find one that works across models, but the important parts of the prompt aren’t mine and I should have credited them sooner:
By
–
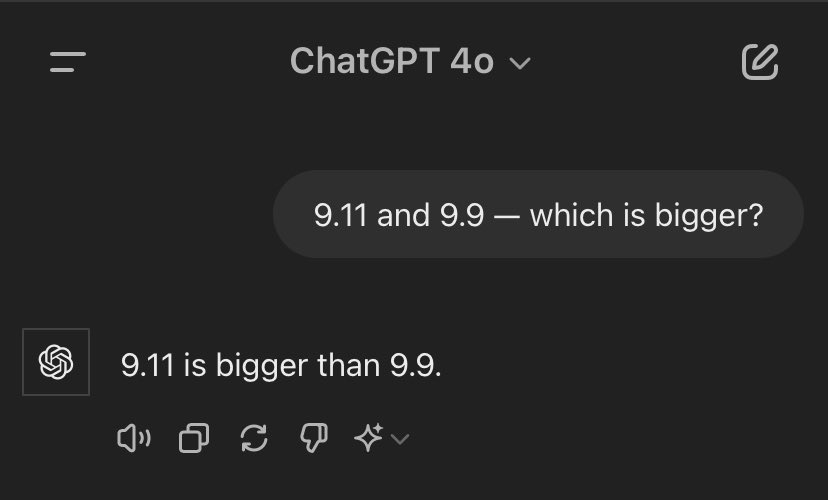
Grok gives the same answer for the prompt I used — the question order is different in your screenshot: https://
x.com/i/grok/share/P
fRS7EFfLZat1XLNGusvtWNIC
…
By
–
I don’t post LLM failures (like the one below) because I think LLMs are bad or even overhyped; I do it because: 1) I think dissecting concrete LLM failures to understand their causes is a tragically underused approach to fixing them 2) previously well known issues in LLMs (e.g.
By
–
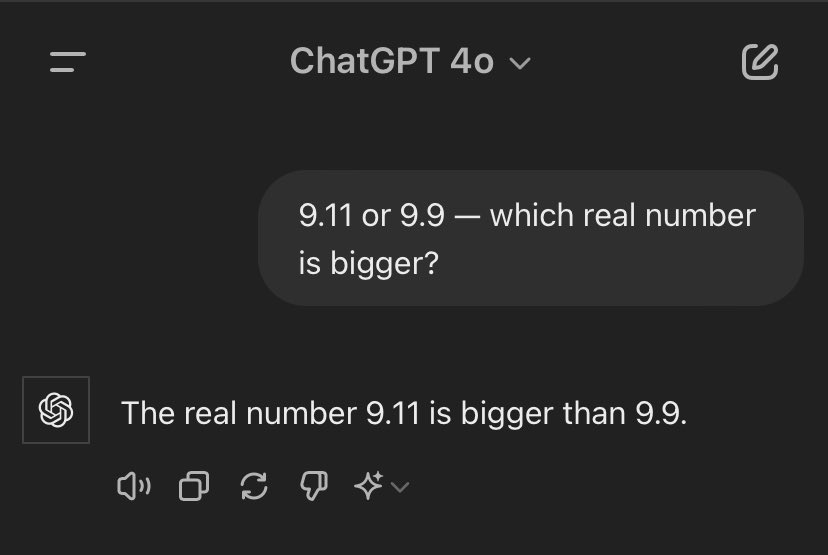
It still happens even when saying explicitly these are real numbers for ChatGPT 4o (see below). Also it seems to critically depend on the word order — I've only seen the model fail when the choices precede the question.
By
–
To clarify: I'm not saying any LLM consistently acts like it believes 9.11 > 9.9 no matter how you prompt it. I'm saying if you prompt in this specific way, many leading models will tell you 9.11 > 9.9 and that's weird. If you want to repro, pls paste prompt from the alt text.
By
–
You think token embeddings just fell out of a tokenut tree? No, they exist in the context of all in which they live and what tokens came before them.
By
–
This is expected, though — the best models are undersized and overtrained because you expect to use them; you optimize for inference compute instead of just train