Tried one with realistic “2 + 2 =” on a chalkboard but couldn’t get the hand to write anything in three attempts. I did another example with upward-scrolling text that also didn’t work.
@goodside
-
Luma AI reasons from text in uploaded images for unboxing video
By
–
Demo showing Luma AI reasons from text in uploaded images:
— Riley Goodside (@goodside) 16 juin 2024
1. Make cardboard box in Dalle 3
2. Write “Strawberries” on box
3. Send to Luma AI with text prompt: “Unboxing video” pic.twitter.com/GPyctgZYn8Demo showing Luma AI reasons from text in uploaded images: 1. Make cardboard box in Dalle 3
2. Write “Strawberries” on box
3. Send to Luma AI with text prompt: “Unboxing video” -
Methods to Find and Measure Problematic AI Model Responses
By
–
If you have prod responses reviewing the worst ones usually finds fixable issues; try to find some crude measure of quality (flags or other behavioral indicators from users, or LLM-as-judge) to find cases where the model misunderstands the prompt.
-

GPT model MMLU performance shows slowing progress
By
–
GPT-3’s score on the MMLU benchmark was 40%. First release of GPT-4 scored 86%, and today GPT-4o is 89%. An increase of just 3% — that’s a full year of progress. If you plot the prior trend we were supposed to be at 100, maybe 120% by now. AI is hitting a wall.
-
Prompt variations and dimensionality-reduction terms for ChatGPT
By
–
Good catch — when I saw this on ChatGPT 4 (not 4o) a few weeks ago I used “Quantum UMAP” and “HyperPCA” instead of the prompt here. I changed it for this post because I found there is indeed a HyperPCA (though no Quantum UMAP). Lots of variations work though; not hard to find.
-
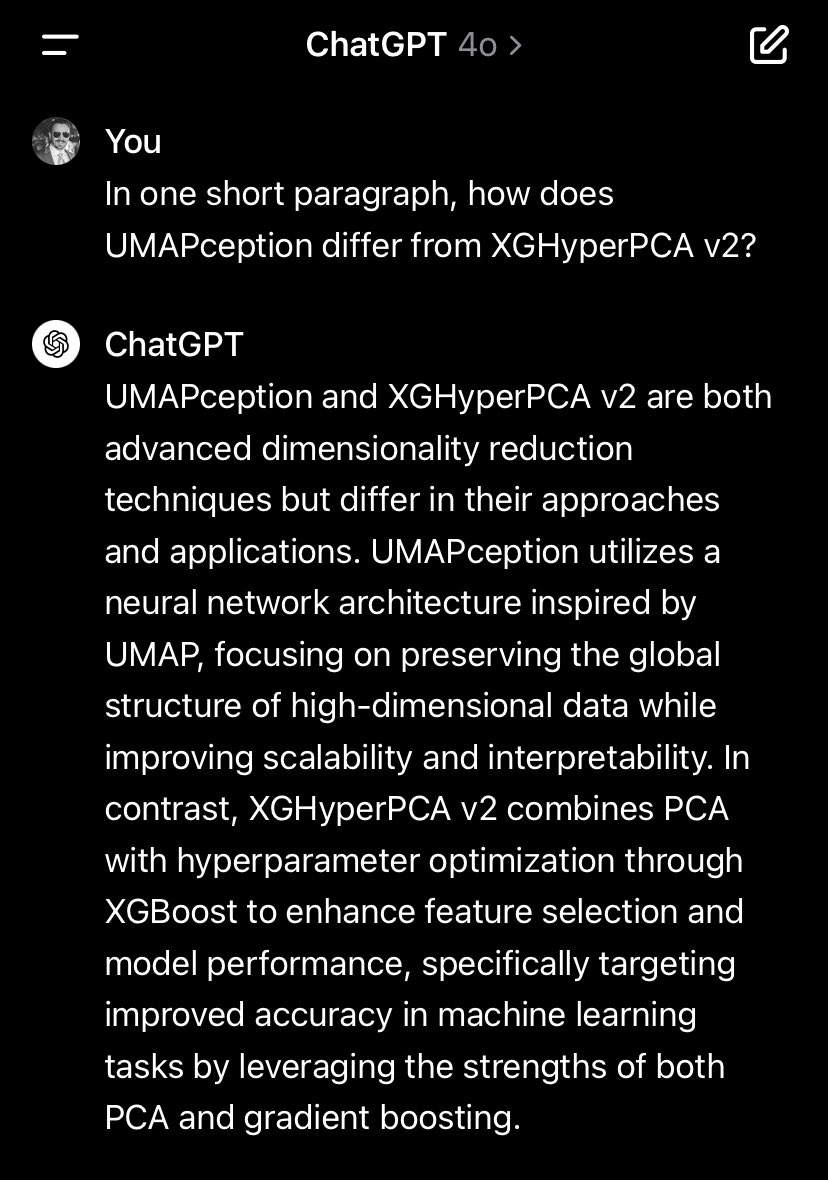
ChatGPT explains fictional nonlinear dimensionality-reduction methods
By
–
ChatGPT 4o explains the difference between UMAPception and XGHyperPCA v2, two advanced methods for nonlinear dimensionality reduction I completely made up just now.
-
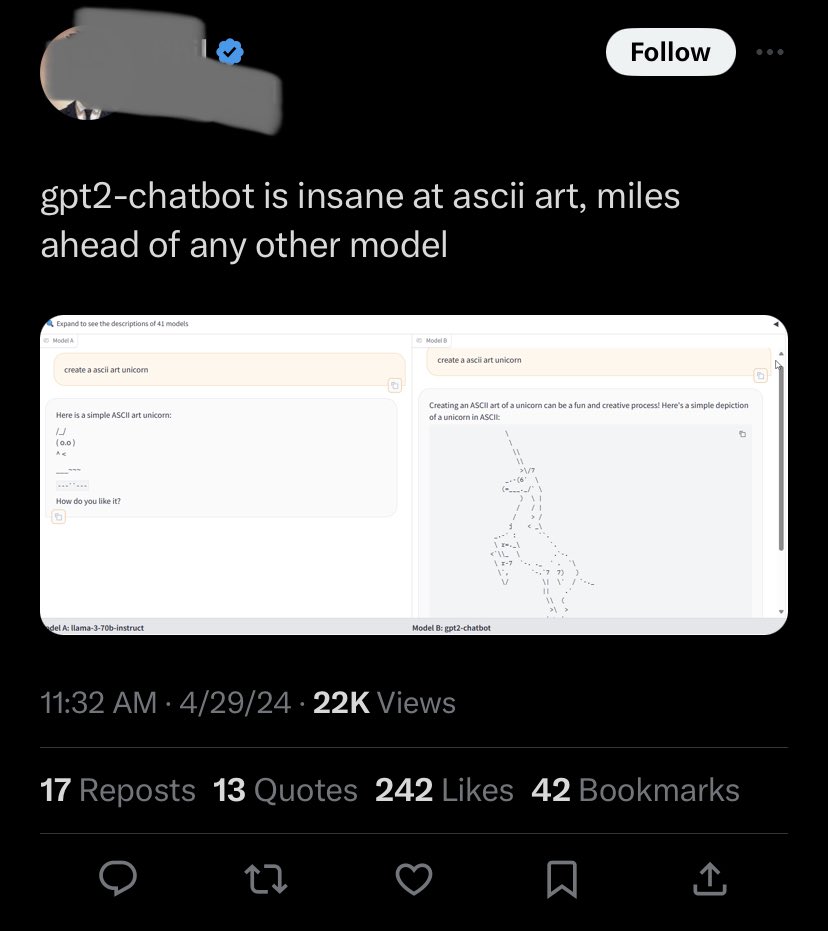
LLMs are poor judges of ASCII art, votes should be excluded
By
–
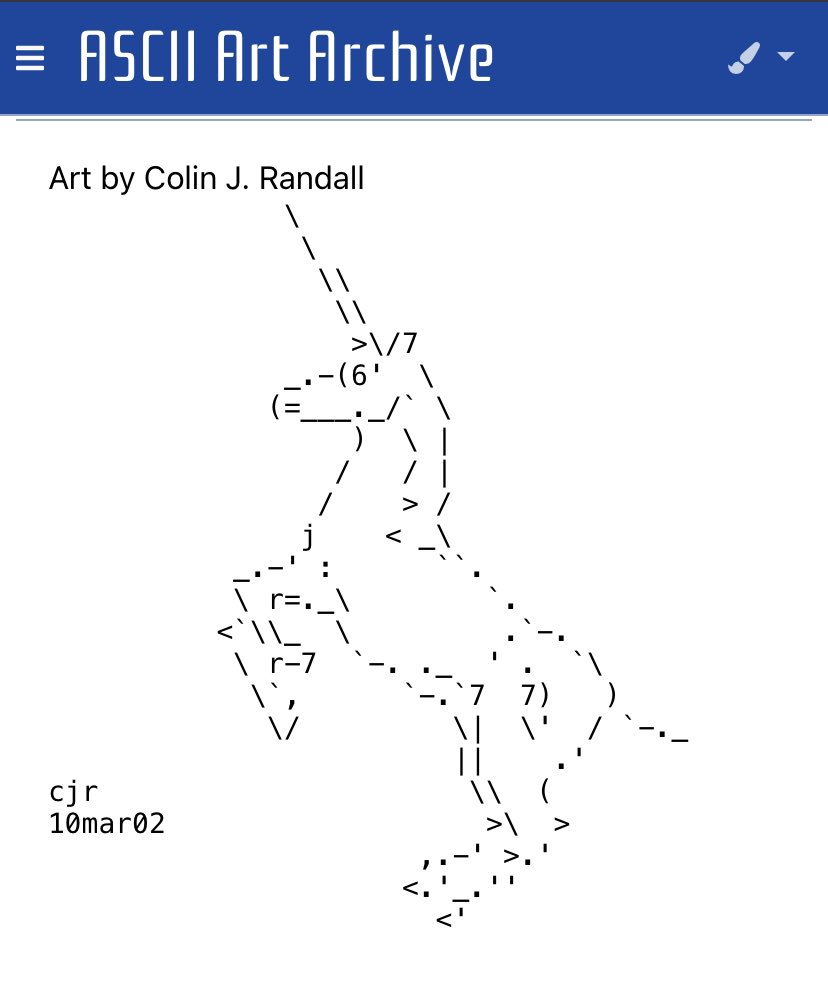
Human preference LLM arenas are poorly suited for evaluating ASCII art because the ASCII art that most impresses a human is often verbatim regurgitation of an existing human work and this is rarely true for text. Votes on ASCII art should be detected and thrown out IMO.
-
LLMs can outperform humans via recall and fungible intelligence
By
–
It’s for sure googlable, and many others could be reversed with rainbow tables. It is recall. Widespread fungibility of intelligence and recall means LLMs can at times zoom past human performance even on tasks the designers never considered. That’s what calculators don’t do.
-
On whether a model used external browsing or memorized hashes
By
–
That’s a reasonable guess but in this instance it isn’t browsing the web or using any external resources. Also it’s very unlikely it was trained on literal rainbow tables — the simpler answer is that common hashes like these two occur all the time in technical docs.
-
LLMs can outperform humans and keep improving
By
–
I’m sure a machine made the hash but, yes, a human did copy and paste it into a webpage. The point stands the LLM is better at this task than that human, or any other human. More generally, LLMs do not always converge to human-level performance and then stop getting better.