The ModelParallel scheme above scales to arbitrary model sizes and numbers of devices on a single host, but it also works with multi-host training. If you do multi-host training, a common gotcha is that you need to remember to seed everything in the same way on each host (else
@fchollet
-
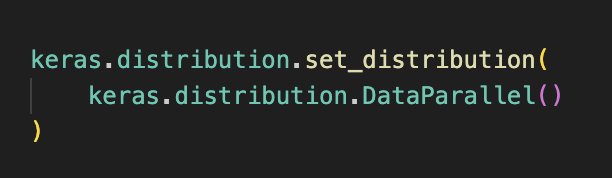
Keras JAX Data and Model Parallelism Configuration
By
–
1. Configuring data parallelism for Keras models running on JAX (works with fit/evaluate/predict with 0 other changes to your code). All model state and incoming dataset are automatically distributed. 2. Configuring model parallelism + data parallelism while specifying the
-

Accelerating Infrastructure: From Chips to Renewable Energy
By
–
Driven mostly by chip manufacturing right now. Let's keep it going up and to the right. Next up: fully-automated ports, high-speed rail, nuclear power, solar. It's time to build.
-
Major daily services rely on this code
By
–
Most of the services you use daily (including X/Twitter, YouTube, Spotify, Netflix, Snap, Waymo…) are using some of this code
-
AI as Excuse for Cost-Cutting, Not Genuine Productivity Gains
By
–
Haven't seen any company firing devs because they genuinely anticipated they wouldn't need humans anymore. But I have seen a few companies firing devs because they needed to cut costs, saying "it's because of AI!" The story "we're so productive now we don't need employees
-
Knowledge Benchmarks Don’t Equal Real-World Capabilities
By
–
Exam-style knowledge benchmarks != Real-world capabilities
-
LLMs positioned mid-way between capabilities and limitations
By
–
I would disagree here, based on current LLM capabilities and failure cases, I would place them mid-way. They are genuinely "in-between"
-
Understanding Differs from Compression: Prediction and Action Across Contexts
By
–
No, compression is a means, understanding is an ability. You understand something if you can correctly make predictions and take action across all relevant situations
-
Deep Learning Abstractions Limited to Local Generalization Across Domains
By
–
These weakly abstract models can generalize, but only locally so. They still break down upon simple problem modifications or when encountering novel problems. This has been true of all deep learning generated abstractions, across every domain and across all architectures.
-
Models as spectrum between associations and causal abstractions
By
–
While this is directionally right, keep in mind that this is not a binary distinction. There's a spectrum between, on one extreme, collections of associations (e.g. a lookup table), and on the other extreme a maximally concise, abstract causal model (e.g. Snell's law). With https://
x.com/Grady_Booch/st
/Grady_Booch/status/1835413920624030136
…