Keras was there before TensorFlow, and it will still be there long after TensorFlow is dead. As long as a product is able to maintain PmF, it will keep going. If you no longer have PmF, no moat will protect you in the long term. The rest ebbs and flows.
@fchollet
-
Keras Celebrates 10 Years with 500K Daily Downloads
By
–
Keras will turn 10 this March. As of late 2024, it's getting downloaded half a million times every day on average. I recently drafted a doc that had a section titled "Keras 2035".
-
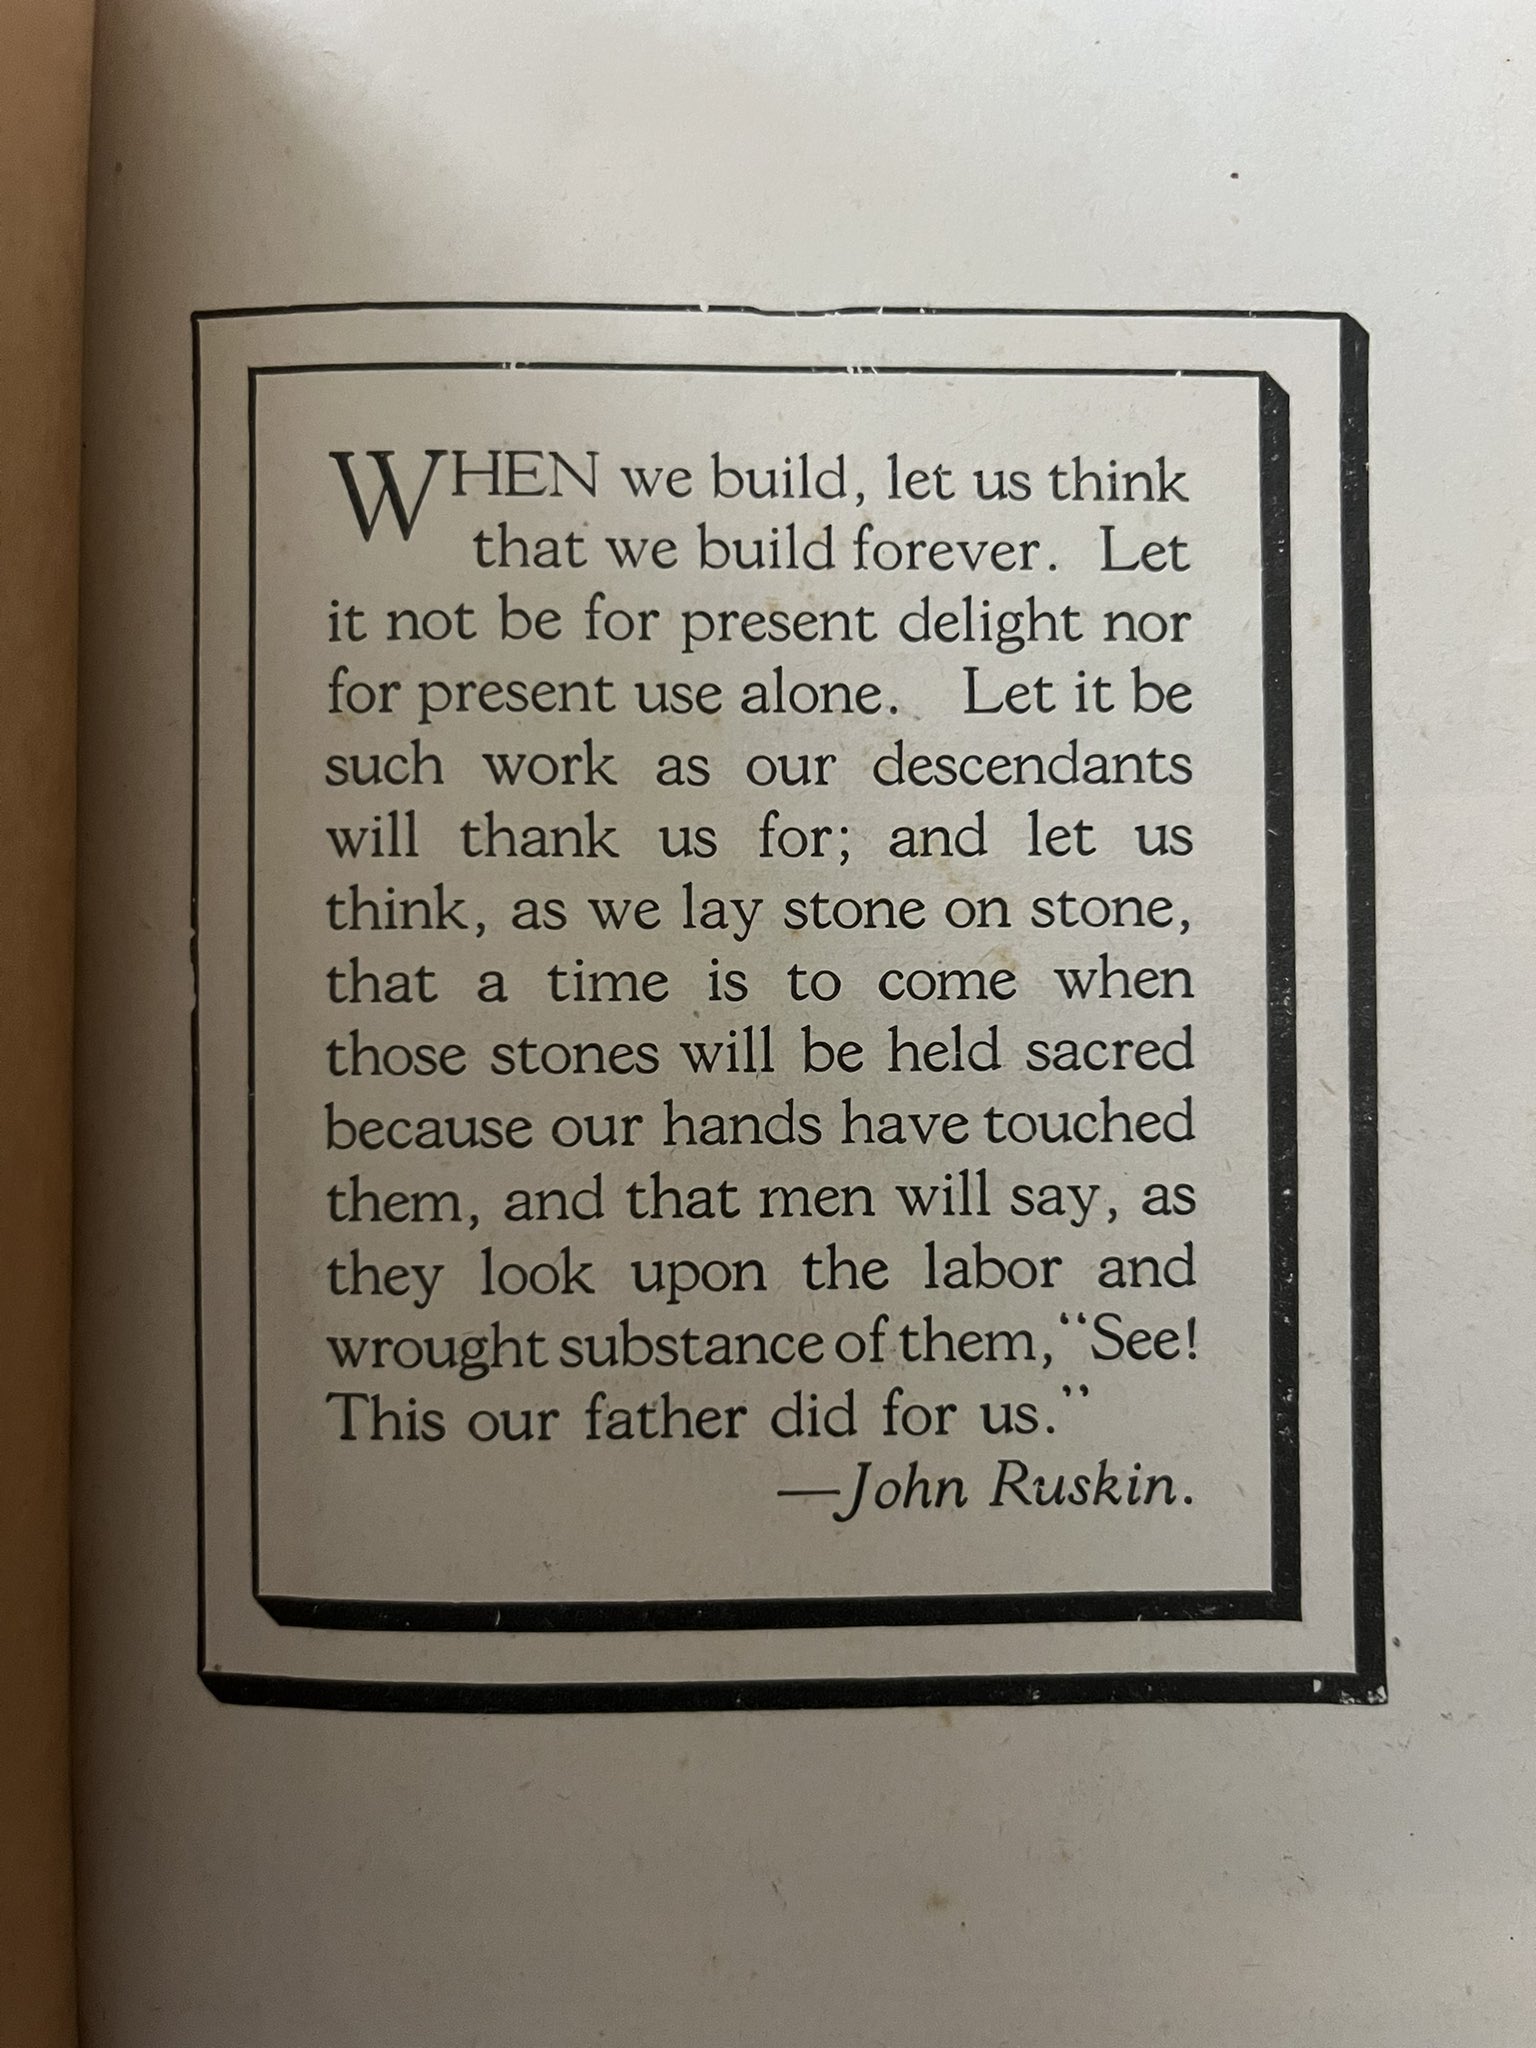
Keras vision: Long-term thinking for future generations of deep learning
By
–
I remember doing a little speech to a number of TF team members at my desk back in 2019 — about why they should think long-term, about how I wanted my future children (not even in the plans at the time) to eventually learn deep learning with Keras, 20 or so years in the future.
-
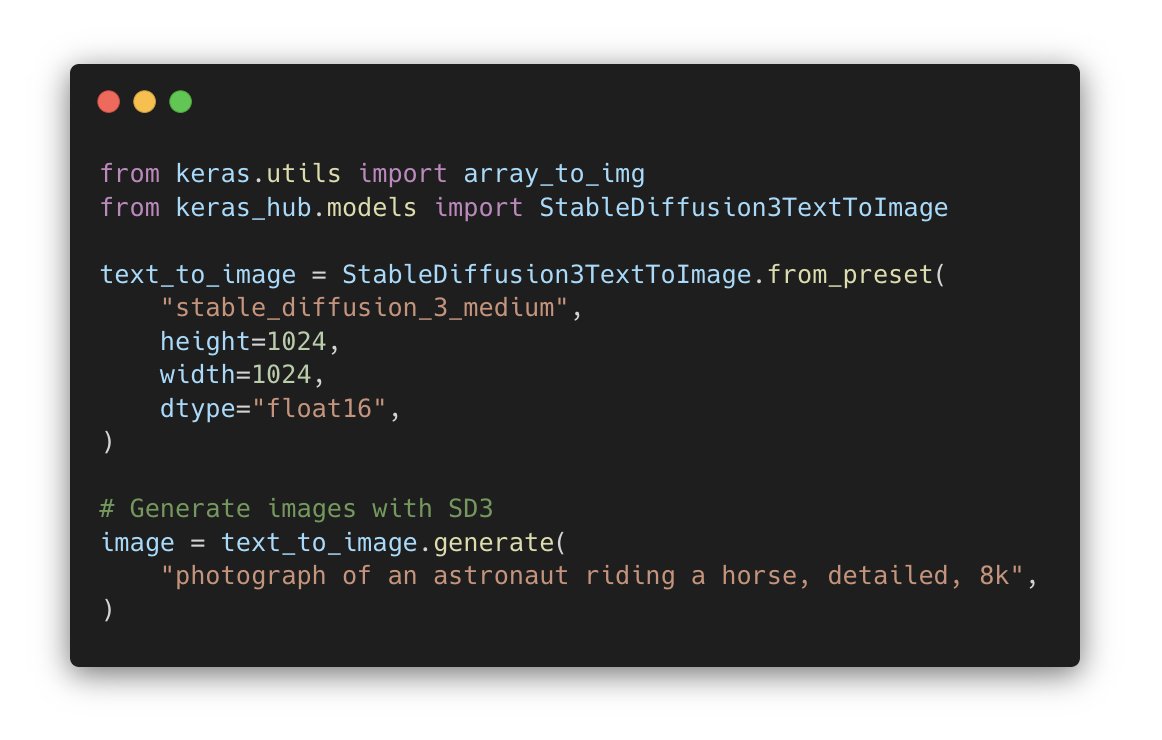
StableDiffusion 3 Image Generation with KerasHub Float16 Inference
By
–
Generating a 1024×1024 image with StableDiffusion 3 in KerasHub, using float16 inference. The `generate` method is compiled, and compilation happens on the first call. The next time you call the model again you will reuse the same compiled function and it will be super fast.
-
Custom Callbacks and Async-Safe Logging in Training Batches
By
–
Note that if you use custom callbacks that override `on_train_batch_end()`, you are at risk of forcing synchronous logging. Make sure to make your callbacks async-safe, and annotate them as such by setting `self.async_safe = True`
-

Keras fit() automatic data prefetching and asynchronous logging optimization
By
–
This isn't obvious. Most people remember to do data prefetching, but few do asynchronous logging. Keras `fit()` does both out of the box automatically, regardless of your data source. This gets you fully compact train_step stacking, like here — zero idle time.
-
Data Prefetching and Asynchronous Logging for GPU Utilization
By
–
To order to get high device utilization when training, the most important best practice is to both do data prefetching (moving the next batch of data to GPU memory while the previous batch is being processed) and asynchronous logging (moving the metrics from the previous batch to
-
CMU Talk on ARC Prize and Path to AGI
By
–
If you're at CMU, come see @mikeknoop talk about @arcprize and the path to AGI! It's tomorrow, register at the link below.
-
Weights Sharding Strategy: Full Replication Except Last Dimension
By
–
Also, tip on weights sharding: as a generic rule of thumb you can use full replication for all variable dimensions except the last one, which should be sharded across the "model" axis
-
JAX and Keras offer superior large-scale model training performance
By
–
In general, you will find that JAX (and in particular JAX + Keras for the super simple API) offers an exceptionally smooth and performant large-scale model training experience. Zero hassle and high utilization out of the box — there is no alternative that comes close to it.