In 2023 there was a big uptick in companies marketing their products as “AI powered”. 2026 will be the year of companies marketing their products as “AI free” (a trend already underway)
@fchollet
-
AGI Benchmarking Article Featured in IEEE Spectrum
By
–
Good article on AGI benchmarking in IEEE Spectrum
-
Causal Substrate and Symbolic Representation in Models
By
–
"Does a causal substrate necessarily need to be symbolic?" you ask. Could it be based on parametric curves? Yes it does, because in such a substrate the model is isomorphic to the graph of causal factors of what you are modeling. And such a graph is necessarily very sparse, i.e.
-
Deep Learning Generalization: Interpolation Versus Causal Understanding
By
–
When you store your knowledge and skills as parametric curves (as all deep learning models do), the only way you can generalize is via interpolation on the curve. The problem is that interpolated points *correlate* with the truth but have no *causal* link to the truth. Hence
-
The Critical Importance of Asking the Right Question First
By
–
This is why, to solve a difficult open-ended problem (like AGI), you must always start by asking the right question.
-
Important Learning Point from Deep Learning with Python Book
By
–
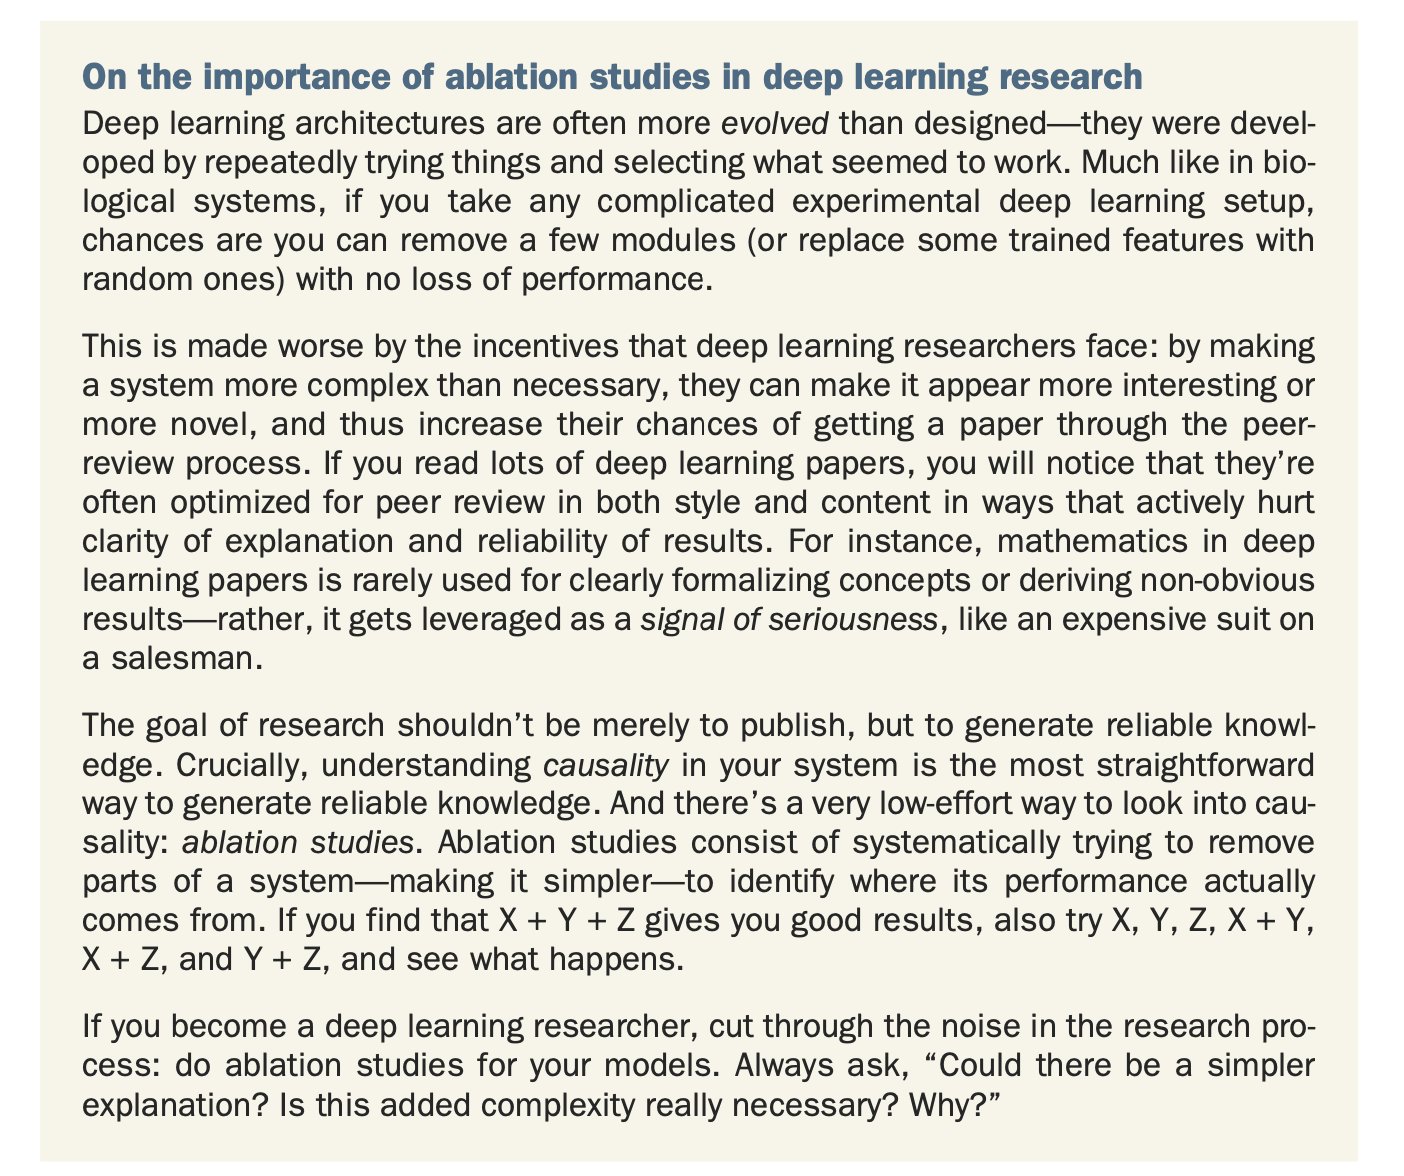
Important point from Deep Learning with Python…
-
No Data Leakage in Model Training and Evaluation Process
By
–
Importantly: there was in fact no data leakage at work in the codebase, unless what a first read of the code suggested. The model is trained on the *demonstration pairs* of the evaluation tasks, but never sees the *test pairs* of those tasks, which is what it gets tested on.
-
HRM Paper Findings Reproduced on ARC-AGI-1 with Ablation Analysis
By
–
We were able to reproduce the strong findings of the HRM paper on ARC-AGI-1. Further, we ran a series of ablation experiments to get to the bottom of what's behind it. Key findings: 1. The HRM model architecture itself (the centerpiece of the paper) is not an important factor.
-
AI writing style detection and recognition in social media
By
–
Interesting findings from this post: 1. It should be obvious to anyone who has interacted with LLMs before that the writing style of the tweet is a conspicuous caricature of AI slop (e.g. em dashes, the "it's not… it's…" construction, rambling, florid prose, etc.). Yet, many
-
Google Releases Gemma3 270M Tiny LLM on KerasHub
By
–
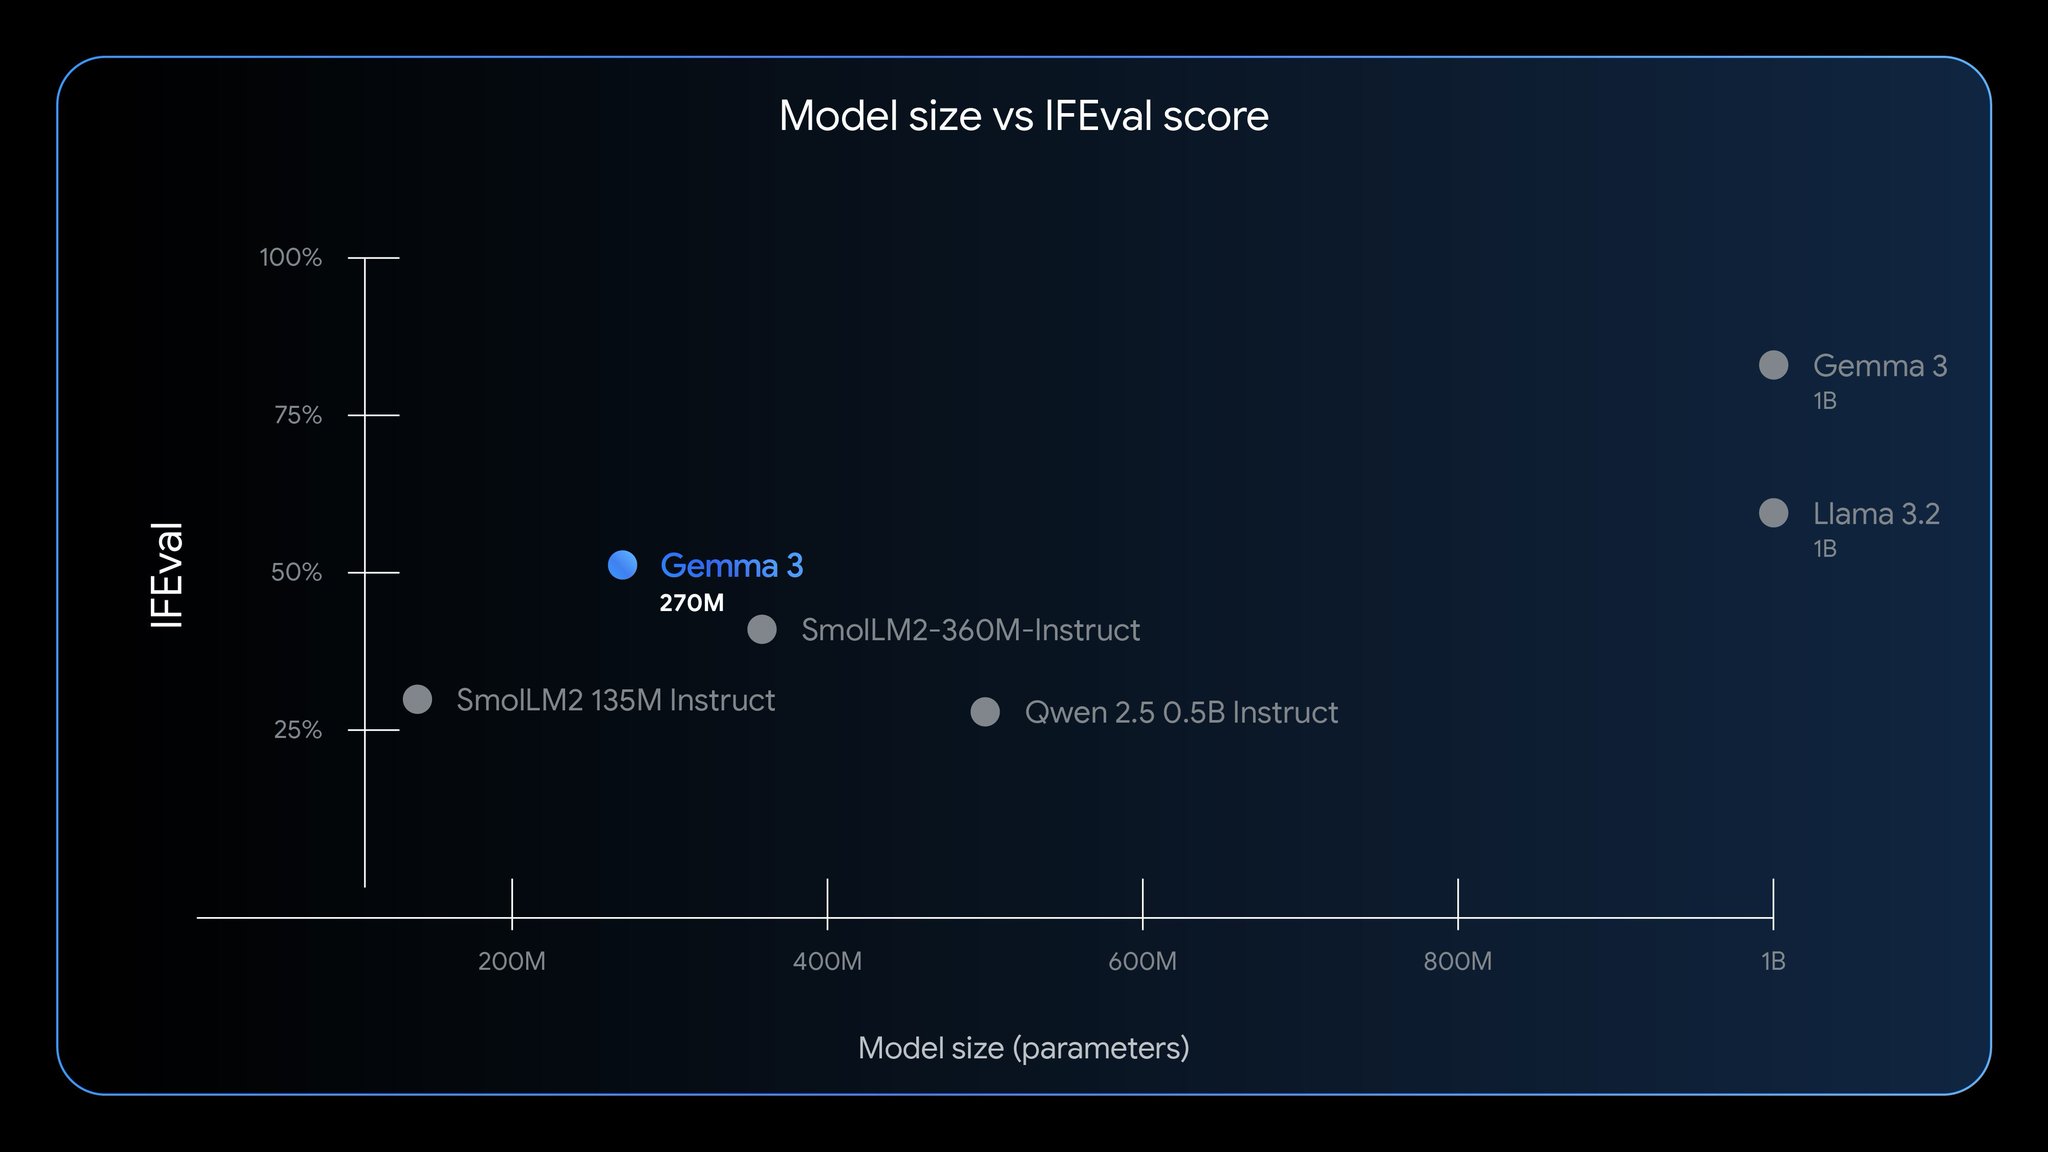
Google just dropped a new tiny LLM with outstanding performance — Gemma3 270M. Now available on KerasHub. Try the new presets `gemma3_270m` and `gemma3_instruct_270m`!