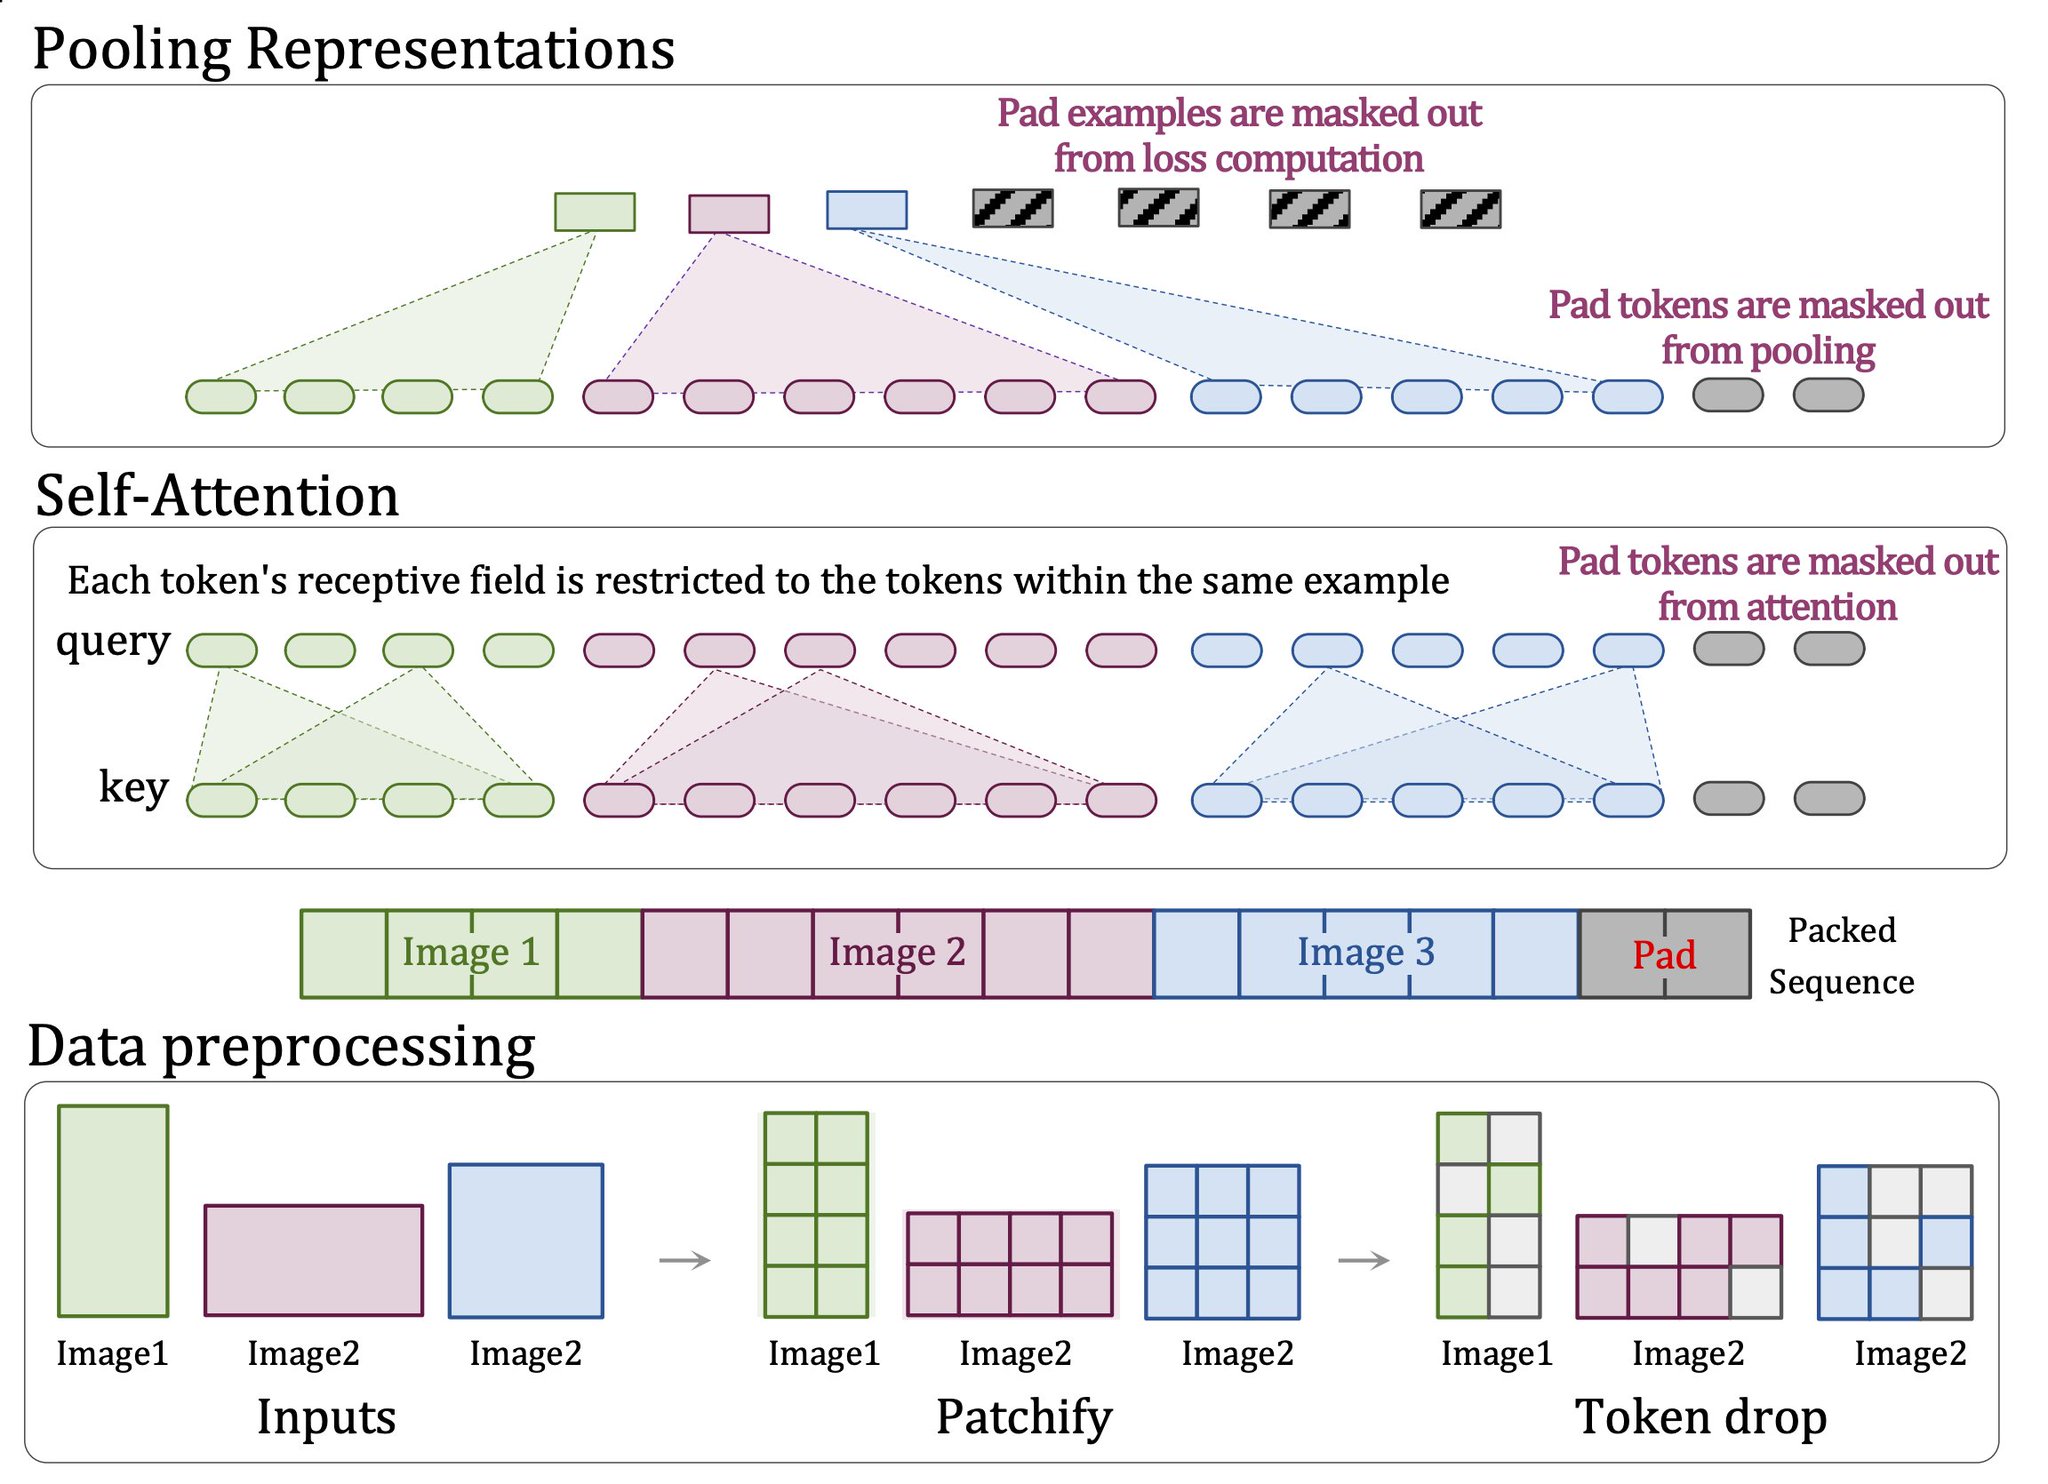
5/ Patch n’ Pack: NaViT – a vision transformer for any aspect ratio and resolution through sequence packing; enables flexible model usage, improved training efficiency, and transfers to tasks involving image and video classification among others.
@dair_ai
-
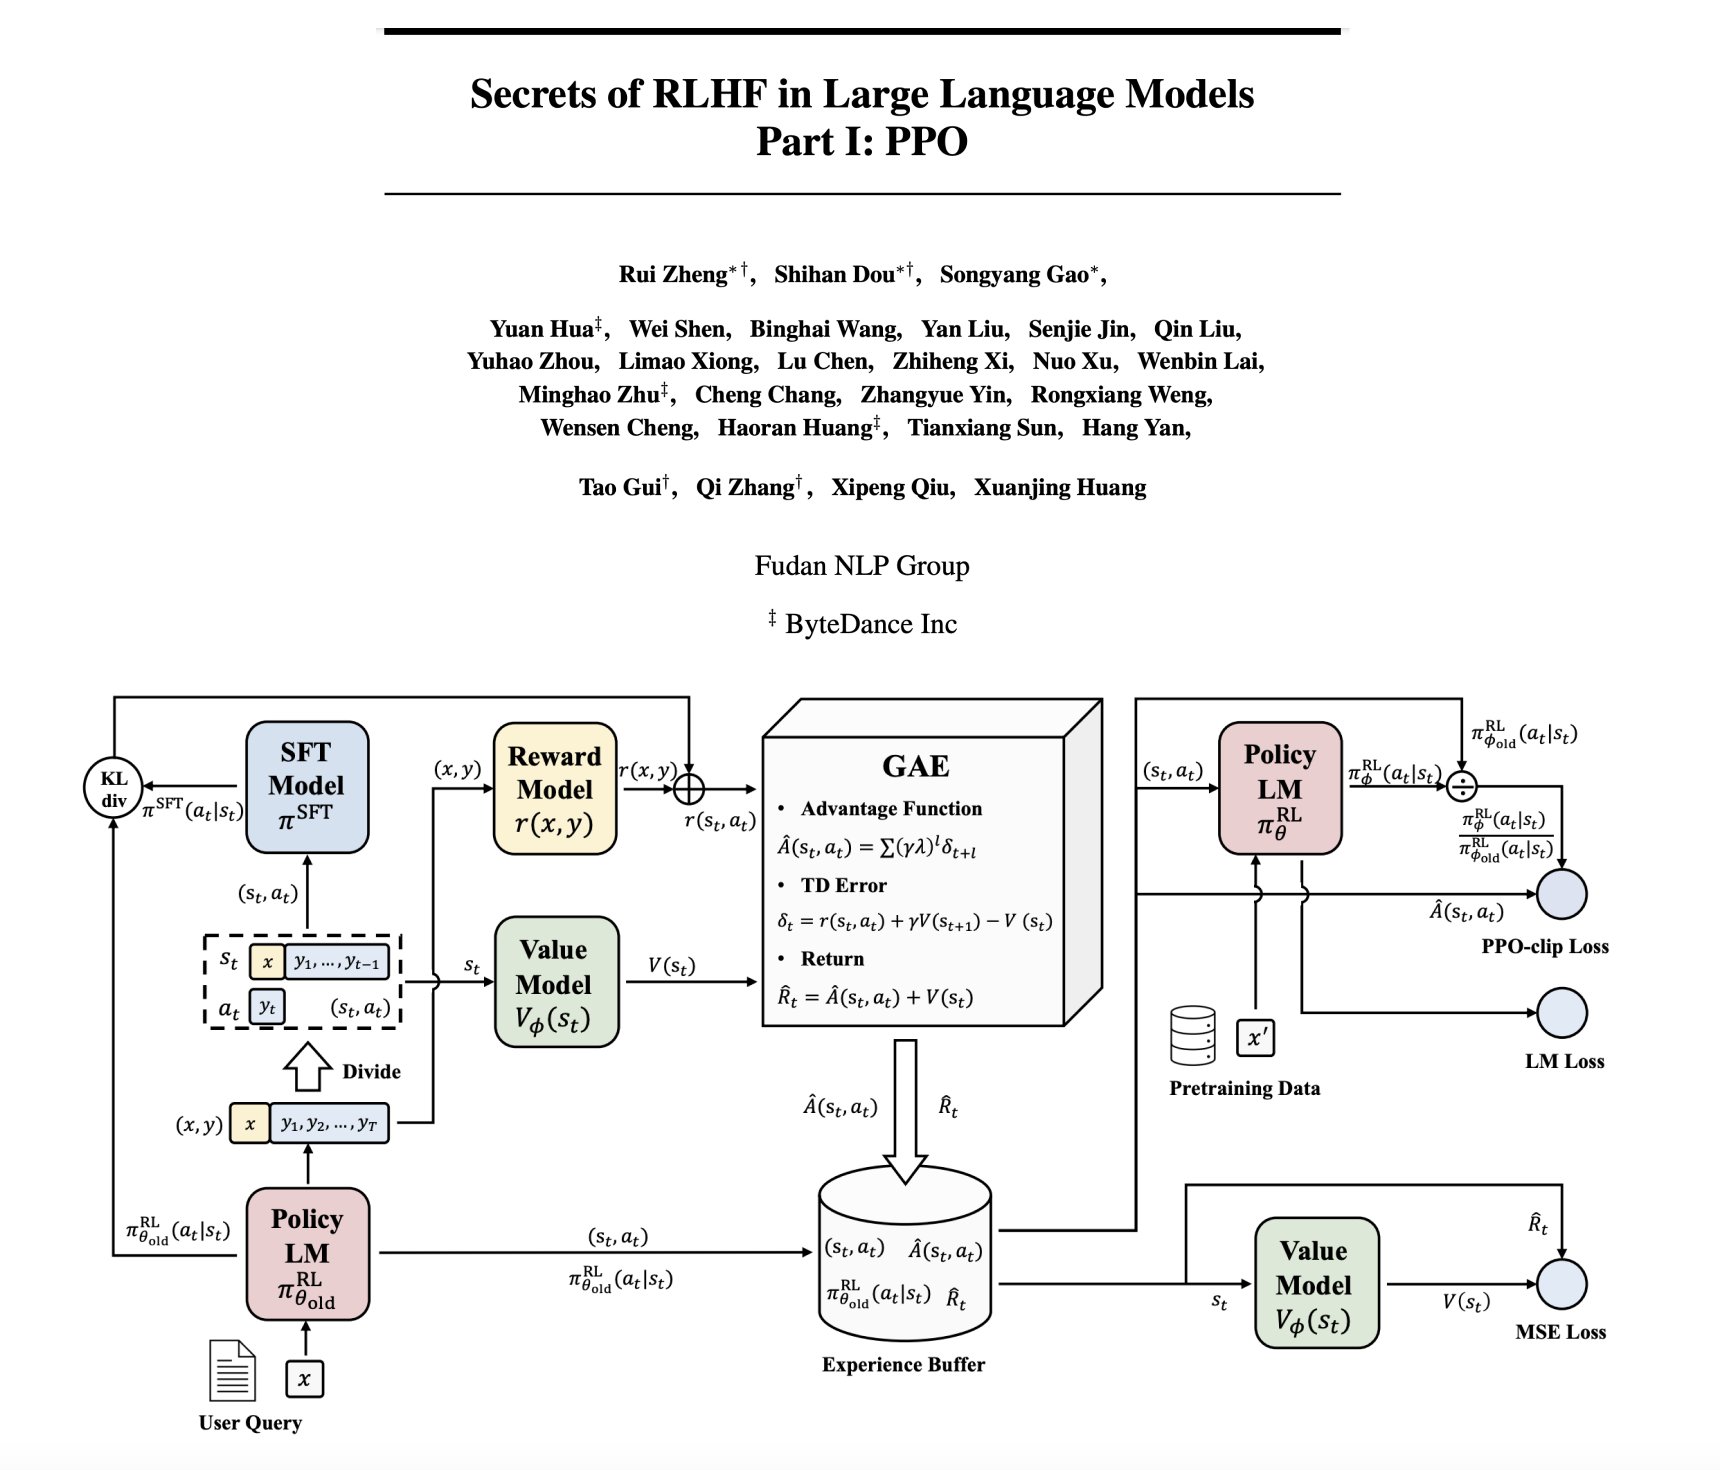
Secrets of RLHF in LLMs: PPO Inner Workings Explained
By
–
3/ Secrets of RLHF in LLMs – takes a closer look at RLHF and explores the inner workings of PPO with code included.
-
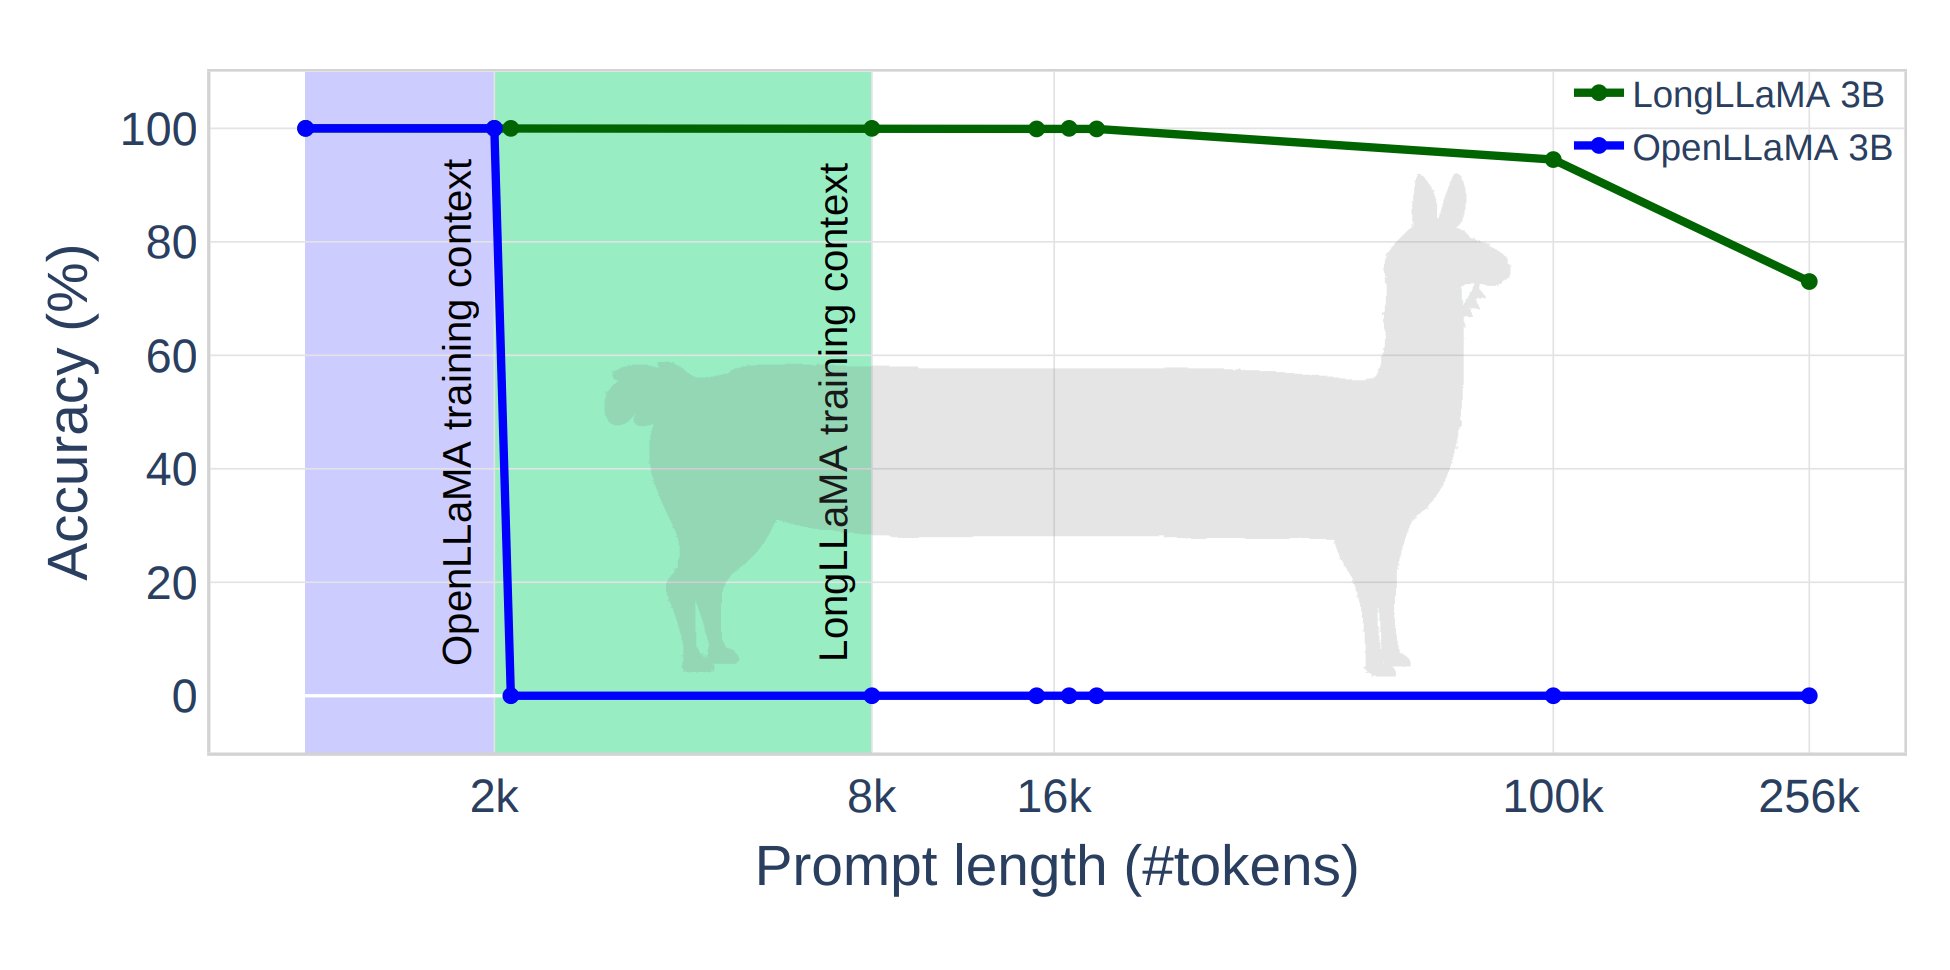
LongLLaMA Extends Context Length via Contrastive Training
By
–
4/ LongLLaMA – employs a contrastive training process to enhance the structure of the (key, value) space to extend context length; presents a fine-tuned model that lengthens context and demonstrates improvements in long context tasks.
-
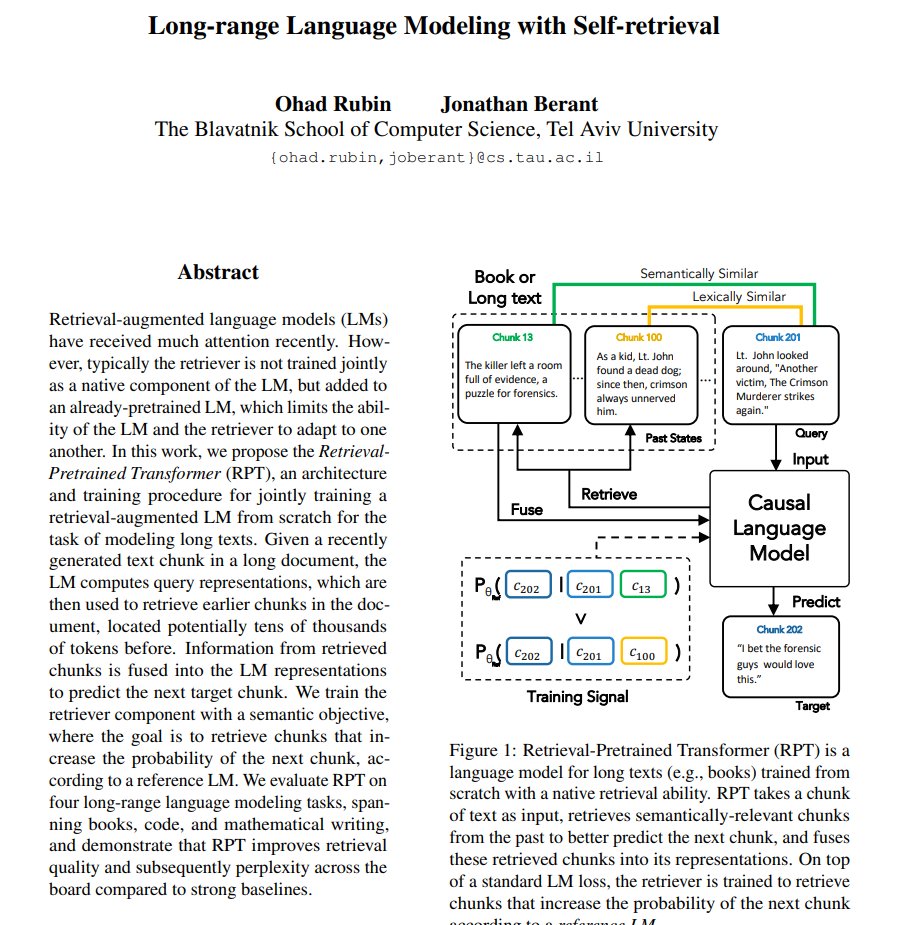
Self-Retrieval Architecture for Long-Range Language Modeling
By
–
9/ Long-range Language Modeling with Self-Retrieval – an architecture and training procedure for jointly training a retrieval-augmented language model from scratch for long-range language modeling tasks.
-
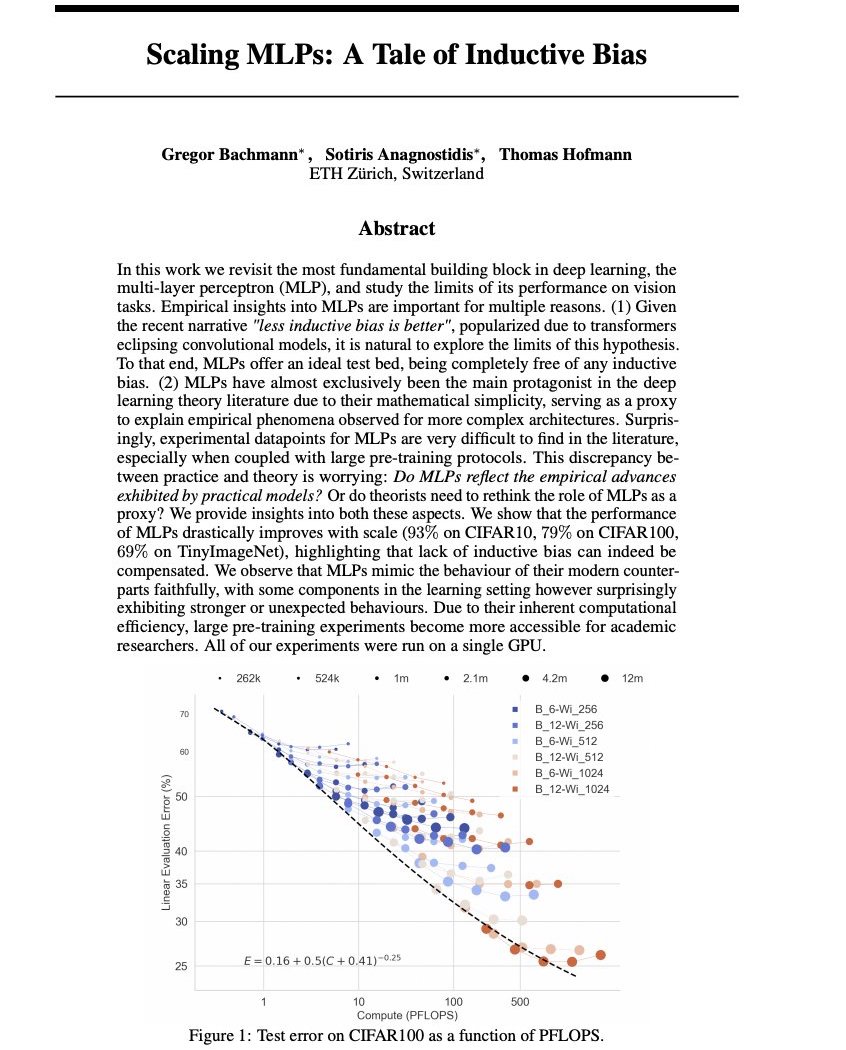
Scaling MLPs: How Inductive Bias Compensates at Scale
By
–
10/ Scaling MLPs: A Tale of Inductive Bias – shows that the performance of MLPs improves with scale and highlights that lack of inductive bias can be compensated.
-
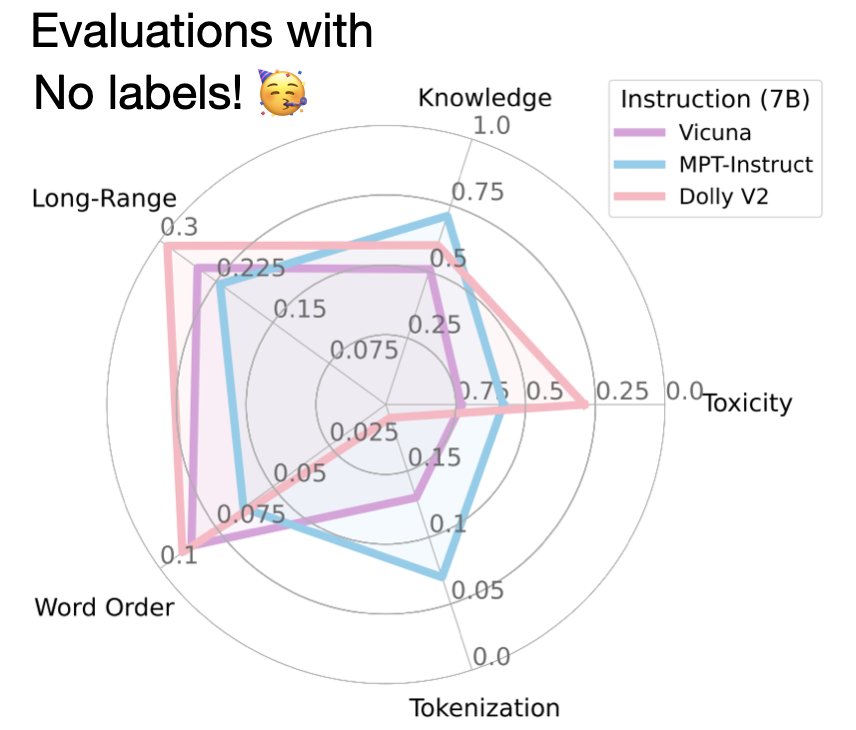
Self-Supervised LLM Evaluation Framework for Deployment Monitoring
By
–
8/ Evaluations with No Labels – a framework for self-supervised evaluation of LLMs by analyzing their sensitivity or invariance to transformations on input text; can be used to monitor LLM behavior on datasets streamed during live model deployment.
-

Theory-of-Mind Evaluation Framework for Large Language Models
By
–
7/ Understanding Theory-of-Mind in LLMs with LLMs – a framework for procedurally generating evaluations with LLMs; proposes a benchmark to study the social reasoning capabilities of LLMs with LLMs.
-
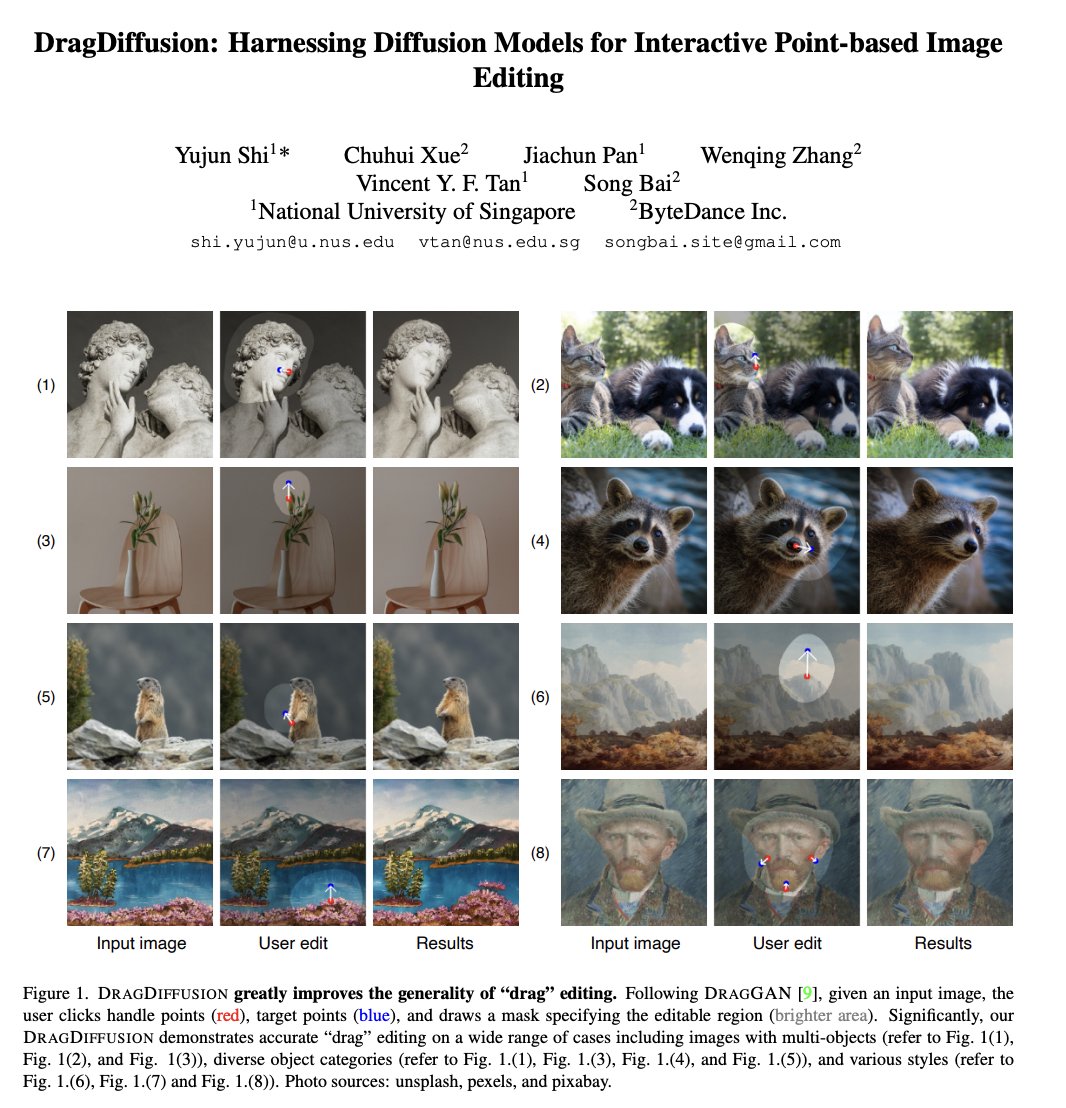
DragDiffusion: Precise Spatial Control in Diffusion-Based Image Editing
By
–
6/ DragDiffusion – extends interactive point-based image editing using diffusion models; it optimizes the diffusion latent to achieve precise spatial control and complete high-quality editing efficiently.
-

Visual Navigation Transformer: Pretrained Model for Robotic Navigation
By
–
4/ Visual Navigation Transformer – a foundational model that leverages the power of pretrained models to vision-based robotic navigation; built on a flexible Transformer-based architecture that can tackle various navigational tasks.
-

Computer Vision Through Natural Language: LLM-Based Modular Approach
By
–
3/ Computer Vision Through the Lens of Natural Language – a modular approach for solving computer vision problems by leveraging LLMs; the LLM is used to reason over outputs from independent and descriptive modules that provide information about an image.